This is the multi-page printable view of this section. .
PIG Blog
-
1: Article
- 1.1: SOW: Postpartum Care for 100,000 Packages
- 1.2: How a Packaging Patch Broke Valkey’s Memory Accounting
- 1.3: Instantly Clone PostgreSQL Databases—No Black Magic Required
- 1.4: What Is a PostgreSQL Distribution?
- 1.5: Extensions for Everyone
- 1.6: 504 Extensions: Expand the PostgreSQL Landscape
- 1.7: The PostgreSQL Extension Encyclopedia: Bilingual and Ready to Use
- 1.8: 464 Extensions, Ready Out of the Box: The New PostgreSQL Extension Catalog
- 1.9: Forging a China-Rooted, Global PostgreSQL Distro
- 1.10: On Trusting Open-Source Supply Chains
- 1.11: PG Extension Cloud: Unlocking PostgreSQL’s Entire Ecosystem
- 1.12: Build and Packaging: An Overlooked but Scarce Skill
- 1.13: The PostgreSQL 'Supply Cut' and Trust Issues in Software Supply Chain
- 1.14: PGDG Cuts Off Mirror Sync Channel
- 1.15: Postgres Extensions Day — See You There!
- 1.16: Pig, The Postgres Extension Wizard
- 1.17: The Ideal Way to Deliver PostgreSQL Extensions
-
2: Design Notes
- 2.1: From Human-Friendly to Agent-Native: PIG's CLI Contract
- 2.2: Compile, Validate, Then Commit: The Native sty conf Pipeline
- 2.3: The 70% Tuner: Defining the Boundary of pig pg tune
- 2.4: Why PIG Keeps the Cobra Command Layer Flat
- 2.5: Why PIG Builds Debug Packages by Default
- 2.6: One Grammar for Dangerous Work: PIG's Operations CLI Safety Contract
- 2.7: Edit the Declaration, Preserve the Document: Lossless Pigsty Inventory
- 2.8: Use the CMDB Pigsty Already Has
- 2.9: A Bounded Grafana Client Instead of Dashboard Shell Scripts
- 2.10: Let Patronictl Speak for Itself
- 2.11: PIG 2.0 Product Direction
- 2.12: Catalog v2 Proposal: Immutable Typed Snapshots
- 2.13: One-command Xray Clients and Servers
- 2.14: Bootstrapping a Pigsty Controller as a Recoverable Transaction
- 2.15: Install the Pigsty Repository Key Automatically
- 2.16: One Catalog Entry Count for the Website and CLI
- 2.17: Target PostgreSQL Versions for Category Aliases
-
3: Release Notes
- 3.1: pig v1.10.4
- 3.2: pig v1.10.3
- 3.3: pig v1.10.2
- 3.4: pig v1.10.1
- 3.5: pig v1.9.0
- 3.6: pig v1.8.1
- 3.7: pig v1.8.0
- 3.8: pig v1.7.0
- 3.9: pig v1.6.2
- 3.10: pig v1.6.1
- 3.11: pig v1.6.0
- 3.12: pig v1.5.1
- 3.13: pig v1.5.0
- 3.14: pig v1.4.2
- 3.15: pig v1.4.1
- 3.16: pig v1.4.0
- 3.17: pig v1.3.4
- 3.18: pig v1.3.3
- 3.19: pig v1.3.2
- 3.20: pig v1.3.1
- 3.21: pig v1.3.0
- 3.22: pig v1.2.0
- 3.23: pig v1.1.1
- 3.24: pig v1.1.0
- 3.25: pig v1.0.0
- 3.26: pig v0.9.0
- 3.27: pig v0.8.1
- 3.28: pig v0.8.0
- 3.29: pig v0.7.5
- 3.30: pig v0.7.4
- 3.31: pig v0.7.3
- 3.32: pig v0.7.2
- 3.33: pig v0.7.1
- 3.34: pig v0.7.0
- 3.35: pig v0.6.2
- 3.36: pig v0.6.1
- 3.37: pig v0.6.0
- 3.38: pig v0.5.0
- 3.39: pig v0.4.2
- 3.40: pig v0.4.1
- 3.41: pig v0.4.0
- 3.42: pig v0.3.4
- 3.43: pig v0.3.3
- 3.44: pig v0.3.2
- 3.45: pig v0.3.1
- 3.46: pig v0.3.0
- 3.47: pig v0.2.2
- 3.48: pig v0.2.0
- 3.49: pig v0.1.4
- 3.50: pig v0.1.3
- 3.51: pig v0.1.2
- 3.52: pig v0.1.1
- 3.53: pig v0.1.0
- 3.54: pig v0.0.1
- 3.55: pig v1.10.0
Articles, design decisions, and release history for PIG, the PostgreSQL command-line tool from Pigsty. PIG manages repositories, extensions, database instances, and Pigsty environments.
1 - Article
Long-form articles about the problems PIG is built to solve: making PostgreSQL extensions discoverable, packaging them as native RPM/DEB artifacts, publishing trustworthy repositories, and exposing the resulting capabilities through a practical CLI.
Versions, counts, and examples in these articles reflect their publication dates. For current usage, see the PIG documentation, extension catalog, and release notes.
Suggested reading paths:
- PIG and the pig family: Meet PIG, instant PostgreSQL cloning, and SOW’s repository state model.
- Extension delivery: the original repository rationale, PG Extension Cloud, the extension encyclopedia, and Extensions for Everyone.
- Packaging and trust: why Linux packaging is scarce, the PGDG mirror incident, Pigsty’s response, and what a Valkey packaging bug teaches us.
- The distribution layer: forging a global PostgreSQL distribution and what a PostgreSQL distribution actually is.
1.1 - SOW: Postpartum Care for 100,000 Packages
Today, let’s talk about Postpartum Care for Sows—a Chinese meme for the sort of absurdly specialized practical topic nobody expects to discuss. This time, the sow in question is my new open-source project, SOW.
When you maintain a PostgreSQL distribution, compiling the software is rarely the most painful part. The real pain is dealing with everything the build produces.
Pigsty maintains hundreds of components across multiple Linux distributions, CPU architectures, and major PostgreSQL versions. Multiply those combinations out, and the repository ends up with more than 100,000 artifacts: RPMs, DEBs, indexes, signatures, checksums, snapshots, and piles of metadata that exist only to keep package managers happy.
Users see apt install or dnf install. Maintainers see something else entirely. You update one package and must guarantee that the other 99,999 objects were not accidentally deleted. You change one index and must ensure that users around the world never catch the repository halfway through the cutover, with half the old state and half the new. At small scale, these look like scripting problems. At 100,000 artifacts, they abruptly become database, distributed systems, and software supply-chain problems.
That is why I built SOW, a self-contained APT/YUM repository manager written in Go.
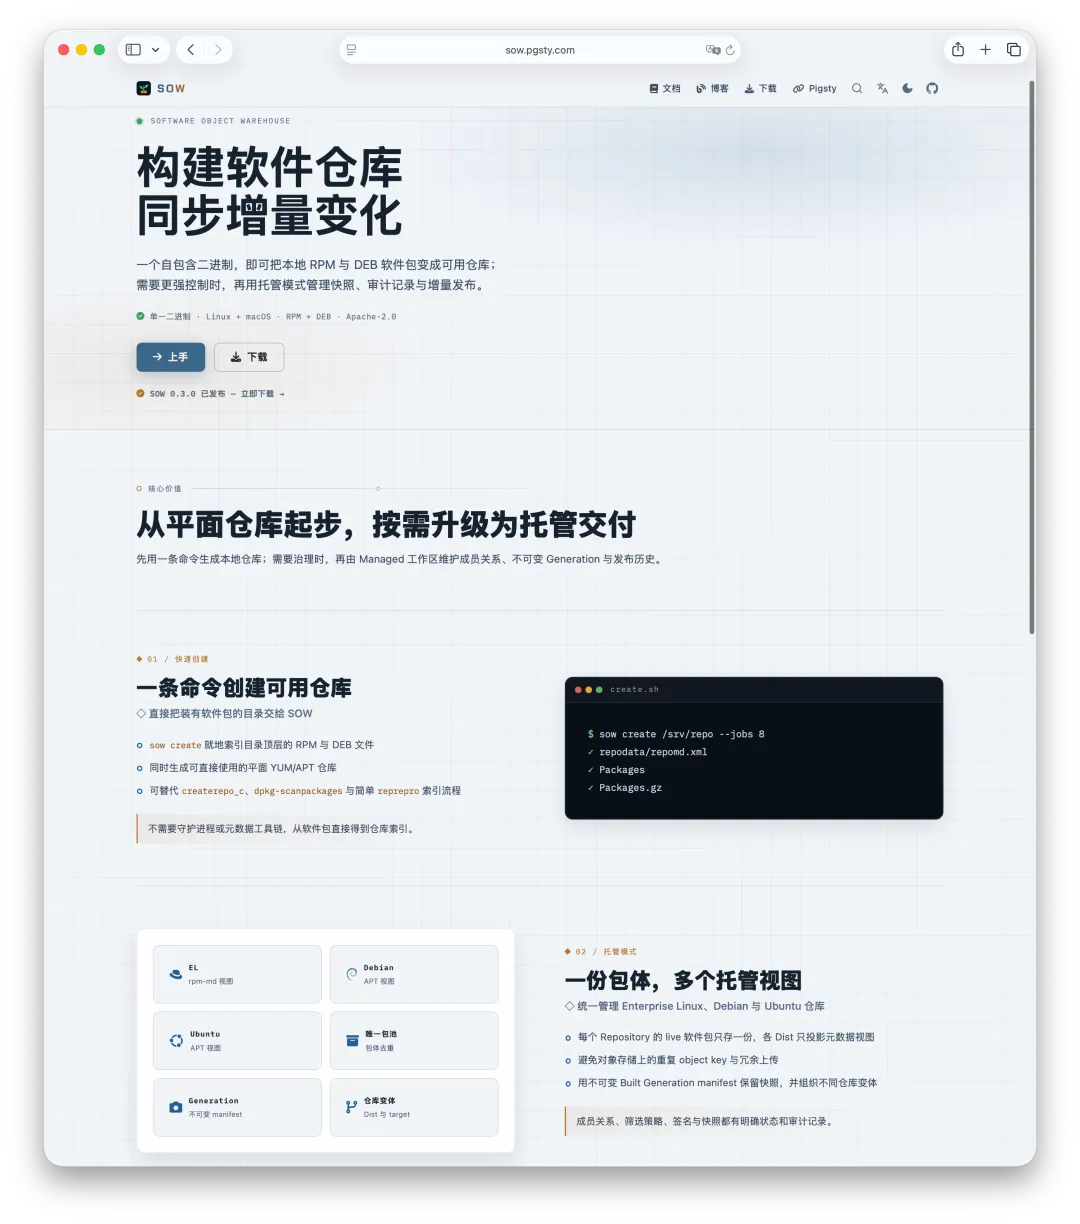
If all you need is to turn a directory of RPMs and DEBs into a usable repository, one command is enough:
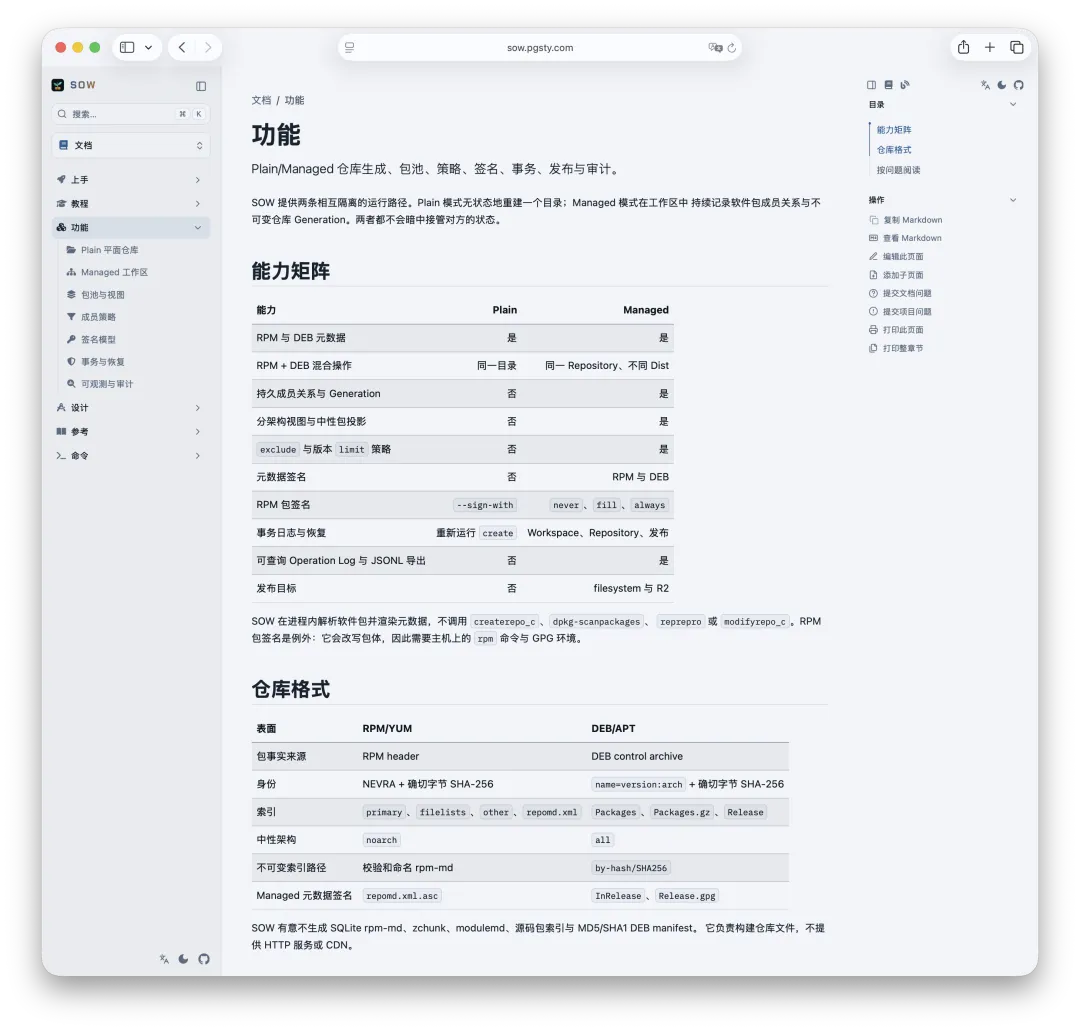
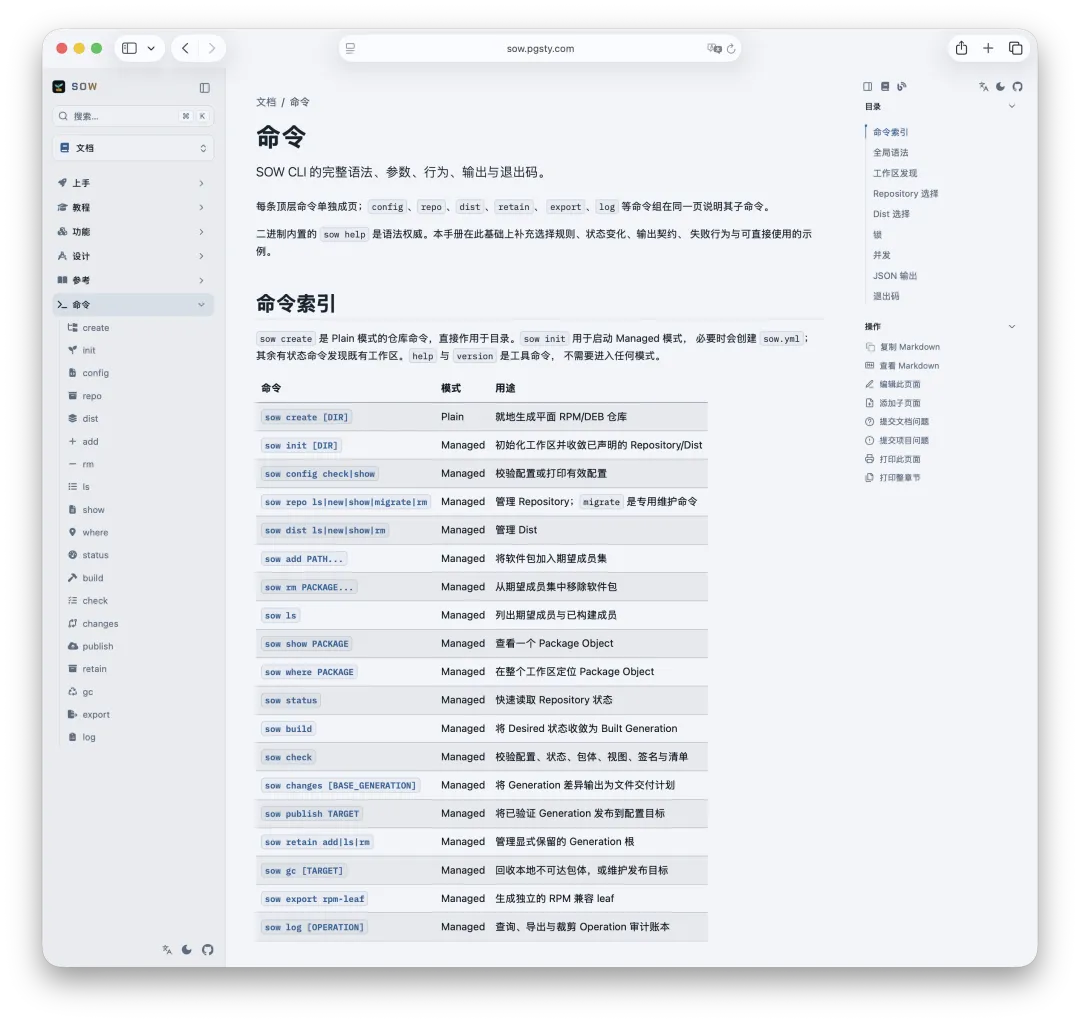
For a repository you intend to maintain over time, SOW also provides Managed mode. It projects one package payload into multiple distribution views, records desired and built state, creates immutable snapshots, computes exact changesets, and publishes incremental updates to a filesystem or object store.
SOW provides both repository indexing and long-term repository management in one binary.
I built this tool entirely to solve my own problems. But if you also maintain a large software repository spanning multiple Linux distributions, it should help you too—though admittedly, there probably aren’t many of us.
Why SOW?
The name deserves an explanation. We previously built a companion project, Pig—PostgreSQL Install Genius, the package manager for the PostgreSQL ecosystem. If a little Pig installs the packages, then the tool that produces, stores, organizes, and distributes those artifacts naturally has to be its mother: SOW.
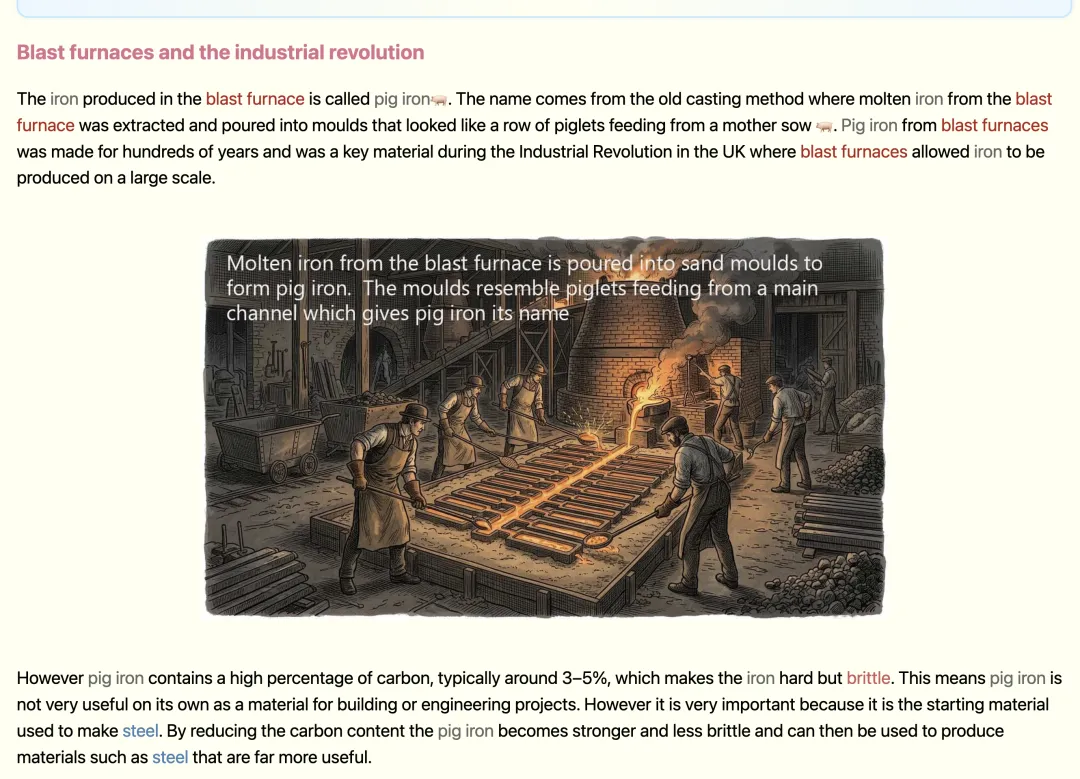
It also expands neatly to Software Object Warehouse, a name that fits naturally into the software supply chain. Better yet, the pig metaphor has roots in industrial history. In traditional pig-iron casting, molten iron flowed down a central channel and branched into rows of smaller molds. The cooled ingots were called pigs, while the main runner that fed them was the sow. Seen from above, one large channel feeding rows of ingots looked like a sow nursing her piglets.
Why Build Another Repository Tool?
The immediate trigger was Pigsty’s offline installation. Pigsty first downloads the required RPMs and DEBs, then turns them into a local offline repository. Historically, RPM systems relied on createrepo_c, while Debian and Ubuntu relied on dpkg-dev. The output is only a few XML files, Packages indexes, and compressed metadata, yet preparing the toolchain pulls in hundreds of megabytes of dependencies.
That is cumbersome enough on Linux and even uglier on macOS. You have to start different Linux containers, mount the same directory into each one, run the RPM and DEB tools separately, then copy the results back. Bringing in hundreds of megabytes of tooling and a fleet of containers to generate a few megabytes of metadata is hardly elegant.
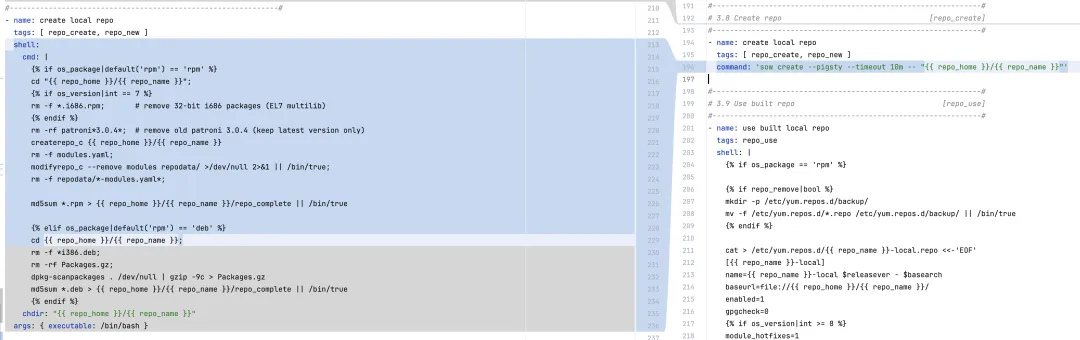
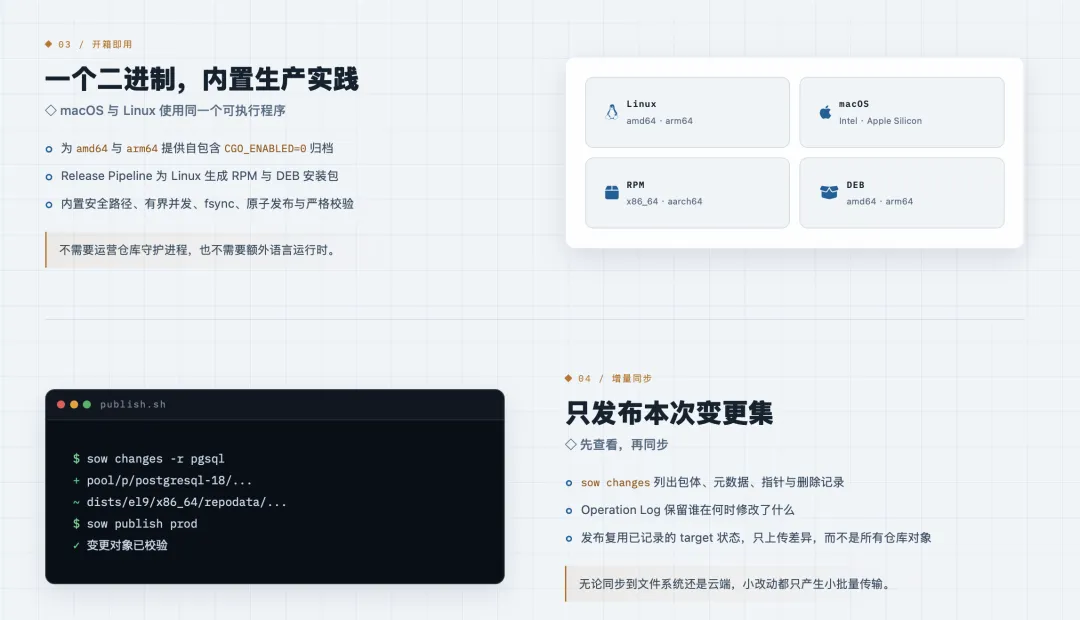
In Pigsty 4.5, I removed that clutter. SOW is a self-contained binary. It runs directly on Linux and macOS, understands both RPM and DEB package formats, and implements the APT and DNF repository specifications. It has no daemon and requires no separate language runtime.
But installing fewer tools was only the surface problem. Four deeper problems convinced me to keep building SOW as the repository grew.
First, Hard Links Don’t Help in Object Storage
The same noarch RPM may appear in repositories for several architectures, and the same package may belong to beta, latest, and stable views. On a local disk, hard links let many paths share one inode. Upload them to Cloudflare R2, Alibaba Cloud OSS, or another object store, and every object key incurs real storage and upload costs. Identical content does not make the cloud treat those keys as one object.
Second, 100,000 Files Make Even a Comparison Expensive
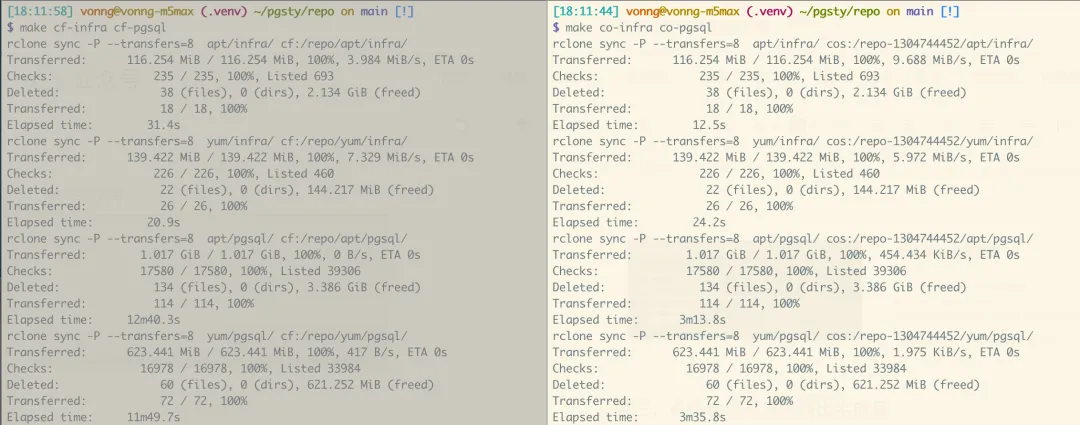
A repository update may change only a few dozen packages, yet traditional synchronization tools often have to walk, compare, and verify more than 100,000 files to prove it. A full comparison can easily take more than ten minutes. The actual transfer may take seconds; almost all the time goes into proving that nothing changed.
Third, a Live Repository Must Never Expose a Half-Built State
An RPM repository is more than a directory of .rpm files. Clients read repomd.xml first, then follow it to primary, filelists, and the package payloads. APT has the same constraint: Release, InRelease, Packages, and by-hash files form a strict graph of references.
If you publish them in the wrong order, a client may see a new pointer before the object it references exists. To the maintainer, that is only a few seconds during an upload. To a user who happens to arrive during that window, it is an irreproducible 404, checksum failure, or aborted installation.
Fourth, Directories Have No Versions, but Distributions Need Them
The deeper problem surfaced when I wanted to add repository channels. How do you maintain beta, latest, and stable at the same time? Keep a monthly snapshot? Answer “which packages were added last Wednesday?” Roll back safely? Determine which old objects are no longer referenced by any snapshot and may be deleted?
You can script each requirement in isolation. Put them together, however, and those scripts metastasize into a shadow database with no transactions, schema, or audit trail. There are already tools such as createrepo_c, dpkg-scanpackages, reprepro, and aptly, along with general-purpose synchronization and object-storage tools. But I could not find a lightweight open-source tool that brought RPM and DEB support, a single package pool, immutable snapshots, recoverable publishing, and incremental delivery into one clear model.
Fortunately, building your own tools has never been cheaper.
Two Levels of Complexity, Two Modes
SOW does not assume that every repository needs the same degree of governance. It splits the problem into Plain and Managed modes: small problems stay small, while large ones get the full state machine.
Plain: The Package Directory Is the Truth
Plain mode has one central command:
The RPMs and DEBs in the directory are the sole source of truth. repodata/, Packages, and Packages.gz are projections that can be discarded and rebuilt at any time. SOW scans top-level packages concurrently. Without signing, it opens each package only once, computing its SHA-256, parsing it, and extracting every fact needed for rendering in the same pass before generating metadata for both repository formats.
The output first goes into a private staging area on the same filesystem. SOW validates it with its own parsers. Before replacing public files, it compares the package list and stat snapshots to detect changes during the build. It does not rehash every package at this stage.
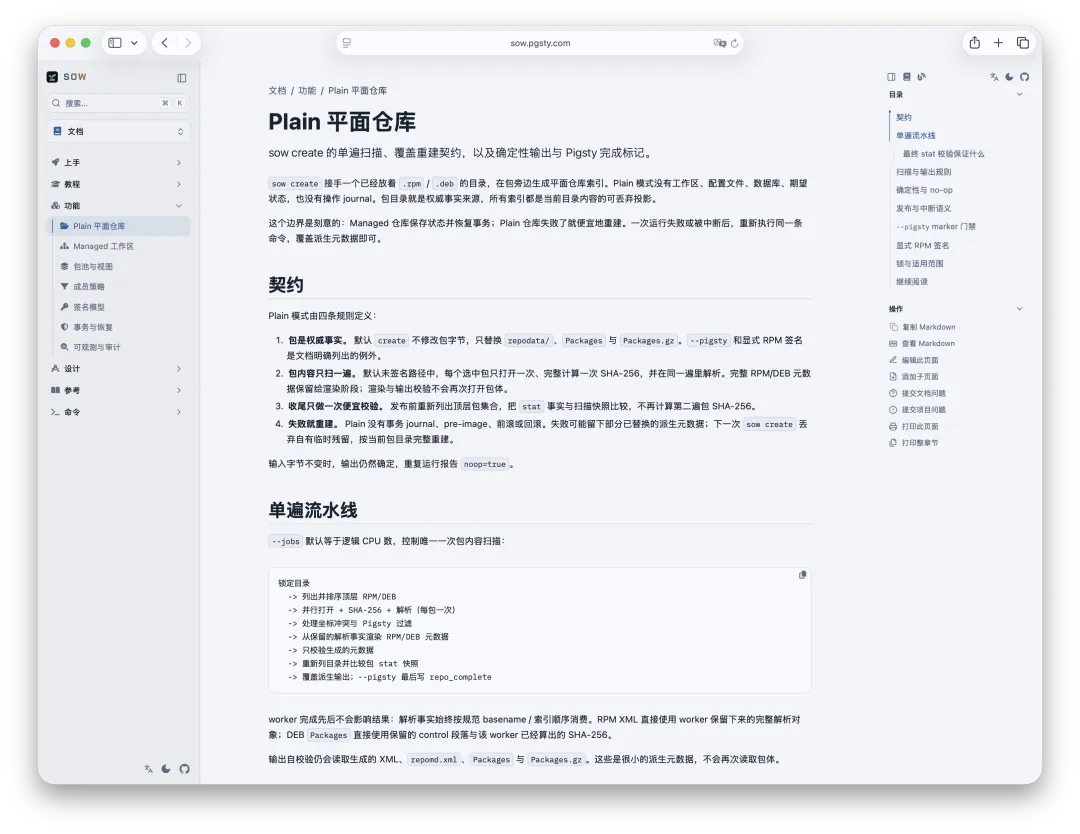
Plain mode does not maintain an operation log. Its file replacements are separate operations, so an interruption can leave incomplete indexes. Run the same sow create command again to rebuild them from the package directory. For a live service, build in a separate directory and switch it into service after the command succeeds.
With --pigsty, SOW removes DEB i386 packages and Patroni 3.0.4 packages, then writes a repo_complete marker containing the retained packages’ SHA-256 hashes. It removes an old marker before changing public files and writes the new marker last. Consumers that use this convention wait for the marker before using the repository.
This mode solves Pigsty’s original problem: replace two toolchains and several containers with one small binary, then quickly produce a repository that real APT, DNF, and YUM clients can consume.
Managed: The Repository Is a State Machine, Not a Directory
A long-lived repository cannot look only at “what is in the directory now.” It must also know what you want, what it published successfully last time, and why the two differ.
SOW’s Managed model has four layers:
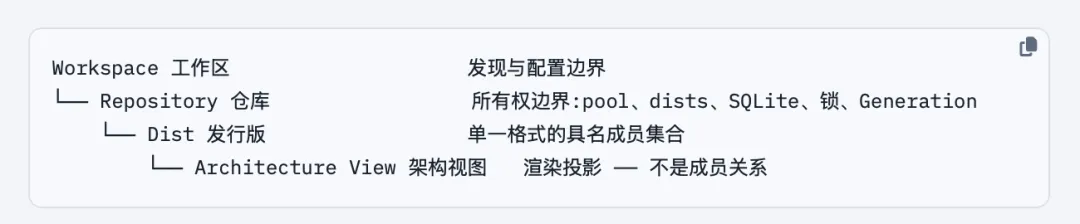
A Workspace is the configuration and discovery boundary. A Repository is the ownership boundary. A Dist is a named set of RPM or DEB members. An Architecture View is only a rendered result and does not own package payloads. The most important invariant is this: within one Repository, every package has exactly one canonical payload and no duplicates.
A noarch RPM or all DEB can appear in several architecture indexes without copying its payload. Beta and stable can reference the same package object without creating a second cloud object key. APT and DNF repositories can also live under the same directory hierarchy.
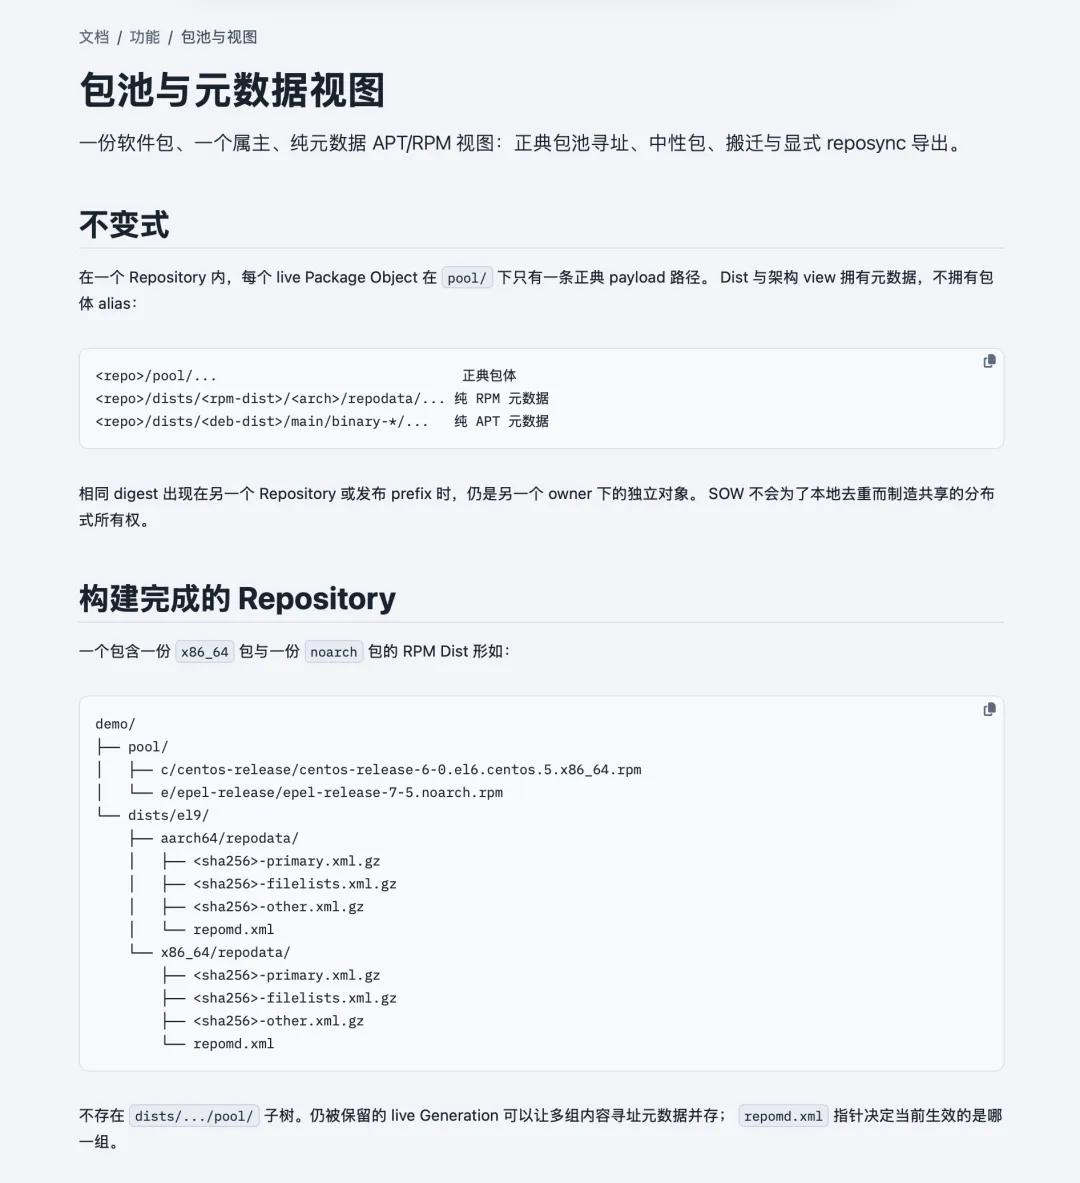
The boundary of “store only one copy” must be stated precisely: it is one Repository or one publication prefix, not an entire Workspace, bucket, or the whole world. SOW does not deduplicate implicitly across Repositories, because deduplication must not destroy ownership boundaries. Deleting one repository must never remove a shared object that another repository still needs.
Desired, Built, and Generation
Managed mode divides repository state into three concepts:
| State | Meaning |
|---|---|
| Desired | The membership set requested by configuration and add/remove operations |
| Built | The last public view that was fully rendered, validated, and committed successfully |
| Generation | An immutable manifest of a particular Built state |
This distinction may sound academic. In practice, it exists specifically to handle failure.
Suppose you add 5,000 packages in one operation. Desired has changed, but the build is killed halfway through with SIGKILL. Without this separation, the system is left staring at a directory tree with no idea how far the update got. With it, SOW retains the previous completed Generation and records the interrupted operation. Recovery can determine which work remains and whether to roll back or continue.
A Generation does not copy the entire repository. It stores an immutable manifest, metadata, and a set of package-payload references; many snapshots can reference the same Pool objects. The exact difference between two Generations is a Changeset: which payloads to add, which metadata to replace, which pointers to switch, and which old objects may be deleted after their retention period.
The transfer set comes from comparing two known Generations. SOW still checks the local tree and remote inventory, but it can avoid transferring unchanged objects.
Publish the Referenced Objects Before the Pointers
SOW publishes repository objects in a defined order:
First, place immutable package payloads. Next, write checksum-addressed metadata and by-hash indexes. Then update the client entry points: repomd.xml, Release, and InRelease. Garbage collection removes an old object only after it is no longer needed by retained Generations or publication targets and its retention period has expired.
This order makes the referenced immutable objects available before their new pointers. The whole repository does not switch in one atomic transaction: views, direct APT indexes, and detached signatures change in separate writes. A client can still need to retry during that transition.
On a local POSIX filesystem, this protocol relies on same-filesystem staging, fsync, atomic rename, stable-path locks, and a durable operation log. Before any Managed write command begins its own work, it checks for any unfinished prior operation and recovers it. Recovery decides whether to roll back or roll forward solely from evidence already persisted on disk. If the recorded state conflicts, SOW stops without applying a guessed repair.
Object stores do not support atomic commits across several keys. SOW therefore persists a commit intent first, advances the protocol pointers in deterministic order, and records an Applied Checkpoint for each target. A filesystem target and an R2 target each have their own evidence; success on the former is never mistaken for success on the latter. In SOW 0.3, R2 garbage collection reports candidates and keeps the remote objects.
This is the essential difference between SOW and a single rclone sync command. Moving files is easy. The hard parts are knowing what to transfer, when the operation counts as committed, which direction recovery should take after failure, and what is truly safe to delete.
At 100,000 Objects, Performance Needs Proof
Most of the work in SOW 0.3 was not adding more features. It was making an already sound model work at real repository scale.
The Plain path now reads, hashes, and parses each package in a single pass, using bounded concurrency through --jobs. Identical input produces byte-for-byte identical metadata. When nothing needs updating, SOW returns no-op and does not replace a public inode merely to bump its timestamp.
The Managed path caches parsed “package facts” in SQLite, keyed by their immutable SHA-256 digest. SOW reads each new package to calculate its digest and parse its metadata on ingestion. Later builds load facts in batches and compute the membership projection in memory. A warm build still walks the public namespace, but for unchanged Pool files it checks only the device, inode, size, mtime, and ctime fingerprint instead of reading every payload again. If the fingerprint drifts, SOW falls back to one authoritative SHA-256 pass and repairs the cache automatically. When you need a full cryptographic audit, run sow check explicitly.
Optimizations like these matter only when they show up in the numbers.
In the project benchmark, membership expansion for a Dist with 5,000 objects fell from about 4.1 seconds to 33 milliseconds. At 50,000 objects, the new implementation finishes in under a second, where the old one did not finish in the benchmark. See the v0.3.0 release notes for the benchmark context. Payload promotion now uses bounded, single-writer group commits, capped at 512 objects or 1 GiB per batch. This both reduces fsync storms and prevents file-descriptor use and recovery state from growing without bound as the repository expands.
These numbers are not there to decorate a benchmark slide. They simply demonstrate that once a repository truly holds 100,000 artifacts, “the state model is correct” is only the passing grade. Whether routine small changes remain cheap enough determines whether the tool stays viable over time.
Tearing Down V1 and Rebuilding from a Minimal End-to-End Core
SOW took a while to build. Midway through, I tore it down almost completely and started over.
That original implementation remains archived as v0.1.0. It was ambitious: Git refs managed repository views, a SHA-256 CAS stored artifacts, and the same system handled upstream synchronization, multi-target cloud publishing, verification, repair, garbage collection, a Cloudflare Worker, CDN purges, edge validation, and production migration.
Many of those features worked, and some paths passed acceptance tests against real APT and DNF clients and a non-production R2 environment. But the flaw was equally clear: the repository model, cloud provider, CDN, edge runtime, and migration workflow were too tightly coupled. Proving one feature correct required half of the rest of the system; every small change dragged a long acceptance matrix behind it.
In the end, I shelved it.
I did not abandon the goal, only the route to it. The worst fate for an infrastructure tool is to have a little of everything without any layer that can be explained and verified on its own. So the second version rebuilt the smallest self-contained slices first:
- P0 / Plain Create: one directory in, one working repository out;
- P1 / Managed Control Plane: Workspace, Repository, Dist, Membership, Build, Generation, Check, Changes, and Operation Log;
- More complex synchronization, remote publishing, CDN, and provider control planes went back into separate acceptance queues, one capability at a time.
v0.2.0 established today’s Plain + Managed foundation: a single package pool, metadata views, deterministic builds, locks, logs, crash recovery, Generations, and publication to filesystems and R2.
v0.3.0 introduced no new conceptual layer. Instead, it removed the old V1 runtime, tightened the cloud-transfer boundary, and fixed repeated reads, per-object queries, payload commits, and observability at large scale in both Plain and Managed modes. The current release binary depends only on the new V2 core. The old implementation remains in Git history and the v0.1.0 / v0.2.0 tags as a record of what we learned, not as a second source of truth.
This path looks slower than building everything for one grand reveal, but it is faster. Every layer has an independent contract, explicit failure semantics, and acceptance tests against real clients. The next layer rests on solid ground, not on an increasingly unreadable wish list.
Where SOW Goes Next
SOW 0.3 can create repositories, manage membership and snapshots, calculate changesets, and publish to filesystems and R2. It is still some distance from the complete software-artifact control plane I have in mind.
The roadmap has four main tracks:
- Upstream repository synchronization. Consume upstream APT/YUM indexes directly, verify signatures and digests, fetch only missing artifacts, and bring mirror results into the same Package Object, Membership, and Generation model.
- More complete incremental delivery. Today,
changesand target checkpoints already make changesets explicit and reusable, so SOW can publish only the delta. Next comes support for more object stores and synchronization providers, with large remote inventories, resumable transfers, conditional writes, and safe-deletion evidence forming a reliable end-to-end system. - CDN and cache control. A CDN purge is not merely “call an API.” It must be bound to an exact Generation, cache TTL, receipt, and failure-recovery protocol. V1 proved this path can work, but it will return as an independent, testable module rather than being welded back onto the repository core.
- Version and retention policies. Dist, Generation,
retain, and target can already express beta, latest, stable, and monthly snapshots. Higher-level policy orchestration will eventually make common release cadences possible without hand-wiring them through external scripts.
Most of these capabilities existed in some form in the first version. I will not port the old code wholesale. As with 0.2 and 0.3, I will bring back one sharply bounded, independently testable capability at a time.
No more disappearing to build the grand design in one shot. Ship small, complete systems continuously.
The Pig Family Keeps Growing
SOW is part of Pigsty’s increasingly elaborate porcine universe. The naming scheme keeps getting more ridiculous—and more complete:
- Pigsty: the sty, responsible for installing and managing the PostgreSQL ecosystem;
- SOW: the mother pig, responsible for organizing, building, and publishing software repositories;
- Boar: the male pig, a graphical control plane for Pigsty now under development;
- Silo: the grain bin, responsible for S3-compatible object storage;
- Oink: the sound pigs make, powering the documentation and website framework;
- Snort: the pig rooting around, collecting logs and monitoring metrics.
The names are jokes first, of course. But behind them, a complete chain is taking shape: SOW organizes the artifacts; Silo stores them; Pigsty installs them into running systems; Snort watches those systems; and Oink explains everything. SOW fills the part of that chain that was easiest to overlook.
A software repository looks like a directory that Nginx can serve. But once it carries 100,000 objects across multiple operating systems and architectures for countless users, it is really a headless database. It has objects, relationships, versions, transactions, logs, garbage collection, and commit pointers that absolutely must be correct.
SOW makes those hidden rules explicit. It replaces the hopeful assumption that “the legacy scripts are probably fine” with an engineering contract backed by checks, recovery, and auditability. If all you want is an offline repository, start with one command:
If you also maintain a long-lived software distribution, visit the SOW project site or go straight to the documentation to see what lies beneath.
SOW is licensed under the Apache-2.0 license. The v0.3.0 release described here provides amd64 and arm64 archives for Linux and macOS, plus RPM and DEB packages for Linux. Get the latest release from the download page, or browse the source code.
A hundred thousand packages aren’t frightening. Treating them as nothing more than a hundred thousand files is.
Originally published on vonng.com.
1.2 - How a Packaging Patch Broke Valkey’s Memory Accounting
I was updating the Redis module in Pigsty recently, adding Valkey as an alternative engine, and found a bug in an inherited packaging patch.
In affected Valkey DEB packages, failed synchronous saves can corrupt used_memory until it reports a value near 2^64.
With maxmemory set, commands subject to its limit then return OOM errors. Restarting the server resets the counter.
There can be plenty of free memory. The log records the save failure, but not a separate memory-accounting error. used_memory_rss stays normal and RSS graphs are flat. The only number moving is used_memory, and nobody alerts on memory usage slowly going down.
A build that applies the same patch and links the bundled private jemalloc can crash on the first failed SAVE. Pristine upstream source does not contain the patch and is unaffected.
The cause is a single line in a packaging patch. Its lineage goes back to 2017, it was fixed once in Redis, came back in Valkey, and eventually got copied into Valkey’s own release pipeline — so all five official DEB packaging lines examined in this investigation—7.2, 8.0, 8.1, 9.0, and 9.1—carried it. The official RPM packaging did not.
The packaging fix merged on August 7, 2026. Here is how it surfaced.
What’s wrong
Valkey logs the working directory on two RDB error paths: failure to open the temporary file and failure to rename it to the final snapshot name. Upstream uses a stack buffer, so there’s nothing to release.
Debian’s packaging patch moves it to the heap:
The motivation is fine: keep a 4 KB array off the stack.
The problem is the last line. get_current_dir_name() allocates through glibc’s malloc(). zfree() is Valkey’s own deallocator. They are not interchangeable.
The usual reaction is “it’s a free, what could go wrong”. But zfree() isn’t a wrapper around free(). It does three things: ask the allocator how big the block is, subtract that from used_memory, and then release it.
Step two is wrong unconditionally. This allocation never went through Valkey’s allocator, so it was never added to used_memory — and used_memory is unsigned, so subtracting past zero wraps it.
Whether steps one and three break depends on which jemalloc the binary was linked against. With system libjemalloc.so, as used by the affected DEB packages, global malloc() and Valkey use the same allocator. The pointer belongs to the right heap, so nothing crashes and you only get the corrupted counter. With the bundled private jemalloc — upstream’s default — it can’t find the pointer in its own bookkeeping and dereferences null:
Look familiar? Same top-of-stack as redis/redis#7927 from 2020 — the same bug, in Redis.
The saving grace is that only synchronous saves in the main process accumulate. BGSAVE and scheduled saves fork, so the damage dies with the child. The real-world trigger is a full disk, wrong permissions, or a read-only filesystem, combined with something calling synchronous SAVE in a loop: a monitoring script, a backup cron, a client that retries.
It waits until you already have a problem, then quietly adds a second one.
How I found it
Not through any clever analysis. Upstream’s own test suite caught it.
While reworking the Valkey DEB packaging for Pigsty, I ran runtest as usual. Three cases in unit/shutdown failed and the server left a crash report.
Our packages use the bundled jemalloc, so we were on the crashing side — louder symptoms than the official packages, and much easier to catch. Following the crash trace up, then opening debian/patches/0003-*.patch, and there it was.
The relevant test, by the way, deliberately creates a directory named dump.rdb to force rename(2) to fail — which is exactly one of the two patched paths.
Once I understood the mechanism, the first thing I did was disbelieve myself: two Valkey versions, three builds each (pristine, patched, patched-and-fixed), against three allocators, on two architectures. The result held.
Then I spent longer than the technical work checking whether someone had already reported it. Worth noting one trap: two of Debian’s search endpoints were broken at the time and returned zero rows for bugs I knew existed. Without a “this query should definitely return something” control, I’d have walked away with a confident false negative.
I found no dedicated Debian bug report for this Valkey defect.
Where the line came from
The patch header goes back further than I expected:
-
2017 — Chris Lamb writes the patch for Debian’s Redis packaging.
-
2020 — a
zfree(cwdp)shows up in Redis’s copy and blows up: redis/redis#7927 and Debian #972683, fixed by switching to libcfree(). -
Debian’s Valkey packaging is derived from the Redis packaging, patch included.
-
In October 2024, a change to fix the leak adds
zfree(cwdp)again. It first ships in Debian Valkey8.0.2+dfsg1-1;8.0.1+dfsg1-1is unaffected. The same mistake, in the same patch lineage, four years apart. -
March 2025 — Valkey maintainer zuiderkwast, reviewing these Debian patches, spots the mismatch immediately:
…the latter uses
malloc()(rather thanzmalloc()) and we later free it usingzfree(). This means it will mess up the memory usage tracking done in zmalloc and zfree. Therefore, we may not want to take this patch, at least not unmodified.Correct diagnosis. He assumed the damage stopped at broken accounting, and the issue lost priority when jemalloc upstream was archived.
-
April 2026 — Valkey builds an automated pipeline covering five version lines, four distributions, and two CPU architectures, and copies Debian’s patch set wholesale. The official
.debs inherit the bug.
The Debian packaging rules leave override_dh_auto_test empty, with the upstream regression-test commands commented out. The pipeline checks installation and service behavior, but those checks do not exercise the failing RDB paths.
Reporting it
Two channels, handled separately.
Debian takes email. No account needed — send a plain text message to [email protected] with pseudo-headers as the first lines of the body:
My first attempt bounced, saying the body didn’t start with Package:, so “your message has been ignored completely”. Which was baffling, because it did:
The answer was in the message-id: it was Apple Mail, which sends rich text by default. BTS only parses plain text, so it never saw the line.
So if you’re filing a Debian bug from a Mac: switch to plain text first (Format → Make Plain Text), and turn off smart quotes, or the quote characters in your patch get mangled and the patch is worthless. Resent, it went through as #1143239.
Upstream took a comment, then a PR. zuiderkwast’s year-old comment was the natural hook, so I picked up from there with what he didn’t have: under the bundled allocator this is a segfault, not drift; the upstream test suite already catches it; and the official .debs have it today.
He asked for a PR on August 3. The change is one line:
zlibc_free() exists in Valkey for exactly this case — it’s defined specifically so callers can reach the real libc free().
Which also explains how zfree got picked in the first place. A plain free(cwdp) does not compile: Valkey deliberately marks free() deprecated and builds with -Werror. One possible explanation is that the compiler rejected free() and the author chose the closest-looking name.
A defensive measure that pushed someone into the hole it was guarding.
Outcome
zuiderkwast approved the same day, with a question: why keep this patch at all? The path is only used in one error message; just go back to the stack buffer.
Fair, and I’d listed dropping it as the alternative in the PR description. Since he was leaning that way, I did it downstream first — removed the patch entirely from Pigsty’s Valkey and Redis packaging, rebuilt, and reported back: the shutdown tests pass, and ordinary paths still appear in the error message. If a path exceeds the stack buffer, upstream reports unknown. The problem goes away along with the patch.
Then it went somewhere I didn’t expect. zuiderkwast turned to the maintainers who built the pipeline:
Why did we copy Debian’s patches?
If some things need to be patched, that’s better fixed upstream in Valkey itself. Bugs in this repo’s patches are harder to spot than bugs in Valkey main repo IMHO.
That last sentence is the best summary of the whole episode.
The PR merged on 2026-08-07. It corrects both deallocation sites in all five packaging lines. The maintainer who built the pipeline replied “Thanks for the notification. Will investigate this!” — a review of the whole patch stack is underway.
As of this article’s publication on August 9, the Debian report had received no maintainer reply. The investigation also found the same defect in bookworm’s Redis 5:7.0.15-1~deb12u7 package. I included that finding in the Valkey report but had not filed it separately.
Takeaway
Nobody involved did anything stupid.
Lamb’s 2017 patch was legitimate packaging hygiene. Whoever added zfree(cwdp) was fixing a real leak and picked the wrong deallocator — pushed there by free() being deliberately deprecated. zuiderkwast spotted the mismatch a year ago and diagnosed it correctly; he just underestimated the consequence. Copying Debian’s patches into the release pipeline was the pragmatic move, and Debian’s packaging quality is famously good.
Every step was reasonable. The result sat quietly across five product lines and four distributions.
Packaging patches are where bugs hide. They can be absent from upstream CI, upstream code review, and the source history users normally inspect. They get copy-pasted across projects (Redis → Valkey) and across organizations (Debian → Valkey’s own pipeline), losing a little context each time.
And the reason this surfaced at all: that test case was sitting there the whole time, creating a directory named dump.rdb to force exactly this failure. The official DEB build had the regression-test commands commented out, so this test did not run there.
Packaging is dull work. Run the tests anyway.
Postscript: a question at PGConf
At PGConf this year I gave a talk called Extension for Everyone. Afterwards Christoph Berg, who maintains the PGDG APT repository, asked me a good question:
How do you actually test all these packages?
Pigsty maintains packaging for a few hundred extensions and components. The packaging repos alone carry over a hundred patches, a good share of them fixing small, fiddly details. One person cannot hand-verify every path in every package. There isn’t enough time.
My answer: beyond whatever tests the package ships with, I have Codex run a smoke pass — model how the software actually gets used in production and try to hit the things that break.
It turns up a lot. This bug is the biggest thing it has found so far.
Which is worth sitting with for a moment: why did this survive so long?
Valkey is not an obscure project anymore; it’s the default Redis replacement in several distributions. Debian is about as mainstream as it gets, with famously good packaging. Valkey’s maintainers are excellent engineers — zuiderkwast diagnosed the mechanism correctly a year ago just by reading the patch. And Redis’s own packaging copies Debian’s patch the same way.
So the missing ingredient was never capability. It was patience.
Spending a full day on a footnote-grade bug in a cold error path — comparing patch states, allocators, versions, and architectures, reproducing the crash thirty times, tracing a patch lineage back a decade, checking five different search endpoints to confirm nobody had reported it — does not pay off on a human time budget. It is too boring.
Which happens to be exactly the kind of work an agent is good at.
End to end on this one: it ran the tests, built the reproduction matrix, wrote the patch, drafted the Debian report, and worded the exchanges with the maintainers on GitHub. My job was assigning the work, pushing back, and making the final calls.
I should be clear that this is not “the AI does everything and I put my feet up”. During this investigation I had a second agent do an adversarial review of my draft at maximum effort, and it pulled out four factual errors in one pass: I had misremembered how the old Debian bug was actually fixed, FLUSHDB doesn’t reach this code path at all, “refuses every write” overstated the impact, and I had missed entirely that bookworm’s Redis is still affected today. Sending any of that to maintainers as-is would have been my embarrassment, not the model’s.
So the value isn’t that the agent gets it right the first time. It’s that the cost of making it disprove itself over and over is low enough to be worth doing — where a human would decide that six builds to chase a statistics counter isn’t worth the afternoon.
The change in pace is startling. Two years ago every step in that loop was mine to do by hand. Now I sit here handing out tasks, asking follow-up questions, and signing off — and the rest of it just runs.
Originally published on vonng.com.
1.3 - Instantly Clone PostgreSQL Databases—No Black Magic Required
Six months ago, on January 8, 2026, I wrote Git for Data: Instant PostgreSQL Database and Instance Cloning, introducing a new feature in PostgreSQL 18 and Pigsty v4.0: instant database cloning. With filesystem copy-on-write (CoW) and PostgreSQL 18’s new file_copy_method = clone setting, you can clone a huge database in seconds while initially sharing its data blocks.
This is a particularly good fit for AI agents. As I wrote in What Kind of Database Do AI Agents Need?, ultra-low-cost database cloning is critical for counterfactual experiments. So when Pigsty 4.0 shipped, I added this capability to its PostgreSQL database provisioning workflow.
Today I saw an article from Aliyun announcing support for this feature in Alibaba Cloud RDS for PostgreSQL. I couldn’t help laughing: that took them long enough. The feature itself is not complicated. It requires no kernel patch—just enable one setting in PostgreSQL 18 and add a STRATEGY option when creating the database. But simple as it sounds, a robust implementation still has a few edge cases to handle.
A Few Improvements
Previously, cloning a database through Pigsty’s IaC-style workflow was still somewhat cumbersome: first define the clone with another database as its template, then run the database creation workflow.
So for the Pig v1.5 release, I turned database cloning into one simple command: pig pg clone. If you have a database named meta, just run pig pg clone meta, and it automatically creates a clone.
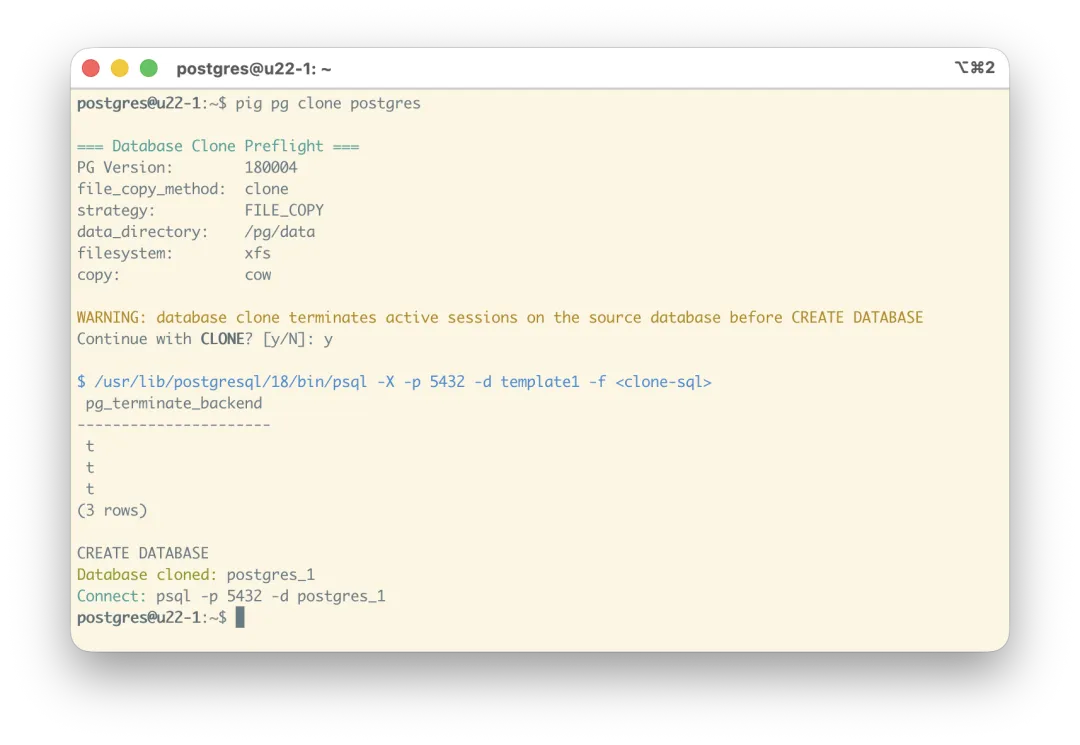
You can, of course, customize its behavior with options—for example, by specifying the branch name. If you do not provide one, Pig generates names sequentially by appending an underscore and a number.
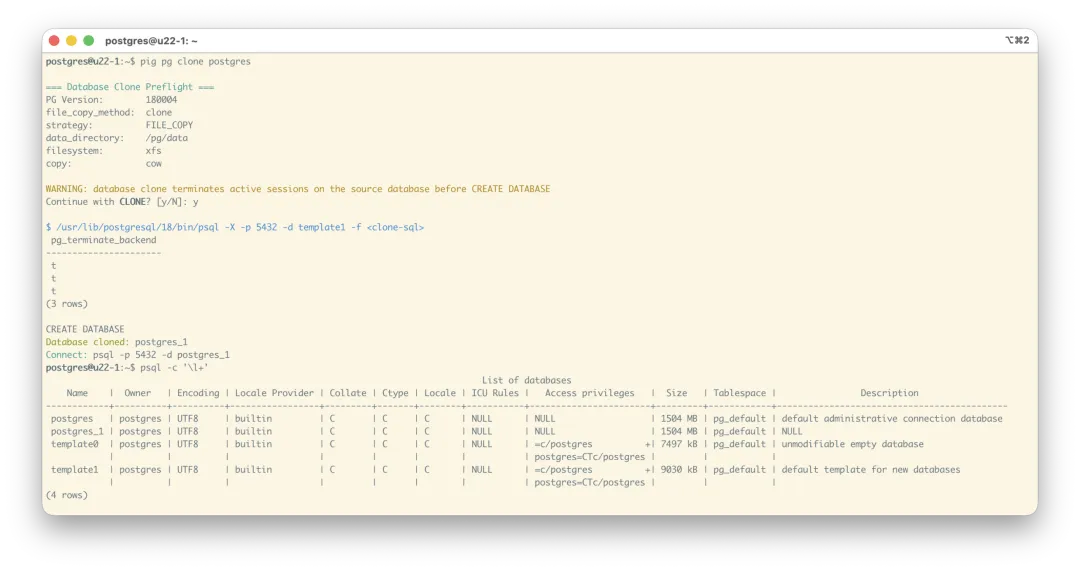
The command automatically detects whether instant cloning is both enabled and supported. At the moment, Pigsty on XFS satisfies those prerequisites. If so, Pig performs an instant clone. If not, it warns you, waits for confirmation, and performs a conventional clone instead. Use -y to skip the confirmation.
As long as the underlying filesystem supports CoW, such as XFS, cloning a database takes essentially constant time—usually a few hundred milliseconds—and initially needs only metadata space. Subsequent writes allocate new space for the modified blocks.
Agent-Native CLI
This command-line tool is built specifically for DBAs and DBA agents. You could already clone a database with an Ansible playbook or Pigsty’s /pg/bin/pg-clone shell script, but neither is as convenient as using the pig CLI directly.
For example, before executing an operation, you can use --plan to print the plan. It tells you what Pig will do and what risks are involved. You can also use -o json or -o yaml to return results in JSON or YAML.
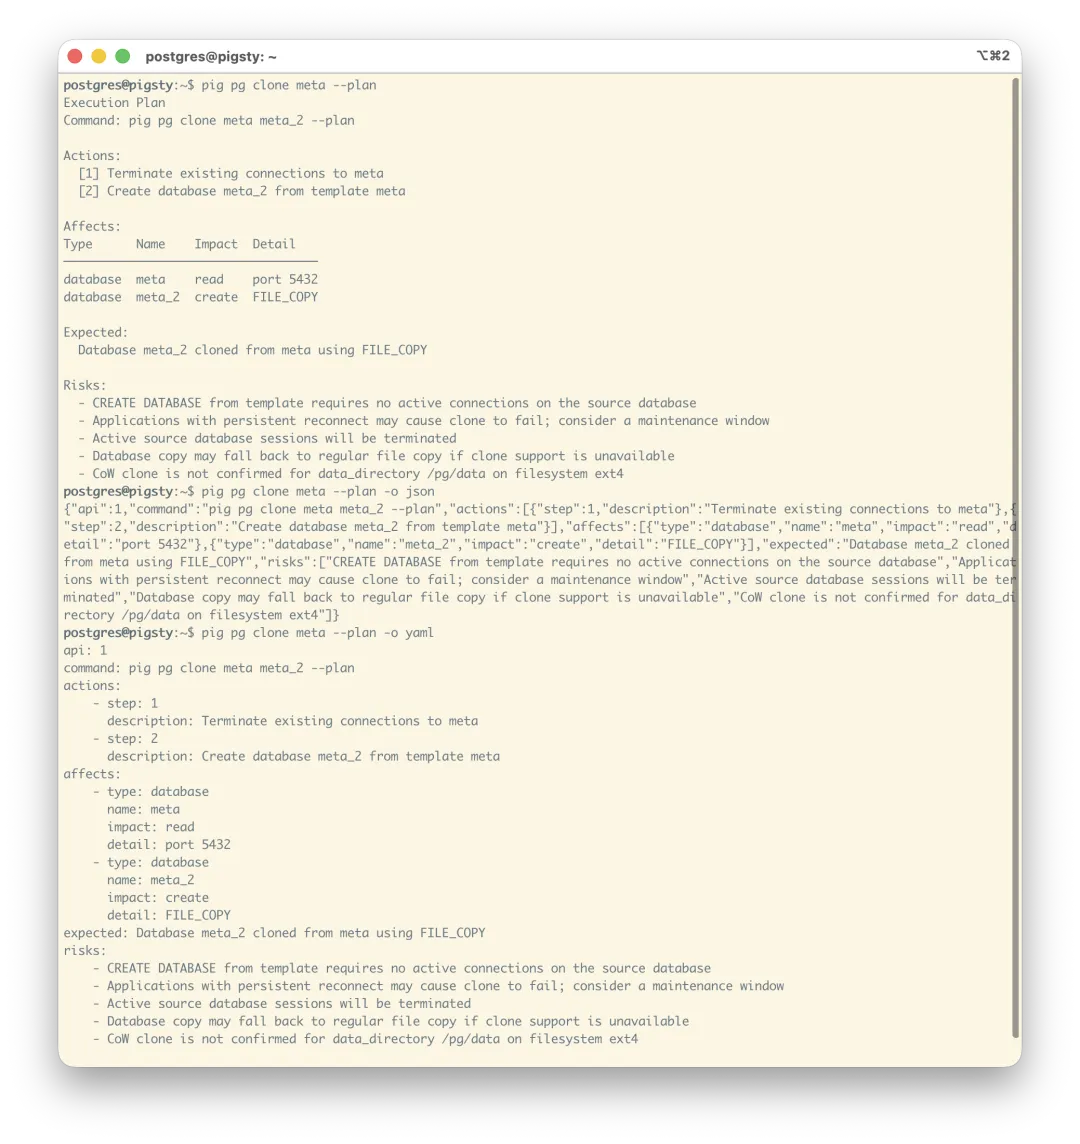
Incidentally, both normal command output and help output are available as text, JSON, or YAML. That is especially useful to agents: they can explore the CLI and retrieve exactly the structured help they need. The pg clone and pg fork commands provide structured results.
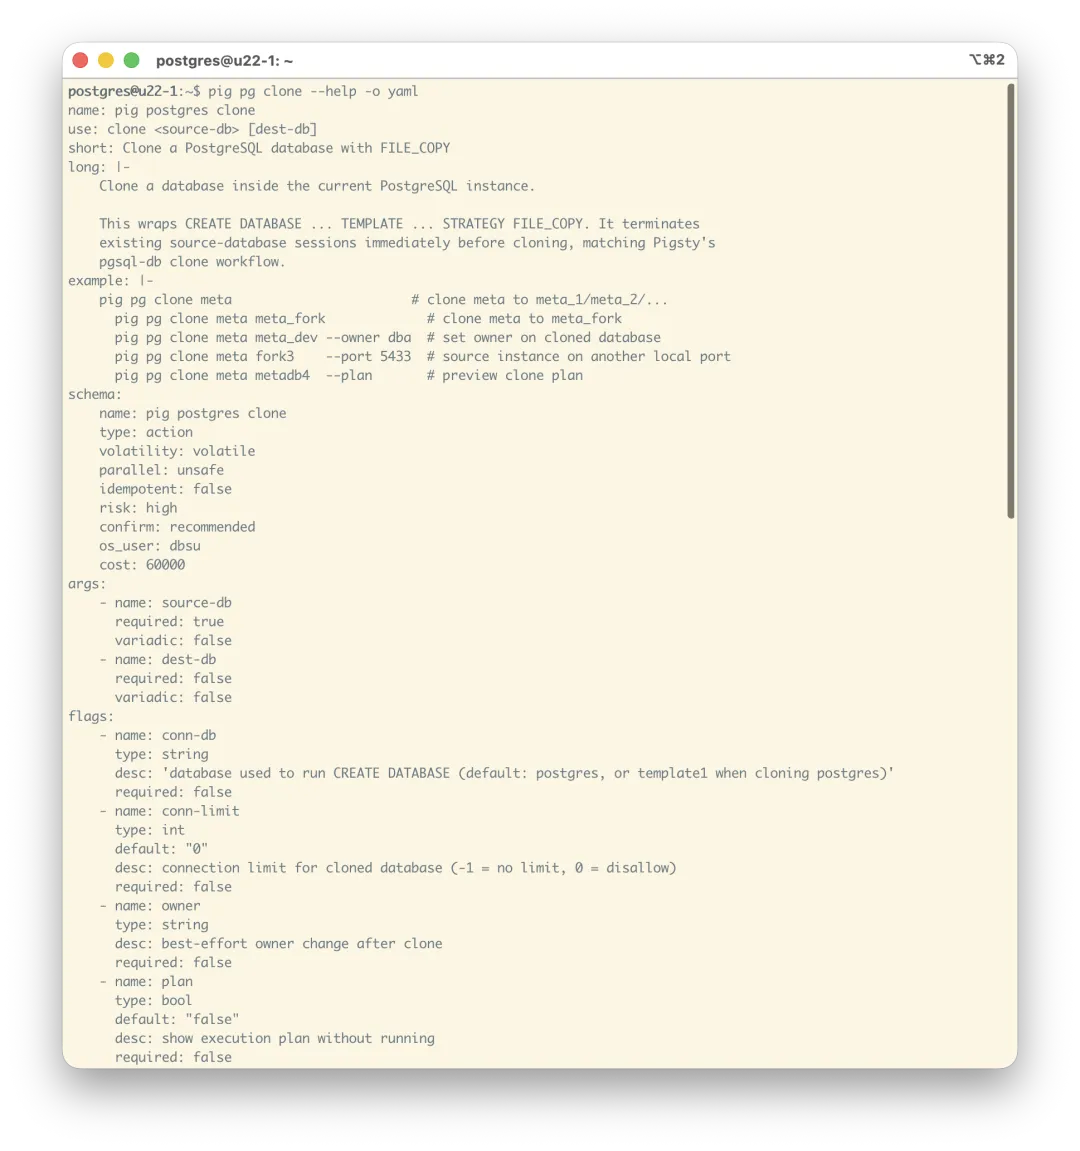
I call this design an Agent-Native CLI, and I have written about it before.
Instance-Level Forks
Database cloning is not the only related new feature worth mentioning. In Git for Data: Instant PostgreSQL Database and Instance Cloning, I also covered instant instance-level cloning, which I call a “fork.”
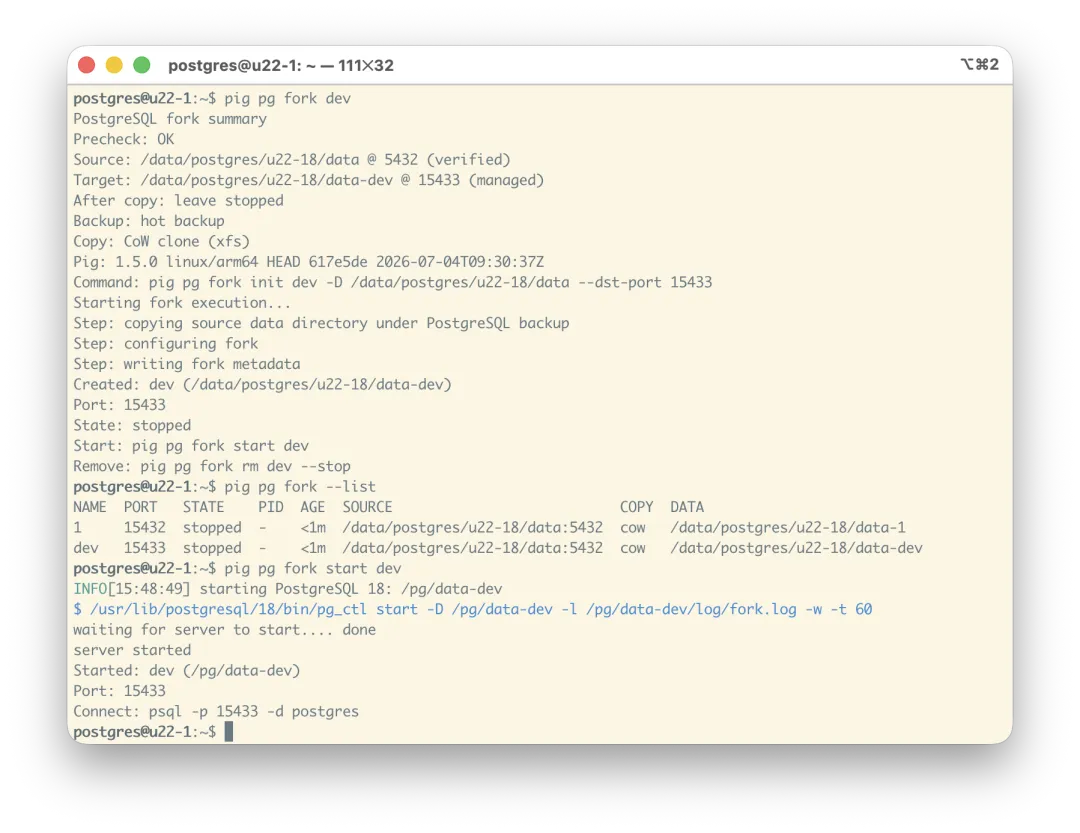
Run pig pg fork dev, and Pig creates an instance named dev from the current instance, assigning it a new random port. This is extremely useful when recovering from an accidental deletion: first create a temporary fork, then quickly run an incremental PITR on the fork to roll back and validate the result. Once you know the recovery is correct, perform it on the main instance.
PITR with pig is now very convenient as well. The example below performs an end-to-end point-in-time recovery to a specific timestamp, coordinating shutdown, restore, and the subsequent startup steps. You can still use pig pgbackrest when you want precise control over every operation.
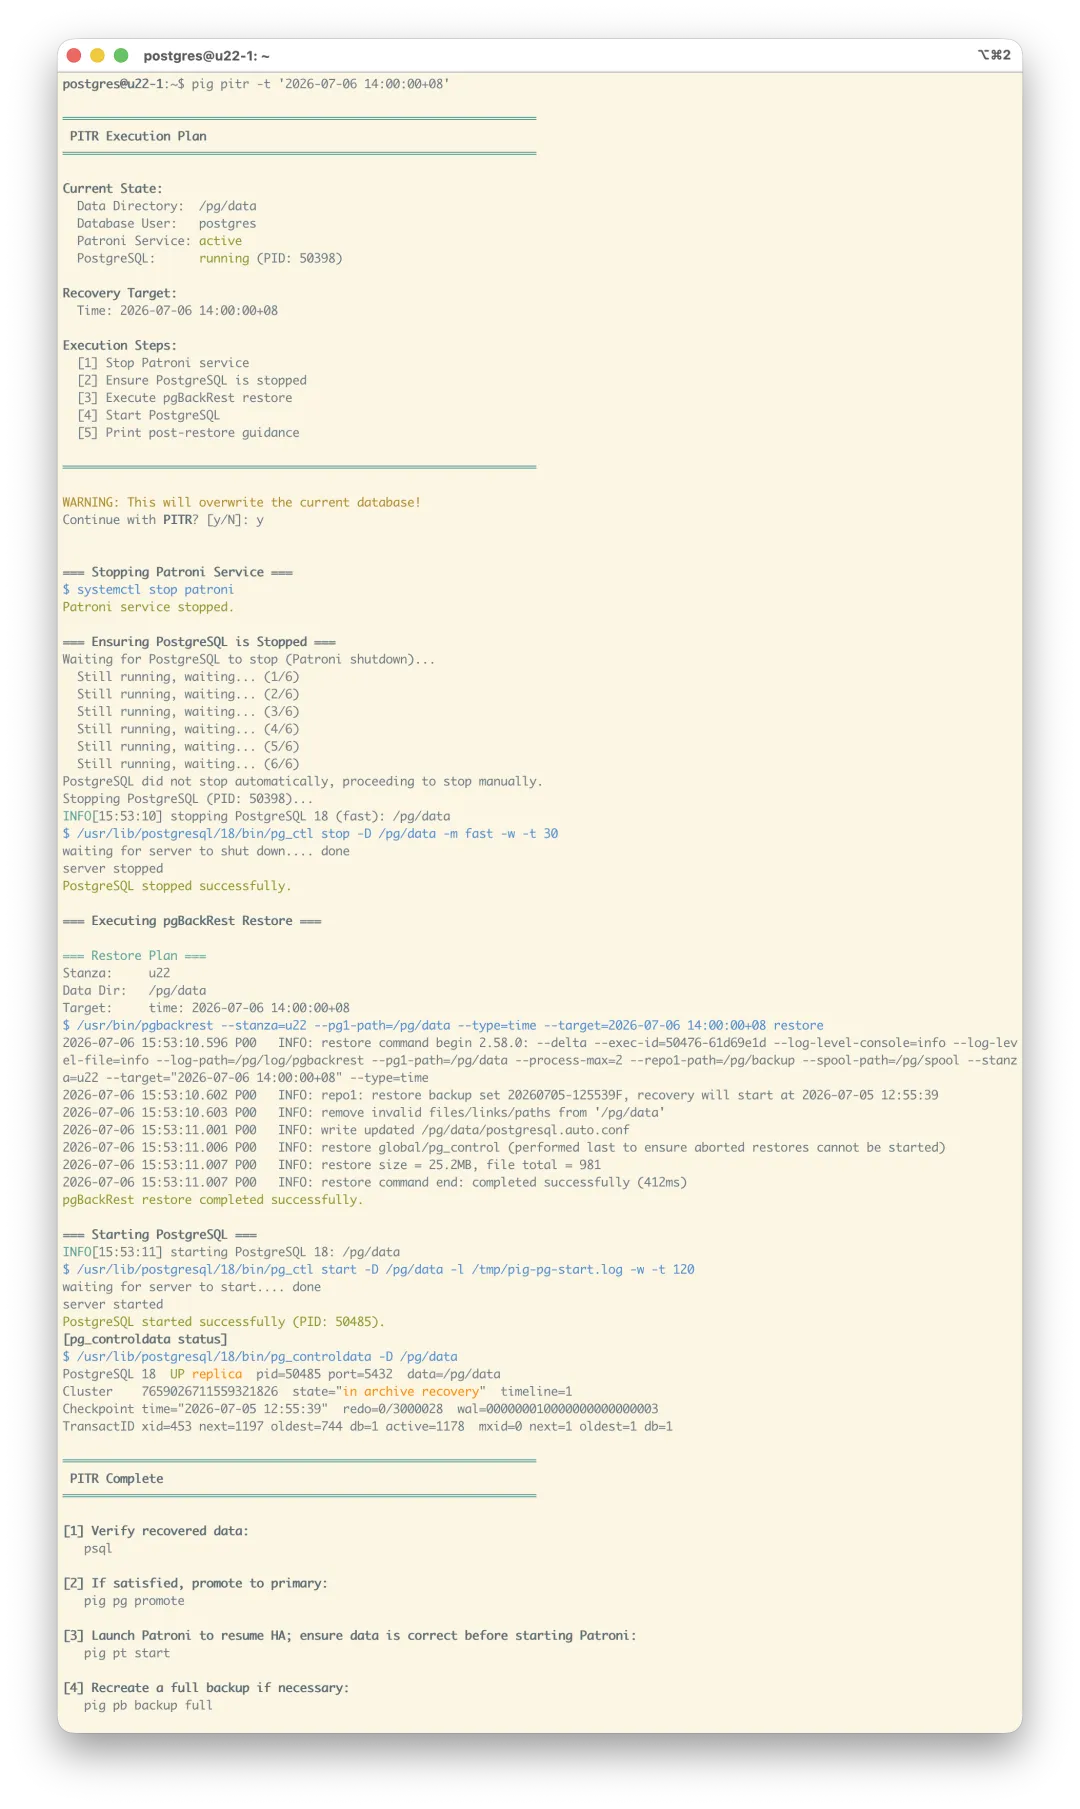
This release of the pig CLI adds many management features, including operations for PostgreSQL, Patroni, and pgBackRest. They are now all exposed as Agent-Native CLI commands like pg clone and pg fork, making them equally convenient for human DBAs and AI agents. I will write a dedicated article about them in a few days.
Further Reading
- Git for Data: Instant PostgreSQL Database Cloning
- Put Your AI Agent’s State in a Database
- What Kind of Database Do AI Agents Need?
Originally published on vonng.com.
1.4 - What Is a PostgreSQL Distribution?
People often ask me: what exactly is Pigsty?
My usual answer is: a PostgreSQL distribution.
The next question is usually: what, then, is a “PostgreSQL distribution”?
That is a good question. And the best place to begin is not databases, but operating systems.
I. Start with Linux Distributions
When most people hear “distribution,” they think of Linux distributions: Red Hat, Debian, Ubuntu, SUSE, Arch, and so on. But if Linux already exists, why do we need Linux distributions? What exactly is the relationship between the two?
The distinction is simple: the Linux project develops the kernel; a distribution assembles the operating system around it.
Compile the Linux kernel and you still do not have a usable machine. There is no shell, init system, C standard library, coreutils, package manager, networking toolkit, user space, or security-update policy. The kernel schedules hardware and exposes system calls, but an industrial-scale gulf separates that from “a usable operating system.”
Someone has to bridge that gulf, and there are countless ways to do it. glibc or musl? systemd or OpenRC? apt, dnf, or pacman? A release every six months, or rolling releases? What should the default security policy be? How are packages signed? How are vulnerabilities patched? How long are versions maintained? Which services are enabled by default? The accumulated answers to those questions are what make a distribution.
A distribution, then, does not merely deliver a kernel. It delivers an integrated set of decisions—and the credibility of an organization willing to stand behind those decisions over time.
Nobody says Debian, Red Hat, and Ubuntu are competing with Linus over who writes the better kernel. They compete at a different task: turning a shared kernel into a system that is more reliable, consistent, and easier to ship.
The shared kernel gives distributions a common foundation. Their integration, release, and maintenance work turns it into a usable system.
That is the key to understanding PostgreSQL distributions.
II. Apply the Analogy to PostgreSQL—Carefully
PostgreSQL is often described as the Linux kernel of the database world. But if you map the Linux analogy directly onto PostgreSQL, it breaks almost immediately.
PostgreSQL is not the Linux kernel. Compile PostgreSQL from source, run initdb, and start the server; you have a working database. The SQL engine, transactions, MVCC, WAL, replication protocol, psql, and client libraries are all there.
The official PGDG repositories also ship prebuilt binaries that users can install and start directly.
The Linux kernel is not useful on its own, but the PostgreSQL kernel can run independently. That raises an obvious question: if PostgreSQL already works by itself, what problem is a PG distribution supposed to solve?
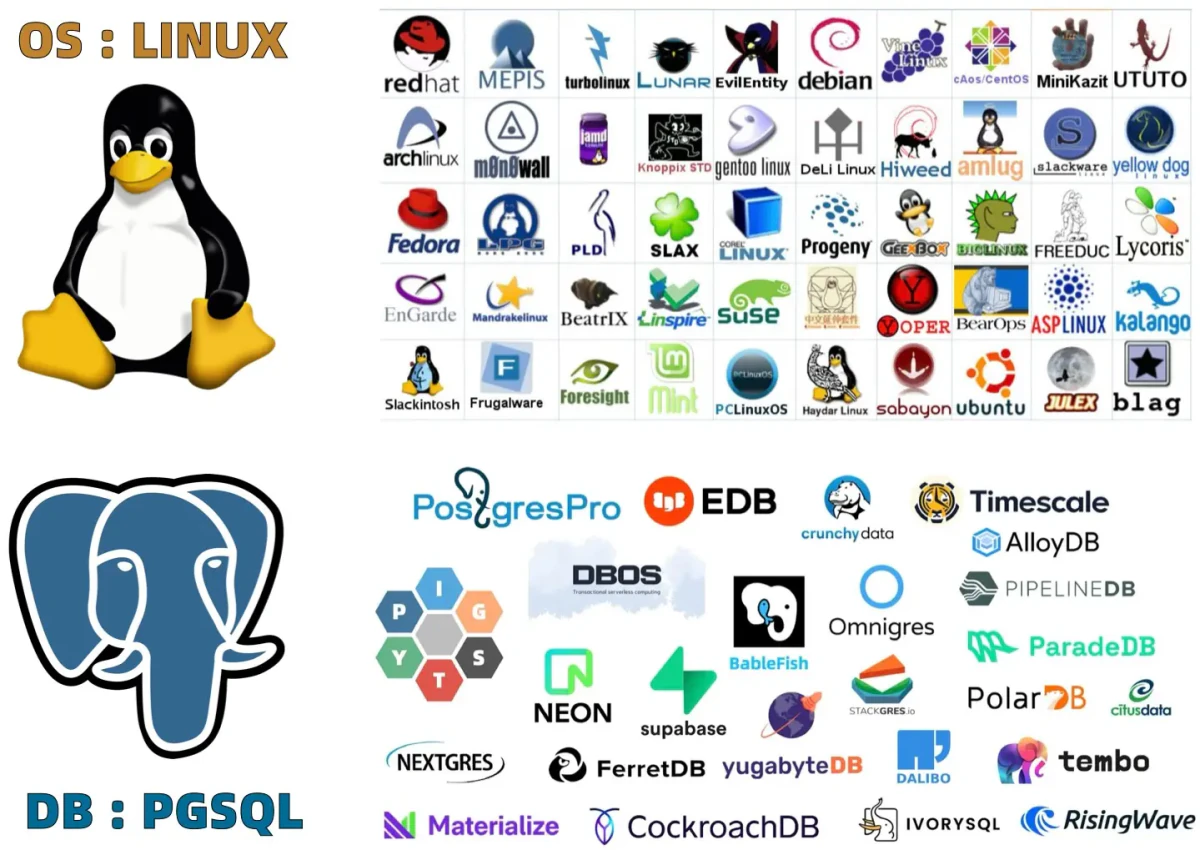
A standalone PostgreSQL instance is an excellent database kernel. A production system, however, needs more than “it starts.” If the primary fails, what takes over? Who notices when a backup is corrupt? Can you recover to a point before data was accidentally deleted? How does the connection pool redirect traffic? How are certificates rotated? How are metrics collected and alerts evaluated? How are extension versions managed? How is configuration drift corrected? How do upgrades work? How is a new replica provisioned? After recovery, what closes the loop and returns the system to a healthy steady state?
Neither initdb nor yum install postgresql answers those questions.
That is where a PG distribution earns its keep. It does not turn PostgreSQL into a usable database—PostgreSQL already is one. It integrates the PostgreSQL kernel into a production-ready data service.
III. The Three Layers of a PG Distribution
A serious PG distribution has at least three jobs: selection and integration, build and distribution, and orchestration and control.
All three matter, but their marginal value is not equal. The further down the list you go, the closer you get to the real battleground.
1. Selection and Integration: Make Decisions for the User
Production PostgreSQL is not a bare postgres process. You need backups, high availability, connection pooling, monitoring, logging, alerting, object storage, extensions, an access-control model, and sensible defaults. Every category offers a long list of choices.
For backups, you might use pgBackRest, Barman, WAL-G, pg_basebackup, or a hand-rolled script built on PostgreSQL’s backup primitives.
For high availability, there is Patroni, repmgr, Pacemaker, or even Pgpool-II pressed into service for primary/standby failover. Monitoring might mean Prometheus, VictoriaMetrics, Grafana, Zabbix, or any number of combinations.
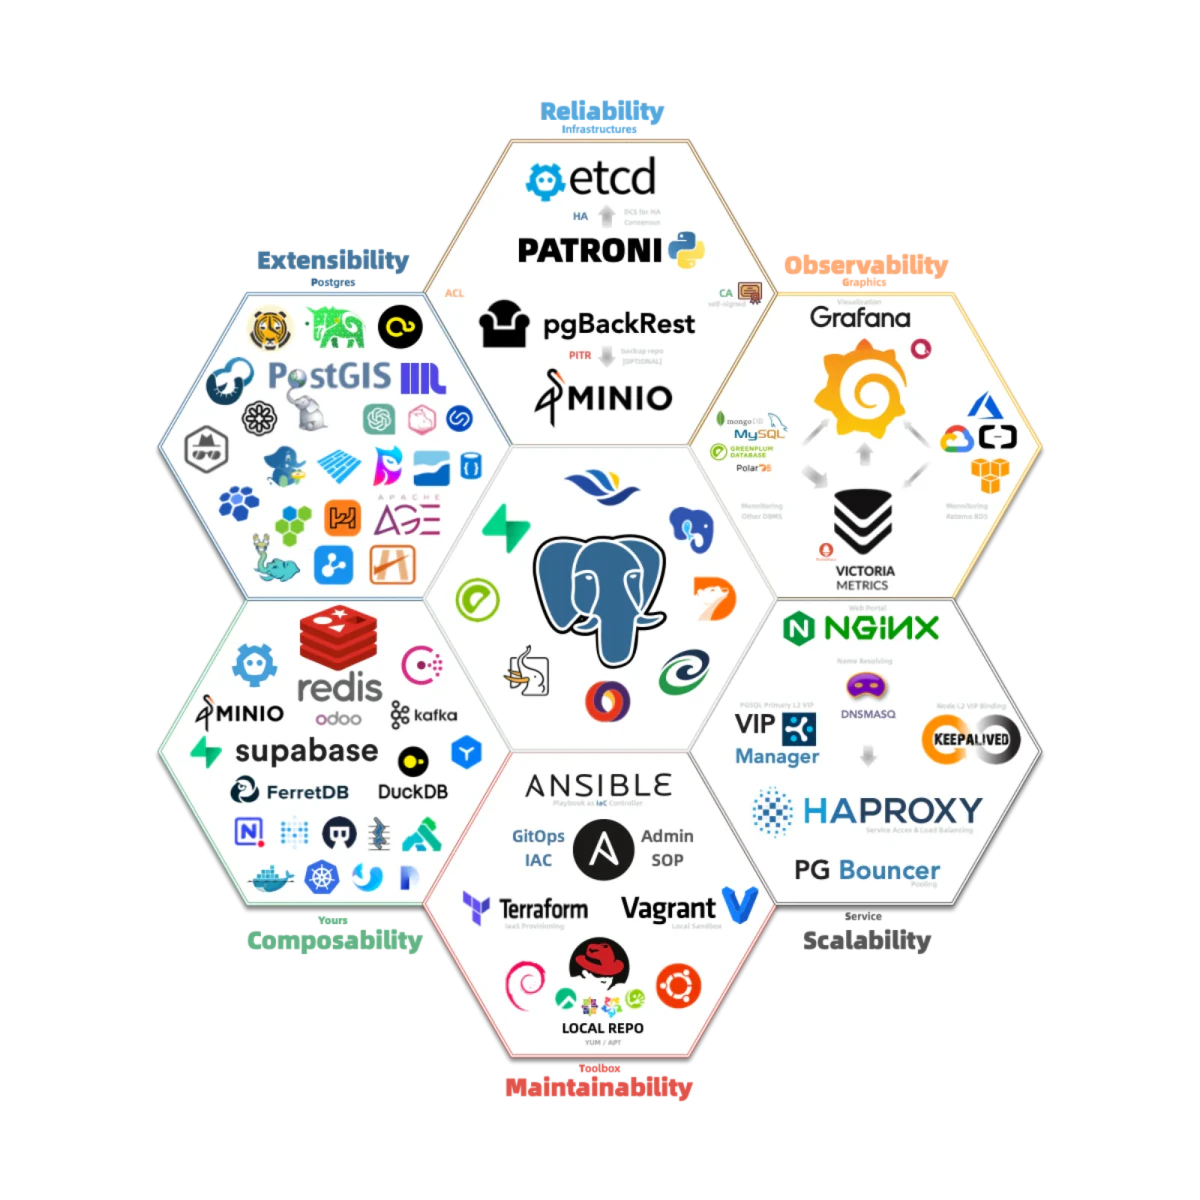
This layer tests a distribution author’s judgment, experience, and sense of responsibility. Being opinionated does not mean making arbitrary choices for users. It means having learned from enough failures to know which paths are sound—and which are better.
To be fair, differentiation at this layer is narrowing. Good tools used for long enough tend to produce community consensus: Patroni is increasingly hard to avoid for HA, pgBackRest for backups, and combinations such as Prometheus and Grafana for monitoring. Selection still matters, but “I chose the right components” is no longer much of a moat by itself.
Choosing well is not enough. You also have to deliver those choices reliably.
2. Build and Distribution: A Supply Chain Is Trust, Not a Gimmick
The second layer is build and distribution. It is often underestimated because users see a package name, not the unglamorous work behind it: multiple operating systems, architectures, versions, and extensions; dependency resolution; ABI compatibility; GPG signing; CVE response; repository availability; and version lifecycle management.
PGDG already provides a formidable piece of public infrastructure. Its YUM and APT repositories deliver prebuilt PostgreSQL binaries, more than a hundred extensions, and several critical ecosystem components. It is an excellent commons.
Precisely because that commons is so good, differentiation at the build-and-distribution layer requires something more. Pigsty’s own repository, for example, fills in a large part of the missing extension catalog—another 300 extensions—along with infrastructure packages. It ships native RPM and DEB packages across 16 Linux OS-and-architecture combinations and has been maintained continuously for almost four years.
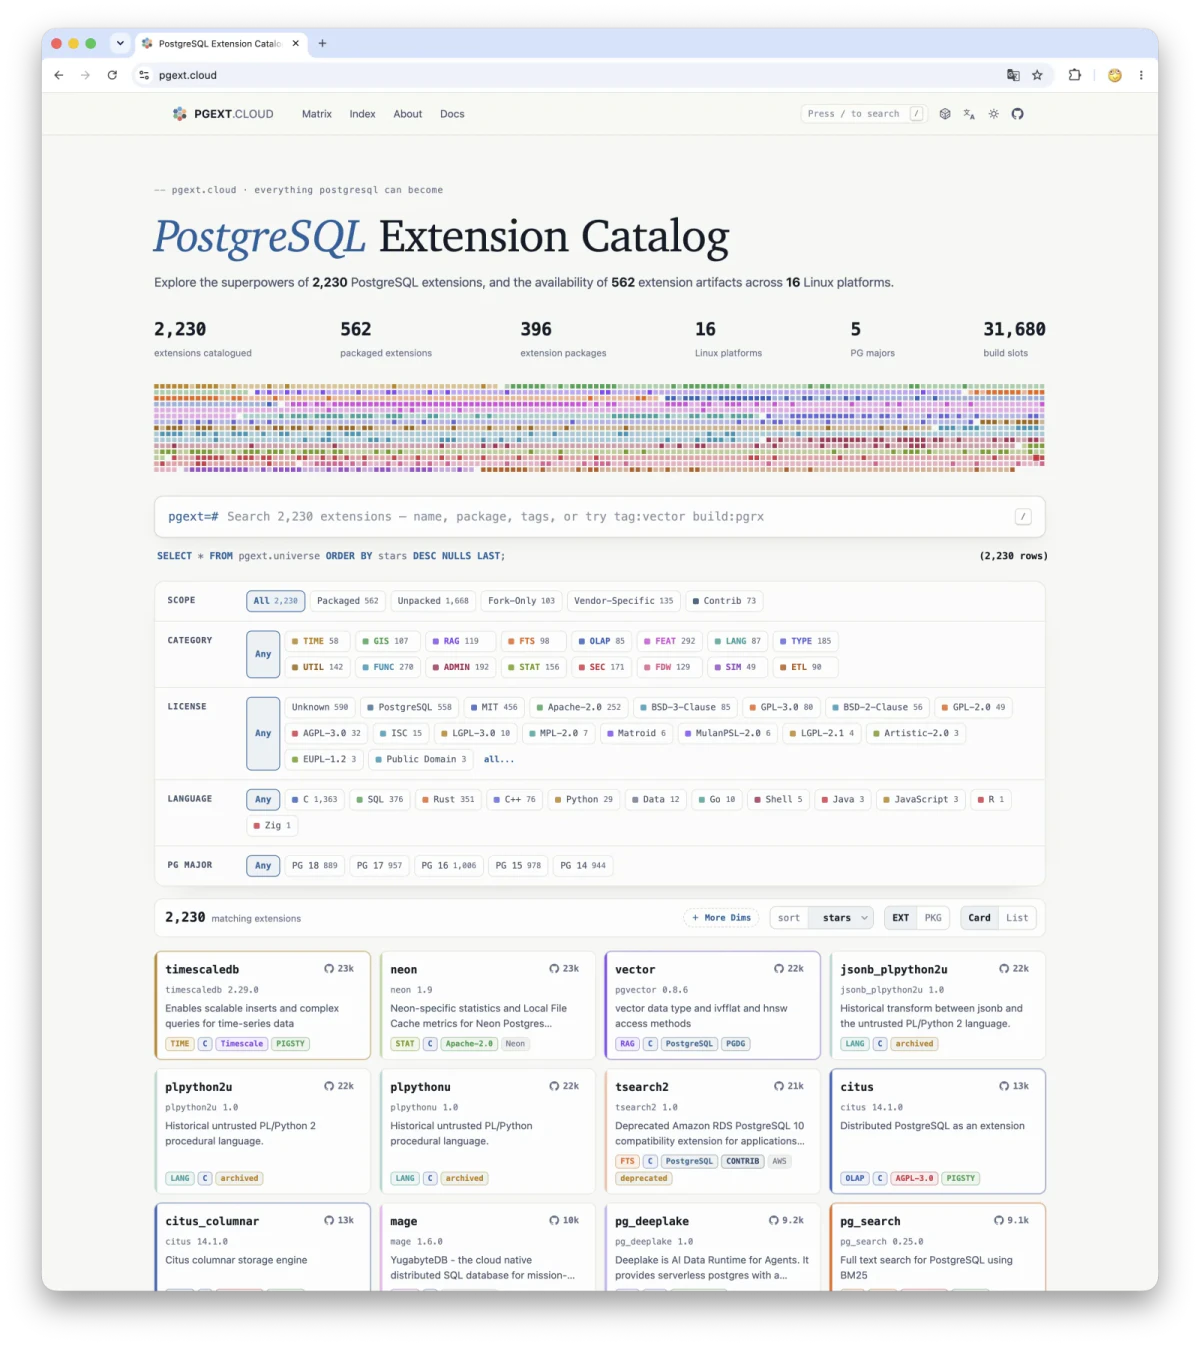
Long-term credibility in packaging, fast patching, a stable supply chain, and a sustained track record of reliable maintenance do form a barrier—and that barrier compounds over time. But this is a defensive capability. It can make users comfortable basing production systems on your repository, yet by itself it rarely explains why they must choose you.
What truly separates a distribution from an “install some packages” script is the next layer: orchestration and control.
3. Orchestration and Control: Turn Static Packages into a Living System
The hardest part of a distribution is orchestration and control. Judgment about component selection is converging, while build and distribution are largely defensive. Orchestration and control are where implementations are tested against one another in the real world. The challenge fits into one sentence: How do you turn all these static packages into a dynamically running service?
Think of a software repository as a supplier of flour, eggs, and butter. It does not bake them into a cake. Even if every package comes with a detailed recipe—that is, documentation—you are still a long way from a finished cake. And some production systems do not merely need a cake; they need an automated cake factory.
The gap between many established open-source distributions and cloud RDS offerings lies precisely in this last mile. One gives you a collection of installed packages. The other sells a ready-to-use service with automated operations and self-healing. The indispensable step between them is orchestration.
Orchestration is the act of “cooking”: turning something static, like software on a DVD, into a live, dynamic system. It must handle everything the PostgreSQL kernel leaves behind after initdb, and everything a package repository never attempts to manage: which components start in what order and what depends on what; how a failed primary is detected, a new leader elected, traffic redirected, pooler connections reestablished, and a replacement replica provisioned—the entire closed loop of failure recovery; and, most importantly, how the whole system remains at its declared desired state and automatically corrects any drift.
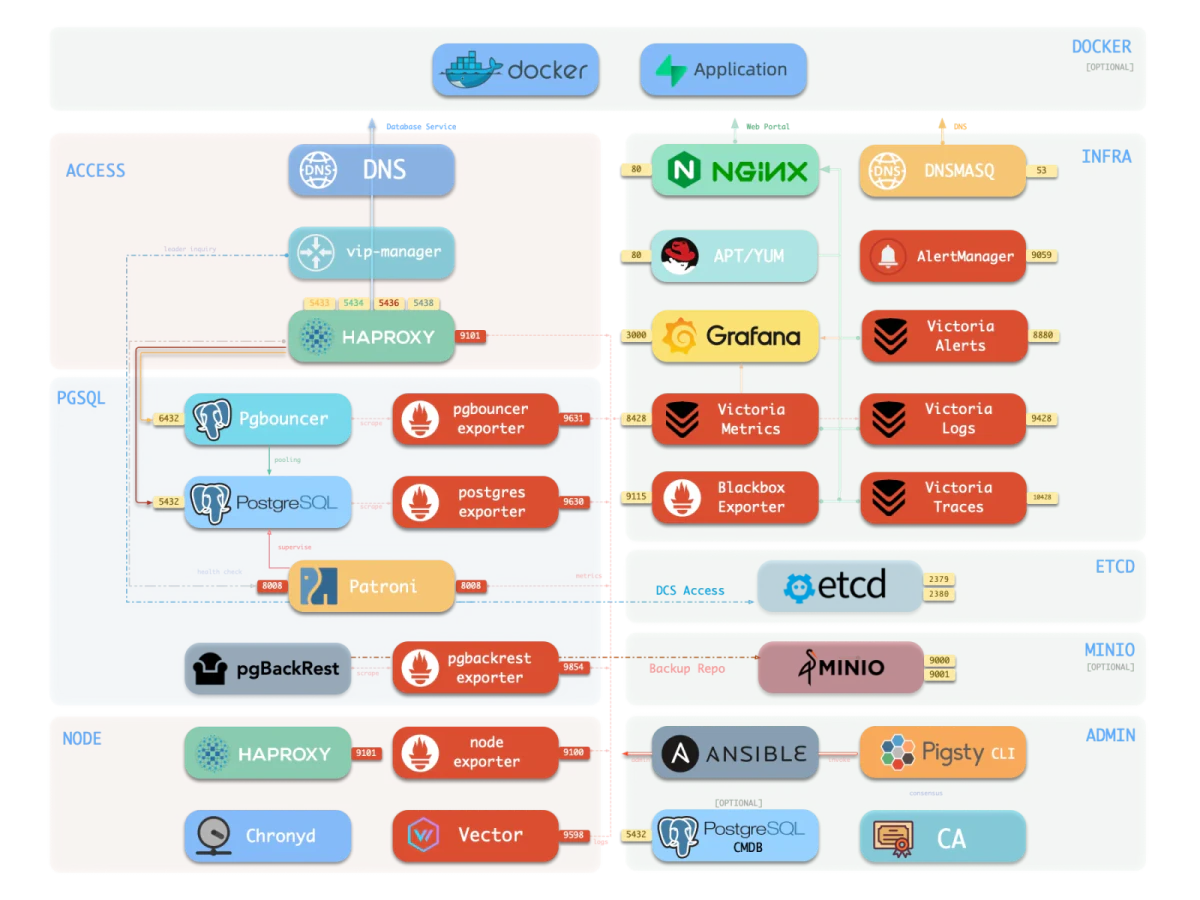
Orchestration and control still require substantial integration. Kubernetes, Patroni, and Ansible provide shared building blocks, but each distribution must connect them into a complete operating procedure.
IV. Two Paths to Orchestration: Kubernetes-Native and Linux-Native
Once orchestration becomes the central problem, the question is: at what layer should the control plane live?
There are two mainstream answers, and they define the two principal tracks for PG distributions today. The essential distinction is where orchestration and control are implemented: one path builds on Kubernetes as a common substrate; the other returns to the Linux operating system and builds upward from there. Neither is universally better. They make different tradeoffs.
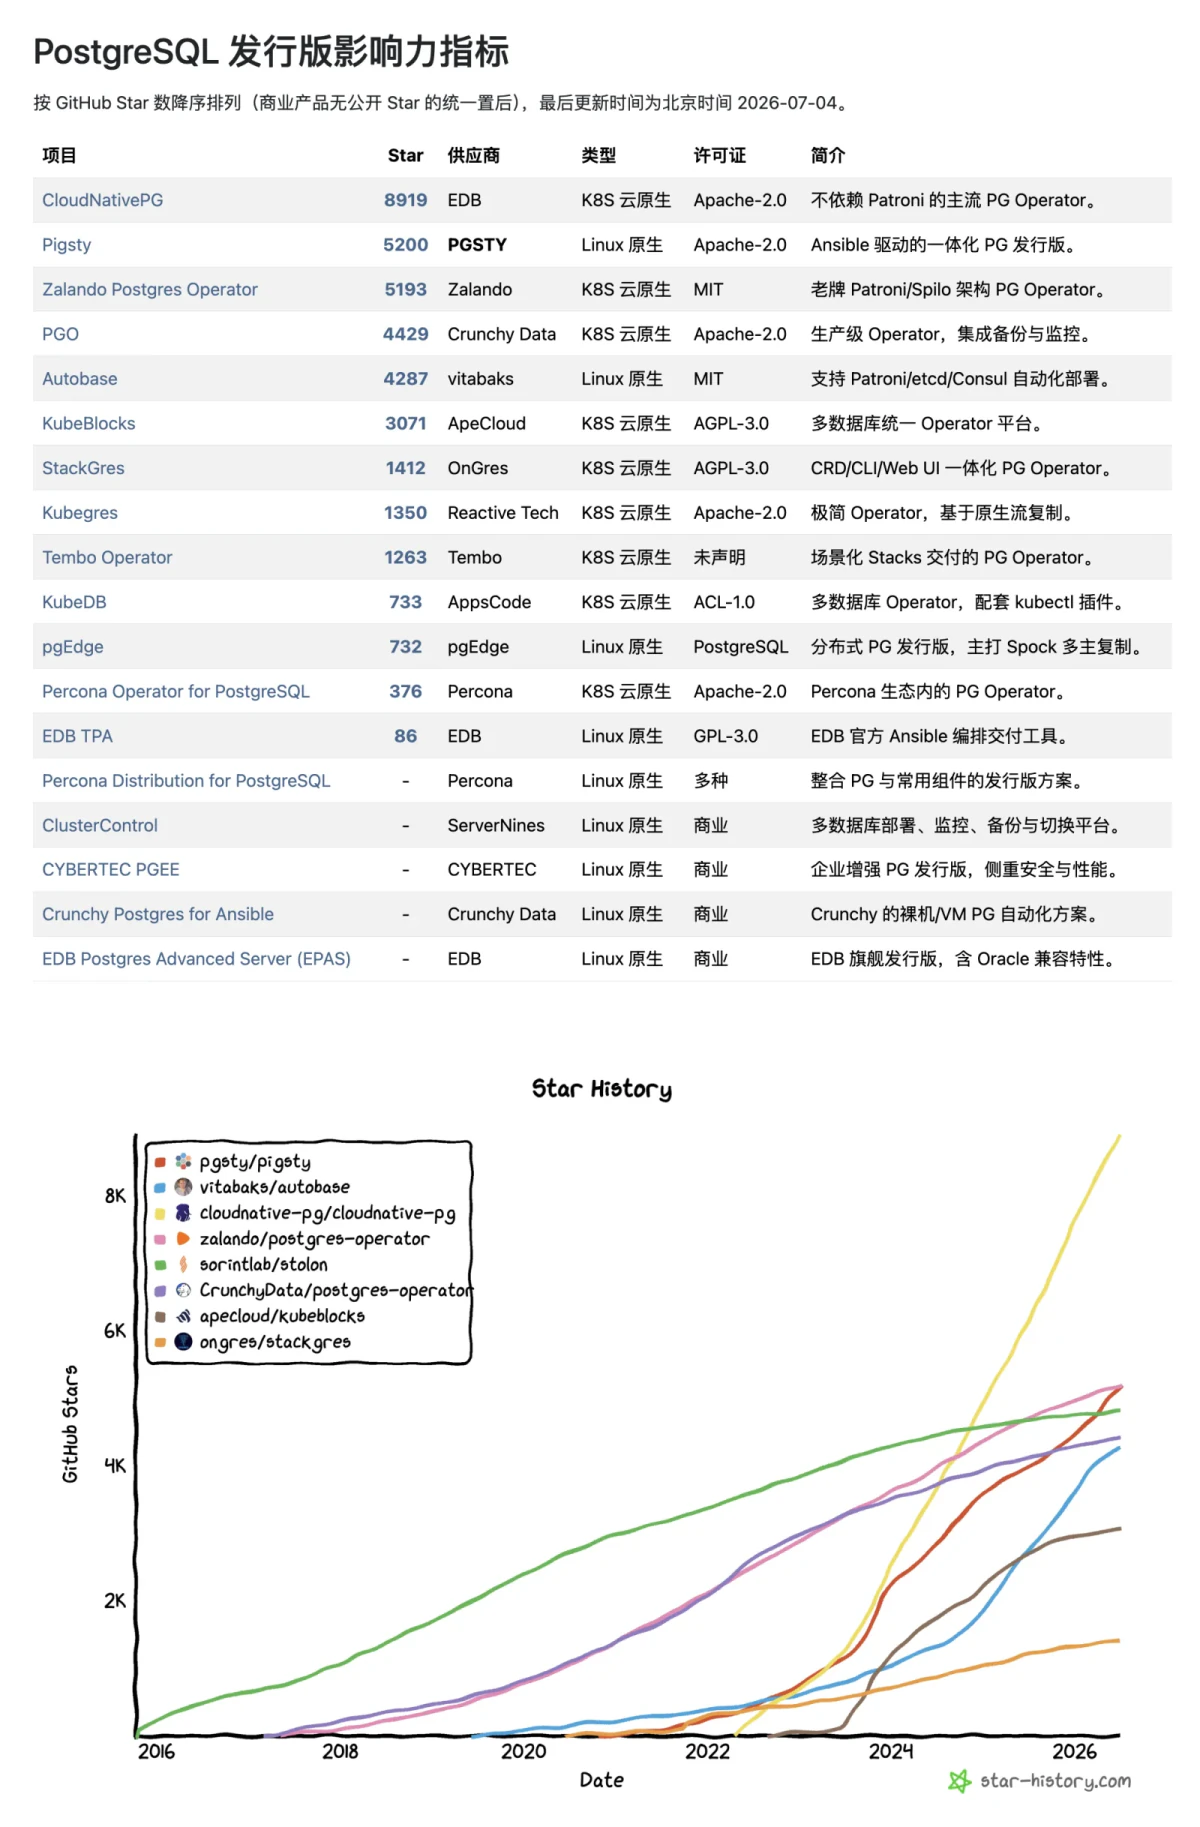
The GitHub star counts below are from July 4, 2026.
Path One: Kubernetes-Native
This path treats the database as a first-class citizen on Kubernetes and uses the Operator pattern for orchestration. You submit a declarative custom resource defined by a CRD, and the Operator’s reconciliation loop continuously drives actual cluster state toward the desired state. Provisioning, monitoring, failover, and scaling all happen at the Kubernetes layer.
This is the busiest and most crowded track. Its players include CloudNativePG, led by EDB, with roughly 8,900 stars; the Zalando Postgres Operator, with about 5,200; Crunchy PGO, with about 4,400; KubeBlocks, with about 3,100; and a longer list including StackGres, Kubegres, Tembo, KubeDB, and the Percona Operator.
The advantages are clear: a unified control plane, a declarative API, smooth GitOps integration, and an easy interface for platform teams. For organizations that already treat Kubernetes as their operating system, putting databases on Kubernetes is a natural extension.
The cost is equally clear. You are not merely adding a PG Operator. You are adopting the entire Kubernetes control plane, storage and network abstractions, scheduling model, authorization model, failure model, and cognitive load. The real entry cost is not the Operator itself, but whether your organization has already paid the Kubernetes tuition.
Path Two: Linux-Native
This path does not put the database inside Kubernetes. It returns to the operating system: run directly on Linux, on physical or virtual machines; install RPM or DEB packages; manage services with systemd; and drive administration with Ansible or a similar infrastructure-as-code tool.
The Linux-native open-source projects include: Pigsty, with roughly 5,200 stars; Autobase, with about 4,300; pgEdge, with about 700; and EDB TPA, with about 90. Percona Distribution for PostgreSQL also provides an open-source stack with commercial support. Commercial products include EDB Postgres Advanced Server, CYBERTEC PGEE, and the ClusterControl management platform.
The advantages are fewer infrastructure layers and direct use of familiar Linux tools. DBAs can inspect the processes, files, and services themselves. The cost is that Kubernetes is no longer providing desired-state reconciliation, idempotent execution, failure recovery, or upgrade orchestration. You have to implement those capabilities yourself while also confronting the differences across more than a dozen major versions of mainstream Linux distributions. It is continuous, unglamorous work.
Pigsty’s Choice
Both paths are reasonable. The right one depends on where your team already stands and where it makes sense to place the complexity. Pigsty chose the Linux-native path. I have explained the reasoning at length in Should Databases Be Deployed in Kubernetes? and Is Containerizing Databases a Good Idea?. My view is that this path better fits the nature of databases. It is difficult, but correct.
Among the projects listed here, Pigsty has the most GitHub stars on the Linux-native track and ranks second overall, after CloudNativePG.
In my own queries to mainstream AI models about self-hosting PostgreSQL on Linux, Pigsty often appears among the first recommendations. For a project led by an independent developer and unaffiliated with any cloud vendor, reaching that point has not been easy.
V. One Step Further: A Meta-Distribution
The story could end there. But Pigsty does something else that pushes at the boundary of the term “PG distribution.”
The industry usually assumes that a distribution is built around one fixed kernel. Debian and Red Hat are built around Linux. Traditional PG distributions are built around the vanilla PostgreSQL kernel. A distribution and its kernel are almost inseparable.
The PostgreSQL world, however, contains some unusual variants. OrioleDB replaces the storage engine. Babelfish adds SQL Server protocol compatibility. PolarDB for PostgreSQL implements a RAC-style architecture. IvorySQL supports Oracle syntax. openHalo is MySQL-compatible, while Percona TDE adds transparent encryption. These projects modify the PG kernel. Strictly speaking, they are no longer “pure PostgreSQL,” but distinct species and subspecies within the PG-compatible family. Traditionally, every variant would need to build its own operational stack.
Pigsty takes another approach: extract the orchestration and control foundation, and make the kernel itself a replaceable layer. This is the natural consequence of taking the third layer far enough. Once the control plane is sufficiently flexible and no longer hard-wired to a specific kernel, replacing that kernel becomes a matter of swapping a build artifact and a configuration template. We build binary packages and provide configuration templates for these different PG forks, allowing users to run different kernels on the same foundation. At the time of writing, Pigsty offers more than a dozen kernel and application-stack configurations.
In that sense, Pigsty is no longer merely a “PostgreSQL distribution.” You can use it to derive a distribution of your own: an IvorySQL distribution, a PolarDB distribution, or a TDE distribution. By combining modules, you can even turn it into a distribution for Redis, Etcd, or MinIO; for Prometheus or VictoriaMetrics; or even for Claude Code and Codex.
More precisely, it is a meta-distribution: a distribution for building distributions. A foundation that can be repeatedly tailored, reused, and redistributed is itself a transferable capability. It no longer belongs to one kernel, or to one person.
The following examples use the Pigsty configuration layout from July 2026:
Epilogue: A Distribution Is a Supply Chain of Trust
Return to the original question: what is a PostgreSQL distribution?
At the technical level, it has three core jobs. Selection and integration make the right decisions on your behalf. Build and distribution deliver the artifacts created by those decisions. Orchestration and control turn those static packages into a living, self-healing system.
But the real soul of a distribution lies beneath those three technical layers.
Technology can be copied. Component choices can be imitated, packages can be rebuilt, and anyone willing to invest enough time can reproduce 70 or 80 percent of the orchestration. Two things cannot be copied—and determine whether a distribution can be trusted for the long term: a community that continues to use and maintain it, and the trust that grows from that work over time.
Users do not merely need an answer to “Which package should I install?” They need answers to harder questions. Whose packages do I trust? Whose defaults? Whose extension builds? Whose HA decisions and backup-recovery process? Who patches a CVE promptly? Who will still maintain this path five years from now? When configuration drifts, a failover occurs, a version is upgraded, or data must be restored—at the moments that matter most—who can bring the entire system back under control?
The answers point not to a piece of code, but to the person and community that continue to take responsibility for it. The essence of a distribution is to gather responsibilities scattered across source code, builds, signatures, repositories, extensions, configuration, orchestration, monitoring, upgrades, and disaster recovery into a supply chain of trust that can be verified, reproduced, audited, and relied upon over the long term. Trust accumulates as promises made along that chain are honored again and again. It cannot be bought or copied. Only a community can grow it over time.
Cloud services provide trust too, but they hide the chain inside a black box. You buy managed trust, while surrendering transparency, portability, and ultimate control. You trust the cloud vendor to choose the right components, apply patches, maintain backups, handle failures, and plan upgrades. You also trust it not to box you in on pricing, access, ecosystem control, compliance, or availability. That is still trust. Its price is that you can no longer inspect or take over the chain yourself.
Pigsty takes another path. It does not mystify complexity or outsource responsibility to an invisible control plane. It makes the chain visible, codifies it, signs it, orchestrates it, and returns as much control as possible to the user. Pigsty is therefore not a “tool for installing PostgreSQL,” nor merely a “script for building your own RDS.” It aims to deliver an open PostgreSQL supply chain of trust: from the upstream kernel to extension artifacts, from RPM and DEB repositories to HA orchestration, from monitoring and alerting to backup and recovery, and from a single PG kernel to the entire family of PG-compatible kernels. Every link can be verified, and every link can be brought under the user’s control. Behind it stands a community willing to maintain it for the long term.
What Linux distributions ultimately accumulated was never just the technical ability to integrate a kernel into a system. It was the credibility earned by names such as Debian and Red Hat through decades of simply continuing to be there. Pigsty aims to grow that same kind of trust in the PostgreSQL world—and to keep it open, auditable, and under the user’s control.
A real distribution ultimately delivers not software, but a supply chain of trust that can be audited, reproduced, migrated, and relied upon for the long term—together with a community willing to stand behind it.
No rented cloud. No vendor worship. No putting complexity—or trust—inside anyone else’s black box.
Instead, put the ability to run a first-rate production database service back in the hands of users willing to run it themselves—along with a community willing to support it for the long haul.
Originally published on vonng.com.
1.5 - Extensions for Everyone
Slide deck: Extensions for Everyone
Part I. Introduction
0. Extensions for Everyone
Hi everyone. This talk is called Extensions for Everyone.
It is about delivering PostgreSQL extensions, and about how a shared delivery layer can benefit users, extension authors, vendors, and PostgreSQL hackers.
1. Who am I
I am Ruohang Feng, author and maintainer of Pigsty, an open-source PostgreSQL distribution.
I also build pgext.cloud, an open-source delivery layer for PostgreSQL extensions.
Over the past two years, I have been cataloging, building, packaging, and testing hundreds of extensions across PostgreSQL versions and Linux platforms. So this talk is not a theory. It is a field report.
2. Extensibility Matters
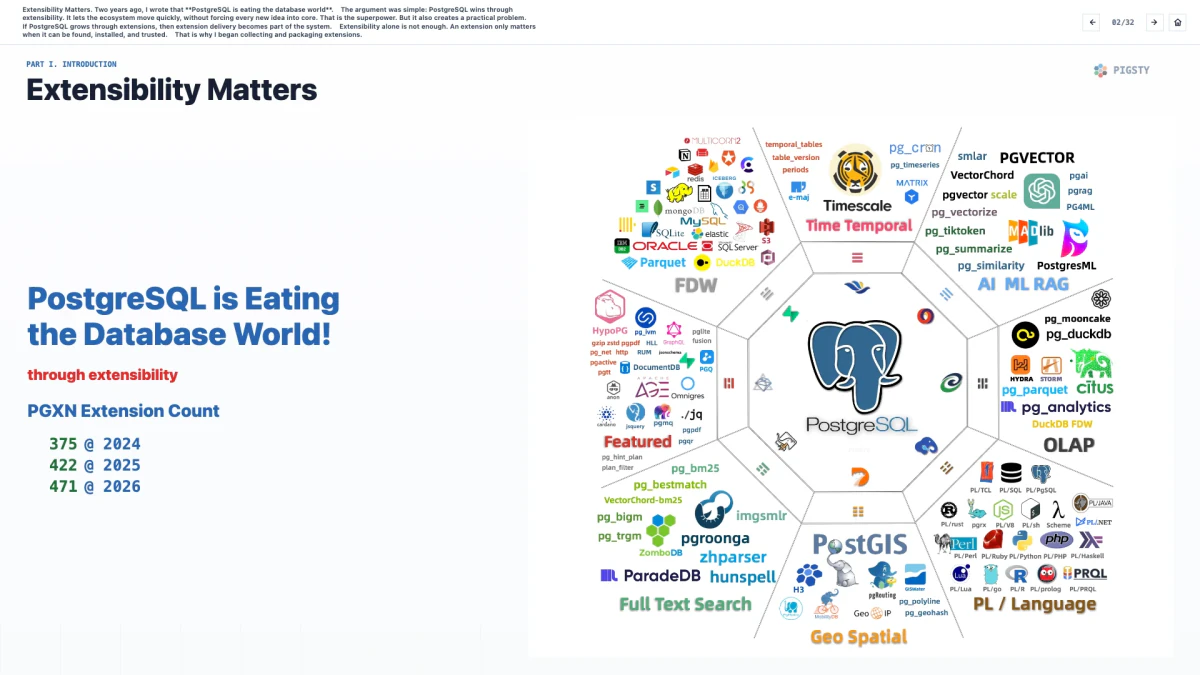
Extensibility matters. Two years ago, I wrote that PostgreSQL is eating the database world.
The argument was simple: PostgreSQL wins through extensibility. It lets the ecosystem move quickly without forcing every new idea into core. That is the superpower, but it also creates a practical problem.
If PostgreSQL grows through extensions, then extension delivery becomes part of the system.
Extensibility alone is not enough. An extension only matters when it can be found, installed, and trusted.
That is why I began collecting and packaging extensions.
3. Two Years Later
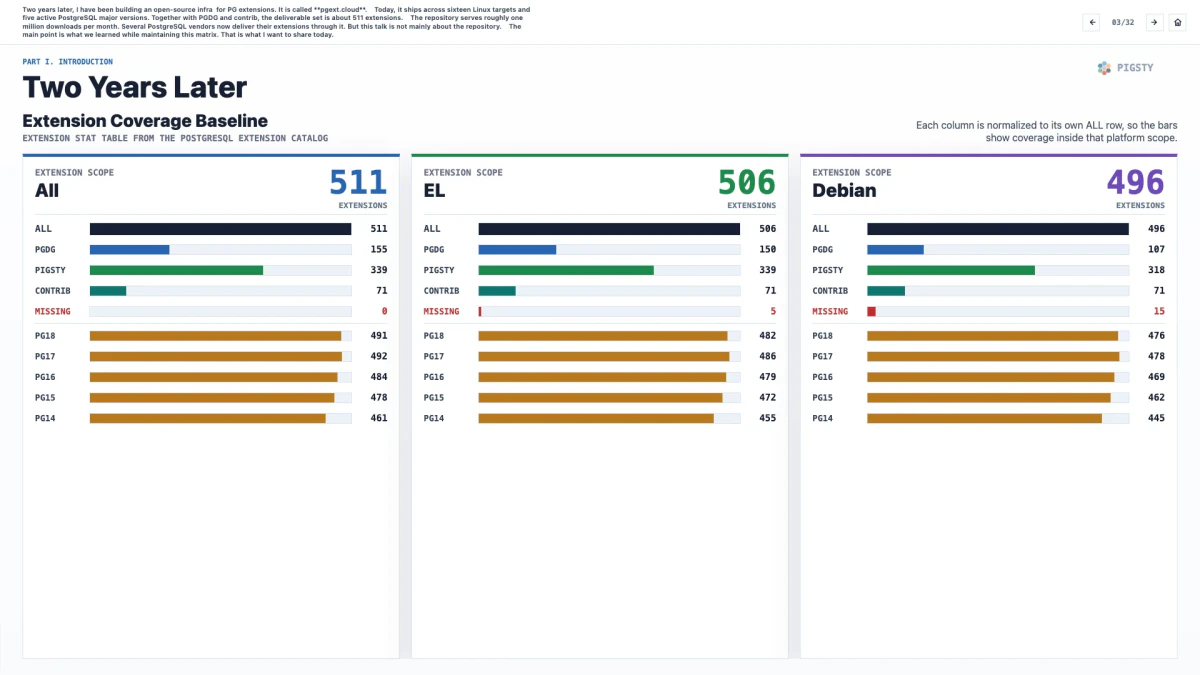
Two years later, I have been building open-source infrastructure for PostgreSQL extensions. It is called pgext.cloud.
Today, it ships across sixteen Linux targets and five active PostgreSQL major versions. Together with PGDG and contrib, the deliverable set is about 511 extensions.
The repository serves roughly one million downloads per month. Several PostgreSQL vendors now deliver their extensions through it. But this talk is not mainly about the repository.
The main point is what we have learned while maintaining this matrix. That is what I want to share today.
4. Who Benefits?
When I say “extensions for everyone”, I mean four groups of people.
First, users and DBAs. They want packages. They do not want to compile code on production servers.
Second, extension authors. They need reach, and they do not want to spend their time on build and delivery work.
Third, vendors. They need reusable components. Rebuilding the same packages again and again is a waste of engineering time.
Fourth, PostgreSQL hackers. They need signals. When compatibility breaks, extensions are often where we see it first.
So this is about a shared delivery layer. Not just for convenience, but also for visibility. Before we talk about delivery, let us look at the ecosystem. We need to understand what we are trying to deliver.
Part II: The Ecosystem Landscape
5. Galaxy
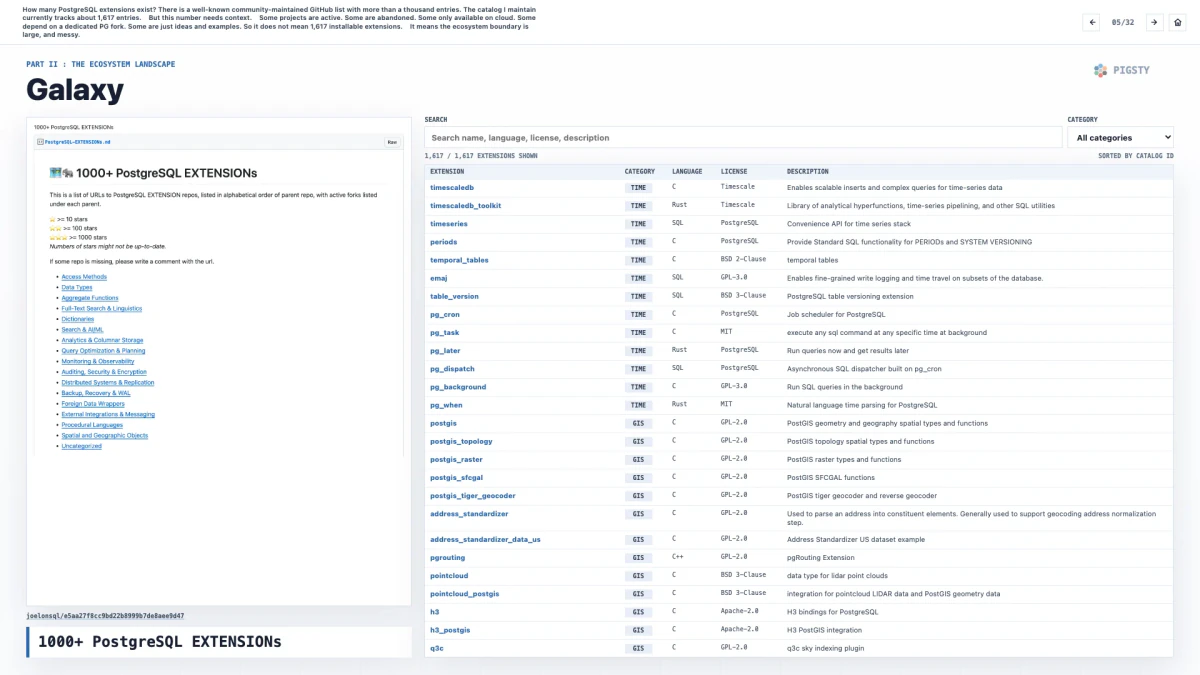
How many PostgreSQL extensions exist? There is a well-known community-maintained GitHub list with more than a thousand entries. The catalog I maintain currently tracks about 1,617 entries.
But this number needs context.
Some projects are active. Some are abandoned. Some are only available on cloud platforms. Some depend on a dedicated PostgreSQL fork. Some are just ideas and examples. So 1,617 does not mean 1,617 installable extensions.
It means the ecosystem boundary is large and messy.
6. GitHub Stars
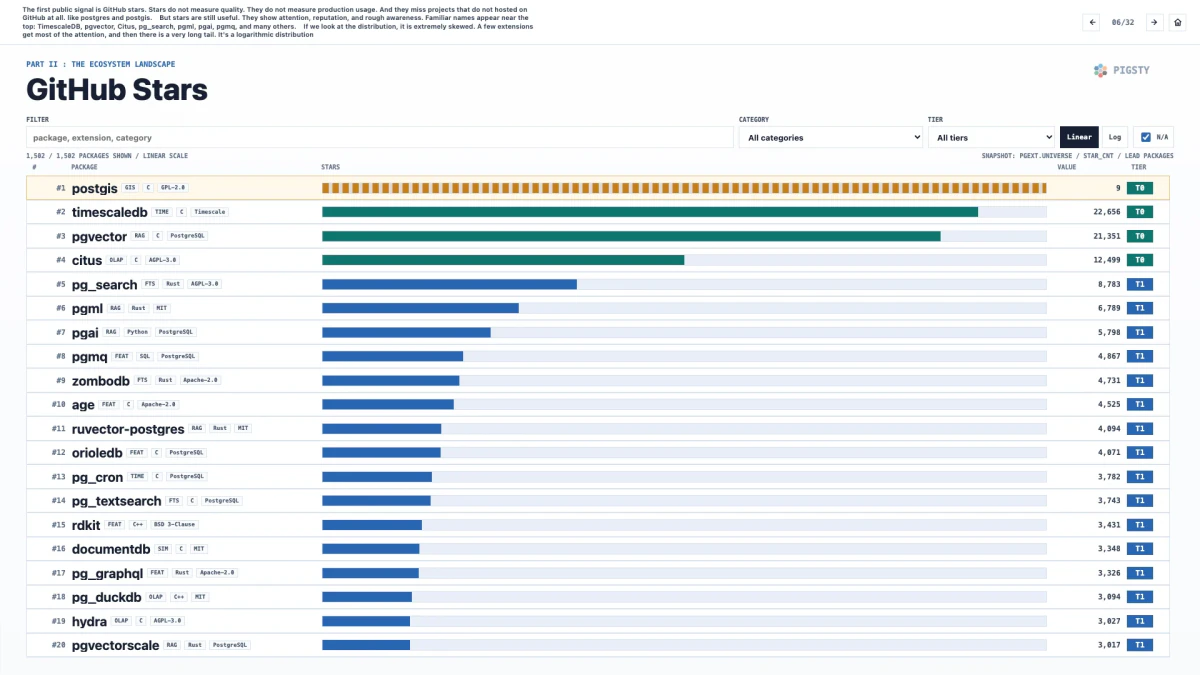
The first public signal is GitHub stars. Stars do not measure quality. They do not measure production usage. They also undercount projects whose main development happens outside GitHub, such as PostgreSQL and PostGIS.
But stars are still useful. They show attention, reputation, and rough awareness. Familiar names appear near the top: TimescaleDB, pgvector, Citus, pg_search, pgml, pgai, pgmq, and many others.
If we look at the distribution, it is extremely skewed. A few extensions get most of the attention, followed by a very long tail. It is a long-tailed distribution.
7. Star Tiering
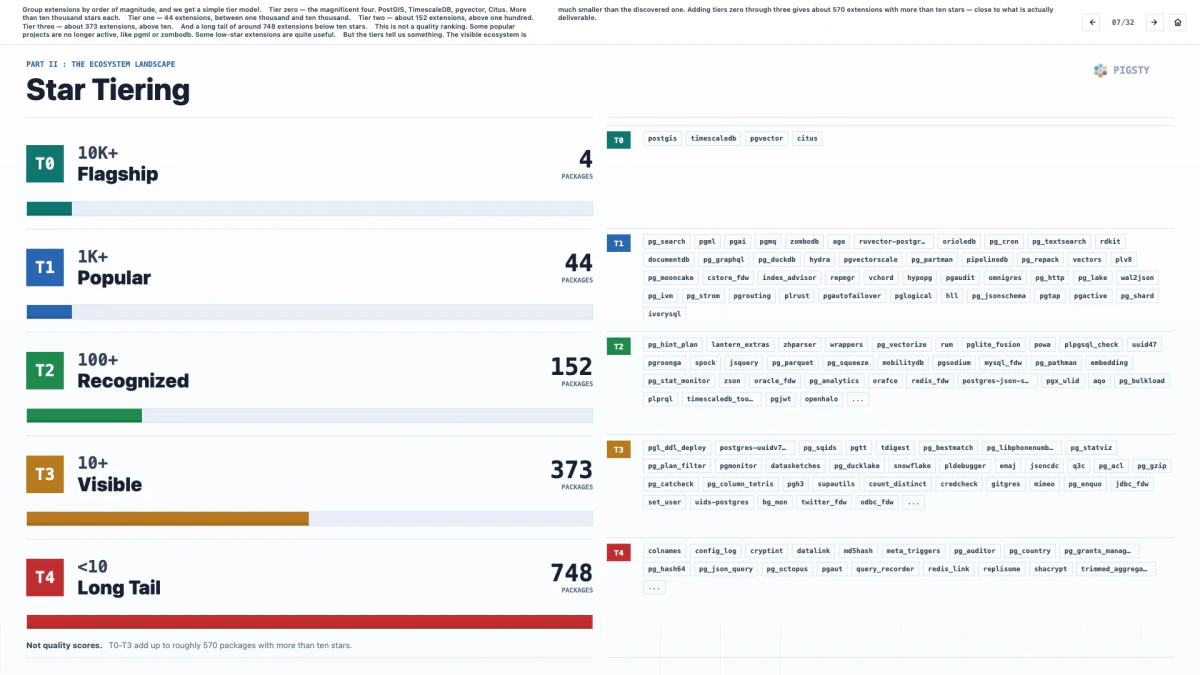
If we group extensions by order of magnitude, we get a simple tier model.
I put four widely recognized extensions in tier zero: PostGIS, TimescaleDB, pgvector, and Citus. The remaining tiers use GitHub star counts.
Tier one: 44 extensions, between one thousand and ten thousand stars.
Tier two: about 152 extensions, between one hundred and one thousand stars.
Tier three: about 373 extensions, between ten and one hundred stars.
And then a long tail of around 748 extensions below ten stars.
This is not a quality ranking. Some popular projects are no longer active, such as pgml or zombodb. Some low-star extensions are quite useful.
But the tiers tell us something. The visible ecosystem is much smaller than the discovered one. Adding tiers zero through three gives about 570 prominent or starred extensions, which is close to what is actually deliverable.
8. The Extension Funnel
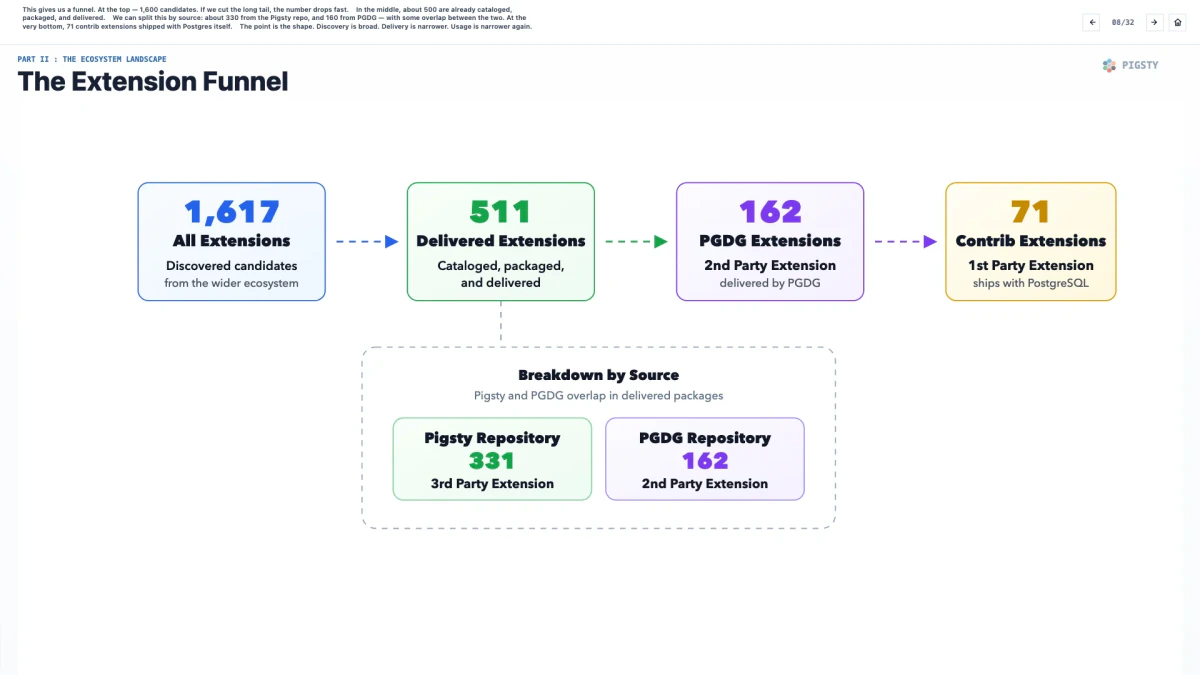
This gives us a funnel. At the top, there are about 1,600 candidates. If we cut the long tail, the number drops quickly.
In the middle, about 500 are already cataloged, packaged, and delivered.
We can split this by source: about 330 from the Pigsty repository, and 160 from PGDG, with some overlap between the two. At the very bottom, 71 contrib extensions are shipped with Postgres itself.
The point is the shape. Discovery is broad. Delivery is narrower. Usage is narrower again.
9. Dimension Analysis
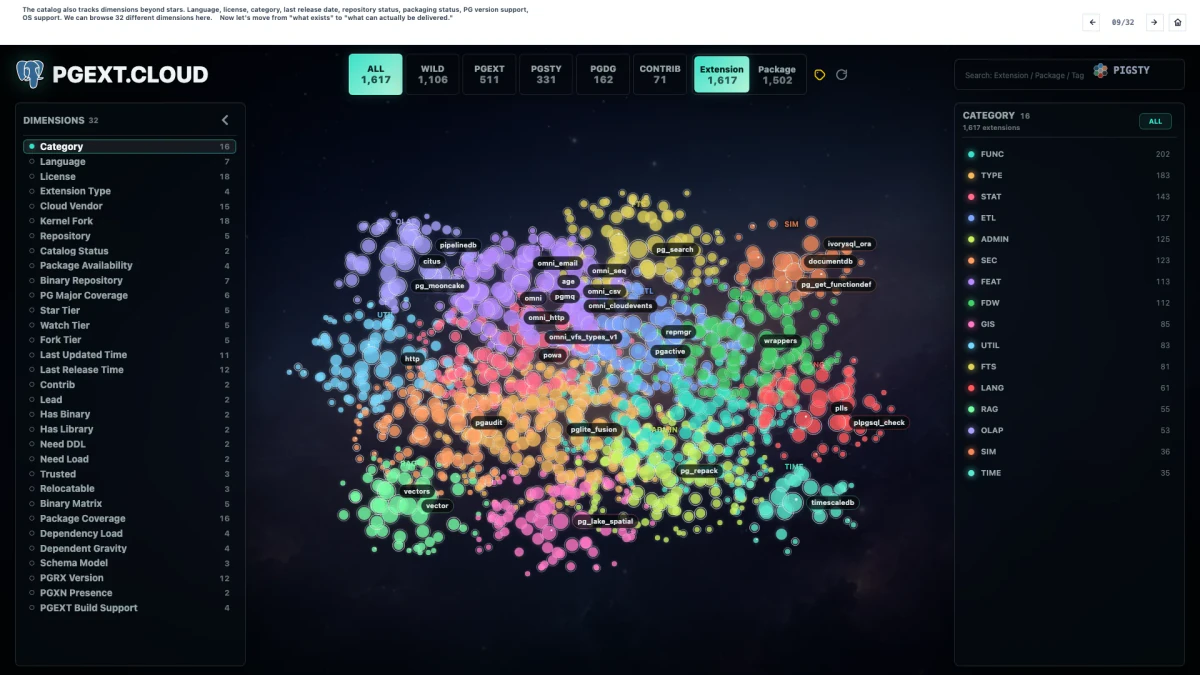
The catalog also tracks dimensions beyond stars: language, license, category, last release date, repository status, packaging status, PostgreSQL version support, and operating system support. We can browse 32 different dimensions here.
Now let us move from “what exists” to “what can actually be delivered”.
Part III: The Delivery Layer
10. The Status Quo
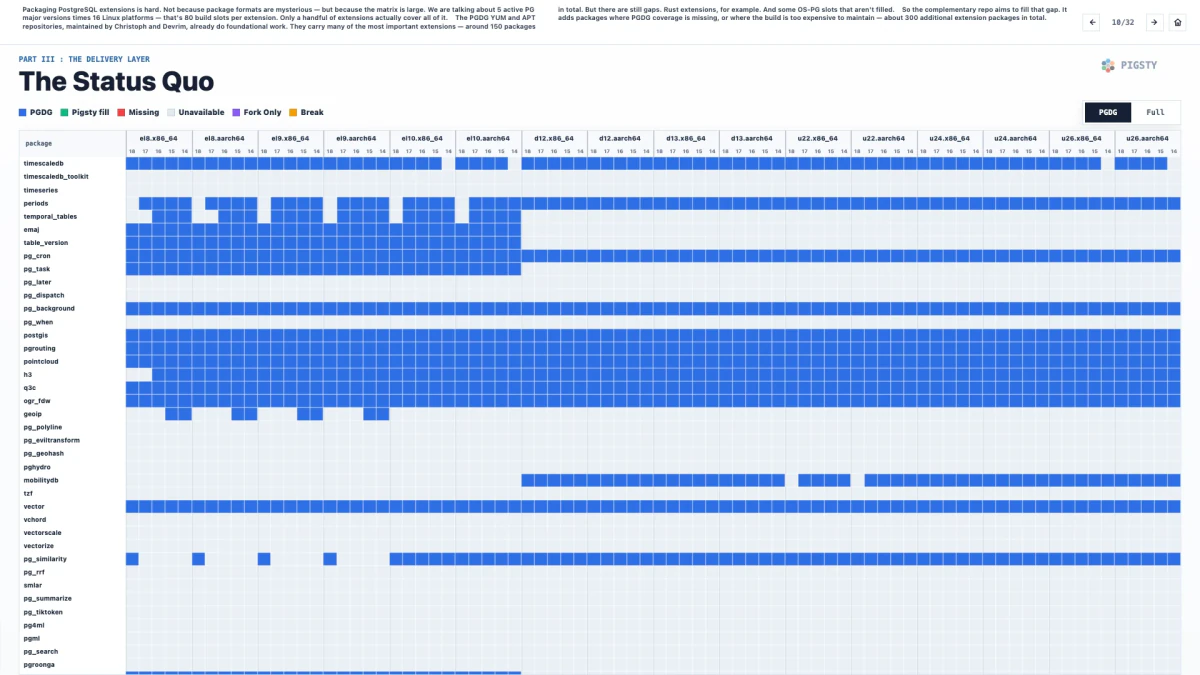
Packaging PostgreSQL extensions is hard. Not because package formats are mysterious, but because the matrix is large. We are talking about 5 active PostgreSQL major versions times 16 Linux platforms. That is 80 build slots per extension. Only a handful of extensions actually cover all of it.
The PGDG YUM and APT repositories, maintained by Christoph and Devrim, already do foundational work. They carry many of the most important extensions, around 150 packages in total. But there are still gaps: Rust extensions, for example, and some operating system plus PostgreSQL slots that are not filled.
So the complementary repository aims to fill that gap. It adds packages where PGDG coverage is missing, or where the build is too expensive to maintain. In total, that is about 300 additional extension packages.
11. The Trade-Off
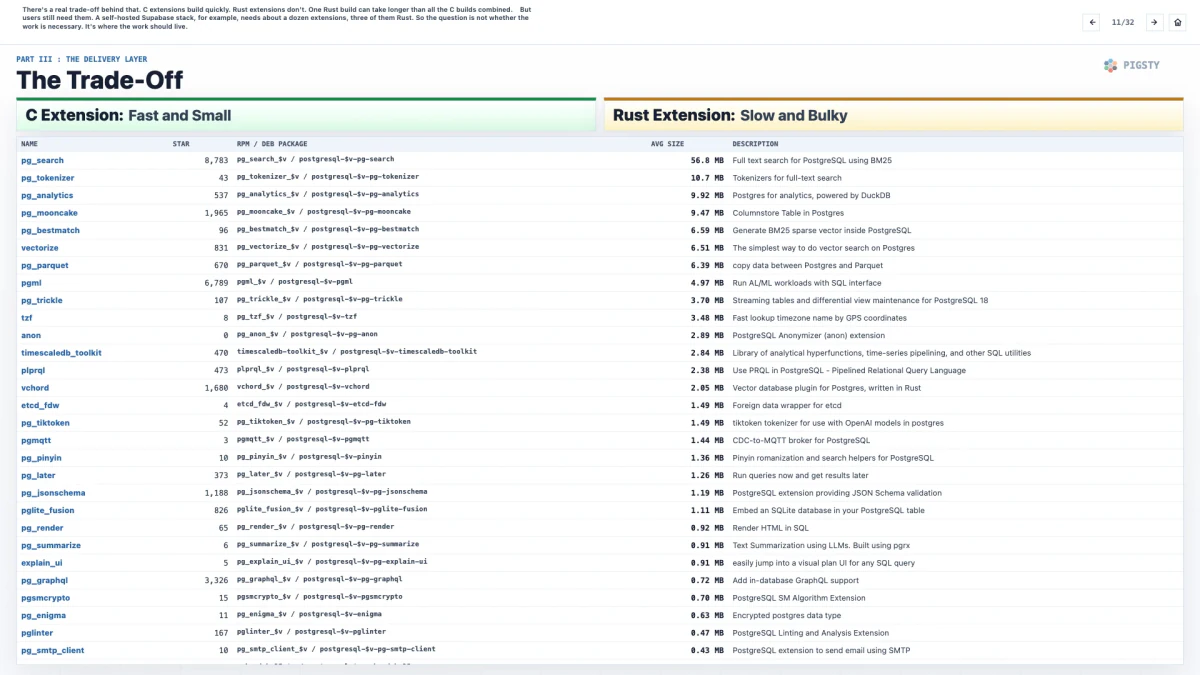
There is a real trade-off behind that. C extensions build quickly. Rust extensions do not. One Rust build can take longer than all the C builds combined.
But users still need them. A self-hosted Supabase stack, for example, needs about a dozen extensions, three of them written in Rust. So the question is not whether the work is necessary. The question is where the work should live.
12. Why Linux Native?
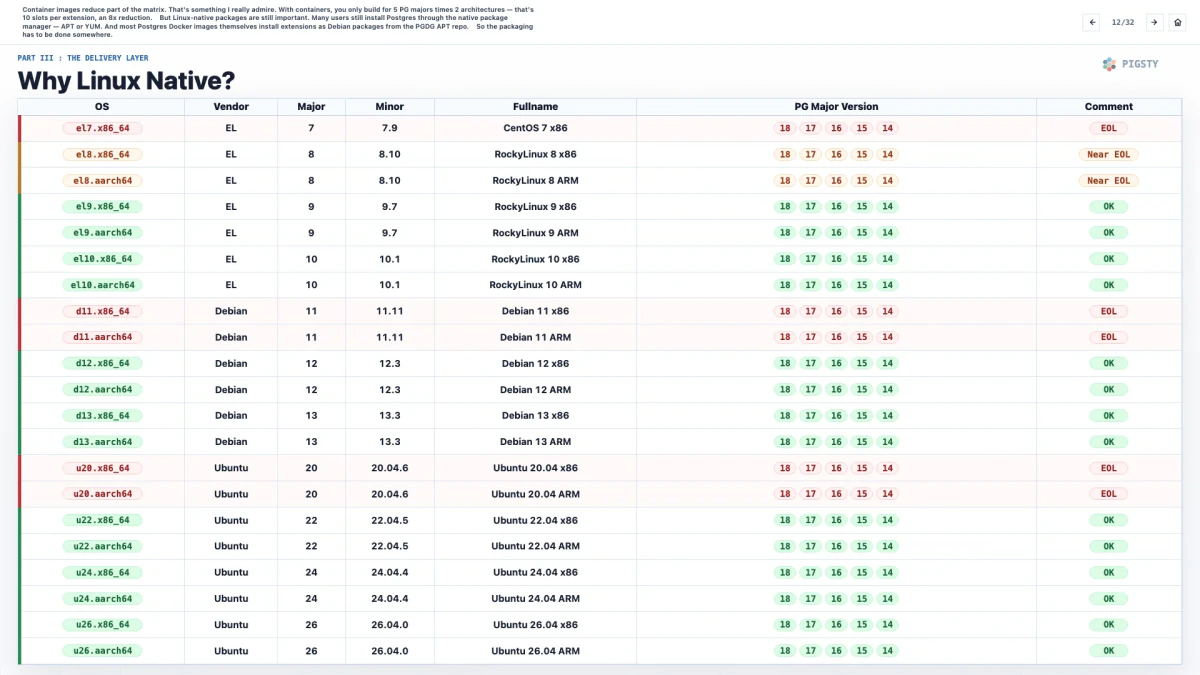
Container images reduce part of the matrix. I really admire that. With containers, you only build for 5 PostgreSQL majors times 2 architectures. That is 10 slots per extension, an 8x reduction.
But Linux-native packages are still important. Many users still install Postgres through the native package manager, APT or YUM. And most Postgres Docker images themselves install extensions as Debian packages from the PGDG APT repository.
So the packaging has to be done somewhere.
13. PGEXT.CLOUD
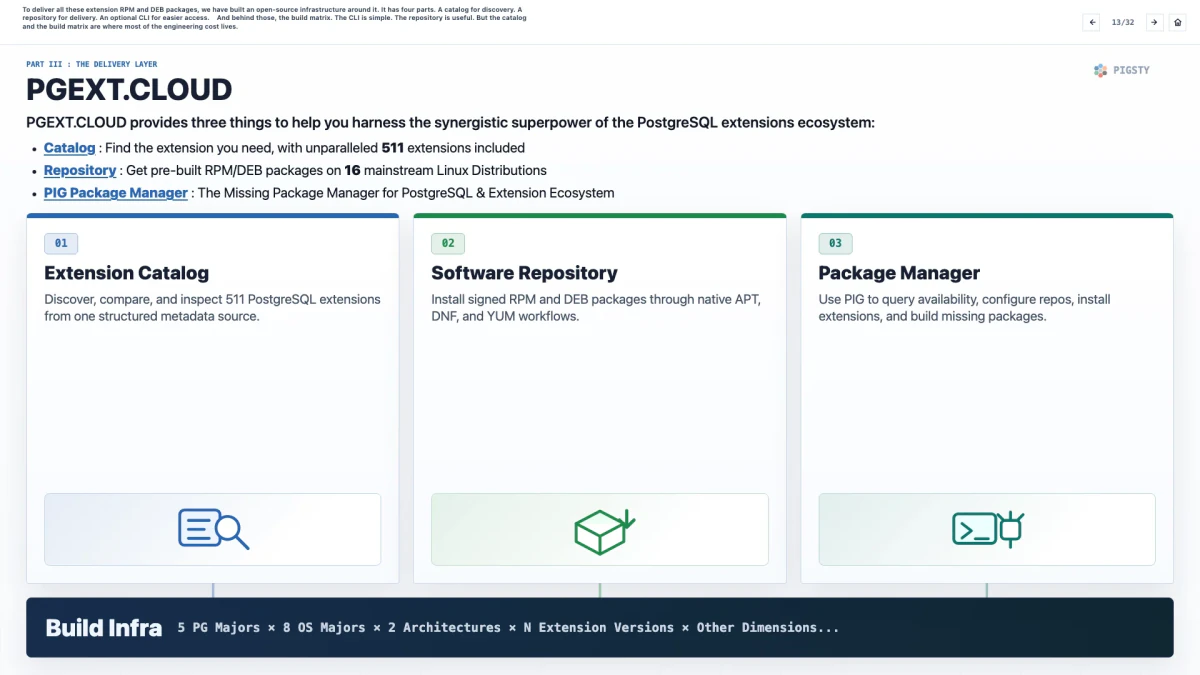
To deliver all these RPM and DEB extension packages, we have built open-source infrastructure around the problem.
It has four parts: a catalog for discovery, a repository for delivery, an optional CLI for easier access, and the build matrix behind them.
The CLI is simple. The repository is useful. But the catalog and the build matrix are where most of the engineering cost lives.
14. Extension Catalog
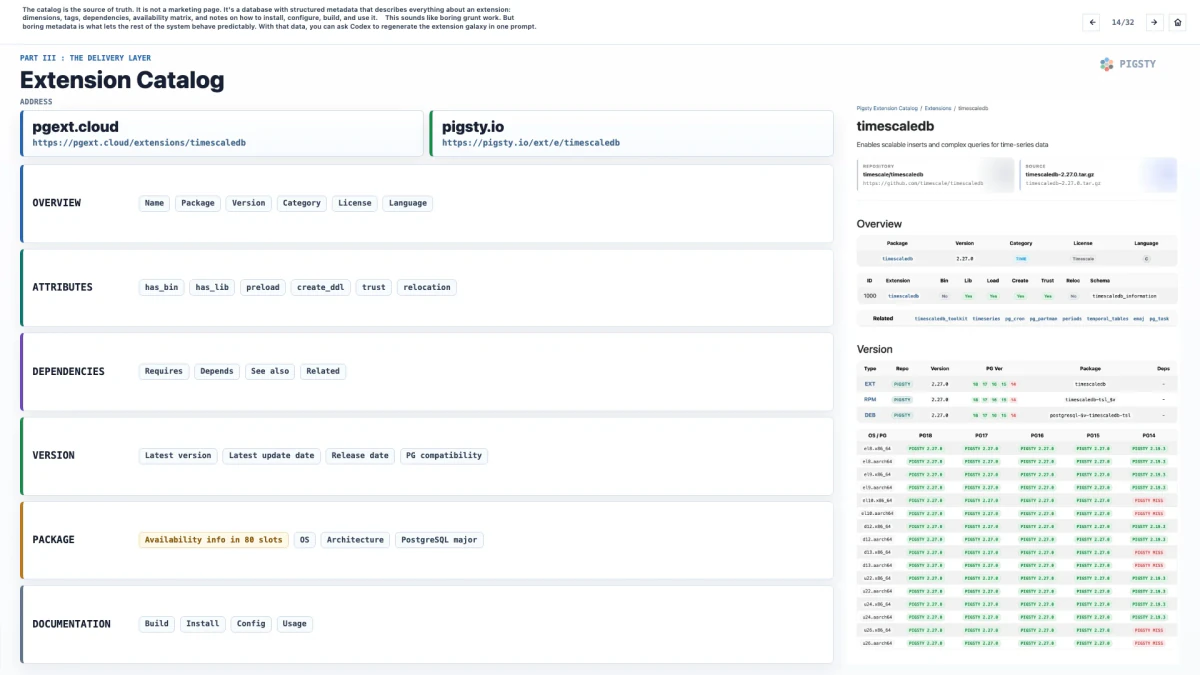
The catalog is the source of truth. It is not a marketing page. It is a database with structured metadata describing everything about an extension: dimensions, tags, dependencies, availability matrix, and notes on how to install, configure, build, and use it.
This sounds like boring grunt work. But boring metadata is what lets the rest of the system behave predictably. With that data, you can ask Codex to regenerate the extension galaxy in one prompt.
15. Catalog Details
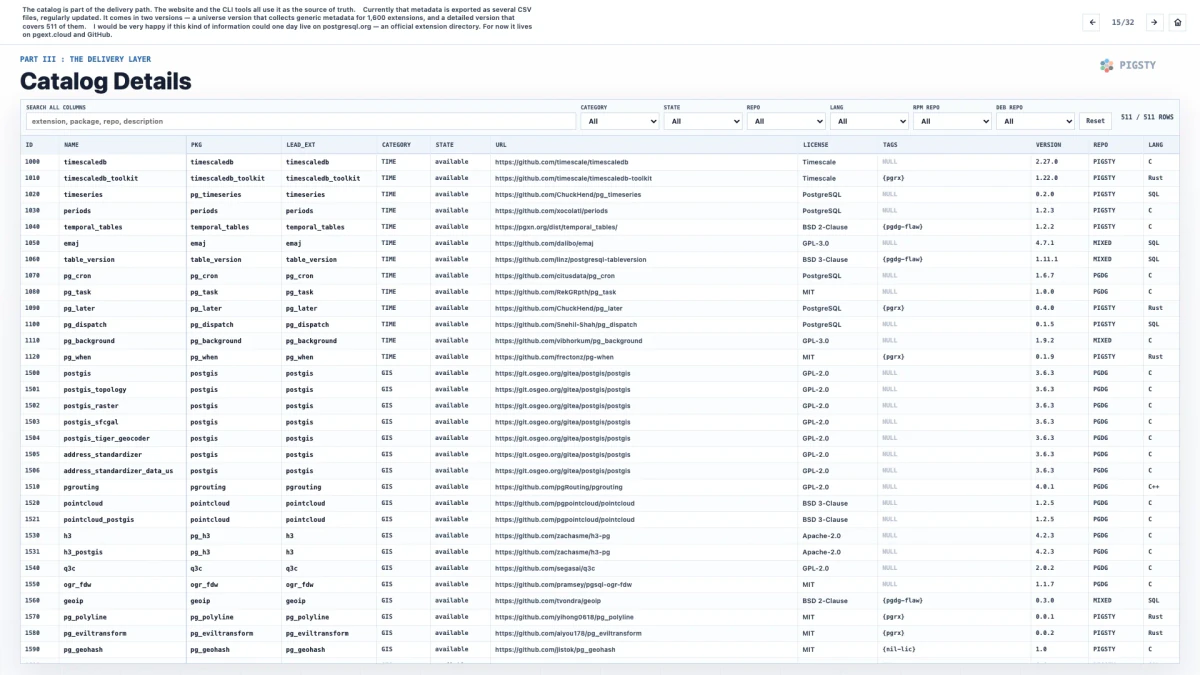
The catalog is part of the delivery path. The website and the CLI tools all use it as the source of truth.
Currently, that metadata is exported as several CSV files and updated regularly. It comes in two versions: a universe version that collects generic metadata for 1,600 extensions, and a detailed version that covers 511 of them.
I would be very happy if this kind of information could one day live on postgresql.org as an official extension directory. For now, it lives on pgext.cloud and GitHub.
16. Catalog Page Views
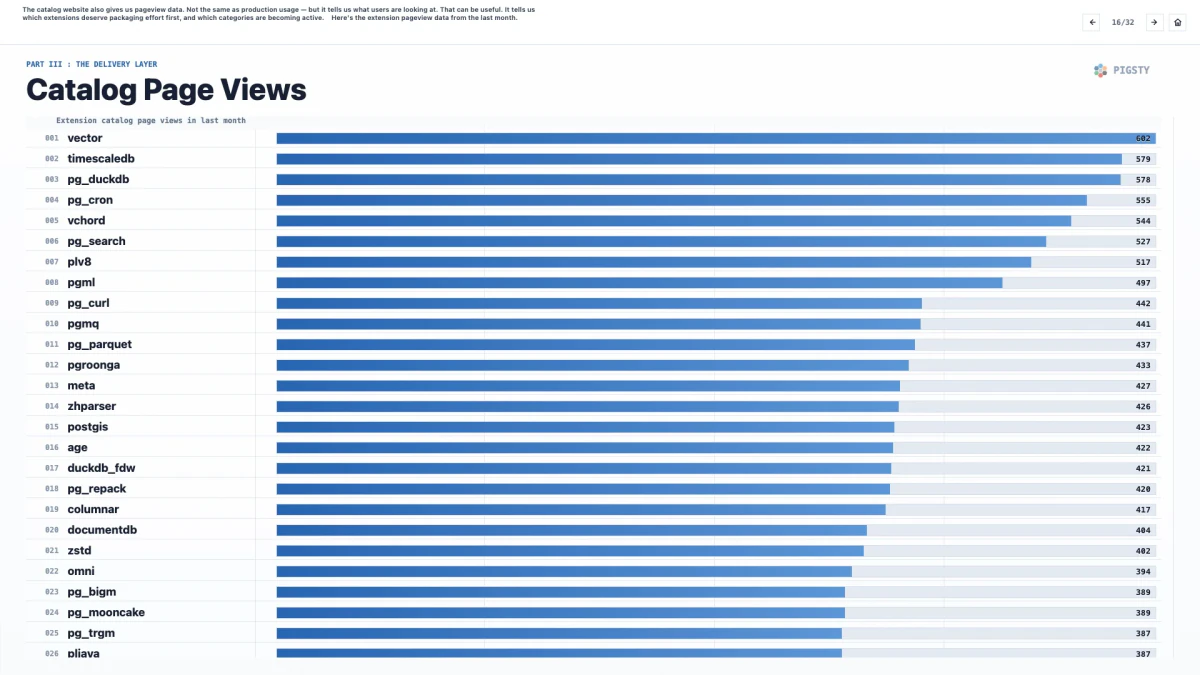
The catalog website also gives us pageview data. It is not the same as production usage, but it tells us what users are looking at. That can be useful. It tells us which extensions deserve packaging effort first, and which categories are becoming active.
Here is the extension pageview data from the last month.
17. Repository
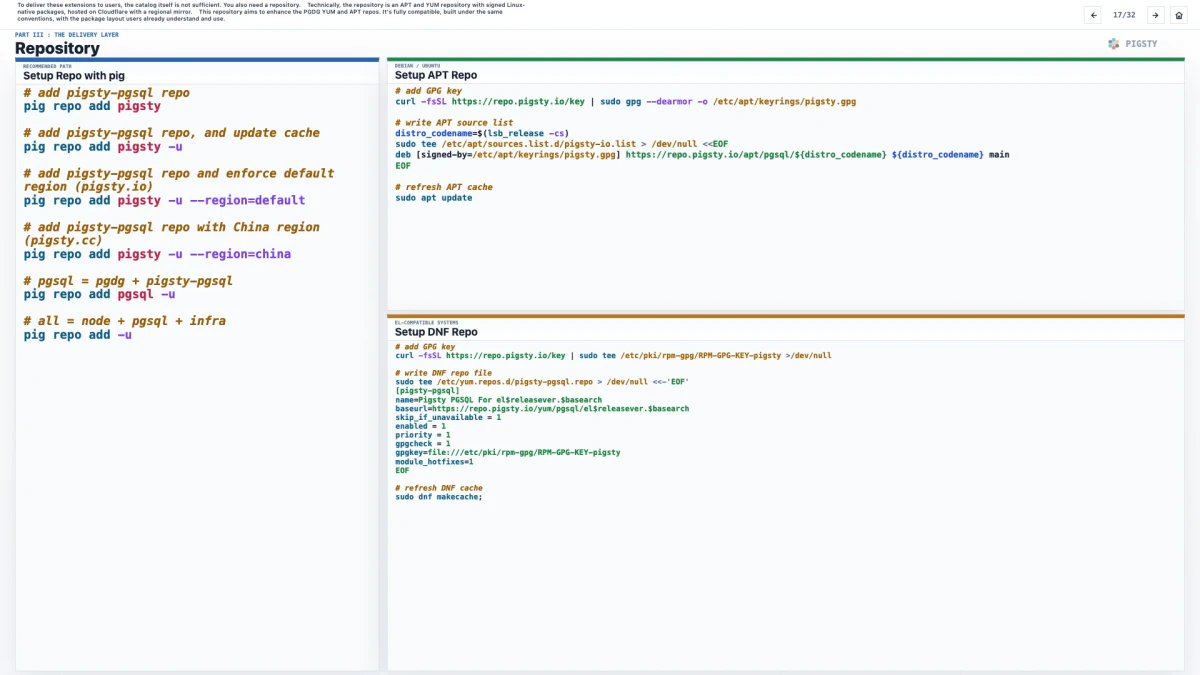
To deliver these extensions to users, the catalog itself is not sufficient. You also need a repository.
Technically, the repository is an APT and YUM repository with signed Linux-native packages, hosted on Cloudflare with a regional mirror.
This repository aims to enhance the PGDG YUM and APT repositories. It is fully compatible, built under the same conventions, with the package layout users already understand and use.
18. Repo Download Stats
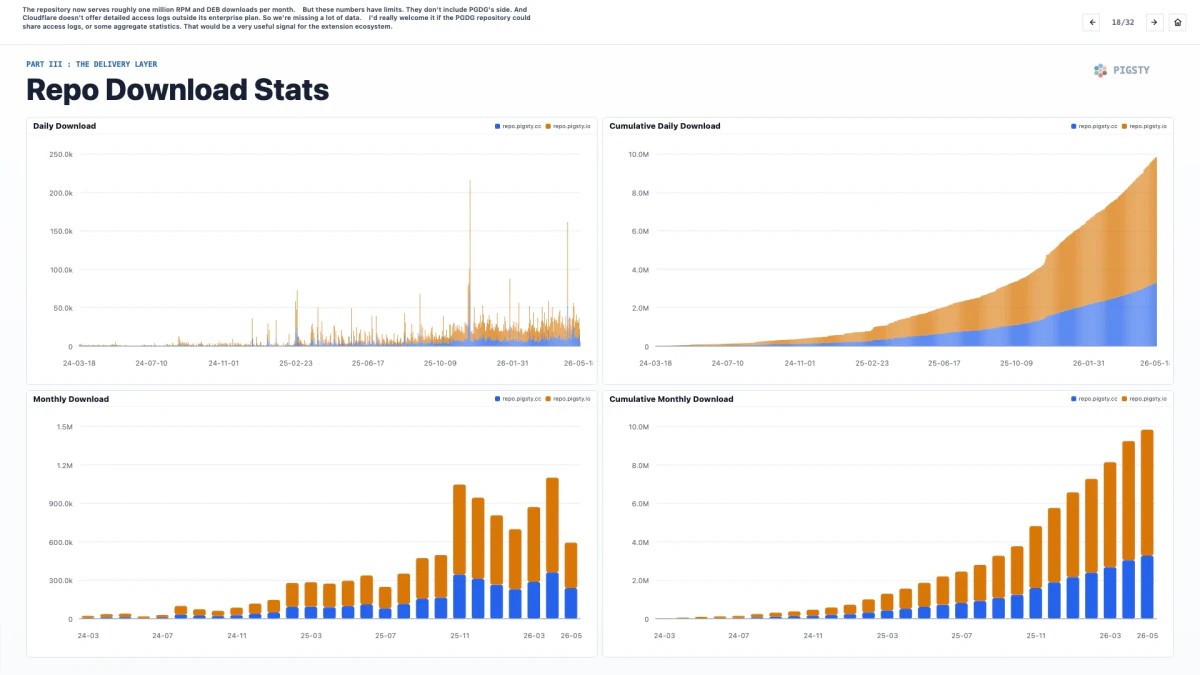
The repository now serves roughly one million RPM and DEB downloads per month.
But these numbers have limits. They do not include the PGDG side. Cloudflare also does not offer detailed access logs outside its enterprise plan, so we are missing a lot of data.
I would really welcome it if the PGDG repository could share access logs, or at least some aggregate statistics. That would be a very useful signal for the extension ecosystem.
19. What We Can Still Infer
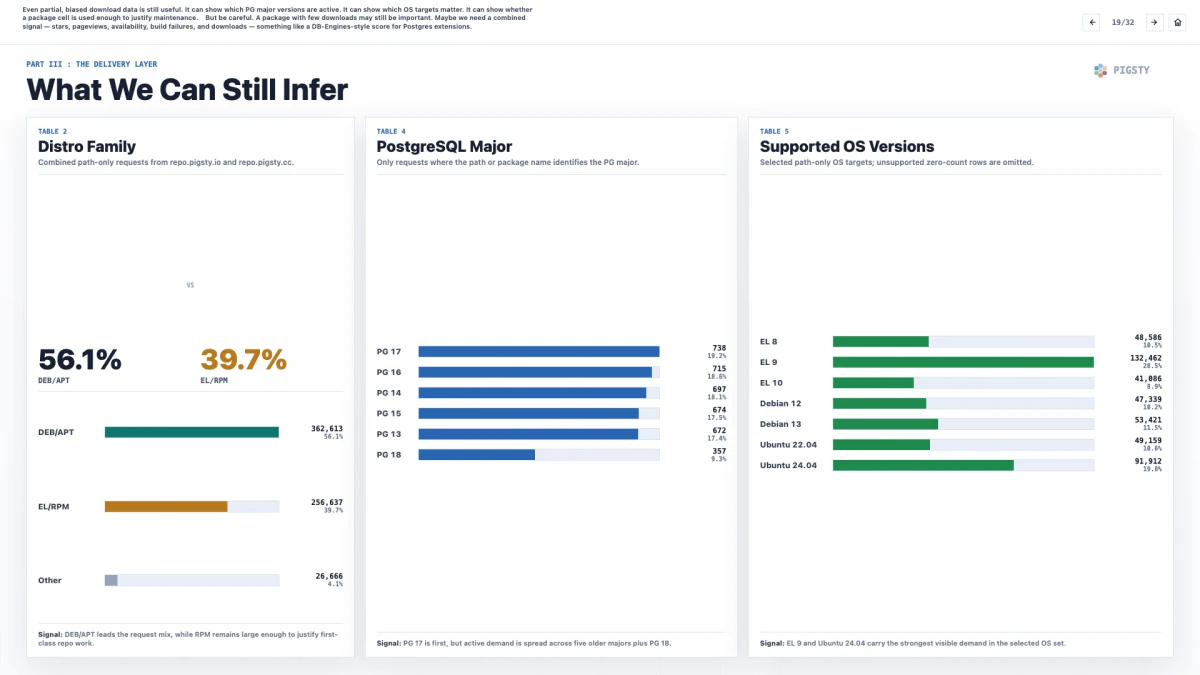
Even partial and biased download data is still useful. It can show which PostgreSQL major versions are active. It can show which operating system targets matter. It can show whether a package cell is used enough to justify maintenance.
But be careful. A package with few downloads may still be important. Maybe we need a combined signal: stars, pageviews, availability, build failures, and downloads. Something like a DB-Engines-style score for Postgres extensions.
20. The CLI - PIG
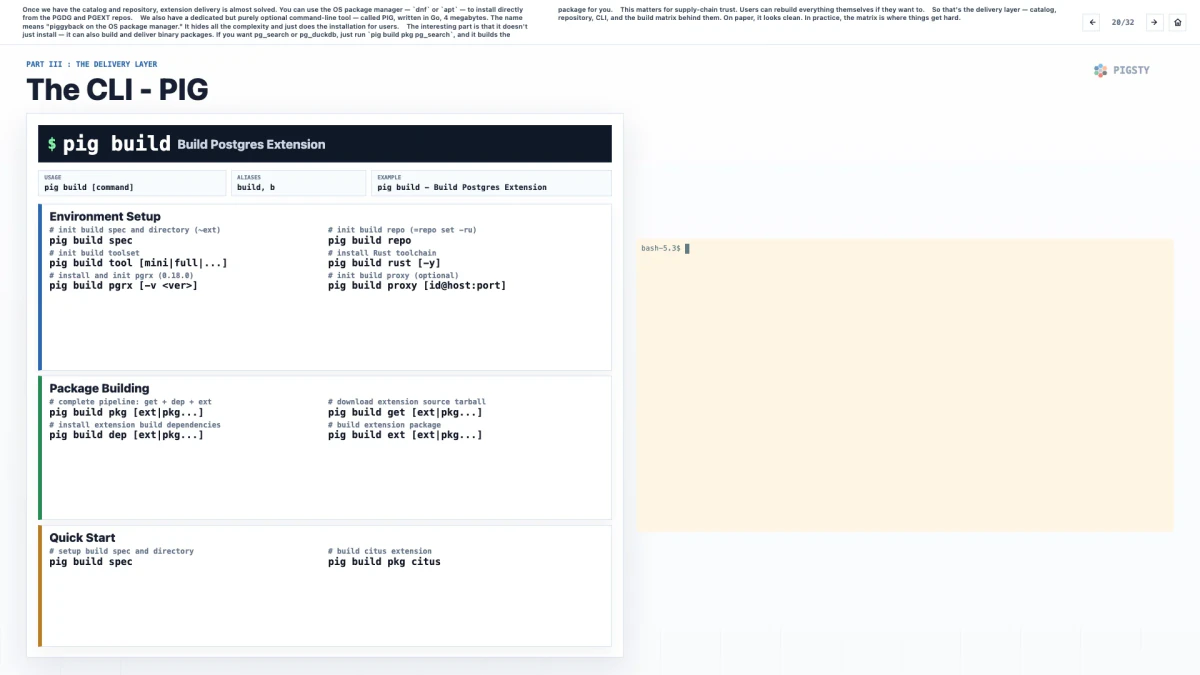
Once we have the catalog and repository, extension delivery is almost solved. You can use the operating system package manager, dnf or apt, to install directly from the PGDG and PGEXT repositories.
We also have a dedicated but purely optional command-line tool called PIG. It is written in Go and distributed as a single executable. The name means “piggyback on the OS package manager”. It resolves extension names to the packages for the selected PostgreSQL version and platform.
The interesting part is that it does not only install. It can also build and deliver binary packages. After setting up the build environment, run pig build pkg pg_search to build pg_search, or select another supported extension such as pg_duckdb.
This matters for supply-chain trust. Users can rebuild everything themselves if they want to.
So that is the delivery layer: catalog, repository, CLI, and the build matrix behind them. On paper, it looks clean. In practice, the matrix is where things get hard.
Part IV: Maintenance in the Wild
21. Dimension Explosion!
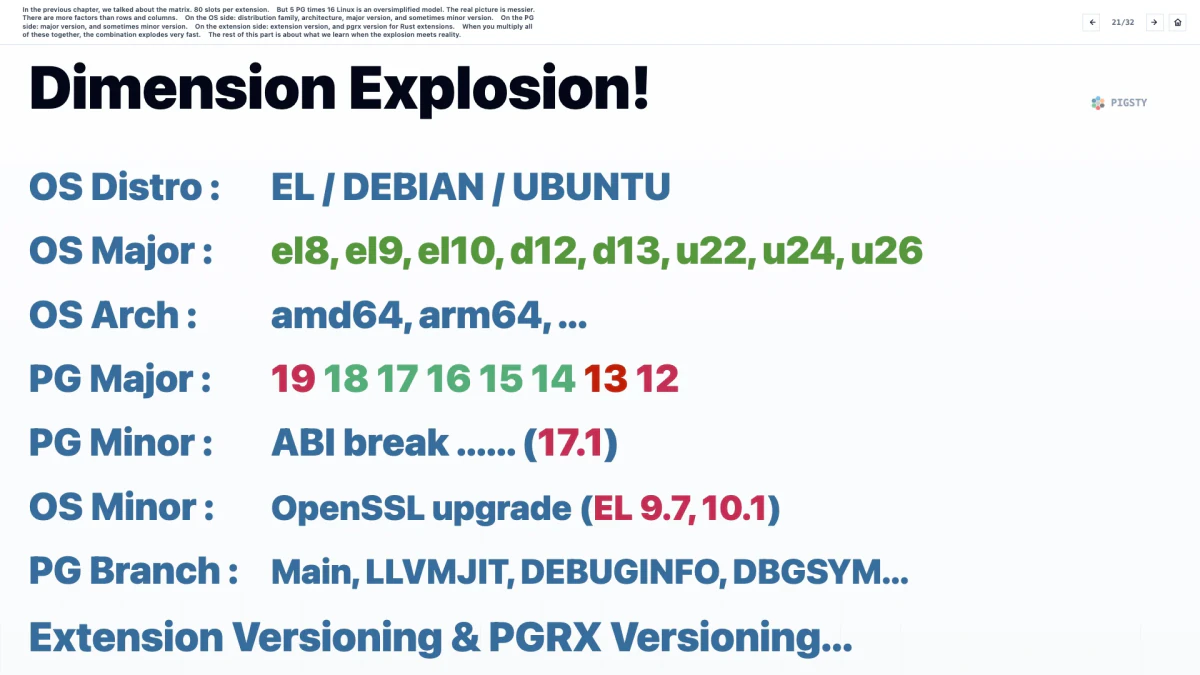
In the previous chapter, we talked about the matrix: 80 slots per extension.
But 5 PostgreSQL versions times 16 Linux targets is an oversimplified model. The real picture is messier. There are more factors than rows and columns.
On the operating system side: distribution family, architecture, major version, and sometimes minor version.
On the PostgreSQL side: major version, and sometimes minor version.
On the extension side: extension version, and pgrx version for Rust extensions.
When you multiply all of these together, the combination explodes very quickly.
The rest of this part is about what we learn when that explosion meets reality.
22. PG Minor ABI Break
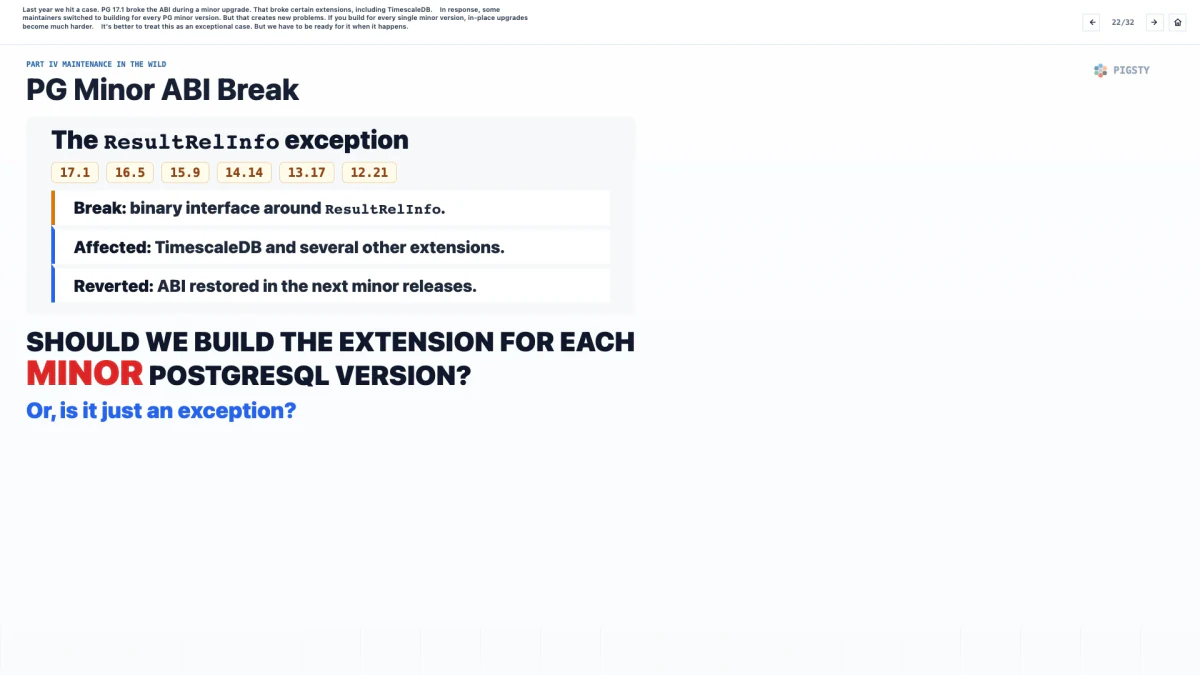
In November 2024, we hit a concrete case. PostgreSQL 17.1 broke ABI compatibility during a minor upgrade. That broke certain extensions, including TimescaleDB.
In response, some maintainers switched to building for every PostgreSQL minor version. But that creates new problems. If you build for every single minor version, in-place upgrades become much harder.
It is better to treat this as an exceptional case. But when it happens, we have to be ready.
23. OS Minor Break
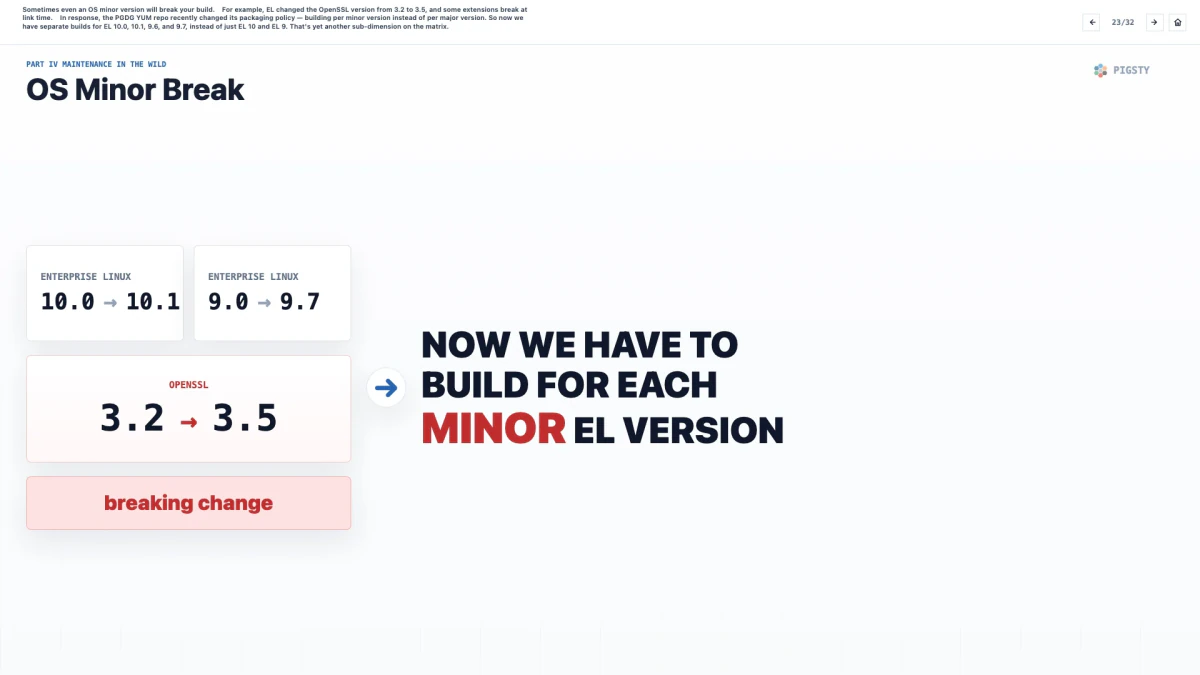
Sometimes even an operating system minor version will break your build.
For example, EL changed the OpenSSL version from 3.2 to 3.5, and some extensions break at link time.
In response, the PGDG YUM repository recently changed its packaging policy. It now builds per minor version instead of per major version. So we have separate builds for EL 10.0, 10.1, 9.6, and 9.7, instead of just EL 10 and EL 9. That is yet another sub-dimension on the matrix.
24. Rust Problems
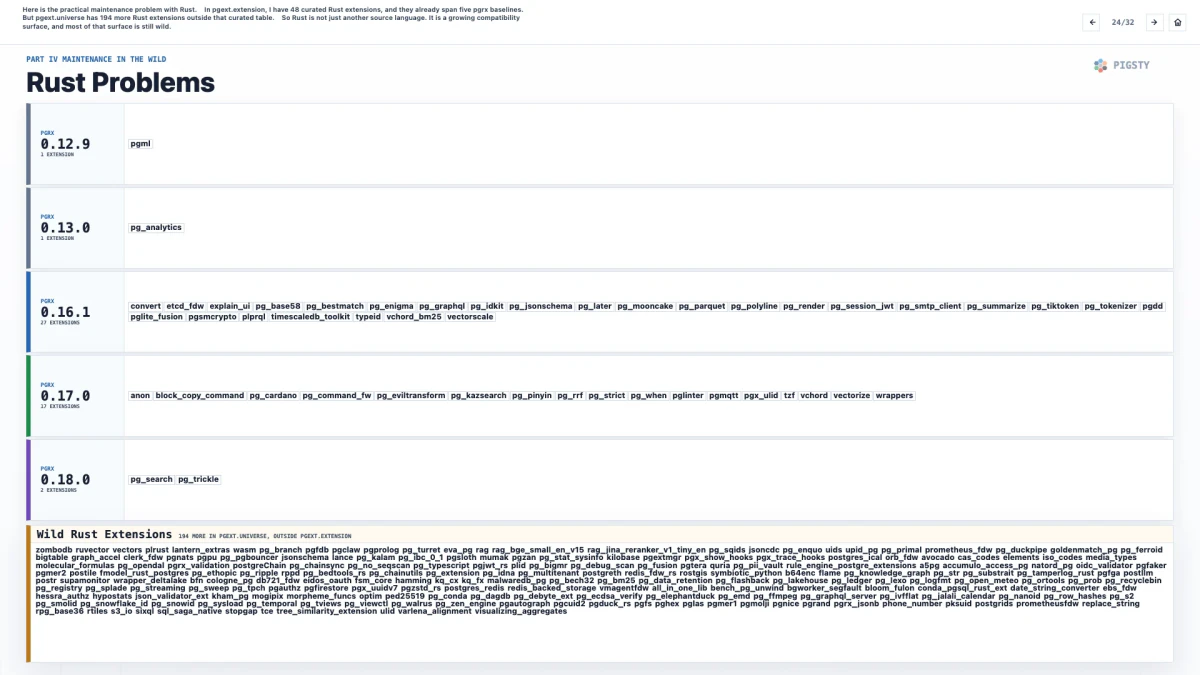
Rust extensions are growing. They bring new people and new ideas into the ecosystem. The Rust community uses a framework called pgrx to write them, and that introduces a few new problems.
First, the build cost. Rust builds are slow and disk-hungry. One Rust extension can take longer to build than all the C extensions combined.
Second, pgrx itself has versions: 0.16, 0.17, 0.18, and so on. They are not interchangeable. I have spent a lot of time aligning Rust extensions to specific pgrx versions, but as time goes by, version drift comes back.
So Rust does not just add another language. It adds another compatibility axis.
25. Bulky Extensions
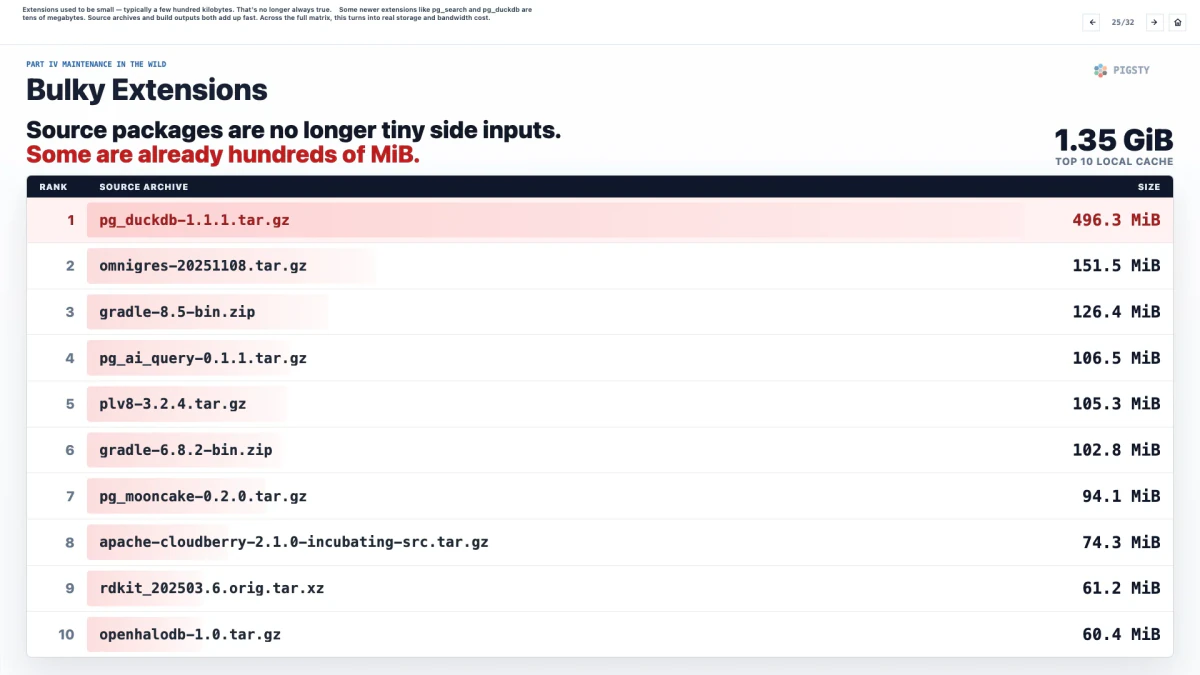
Extensions used to be small, typically a few hundred kilobytes. That is no longer always true.
Some newer extensions, such as pg_search and pg_duckdb, are tens of megabytes. Source archives and build outputs both add up quickly. Across the full matrix, this turns into real storage and bandwidth cost.
26. Naming Conflicts
The matrix is one kind of complexity. Conflicts between extensions are another.
Last year, I talked about Citus and Hydra competing for the same name, columnar. This year, we have a new example: bm25. Three extensions now expose an access method called bm25:
- pg_search from ParadeDB
- pg_textsearch from Timescale
- vchord_bm25 from TensorChord
Unlike Citus and Hydra, you can install these three together. But you cannot create them all in the same database, because the access method name collides.
This is not just a packaging issue. It is an ecosystem metadata problem. If the catalog records not just package names, but also extension objects, libraries, and access methods, authors can check for collisions before release.
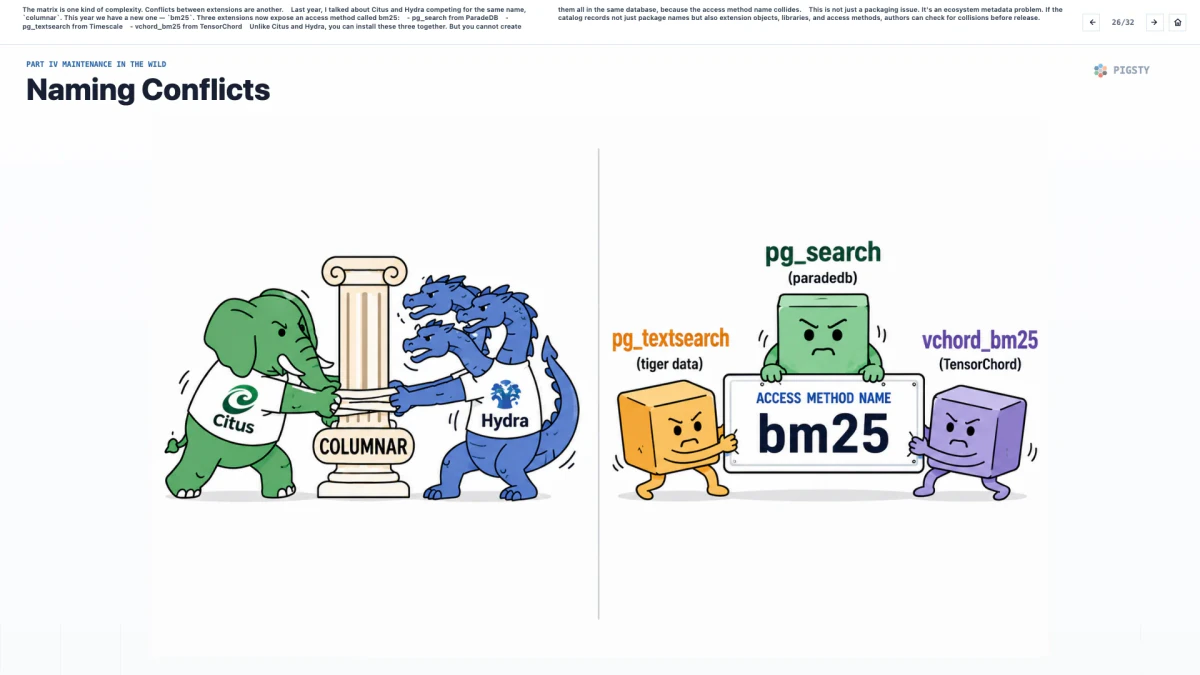
27. Library Conflicts
Here is another example. Three DuckDB-based extensions wanted to use the same shared library: libduckdb.
The package manager sees files on disk. PostgreSQL sees shared libraries and control files. The user sees CREATE EXTENSION. All three layers can disagree.
The practical resolution was to mount two of the extensions as sub-extensions under pg_duckdb. It worked, but it took real effort to coordinate and persuade the authors.
The lesson is simple: names are part of compatibility, and names do conflict.
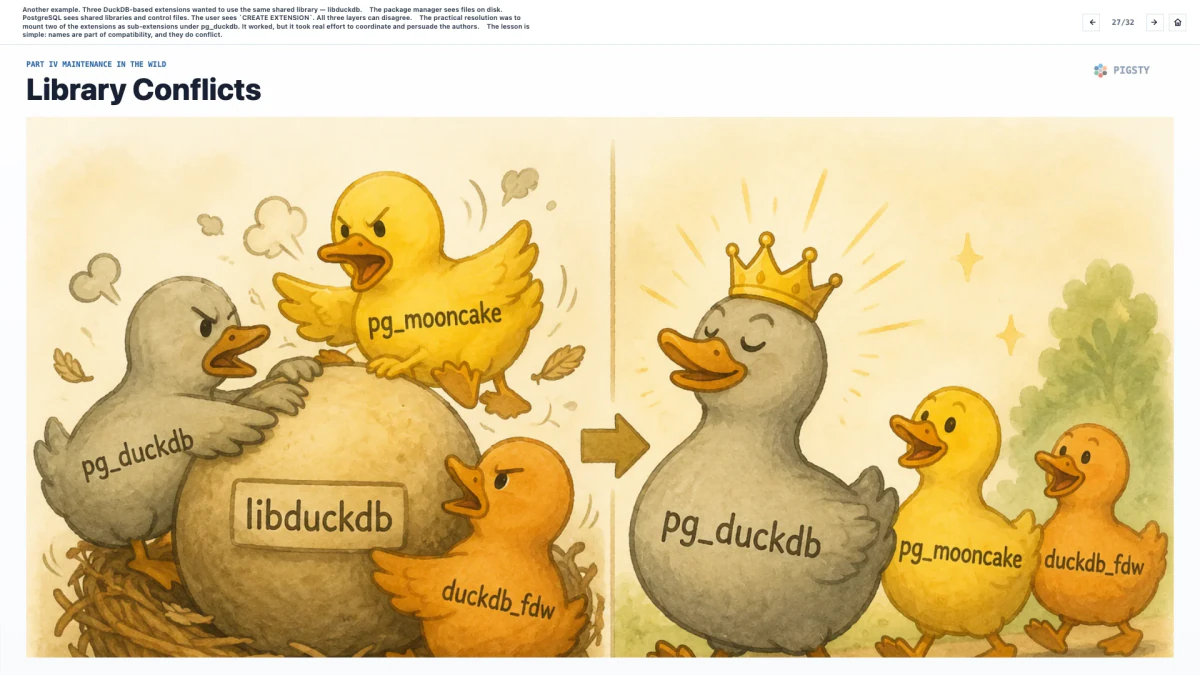
28. API Break
We also fix many extensions that lack active maintenance. The last release date for some of them was years ago, but PostgreSQL major version changes still affect them.
Usually, the original author writes version branches to handle different PostgreSQL majors. If the extension is no longer maintained, a packager has to step in.
We have talked about how this work helps the first three groups: users, authors, and vendors. Can it also be useful to PostgreSQL hackers?
I think build coverage is a useful signal. When a patch breaks N extensions, that number is information. It shows ecosystem impact. This is where delivery infrastructure starts to look like feedback infrastructure.
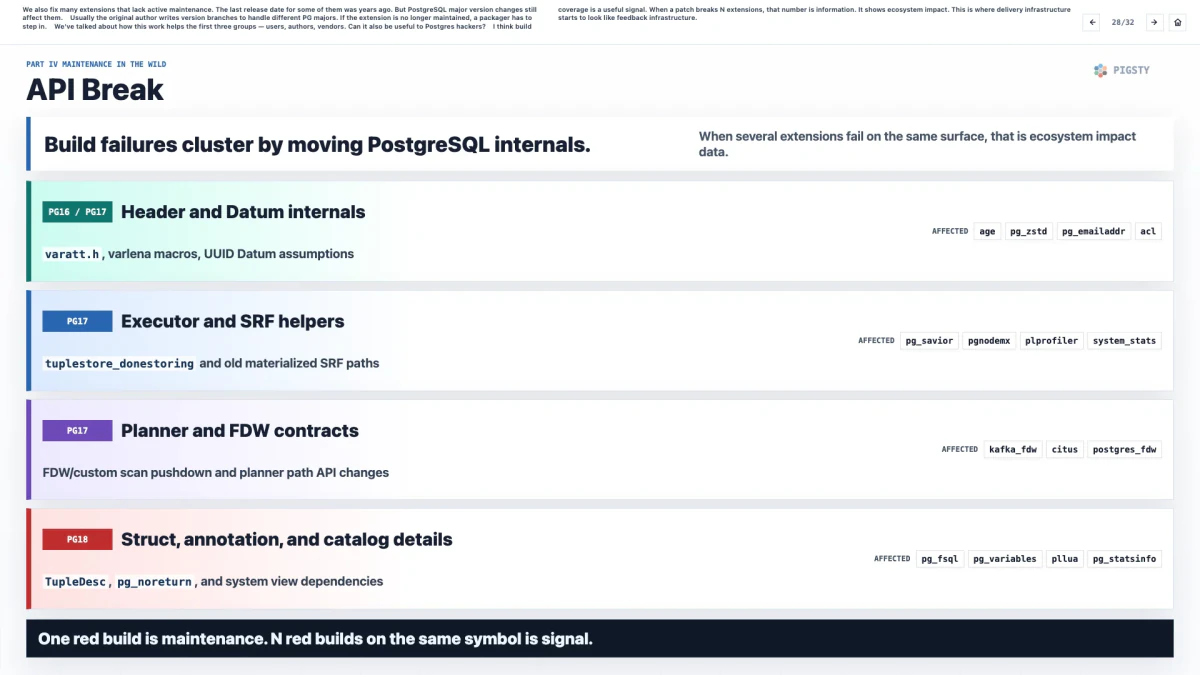
29. PG 19 Compatibility
Here is a concrete case. I ran the build pipeline against PostgreSQL 19 development snapshots. Around 50 extensions failed to build.
The failures cluster into a small set of categories: real API changes, old assumptions, missing version branches, dependency problems, and packages that were already fragile.
Some PostgreSQL hackers told me last year that this might be useful for patches with broad reach, such as threading work, refactors, and hook changes. If a CI pipeline can run extension builds against a patch series, the result could be useful input during patch review.
I would really like feedback from this room on whether that is worth pursuing.
The goal is not to block progress. The goal is to make ecosystem impact visible earlier.
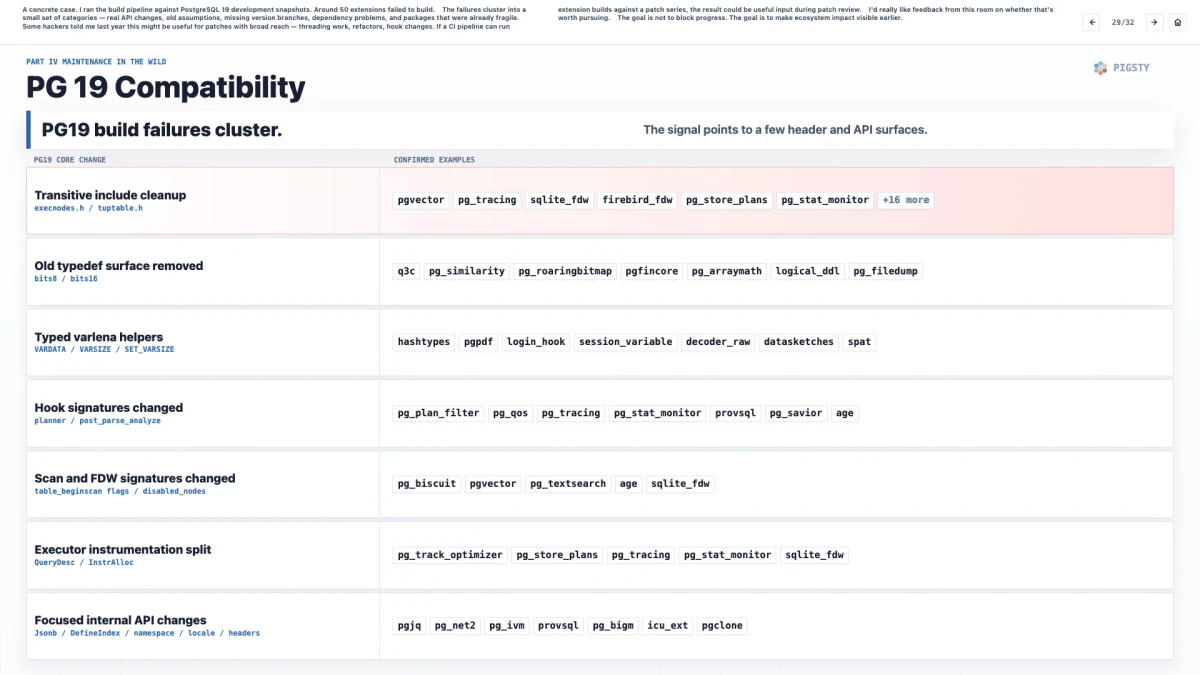
30. Keeping It Maintainable
A practical question is maintainability. All of this work is done by one person. I run a one-person company and a one-person distribution called Pigsty. I have been doing this for about five years.
It is getting easier these days because of AI tooling. A year ago, every build spec was written by hand. After accumulating enough examples, adding new extensions has become straightforward. Last month, I added 50 new extensions in two days.
My friend Yurii Rashkovskii once described an idea called PGPM: URL in, RPM out. With Codex and Claude Code, that idea is becoming real.
AI also lowers testing cost. We can drive sanity checks from extension documentation and catch behavior regressions earlier.
AI may not be ready to commit Postgres core patches. But it is clearly qualified for this kind of work. I maintain a MinIO fork that fixes CVEs and bugs, almost entirely through Codex and Claude Code. It actually works in production.
This is the only way a 511-extension matrix stays alive with one maintainer.
31. Three Questions
To close, extensions are the collective treasure of the Postgres ecosystem. I hope this work helps users, authors, vendors, and Postgres hackers build a better Postgres.
I want to leave this room with three questions.
First, what catalog metrics would actually be useful? Pageviews, downloads, package availability, build failures, last release date, object conflicts. Which of these should be visible, and which are noise?
Second, can extension build coverage help patch review? Is it useful as an early warning signal for API, ABI, and behavior changes?
Third, should some of this metadata live closer to PostgreSQL community infrastructure? Under postgresql.org, alongside PGDG, or somewhere else?
Extensions are collective infrastructure. Delivery is part of extensibility. If we improve delivery, PostgreSQL’s superpower reaches more people.
32. Thank You
Thank you.
If you have any questions, please contact me.
Vonng [email protected]
Originally published on vonng.com.
1.6 - 504 Extensions: Expand the PostgreSQL Landscape
A GitHub issue turned into an extension sprint. 32 new additions say a lot about where PostgreSQL is headed.
It Started with a Chemistry Extension
Two days ago, a user opened a GitHub issue: he was using RDKit, the de facto standard library in cheminformatics, to store molecular structures, run substructure searches, and compute similarity inside PostgreSQL. He noticed that the official PGDG package was built without InChI support. After spending a while rebuilding it with the right compile flags, he got it working, but still hoped Pigsty could support it out of the box.
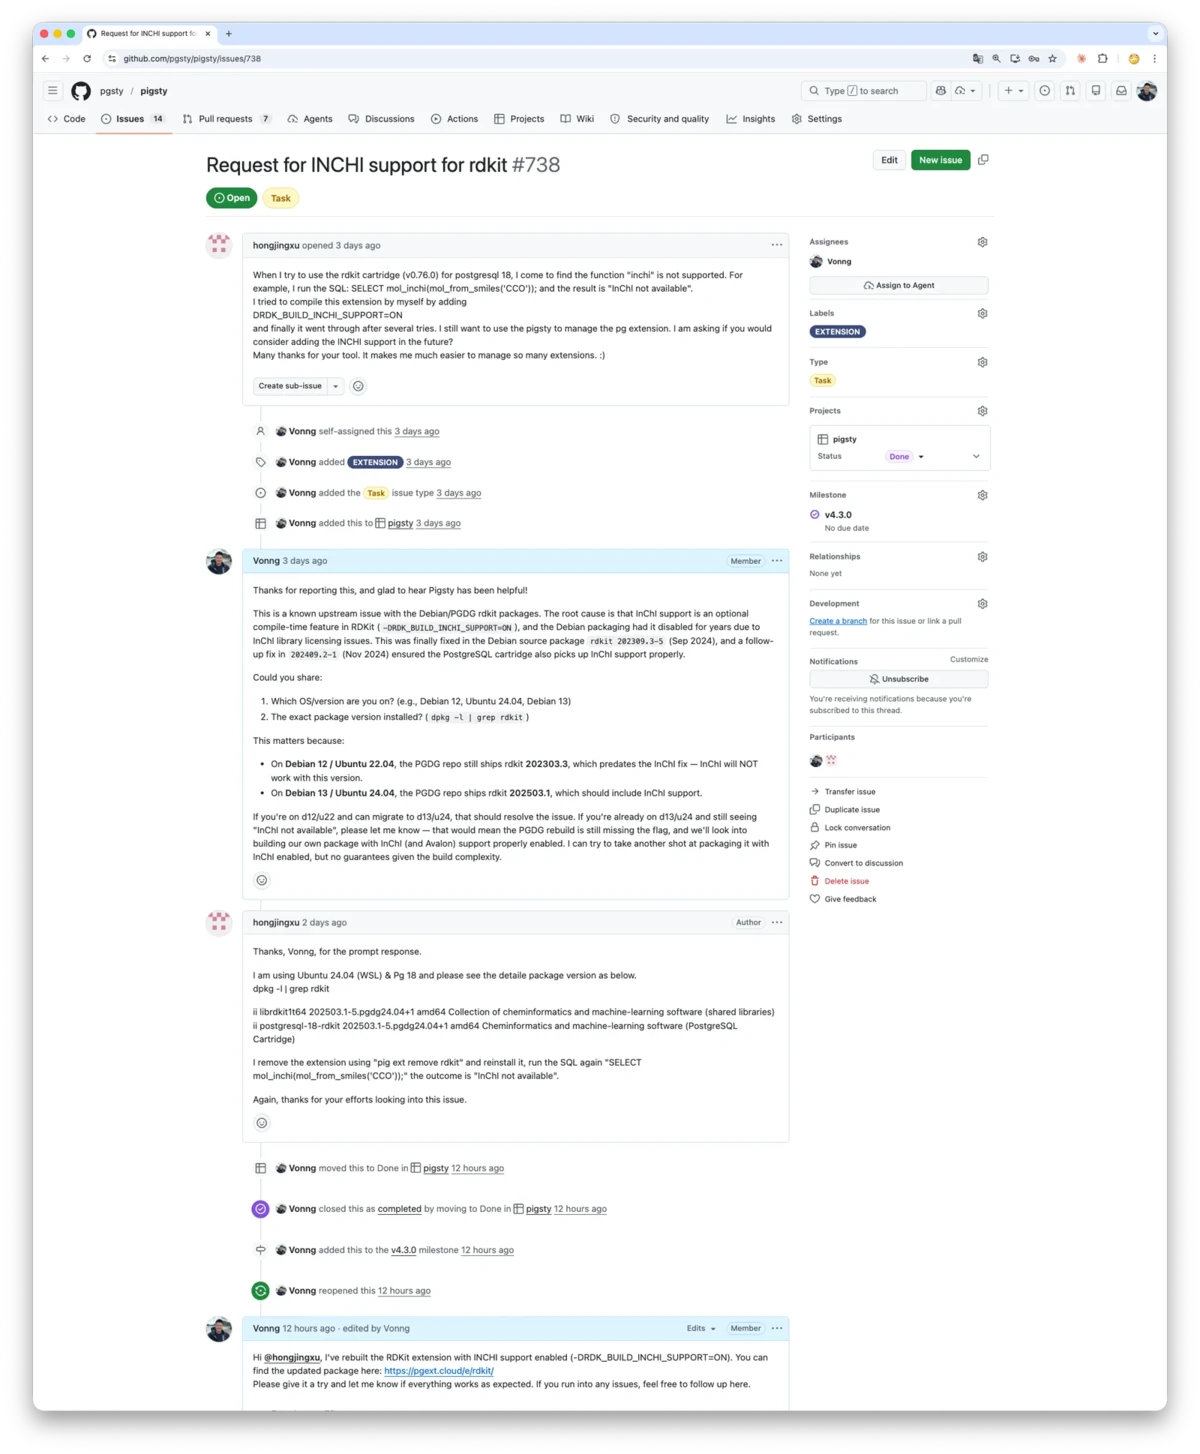
RDKit really is a nasty one. I tried to bring it into the Pigsty extension repo about two years ago, porting it from Debian to EL. The dependency tree was ugly: Boost, Eigen, RapidJSON, Cairo, plus optional modules like InChI and Avalon. Each one came with its own build flags and OS-specific library-version problems. I fought with it for a while, got nowhere, and shelved it.
This time was different. I had coding agents.
Using Codex or Claude Code for this kind of build-system archaeology is almost unfair. Things that used to take endless rounds of trial and error now usually take one or two iterations of prompting and then waiting. This release also fixed the missing InChI support in the PGDG package. In practice it came down to enabling one more build flag and bundling the InChI source. It worked on the first proper pass, and the user was happy.
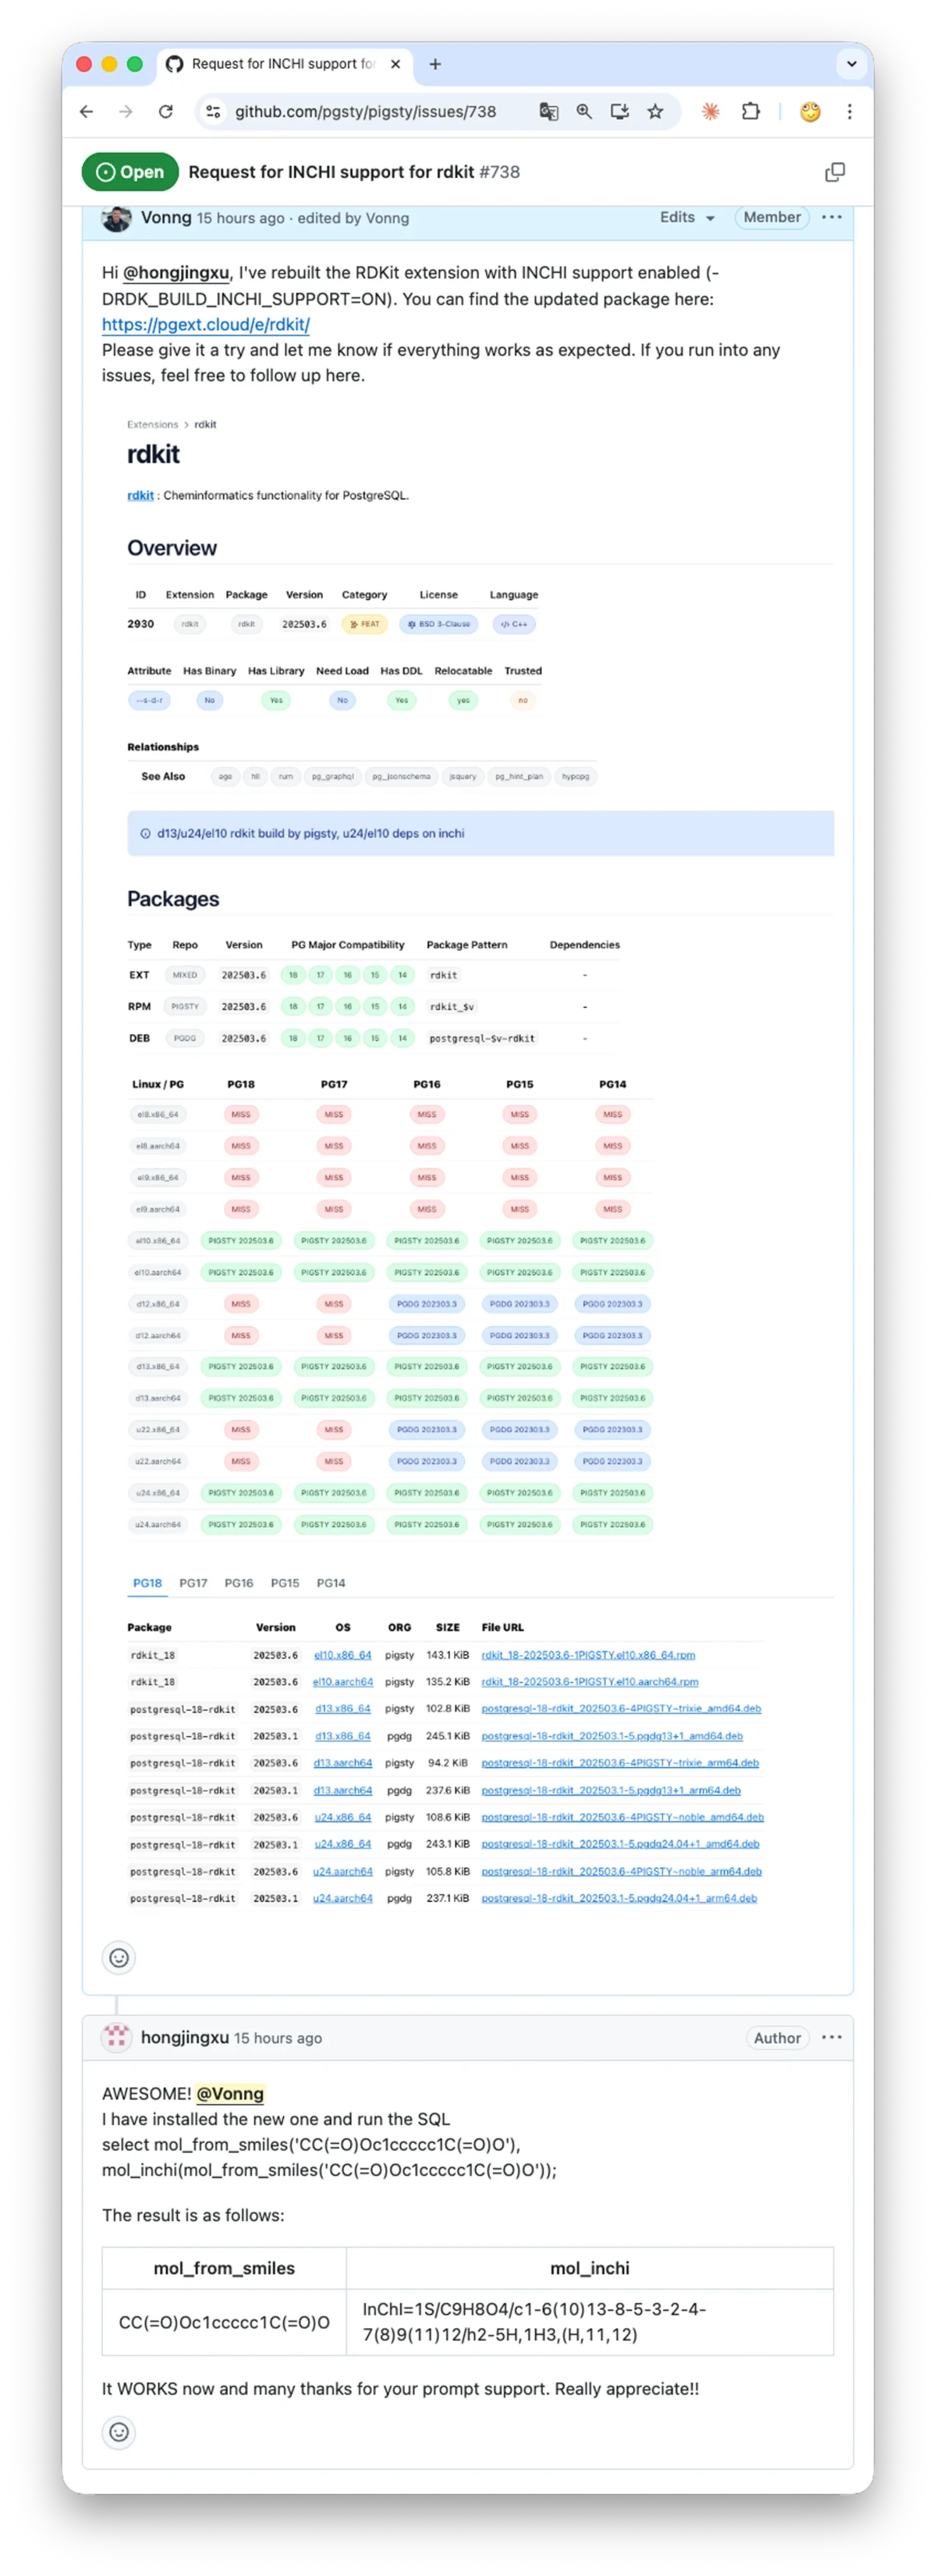
Honestly, feedback like that is the best part of doing open source.
Strike While the Iron Is Hot
Once I was warmed up, I went after a few other long-standing problem cases.
plv8: PostgreSQL bindings for the V8 engine. It had refused to build on EL10 for a while. This time, after carrying a few patches, I finally got it building reliably.
duckdb_fdw: lets PostgreSQL read and write external DuckDB files. Previously it clashed with DuckDB’s official pg_duckdb extension because both wanted the same shared library name, so I had to hide it temporarily. This time I turned duckdb_fdw into a sub-extension of pg_duckdb, so they share the same libduckdb. The conflict is gone, and both can coexist cleanly again.
At that point I figured: if the toolchain is already hot, why not finish the rest of the worthwhile extensions in the PostgreSQL ecosystem that had been sitting on the backlog? That turned into this release: 32 new additions, 22 updates, and the Pigsty extension repo officially crossing 500, landing at 504 total extensions.
| Category | All | PGDG | PIGSTY | CONTRIB | MISS | PG18 | PG17 | PG16 | PG15 | PG14 |
|---|---|---|---|---|---|---|---|---|---|---|
| Total | 504 | 155 | 332 | 71 | 0 | 481 | 488 | 479 | 473 | 457 |
| EL | 499 | 150 | 332 | 71 | 5 | 472 | 482 | 474 | 468 | 452 |
| Debian | 489 | 107 | 311 | 71 | 15 | 466 | 474 | 464 | 458 | 442 |
The catalog combines PostgreSQL’s bundled extensions with packages from PGDG and Pigsty. The repository counts overlap: some extensions are available from more than one source.
To put that in perspective: most managed PostgreSQL cloud RDS expose a few dozen extensions at best. Take Supabase, for example. It looks like a long list, but after you subtract the 35 contrib extensions that come with PostgreSQL, you are left with fewer than 30 third-party extensions.
The New Extensions
This batch is heavy. Broadly, four groups:
Data-domain extensions: make chemical molecules, RDF triples, BSON, Protobuf, recurring schedules, and other complex objects first-class database citizens.
Query extensions: sparse linear algebra and graph algorithms, Datalog-style graph queries, full-text search, hybrid ranking fusion, recursive SQL template engines.
Production engineering extensions: deep observability, exported query telemetry, CDC to MQTT, COPY interception, DDL propagation for logical replication, lightweight distributed locks, soft-alert data quality management.
Developer-experience extensions: session variables, pseudo-autonomous transaction logging, natural-language time parsing.
Together they point to a broader trend: the extension layer is pushing PostgreSQL into the space between an application platform and a data platform. Things that used to require separate services increasingly fit inside a single SQL transaction boundary.
A Tour of the New Additions
This release adds 32 new extensions. The summaries below were compiled with help from Claude, Codex, and Gemini to give readers a quick way to understand what each one does, how it works, and where it fits.
1. rdkit: Cheminformatics Inside PostgreSQL
RDKit is the de facto standard open-source cheminformatics library, started by Greg Landrum (originally at Novartis, now T5 Informatics). Its PostgreSQL cartridge brings molecular storage, substructure search, and similarity computation into a relational database — millions of compounds queryable with plain SQL.
The cartridge adds mol (molecules) and qmol (SMARTS query patterns), plus bfp/sfp fingerprint types. Operators: @> for substructure matching, % for Tanimoto similarity, <%> as a distance operator — all GiST-indexable via fingerprint pre-filtering. Key functions: mol_from_smiles(), morganbv_fp(), tanimoto_sml(). GUCs like rdkit.tanimoto_threshold control match sensitivity.
Using the ChEMBL dataset with 1.87 million compounds as an example:
Use cases center on drug discovery: lead scaffold search across million-scale libraries, SAR analysis via similarity, compound registration with fingerprint dedup, and catalog search over datasets like eMolecules (6M+ compounds).
Settle your index strategy and query templates early — filters that are correct but bypass indexes will be slow. On 1.87M compounds, substructure queries range from ~88 ms to ~1.9 s; with tuning, the cartridge handles 6M+ compounds. BSD licensed. Docker images (mcs07/postgres-rdkit) and conda packages available.
2. provsql: Semiring Provenance for Query Results
ProvSQL, from Pierre Senellart (ENS Paris / INRIA Valda, VLDB 2018), adds (m-)semiring provenance and uncertainty management to PostgreSQL. It tracks which base tuples each query result was derived from, and lets you evaluate that provenance under different algebraic structures: booleans, security levels, counts, or probabilities.
It hooks into query execution and adds a hidden provsql UUID column to each table, pointing into a provenance circuit. Supported SQL is broad: SELECT-FROM-WHERE, JOIN, GROUP BY, DISTINCT, UNION/EXCEPT, aggregates, HAVING, and on PG 14+ also INSERT/DELETE/UPDATE. Core functions: add_provenance(), provenance_evaluate(), formula(), probability_evaluate(). Probability evaluation ranges from naive to Monte Carlo to d-DNNF compilation via external solvers (d4, c2d).
Four typical scenarios: security-label propagation (results inherit the highest source classification), probabilistic databases (base tuples carry confidence scores), data lineage and audit (trace each output row back to sources, optionally export as PROV-XML), and credibility scoring (e.g. weighting witness statements in investigative workflows).
The key property is composability: provenance is not a dead log string but a live object you can keep computing on. Worth enabling on critical paths — core reports, feature pipelines, compliance calculations — not as a blanket switch for the whole database. C/C++ with Boost; provenance circuits live in shared memory. PG 10–18. MIT.
3. onesparse: Billion-Edge Graph Algorithms in SQL
OneSparse wraps SuiteSparse:GraphBLAS to bring high-performance sparse linear algebra into PostgreSQL. Developer Michel Pelletier sits on the GraphBLAS C API committee; advisor Timothy A. Davis is the SuiteSparse author. The premise: represent graphs as sparse matrices and run BFS, PageRank, triangle centrality, and friends via matrix operations — all from SQL.
Types: matrix, vector, scalar, semiring, monoid. Operator @ for matrix multiplication under plus_times semiring. Ships LAGraph algorithms: BFS (level and parent modes), PageRank, triangle centrality, degree centrality, SSSP. Wraps GraphBLAS opaque handles in PostgreSQL’s Expanded Object Header; small graphs (<1 GB) in TOAST, larger ones as Large Objects or files. Built-in JIT with NVIDIA CUDA GPU acceleration.
The published GAP benchmarks include graphs with up to 4.3 billion edges and report BFS throughput above 7 billion edges per second on some inputs. Potential uses include transaction-graph fraud detection, social-network analysis, and Graph RAG. Test data loading, serialization, and query planning with a small representative graph before scaling up.
Requires PG 18 Beta or newer; still alpha. Apache 2.0.
4. pg_datasentinel: Deep Observability for PostgreSQL in the Container Era
pg_datasentinel (Christophe Reveillere / Datasentinel, 1.0 released April 10 2026) fills four gaps in PostgreSQL’s native monitoring, especially for containerized deployments:
- Extended activity monitoring — augments
pg_stat_activitywith per-backend memory usage, live temp-file bytes, and on PG 18+ the current plan ID. - Container resource visibility — CPU quotas, memory limits/usage, and CPU pressure for Docker / Kubernetes / OpenShift / any cgroup environment.
- Transaction wraparound forecasting — tracks XID and MXID burn rate, exposes live ETAs to aggressive vacuum and wraparound limits.
- Log capture views — parses vacuum, analyze, temp-file, and checkpoint events into a shared-memory ring buffer queryable from SQL.
For PostgreSQL on Kubernetes, this gives container-level visibility without a separate monitoring agent. The XID wraparound warning is the standout — wraparound can force-shutdown a database, and having a burn-rate ETA turns firefighting into forecasting. 3-Clause BSD. PG 15+.
5. datasketches: Approximate Analytics at Hundred-Million-Row Scale
Apache DataSketches (Apache Foundation, originally Yahoo/Verizon Media) brings approximate query data structures into SQL. When exact COUNT(DISTINCT), quantiles, or heavy-hitter analysis gets too expensive on large datasets, sketches trade a few percent of accuracy for orders of magnitude in speed and memory.
Seven sketch types: cpc_sketch (compressed probabilistic counting), hll_sketch (HyperLogLog), theta_sketch (distinct counting with set algebra), aod_sketch (tuples), kll_float_sketch/kll_double_sketch (quantiles), req_float_sketch (tail quantiles), frequent_strings_sketch (frequent items). Standard API: *_sketch_build(), *_sketch_union(), *_sketch_get_estimate().
What makes sketches powerful is mergeability: pre-aggregate by dimension slice, union at query time for arbitrary distinct counts. Sublinear memory. Binary format compatible across Java, C++, Python, Rust, and Go.
Use cases: real-time UV counting without storing user IDs, latency distribution (p50/p95/p99 over billions of events), audience overlap via Theta Sketch intersections (“saw ad A and visited site B”). On 100M rows, CPC distinct counting takes ~20 s vs ~2 min for exact COUNT(DISTINCT), with single-digit percent relative error.
6. pghydro: Drainage-Network Analysis from Brazil’s National Water Agency
PgHydro, by Alexandre de Amorim Teixeira (Brazil’s National Water and Sanitation Agency, ANA), is ANA’s official tool for hydrology workflows nationwide. Built on PostGIS, presented at FOSS4G 2022.
It covers the full hydrological network workflow: GIS data import, topological consistency checks, flow direction, Otto Pfafstetter basin coding, upstream/downstream analysis, catchment area, and Strahler stream order. Five sub-extensions: pghydro (core), pgh_raster (DEM), pgh_hgm (hydrogeomorphology), pgh_consistency (validation), pgh_output (export).
Fits national-scale hydrology databases, basin planning, upstream/downstream pollution analysis, and drainage-network validation. Think of it less as “an extension with GIS functions” and more as a domain-specific ETL pipeline living inside the database — raw terrain and river data in PostGIS, processing automated in SQL, recomputation after source updates far more reliable than ad hoc scripts. QGIS plugin PgHydroTools available for visual interaction. Pure PL/pgSQL. GPLv2.
7. pg_stat_ch: PostgreSQL Query Telemetry, Exported to ClickHouse
pg_stat_ch was announced by ClickHouse on February 13, 2026, with Kaushik Iska as the author. Where pg_stat_statements aggregates inside PostgreSQL, pg_stat_ch streams every raw query execution event (45 fields, fixed 4.6 KB each) out to ClickHouse for p50/p95/p99 analysis, top-query ranking, and error analytics.
Pipeline: PG hooks → shared-memory ring buffer → background worker → ClickHouse via native binary protocol with LZ4 compression (statically linked clickhouse-cpp). The 45 fields cover timing, row counts, buffers, WAL, CPU, JIT (PG 15+), parallel workers (PG 18+), client context, and SQLSTATE errors. On queue overflow it drops events and bumps a counter rather than applying backpressure — StatsD philosophy.
On the ClickHouse side it ships four materialized views: events_recent_1h for a rolling one-hour copy, query_stats_5m for five-minute buckets with TDigest quantiles, db_app_user_1m for database/app/user load attribution, and errors_recent for a rolling seven-day error window.
Performance: ~5 μs p99 overhead per query. pgbench at 36.6K TPS / 32 clients captured 7.7M events in 30 s with zero drops and <1% TPS impact. Lock contention minimized in three layers: atomic overflow checks → non-blocking LWLock → per-backend local buffers flushed per transaction (~5x fewer lock acquisitions). A clean division of labor: PostgreSQL for transactions, ClickHouse for telemetry. Far more robust than reconstructing the same picture from log files. PG 16–18. Apache 2.0.
8. pg_rrf: Rank Fusion for Hybrid Search in One Function
pg_rrf (yuiseki, January 2026, Rust/pgrx) packages Reciprocal Rank Fusion (RRF) as a native PostgreSQL function. In hybrid retrieval, different retrievers produce scores on incomparable scales. RRF sidesteps that by using rank positions only:
score(d) = Σ 1 / (k + rank_i(d))
The default k is 60, following Cormack et al., SIGIR 2009.
The extension exposes four functions: rrf(rank_a, rank_b, k) for two-way fusion, rrf3() for three-way fusion, rrfn(ranks[], k) for N-way fusion, and the most useful one in practice, rrf_fuse(ids_a bigint[], ids_b bigint[], k), which takes two ranked ID arrays and returns a fused (id, score) table. It is NULL-safe: an ID that appears in only one list is scored from that list alone.
Replaces 20+ lines of FULL OUTER JOIN / COALESCE / hand-rolled score math with one function call. Good fit for RAG hybrid retrieval, product search, and multi-signal document ranking. Keeping fusion in the database helps when the fused result still needs to join business tables. v0.0.3. MIT.
9. pg_kazsearch: Kazakh Full-Text Search, from Zero to One
pg_kazsearch is the first PostgreSQL full-text-search extension for Kazakh. Kazakh is highly agglutinative — a single word like мектептерімізде stacks plurality, possession, and locative suffixes atop the root мектеп. Existing PG and Elasticsearch analyzers cannot handle this.
Written in Rust/pgrx. Provides kazakh_cfg text-search config and pg_kazsearch_dict. Stemming uses BFS suffix stripping with vowel-harmony validation and a 21,863-root POS-tagged lexicon (Apertium-kaz) to prevent over-stemming. Tunable via ALTER TEXT SEARCH DICTIONARY.
Benchmarks on 2,999 articles: 0.5 ms query latency (2.8x faster than pg_trgm), +25% nDCG@10, +23% Recall@10. Useful for Kazakh news/government-document search, e-commerce, and multilingual systems that need proper search for low-resource languages instead of crude trigram fallback.
10. pg_liquid: Datalog-Style Graph Queries
pg_liquid (Michael Golfi) brings Liquid/Datalog-style declarative graph queries into PostgreSQL. liquid.query(...) lets you declare facts, define rules, and run a terminal query in one call — no separate graph database needed. Rules are scoped to a single invocation. Supports fact assertions, recursive transitive closure, compound queries, and row normalizers.
Also supports ontology predicates (DefPred) and typed compounds (OntologyClaim@(...)), where compounds carry provenance or confidence while rules handle subclass closure. Good fit for knowledge-graph queries, hierarchy traversal (org charts, taxonomy trees), and rule-based business logic. Pure PL/pgSQL, no external dependencies. Early-stage.
11. logical_ddl: Logical Replication, but for DDL Too
PostgreSQL logical replication handles DML only — no DDL. Schema drift breaks replication. logical_ddl (Samed Yildirim) fills that gap with event triggers that intercept DDL, deparse it into a replicated table, and generate equivalent SQL on the subscriber side.
Supported: ALTER TABLE RENAME TO, RENAME COLUMN, ADD COLUMN, ALTER COLUMN TYPE, DROP COLUMN. Built-in types, arrays, composites, domains, and enums work; CREATE TYPE itself is out of scope. logical_ddl.publish_tablelist controls capture per table and per command type.
Useful for automated DDL sync in logical-replication setups, zero-downtime migrations, and multi-datacenter topologies. DDL propagation becomes an auditable data flow rather than a manual side process. MIT. PGXN available. Constraints, indexes, and defaults not yet supported.
12. rdf_fdw: Query the Semantic Web with SQL
rdf_fdw (Jim Jones) is a foreign data wrapper that bridges SQL and the semantic web by querying RDF triple stores via SPARQL endpoints. Adds an rdfnode type for IRIs, language tags, and typed literals. Supports SQL-to-SPARQL pushdown for WHERE/LIMIT/ORDER BY/DISTINCT, plus INSERT/UPDATE/DELETE via SPARQL UPDATE endpoints.
rdf_fdw_clone_table() can batch-clone foreign data into local tables. Watch memory: fetched data is loaded before conversion, so large result sets need effective pushdown. Good for linked-data integration (DBpedia, Wikidata) and using SQL/BI tooling on SPARQL endpoints. MIT. PG 9.5–18.
13. pgbson: A More Exact Binary Document Type than JSONB
pgbson (buzzm, a.k.a. postgresbson) adds a native BSON type to PostgreSQL. BSON provides first-class datetime, decimal128, int32/int64, binary, etc. — types that matter for exact round-tripping across distributed systems. Binary-perfect BSON in, BSON out.
Two access styles. Fast path: dotpath functions like bson_get_string(bson, 'd.recordId'), bson_get_datetime(), bson_get_decimal128() — walk the binary directly, allocate only at the leaf. Slow path: -> / ->> operators that construct intermediate subdocuments at each level. Expression indexes on the function API can yield 10,000x speedups over sequential scan. Also accepts EJSON input.
Use cases: cross-language event pipelines needing exact type preservation, financial data (decimal128), and digital-signature workflows relying on deterministic binary representation. MIT. PG 14–18.
14. pg_when: Describe Time in Natural Language
pg_when (frectonz) parses natural-language time expressions into timestamptz or Unix epochs. when_is(text) returns a normalized timestamp; grammar: date + at + time + in + timezone, defaulting to UTC.
Also: seconds_at(), millis_at(), micros_at(), nanos_at() for Unix epochs at varying precision. A parser, not a scheduler. Fits operator-facing tools that accept human time input, backfill scripts where natural language beats date math, and timezone normalization. MIT.
15. pgmqtt: Push Database Changes Straight to MQTT
pgmqtt (RayElg, Rust) turns PostgreSQL row changes into MQTT messages and maps inbound MQTT messages back into tables. Not a general MQTT client — it wires database CDC to a message broker at the database layer, with SQL-defined topic mappings and payload templates.
Natural fit for IoT: push database state changes to edge devices without middleware, or ingest sensor readings from MQTT directly into tables. Also works for lightweight event-driven systems that want less glue code. Elastic License 2.0.
16. pg_query_rewrite: Transparent SQL Substitution
pg_query_rewrite (Pierre Forstmann) uses the post_parse_analyze_hook to rewrite parsed SQL statements. Rules live in shared memory, matched by exact string equality — whitespace and case both matter.
Statements must match exactly, including whitespace, case, and semicolons. Parameterized statements are unsupported, and each statement is limited to about 32 KB. Reload rules after a restart. This is useful for redirecting fixed SQL during migrations and for query A/B tests. Default max 10 rules. PG 9.5–18.
17. pgclone: Clone Database Objects with One Function Call
pgclone (valehdba, v2.0.0 on PGXN) lets you clone tables, schemas, databases, functions, roles, and privileges from a source instance via SQL functions — no pg_dump/pg_restore or shell scripts needed.
Uses the COPY protocol for fast data movement. Supports async operation with progress tracking, row/column filters, DDL coverage (indexes, constraints, triggers, views, materialized views, sequences), masking, and automatic sensitive-column discovery.
Good for fast dev/test provisioning, sanitized prod-to-staging clones, and cross-database migration — the whole workflow stays inside the database.
18. pgproto: Native Protobuf Support
pgproto (Apaezmx) adds native Protocol Buffers (proto3) storage, query, mutation, and indexing. Register a FileDescriptorSet in pb_schemas, then protobuf columns expose nested fields via path arrays. Operators: -> field navigation, #> nested path, || message merge. Functions: pb_set(), pb_insert(), pb_delete(), pb_to_json().
100K-row benchmark: 16 MB storage (vs 46 MB JSONB, 25 MB relational), 5.9 ms full-document retrieval (vs 33.1 ms relational with multi-table joins). If you want to keep Protobuf for RPC/messaging while making the data indexable inside the database, this delivers. Fits IoT data, microservice event stores, gRPC data layers. PostgreSQL License.
19. pg_fsql: A Recursive SQL Template Engine Driven by JSONB
pg_fsql (yurc) is a recursive SQL template engine driven by JSONB. Templates are organized as dot-path trees; child templates emit fragments or JSON injected into parents. Placeholder syntax: {d[key]} with escaping modes (!r, !j, !i). Command types: exec, ref, if, exec_tpl, map, NULL. Optional SPI plan caching per template. APIs: fsql.run (execute), fsql.render (dry run), fsql.tree, fsql.explain. No superuser needed.
Not “functional SQL” — more a hierarchical template system for generating SQL from JSON request bodies. Reduces conditional branching in the application layer. Fits dynamic reports, ETL orchestration, multi-tenant query generation, and centralized SQL templates stored in tables.
20. pg_dispatch: Async SQL Dispatch on Top of pg_cron
pg_dispatch (Snehil Shah) is an async SQL dispatcher built on pg_cron, TLE-compatible alternative to pg_later. pgdispatch.fire(command) for immediate async execution, pgdispatch.snooze(command, delay) for delayed. The point: get heavy work out of the foreground transaction — if an AFTER INSERT trigger needs something expensive, push it to the background.
Pure PL/pgSQL, runs in sandboxed environments (Supabase, AWS RDS). Requires pg_cron >= 1.5. Good for async side effects in triggers/functions — notifications, background rollups, audit writes that should not block the main transaction.
21. block_copy_command: Security Hardening by Intercepting COPY
block_copy_command (rustwizard, Rust/pgrx) intercepts COPY cluster-wide via ProcessUtility hook. In PCI-DSS or HIPAA environments: block exfiltration via COPY TO, block unauthorized imports via COPY FROM.
Role-based blocklists, directional control (block_to / block_from), COPY ... TO PROGRAM blocked for everyone by default. Blocklist can include superusers. Built-in audit logging.
Useful in multi-tenant or hosted environments, enterprise compliance setups needing centralized audit, and ETL environments where import/export privileges must be tightly separated. The author also maintains a broader command-firewall extension, pg_command_fw.
22. pg_isok: Soft Alerts for Data Quality
pg_isok (Karl O. Pinc, in production for 10+ years) is soft-trigger data integrity management. You write SQL queries that find suspicious data patterns; Isok records, classifies, and defers findings, surfacing only newly introduced problems or changes to previously accepted data — no re-reviewing the same historical anomalies.
Unlike hard constraints, Isok lets questionable data exist while keeping it under review. Workflow: isok_queries and isok_results tables, run_isok_queries to execute checks; results accepted or deferred row by row. Fits messy-data cleanup and business rules too fuzzy for hard constraints that still need human judgment.
23. external_file: Oracle BFILE Semantics for PostgreSQL
external_file (Gilles Darold, HexaCluster Corp) provides Oracle BFILE equivalence. EFILE type references server-side files via directory alias + filename; readEfile(), writeEfile(), copyEfile() for I/O. Built on lo_* large-object machinery with directory-alias and privilege tables controlling access.
Built for Ora2Pg migrations, but also useful for legacy systems with files outside the database and metadata inside, or database-driven batch import/export of external large objects.
24. byteamagic: Detect File Types in bytea
byteamagic (Nico Mandery) wraps libmagic (the library behind Unix file). Two functions: byteamagic_mime(bytea) returns MIME type, byteamagic_text(bytea) returns human-readable description.
If you store BLOBs in tables, this identifies what they actually are from SQL. Good for upload governance, real content-type detection, and historical BLOB cleanup.
25. pg_text_semver: Native Semantic Versioning
pg_text_semver (Rowan Rodrik van der Molen) implements SemVer 2.0.0 as a text domain. Unlike the C-based semver extension, version components have no 32-bit integer limit.
Pure SQL. Supports min/max aggregation and PGXN version-range validation. Useful for extension/package version management, dependency checks, and version analytics.
26. parray_gin: Substring Matching Indexes for text[]
parray_gin (Eugene Seliverstov) adds partial-match operators for text[] columns backed by GIN indexes. Native GIN array operators only do exact element matching; parray_gin adds @@> for matching array elements against LIKE patterns, using pg_trgm trigram decomposition with recheck for false positives.
Useful for tag autocomplete, fuzzy tag search, or any case where array partial matching should hit an index. PG 9.1–18.
27. pg_slug_gen: Cryptographically Secure Timestamp Slugs
pg_slug_gen (Fernando Olle) generates short unique identifiers combining timestamp info with cryptographically secure randomness (pg_strong_random()). Length sets precision: 10 chars (seconds), 13 (milliseconds), 16 (microseconds, default), 19 (nanoseconds).
Not a “slugify the title” URL helper — a short, hard-to-guess public identifier. Good for invite codes, short links, and public resource IDs where exposing auto-increment sequences is undesirable. Much less predictable than base62(sequence).
28. pglock: Lightweight Distributed Locks Inside PostgreSQL
pglock (fraruiz) implements lightweight distributed locks on top of PostgreSQL. Lock table + functions: pglock.lock, pglock.unlock, pglock.ttl, pglock.set_serializable. TTL expiration (default 5 min), optionally reaped by pg_cron. Recommended isolation: SERIALIZABLE.
No Redis or ZooKeeper needed. Fits multi-instance job competition, leader election, idempotent consumers, duplicate-work prevention — lock behavior and business writes stay in the same database. Pure SQL.
29. pg_regresql: Portable Planner Statistics for EXPLAIN Costing
pg_regresql (Radim Marek / boringSQL) solves a specific plan-regression-testing problem: the planner reads real file sizes from disk and scales row counts accordingly, so injected production-sized statistics in pg_class get overridden by your tiny CI dataset’s physical size.
The extension hooks get_relation_info_hook to force the planner to trust pg_class values (relpages, reltuples, relallvisible) instead of physical file sizes. This makes cost estimates portable — compare EXPLAIN output across schema versions, reproduce production plans on a laptop, keep plan baselines stable in CI.
Only affects planner costing, not execution or EXPLAIN ANALYZE actuals. For test/CI only, not production. BSD 2-Clause.
30. pgcalendar: Infinite Projection for Recurring Schedules
pgcalendar (h4kbas) implements a full recurring-event calendar. Events are logical entities; schedules define recurrence (daily/weekly/monthly/yearly); projections generate concrete occurrences; exceptions cancel or reschedule individual instances.
Infinite projection, schedule transitions, and exception handling show up everywhere — rostering, meetings, billing — and become a mess when every application reimplements them. Putting this in the database centralizes permissions, audit, and consistency.
31. pg_variables: Session Variables Faster than Temp Tables
pg_variables (Postgres Professional) adds session-level variables — scalars, arrays, and records — grouped into named packages. By default variables do not roll back; with is_transactional = true they honor ROLLBACK and SAVEPOINTs.
A high-performance temp-table alternative that avoids catalog bloat. Useful for intermediate state in stored procedures/batch jobs, connection-level caching, and as infrastructure for other extensions (pgelog uses it to cache dblink connections).
32. pgelog: Logs That Survive Rollback
pgelog (anfiau) uses dblink to simulate pseudo-autonomous transactions — log records survive even when the calling transaction rolls back. Solves a classic PL/pgSQL problem: logs written inside an EXCEPTION block disappear when the outer transaction aborts. Uses pg_variables to cache dblink connections per session.
On critical paths, losing the diagnostic trail because the business transaction rolled back is exactly the wrong outcome. Also makes staged batch/migration scripts easier to introspect than RAISE NOTICE. Depends on dblink and pg_variables; each session may open an extra connection, so mind max_connections.
Conclusion
These 32 additions trace a few clear lines.
More “professional objects” inside the database. BSON, Protobuf, RDF, recurring schedules, molecules, graphs — the database becomes a queryable store for complex domain objects, with permissions, audit, backup, and transactions already built in. Less data movement, fewer sidecar services.
Query capabilities as composable APIs. RRF fusion, recursive SQL templates, query rewriting, sparse algebra, sketch approximations — more logic expressed in fewer, more stable SQL building blocks, auditable and optimizable.
The extension layer absorbing platform and ops work. Telemetry export (pg_stat_ch), container visibility (pg_datasentinel), security hooks (block_copy_command), soft-alert governance (pg_isok) — capabilities that used to live outside the database are being pulled in.
Deeper vertical penetration. Cheminformatics (rdkit), hydrology (pghydro), Kazakh NLP (pg_kazsearch) — PostgreSQL keeps becoming the computational substrate for more specialized fields.
Cathedrals (Apache Foundation projects) and bazaars (weekend builds) side by side, building the most advanced open-source database ecosystem in the world.
Originally published on vonng.com.
1.7 - The PostgreSQL Extension Encyclopedia: Bilingual and Ready to Use
Extensions are the soul of PostgreSQL. Without them, PostgreSQL is just a very good relational database. With them, it becomes a platform that can swallow entire categories of database workloads.
The problem is that the extension ecosystem has long been awkward to use. People struggle to find extensions, understand them, and install them. You search GitHub for README files, check PGXN for packages, and then wrestle with OS and PG version compatibility by hand.
So I built something different: an encyclopedia for 464 PostgreSQL extensions, each one with a full profile, plus a real binary repository behind it.
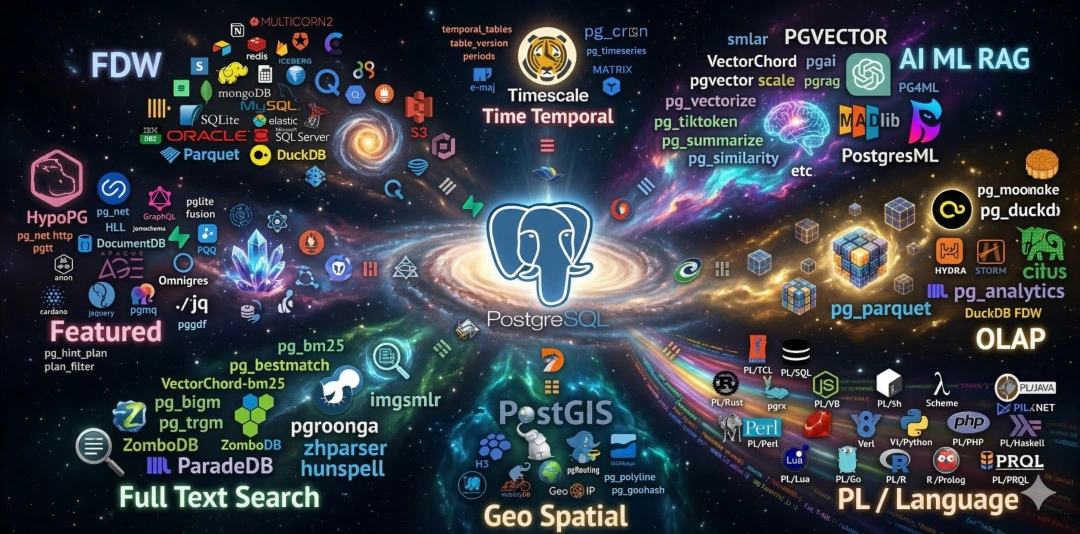
Not just a list
There is no shortage of extension lists on the internet. What is usually missing is operational detail.
On each extension page, you can directly see:
- Basic metadata: version, category, language, license, repository, source download.
- Extension properties: preload requirement, DDL presence, trust, relocatability, target schema.
- Version and packaging data: supported PG majors, RPM/DEB names.
- Platform matrix: which packages exist for which OS and architecture combinations.
- Install commands: ready-to-copy commands for
pig,dnf, andapt. - Relationships: dependencies, conflicts, and related extensions.
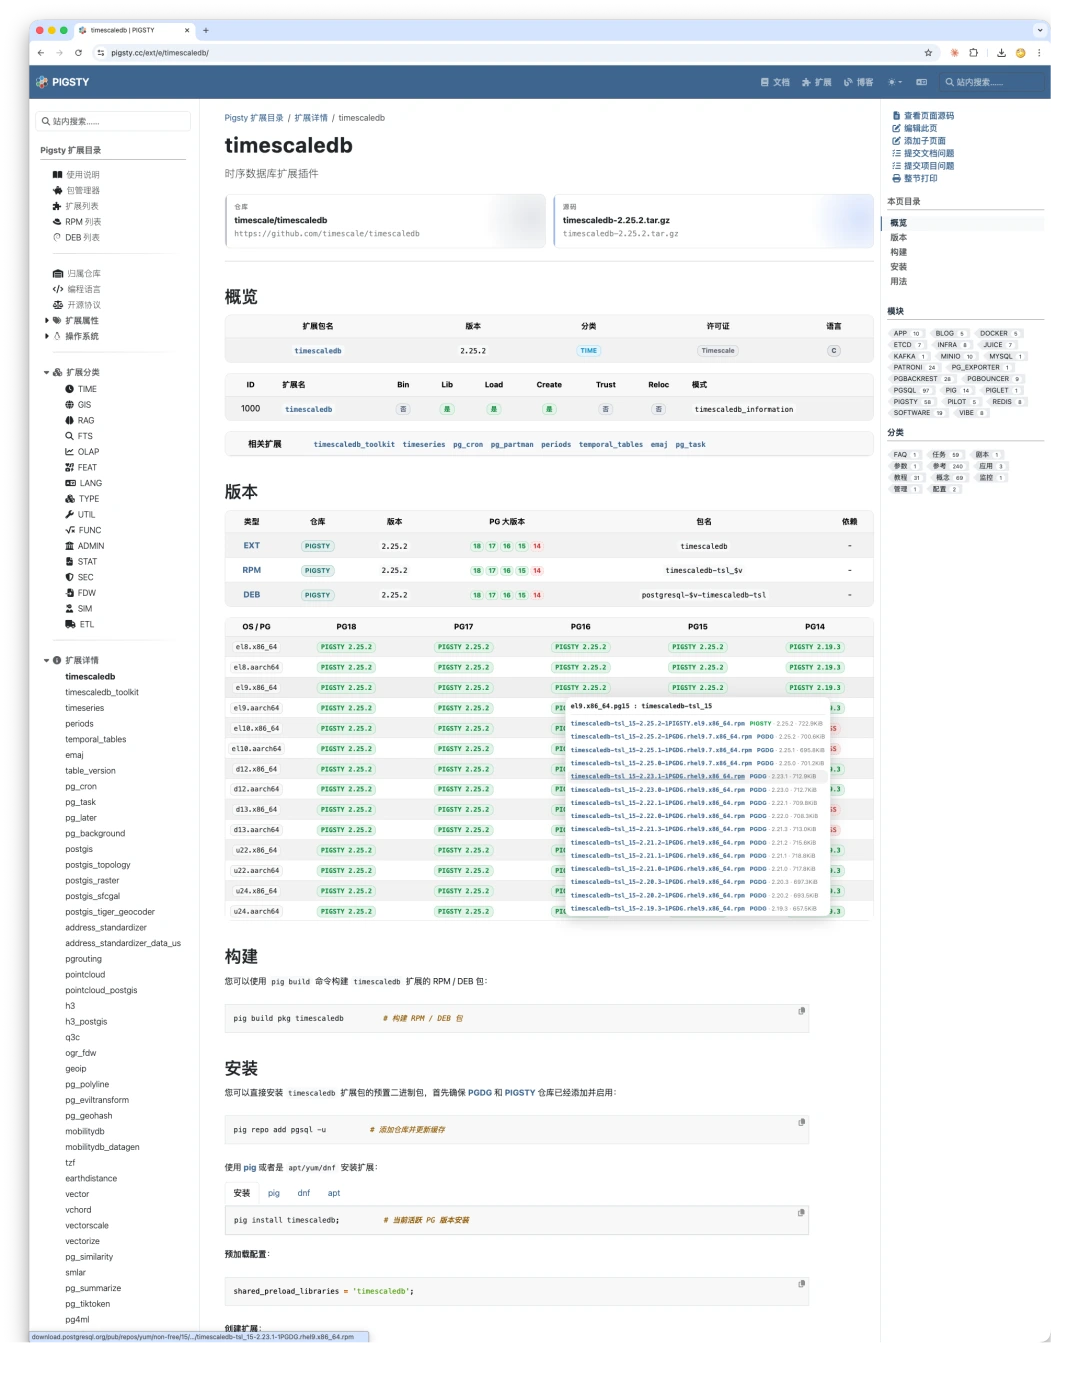
We also aggregated 460+ extension docs so people can browse a large portion of the PG extension world in one place.
464 extensions, 16 categories
The catalog is split into 16 major categories. If you have heard that PostgreSQL can behave like a time-series database, vector database, graph database, document store, or even emulate Oracle and SQL Server semantics, this is where you can see which extensions actually make those claims real.
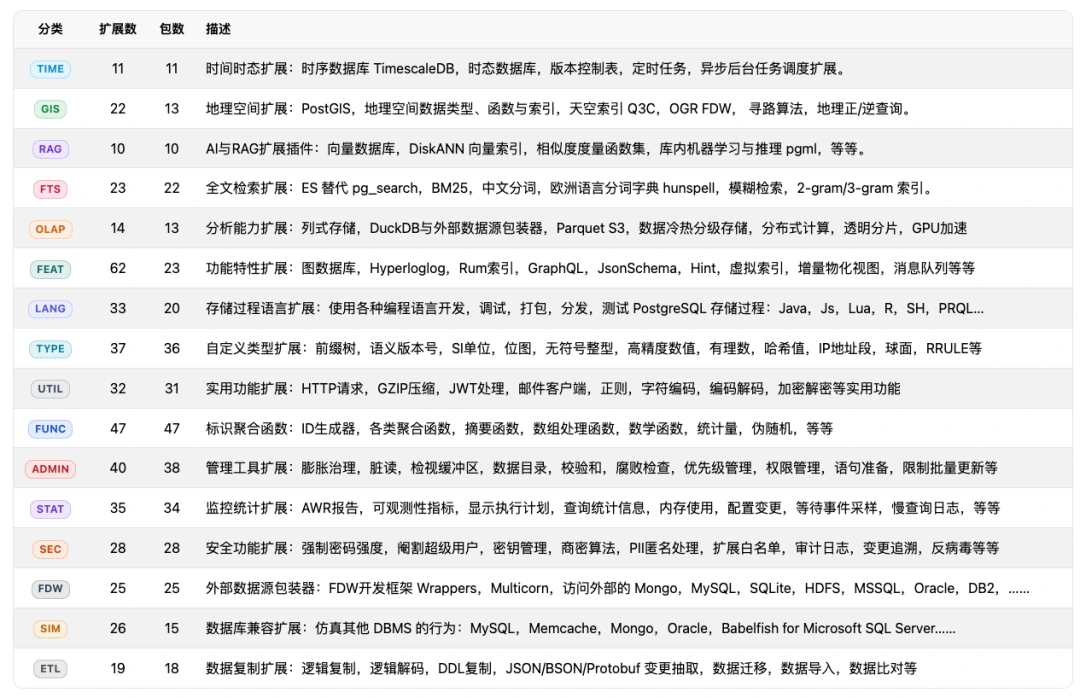
Multiple ways to browse
You can explore the catalog from multiple angles:
By repository origin
Extensions are grouped into PGDG, PIGSTY, and CONTRIB.
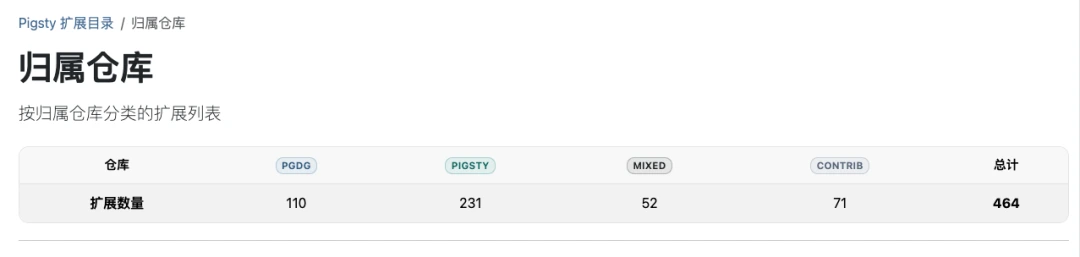
By implementation language
You can see how much of the ecosystem is written in C, C++, Rust, Java, Python, SQL, or plain data files.
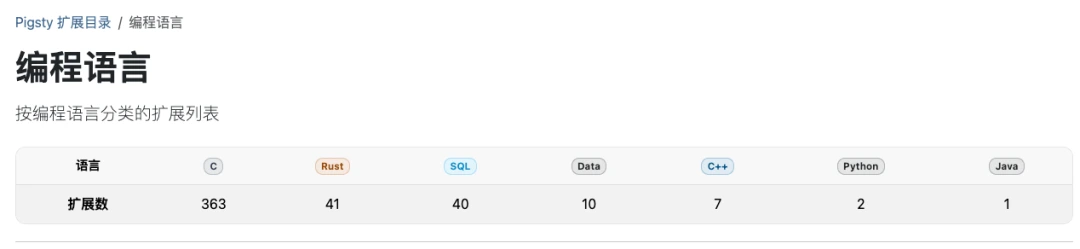
By license
MIT, Apache 2.0, PostgreSQL, BSD, GPL, AGPL, Timescale License: all of them matter in real-world adoption.
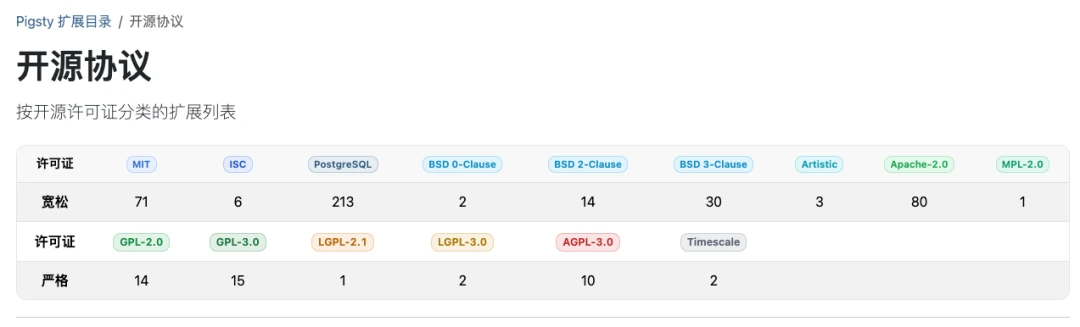
By extension properties
Need shared_preload_libraries? Contains no SQL DDL? Conflicts with something else? Packages multiple extensions together? The directory makes those traits visible.
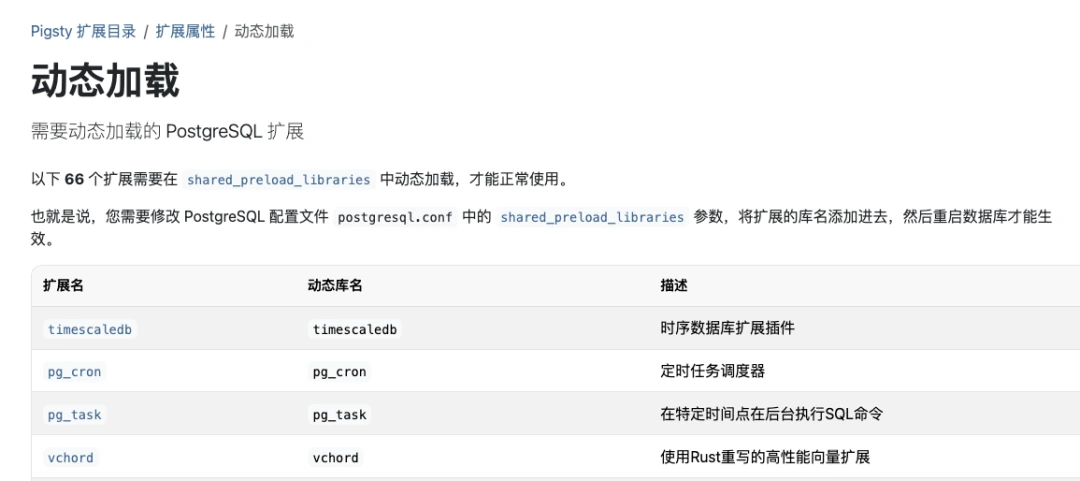
By platform
At the OS and CPU level, you can see exactly which extensions are available and which are not.
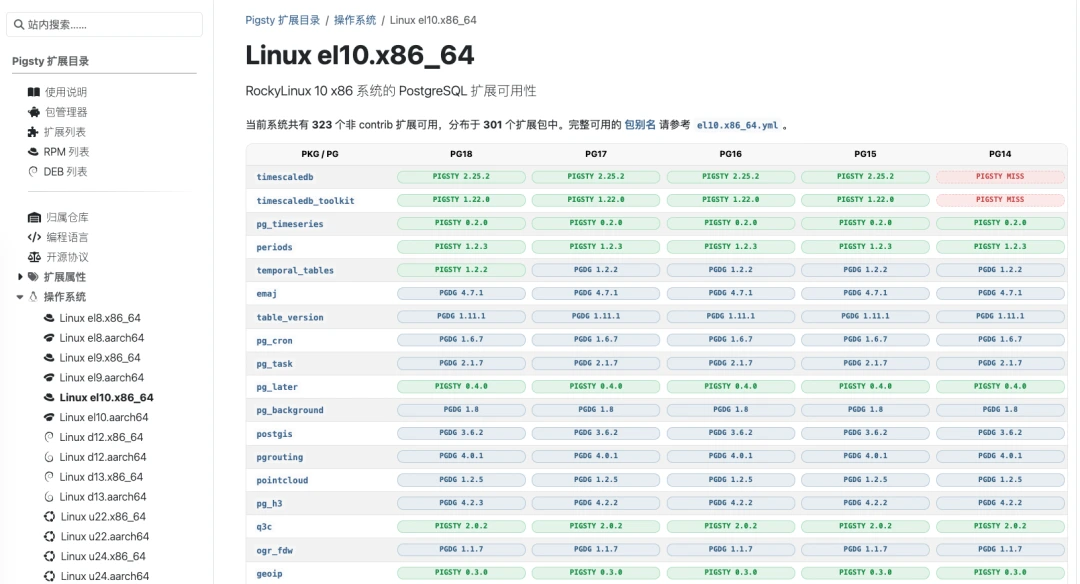
The full stack: directory + repo + package manager
The catalog only makes sense because it sits on top of real infrastructure:
- Directory: what exists, what it does, whether it is available.
- Binary repository: prebuilt RPM/DEB packages distributed through CDN.
pigpackage manager: one command to install across different OS and PG versions.
Together, they turn discovery, evaluation, installation, and use into a single workflow.
A few numbers
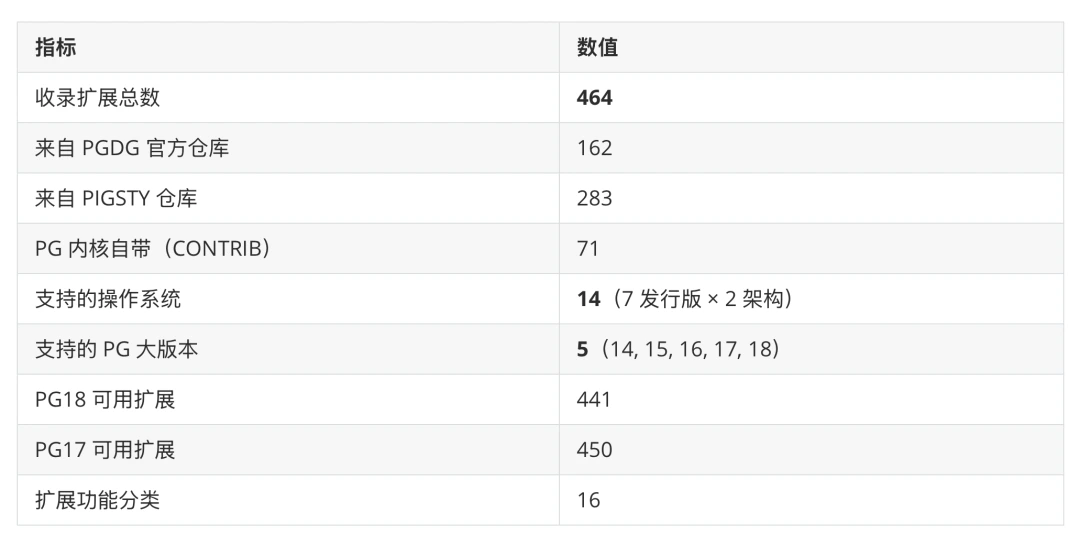
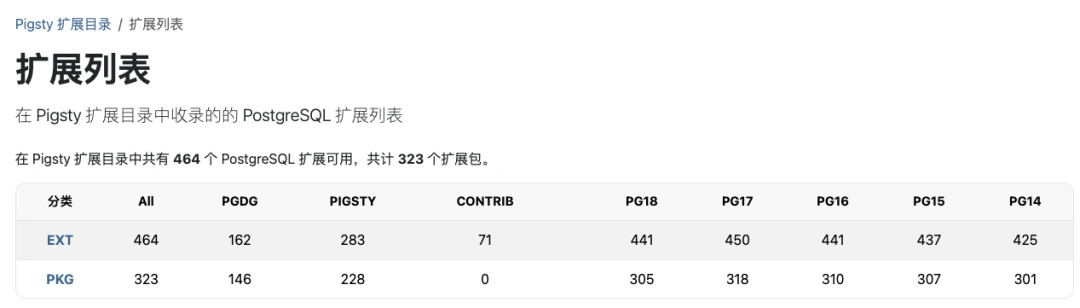
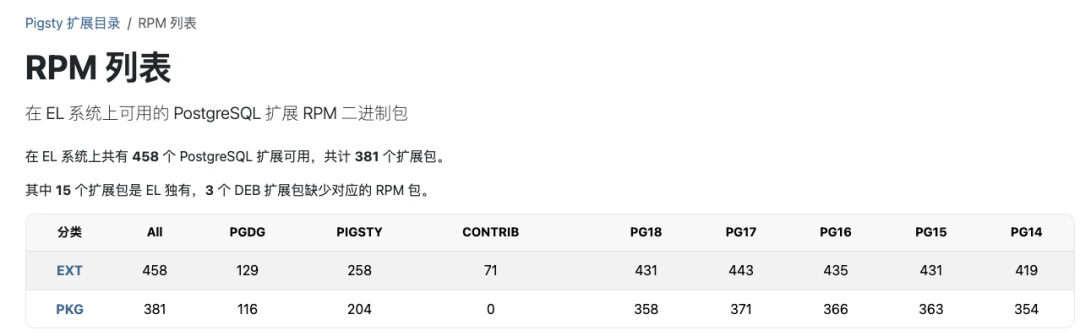
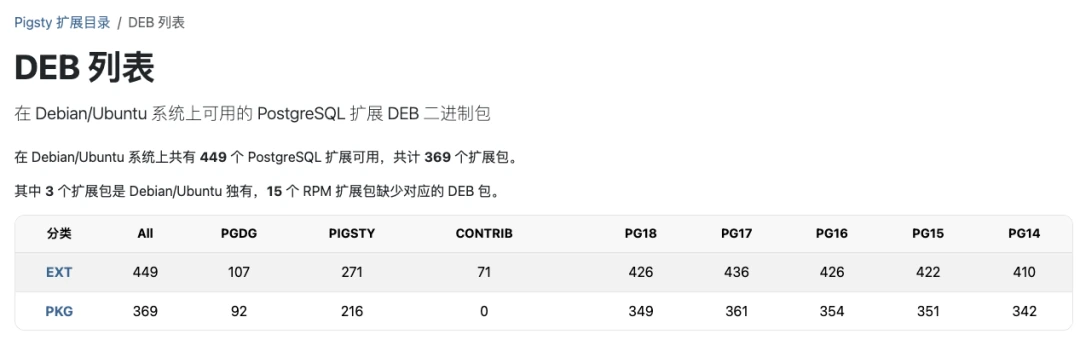
Why build this?
At a glance, this looks like a documentation site. In practice, it is infrastructure for the PostgreSQL extension ecosystem.
Too many good extensions die in obscurity because the path from “I heard this exists” to “I installed it successfully” is still too painful. That friction pushes people toward worse alternatives.
My goal is simple: come here, see what exists, pick what you want, copy one command, and use it.
How to use it
If you already know your way around PostgreSQL and just want more packages beyond PGDG, add the Pigsty APT/DNF repository:
If you want the full experience, use the Pigsty PostgreSQL distribution:
Fully open source
The website and the metadata itself are open source. If you want a copy or want to reuse the data, the source lives in pgsty/pgext.
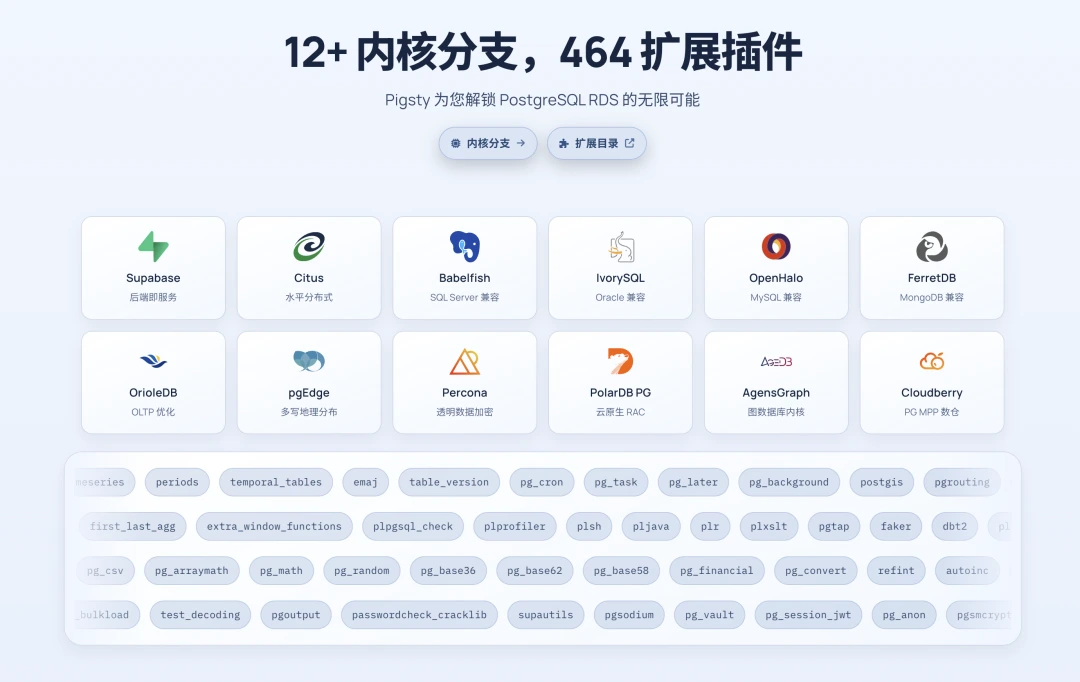
Bonus
The original post also included a related conference poster, so I kept it here as well.
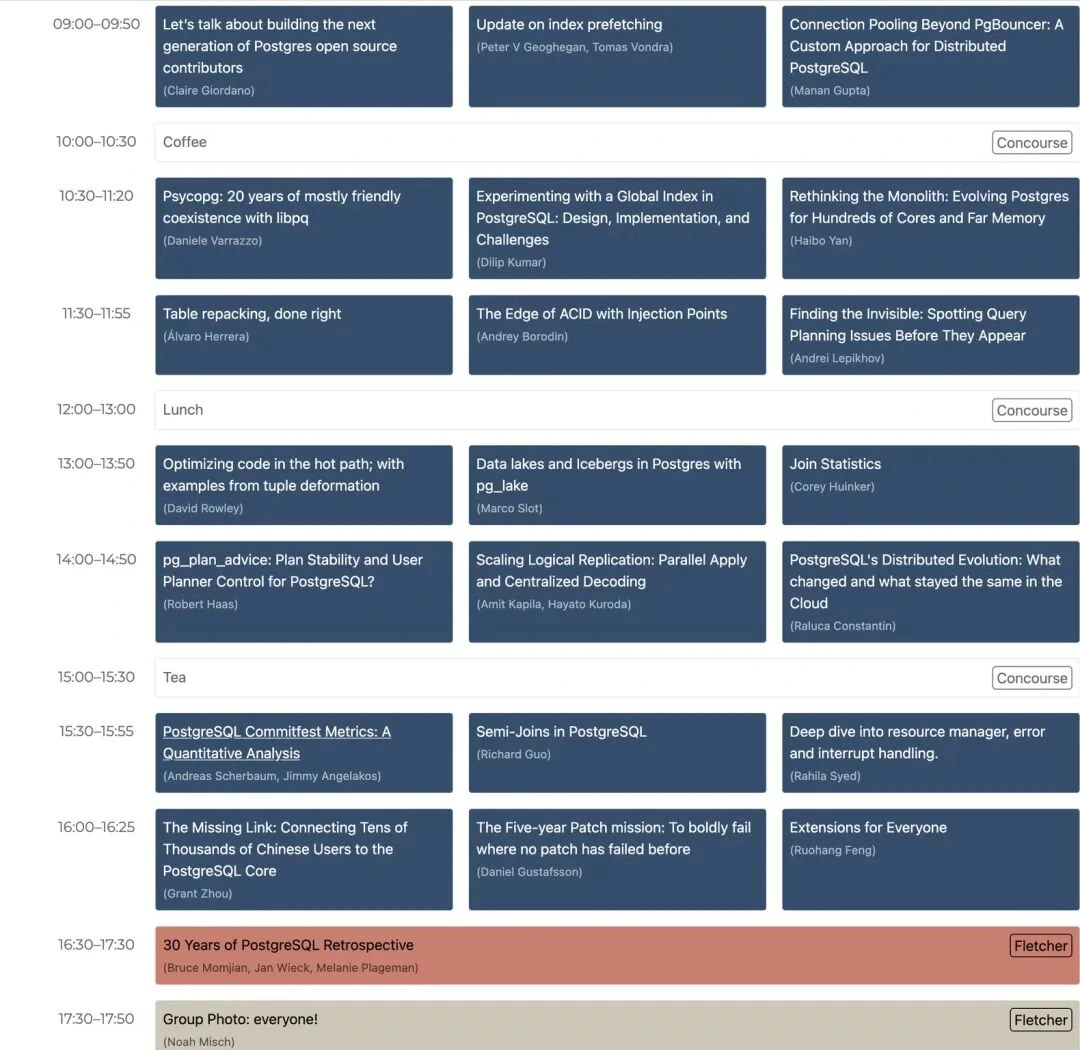
The catalog in numbers
Extensions are the soul of PostgreSQL, and this directory is an index to that soul.
Four hundred and sixty-four extensions. Sixteen categories. Fourteen operating-system and CPU-architecture combinations. Five PG major versions. Bilingual docs, metadata, package links, and install commands in one place.
Originally published in Chinese on vonng.com.
1.8 - 464 Extensions, Ready Out of the Box: The New PostgreSQL Extension Catalog
Today I put Claude Code to work on another genuinely useful project: a completely new PostgreSQL extension catalog. You can find it at pigsty.io/ext.
This is already the catalog’s fifth incarnation. After a long detour, it has returned to the Hugo + Docsy stack used by the first version and has been folded back into the main Pigsty website. That journey is a story in its own right, which I will save for later. First, let us look at what this version actually does.
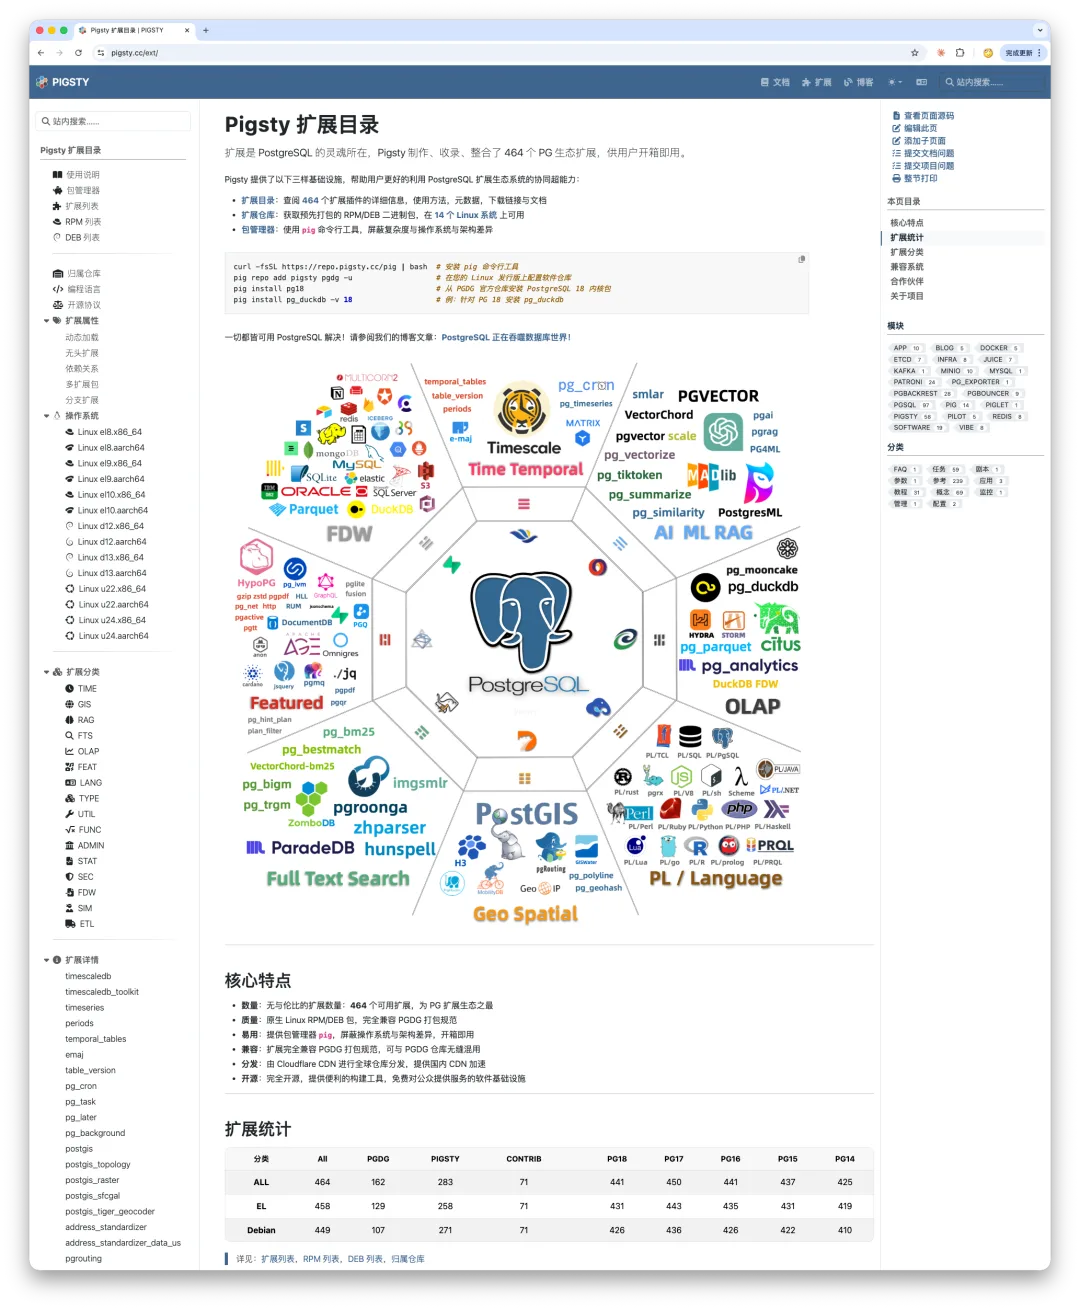
Not Just Packages, but Documentation Too
The old extension catalog answered a few basic questions: What is this extension called? Where is its metadata? Where can I download the binary packages? How do I install it with one command? Once it was installed, however, learning how to use it was your problem. Go find the documentation yourself.
This version is different. With AI’s help, we have begun systematically collecting and translating the documentation for all 464 extensions. The goal is to put the essential usage information for every extension in one place.
There are two broad cases:
For heavyweight extensions with enormous documentation sets, we will build dedicated translation sites. Citus, TimescaleDB, and PostGIS are good examples: each has enough documentation to fill a book and deserves its own treatment.
For most lightweight extensions, things are much simpler: their entire documentation set is often a single README. Take pgvector, one of the hottest vector extensions in the PostgreSQL ecosystem—its documentation fits on one page.
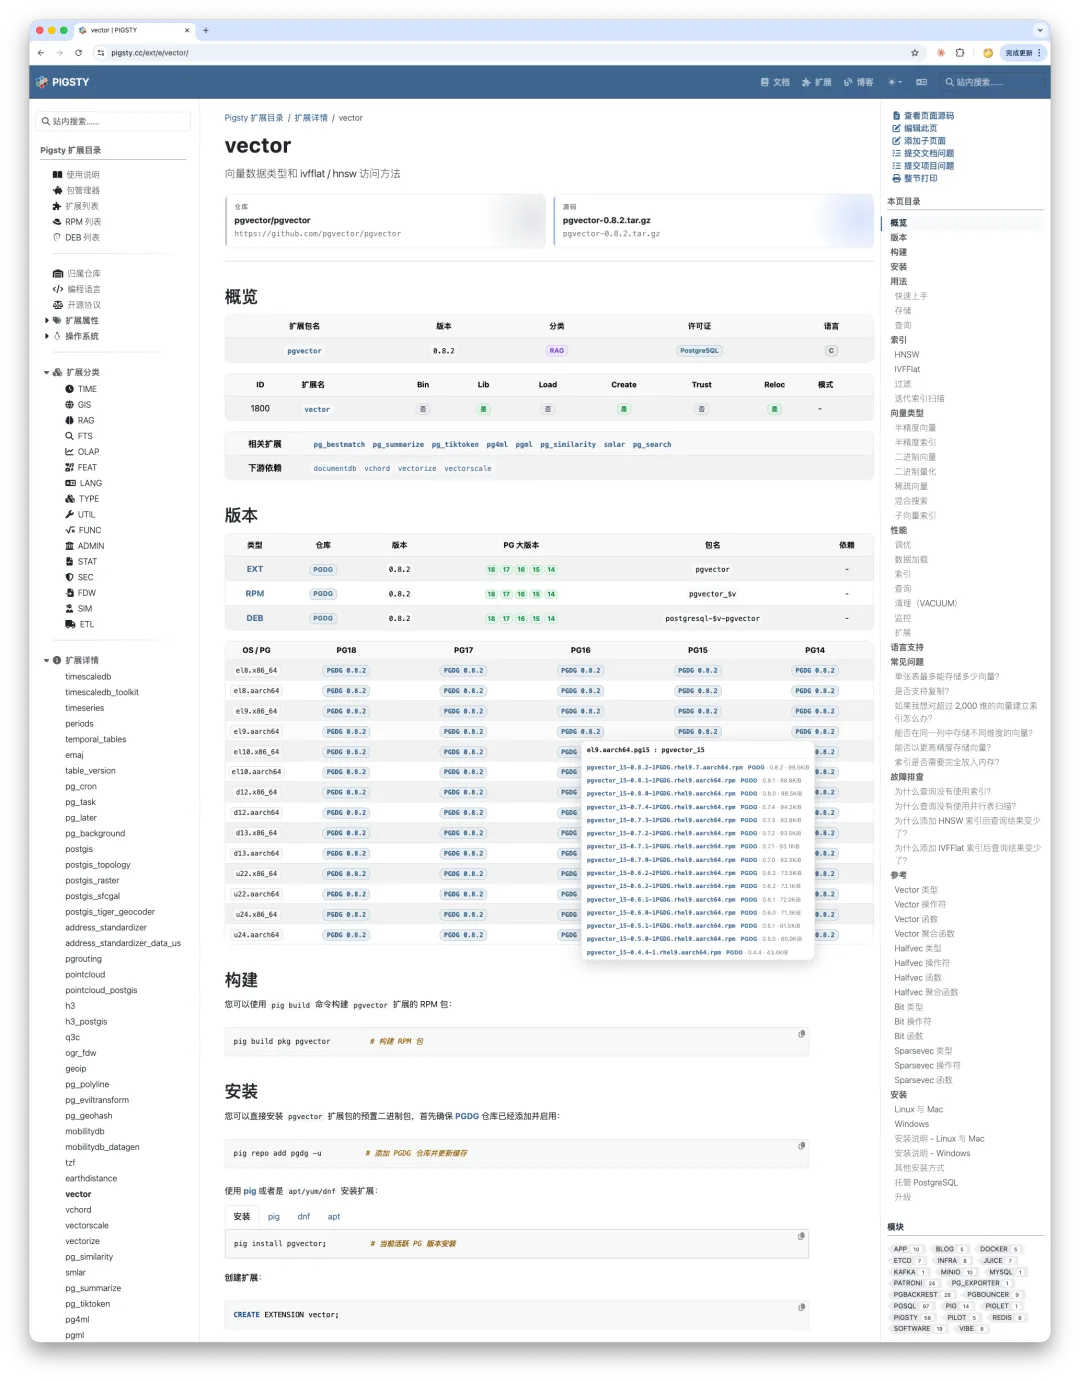
The same is true of pg_repack, an indispensable operations tool for removing table bloat online: its documentation is also a single Markdown page.
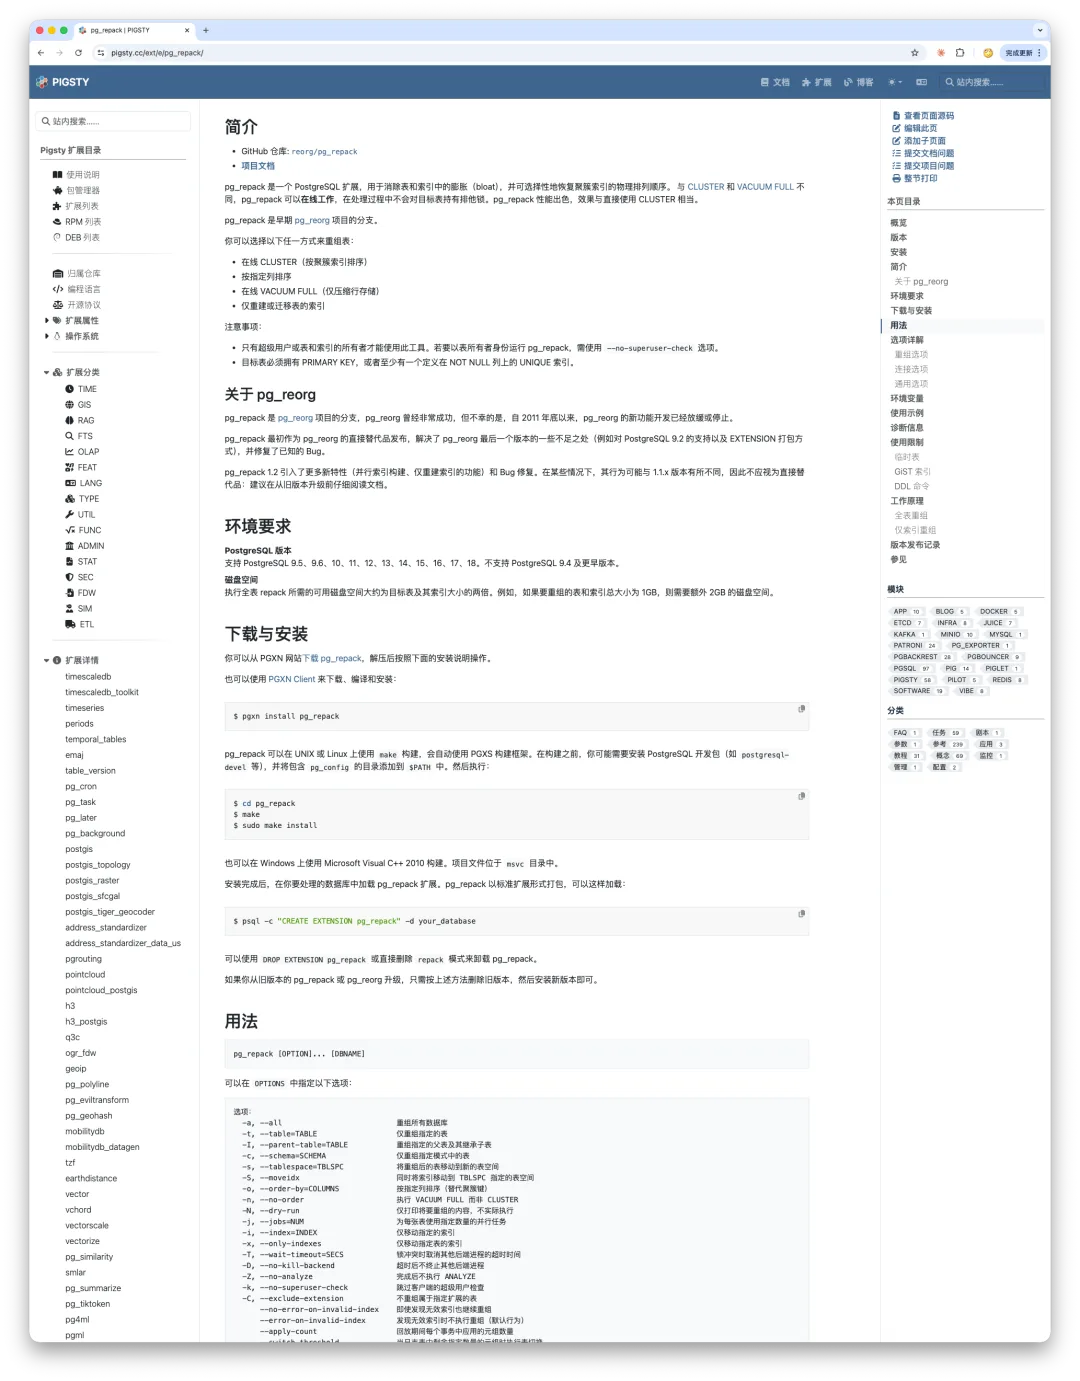
Our job is to collect all those READMEs and embed them in each extension’s detail page. Instead of bouncing between sites and digging through GitHub, you can consult the core documentation for every extension in one central place. For exceptionally large extensions, we will aggregate their information and indexes so that the catalog still provides an authoritative, dependable starting point.
The Chinese Pigsty site has already translated the documentation for PgBouncer, pgBackRest, and Patroni. We will gradually work through and maintain the rest—including PostgreSQL itself.
Translating the PostgreSQL Ecosystem’s Three Core Components in a Day
That is part of the larger vision: to become a dependable source of essential information for the PostgreSQL ecosystem.
To be honest, whenever I finish my “real work” with AI tokens left to burn, I spend them filling gaps like these. It is a useful backstop—and a little public service while I am at it.
Friendly to Agents and Humans Alike
Now let us look at how the catalog is designed.
Although the technology stack has come full circle to Hugo + Docsy, Claude Code makes it possible to build an excellent experience on a purely static site. I followed one core design principle: make it friendly to both AI agents and human readers.
Being agent-friendly means that the site’s source is public, written in Markdown, and subject to one hard rule: keep the noise down. Markdown should not be buried under raw HTML, shortcodes, or formatting clutter, all of which make the content harder for agents to parse and read.
Being human-friendly means organizing information into clear, attractive visual forms so that readers can spot issues quickly and focus on what matters.
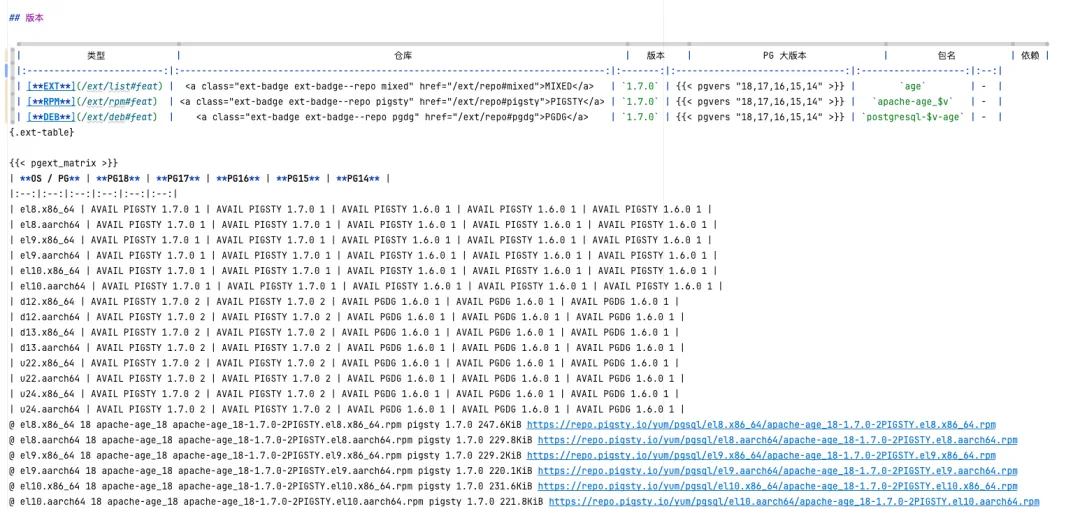
Here is one concrete example. In this version, we tried something genuinely useful: combining every extension into one large matrix. For each combination of PostgreSQL version and operating system, a cell tells you how many packages are available and which repository they come from. Click it, and you can download them directly.
Yet I did not build this with a maze of complex HTML. The source remains standard Markdown, wrapped only in a shortcode that performs the necessary transformation during the Hugo build. Custom CSS then turns the result into a polished presentation.
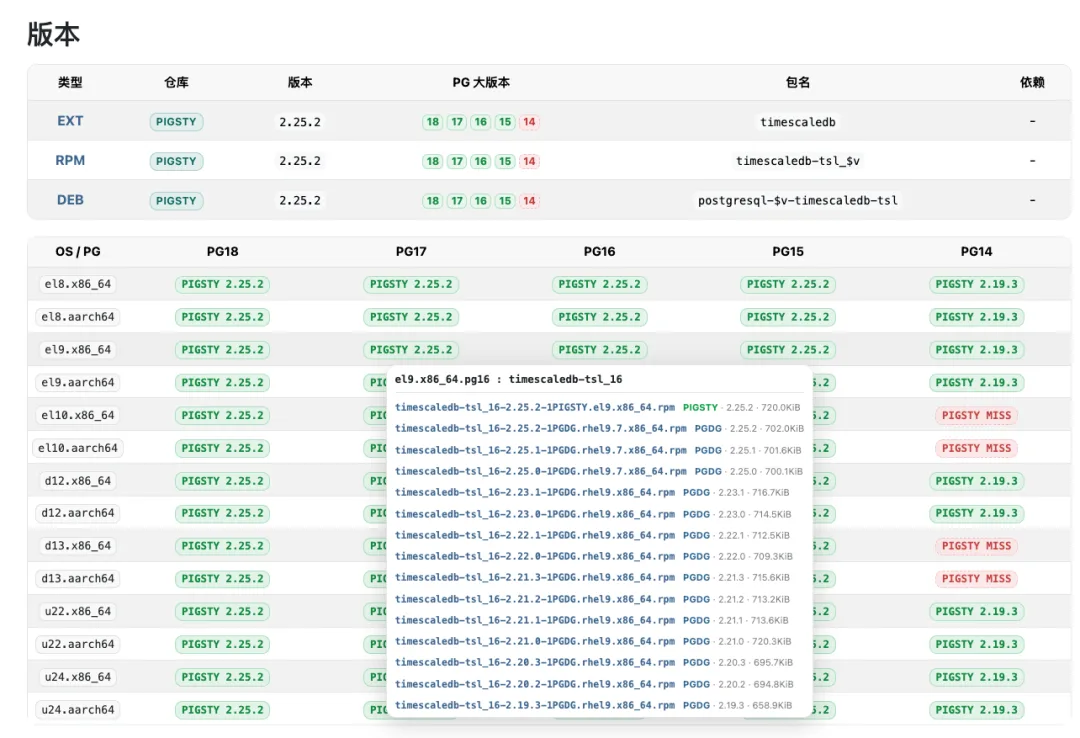
We also added a series of categorized indexes that expose extension metadata from different angles, making extensions much easier to find. Site search is considerably better than it was in earlier versions as well.
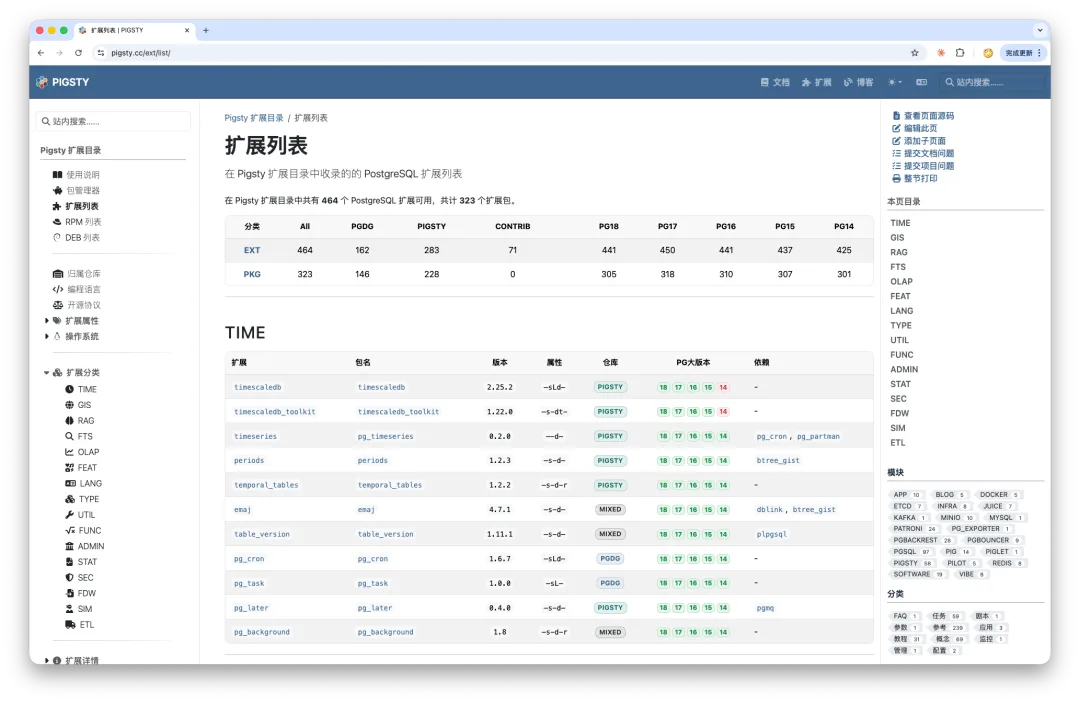
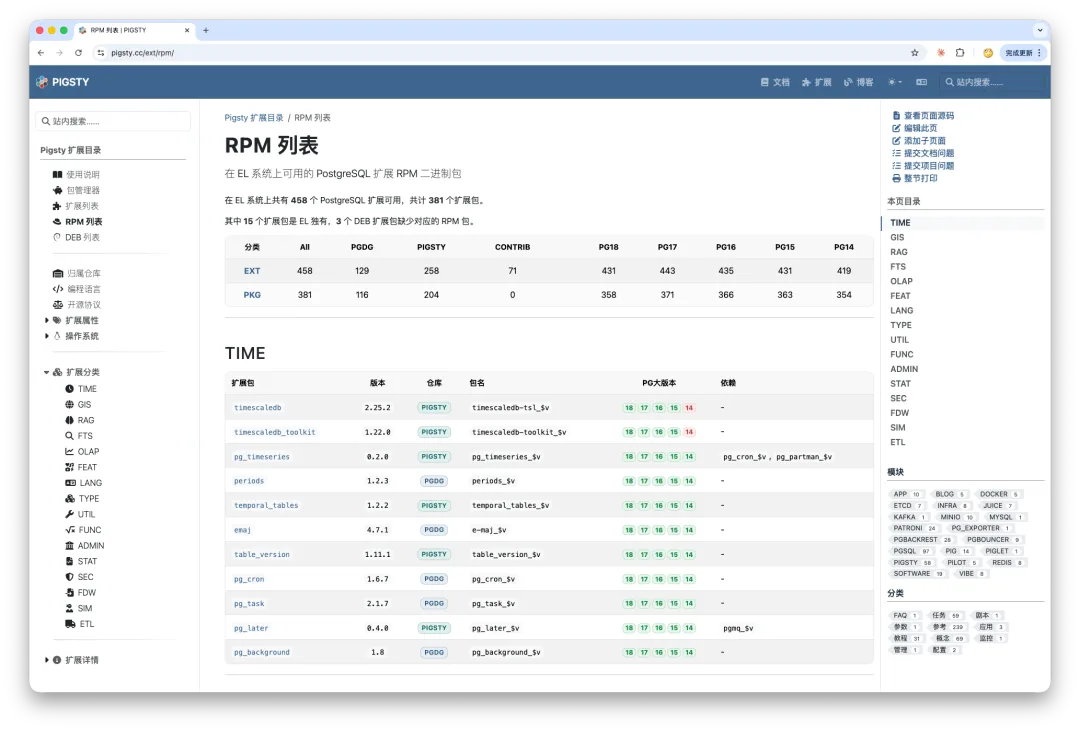
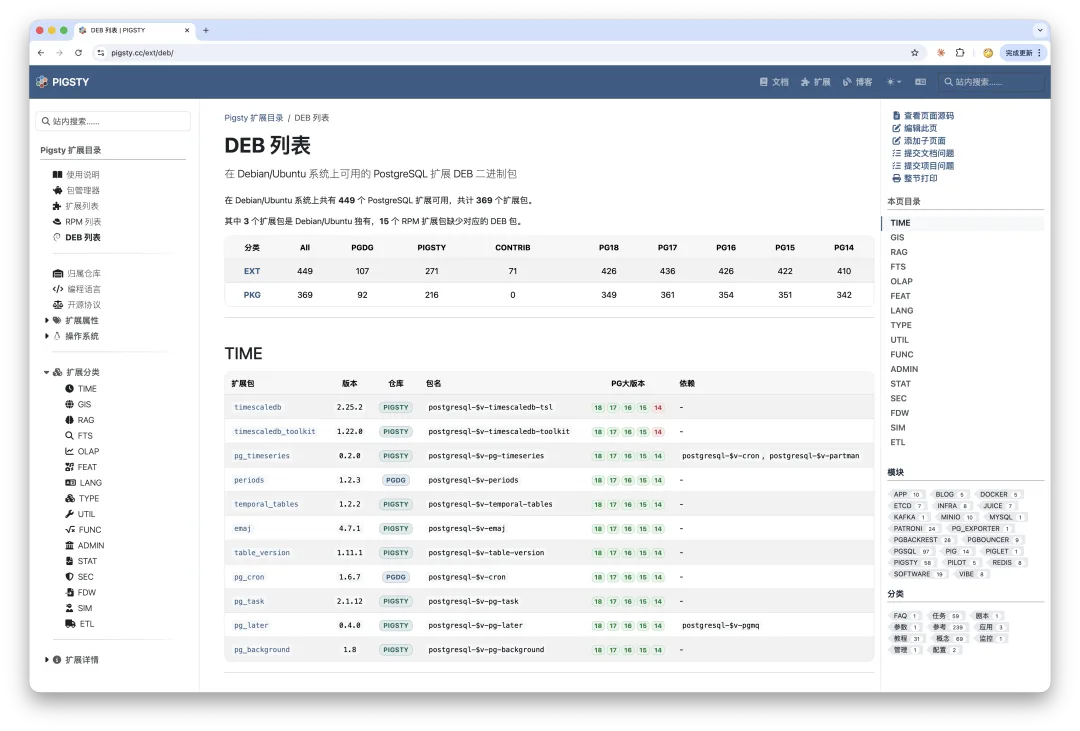
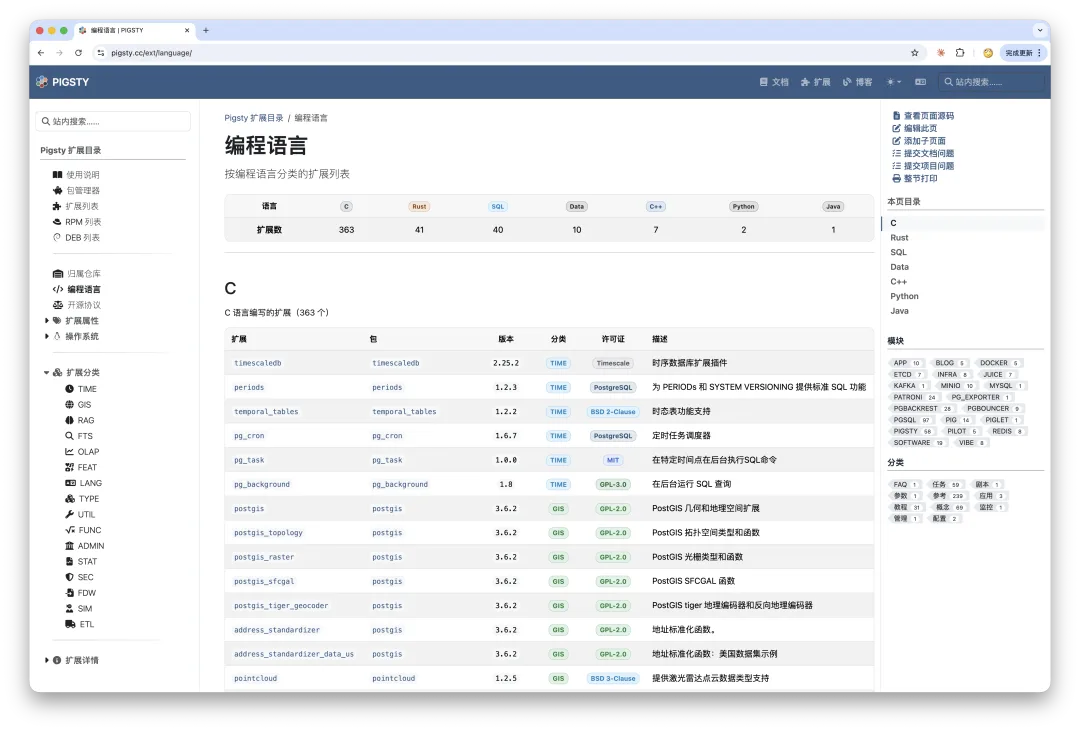
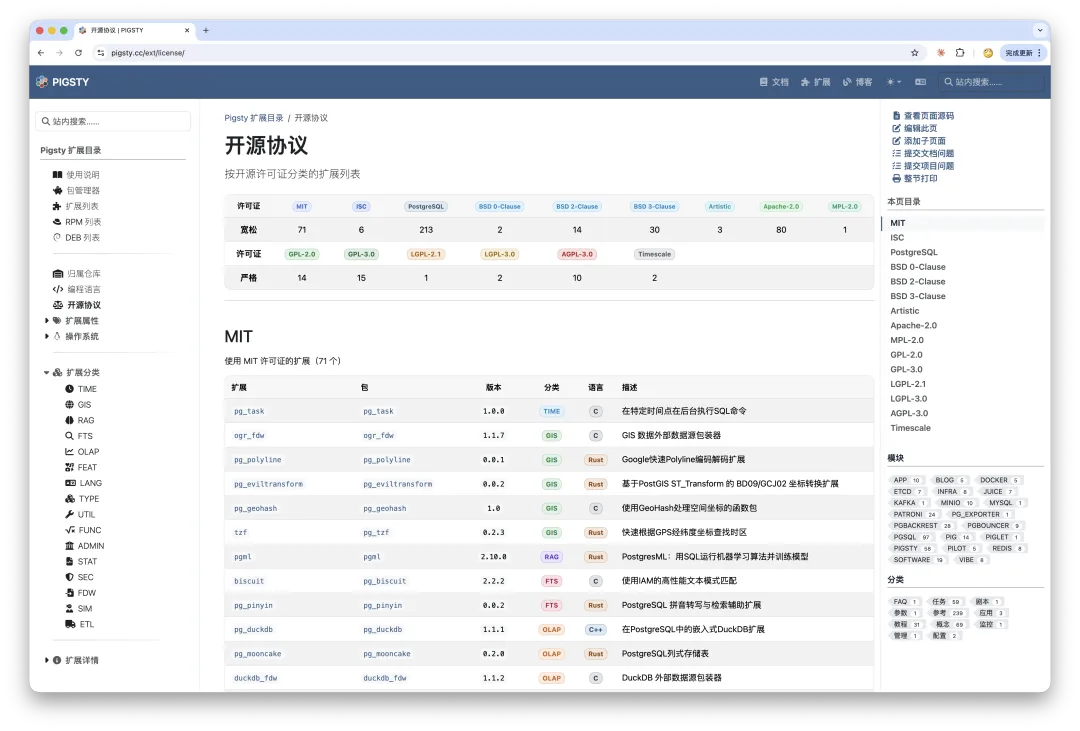
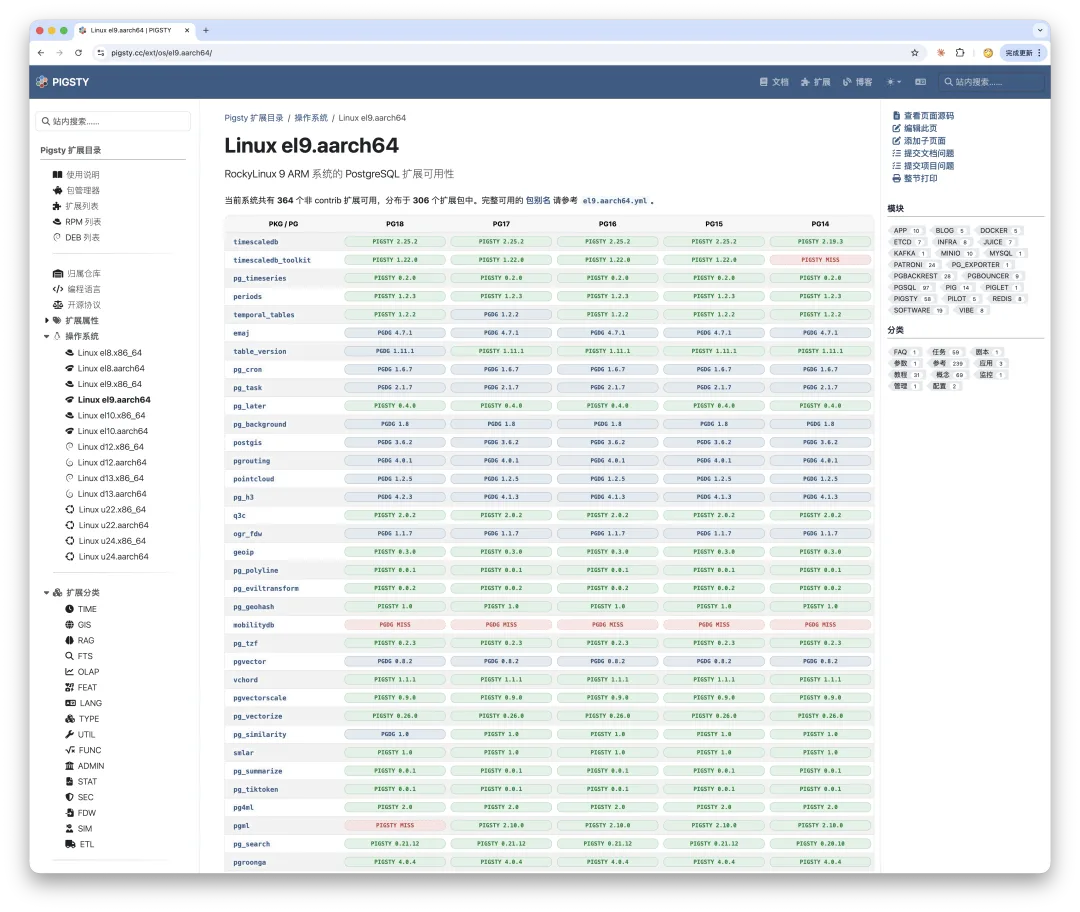
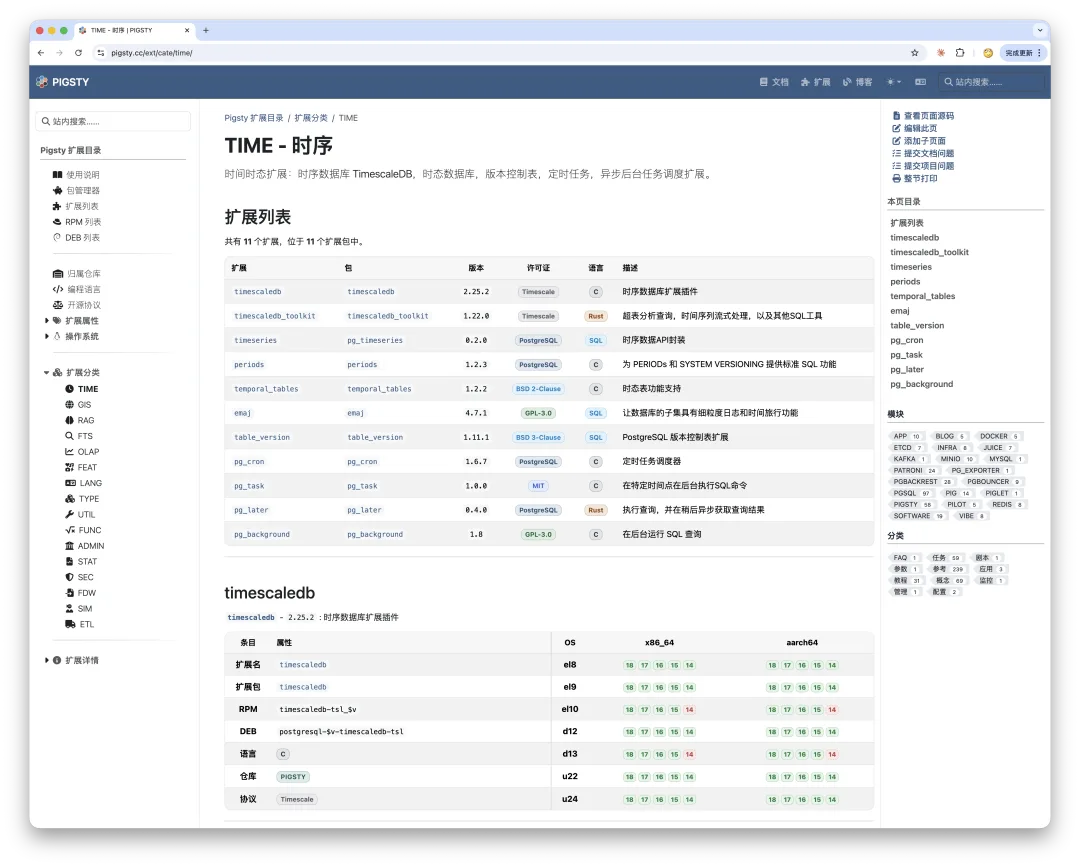
This time, we also included extensions that exist only in particular PostgreSQL forks:
Five Versions, Back Where We Started
There is one last topic—less technical, but more personal: choosing a documentation framework.
The extension catalog has gone through five versions:
- Hugo + Docsy—the original version, integrated into the main Pigsty site
- Docsify
- Next.js
- Hugo + Hextra—the standalone pgext.cloud site
- Hugo + Docsy—the current version, back on the main Pigsty site
The standalone pgext.cloud site lacked a Chinese ICP filing and was hosted on Cloudflare. Some users in mainland China reported unreliable access and suspected that it was blocked. After weighing the options, I decided it was better to use a registered domain and keep things straightforward.
The first version: Hugo + Docsy, just like this one.
The second version: Docsify.
A Piglet Riding an Elephant: PIG, the Package Manager for PostgreSQL and Its Extensions
The third version: Next.js + Fumadocs.
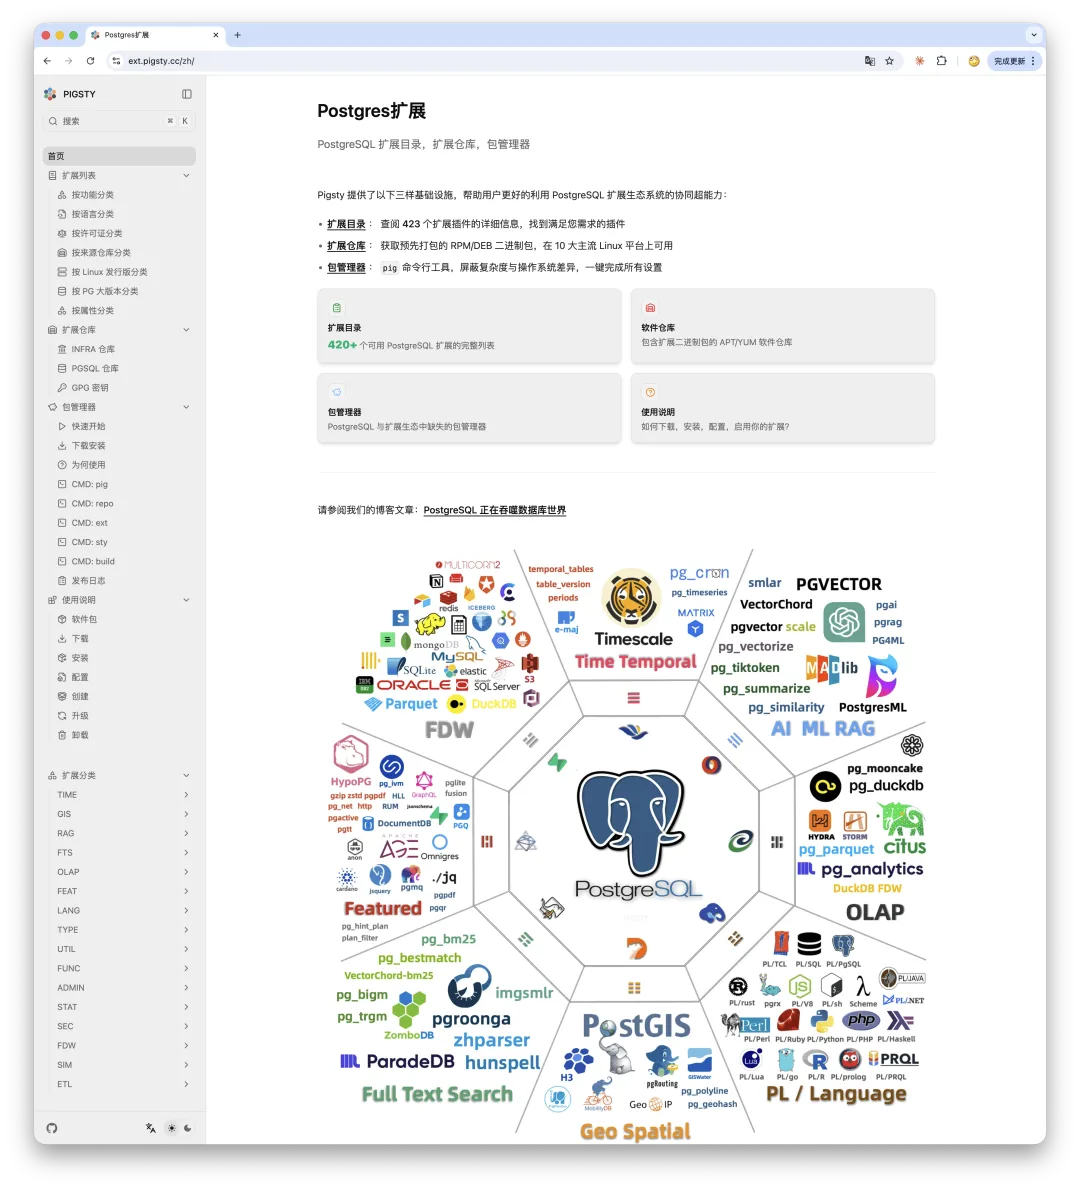
A Database Veteran Ventures into the Modern Frontend Jungle (Chinese original)
Eventually, I got tired of all the hassles that come with dynamic sites and returned to a static one.
The fourth version: Hugo + Hextra.
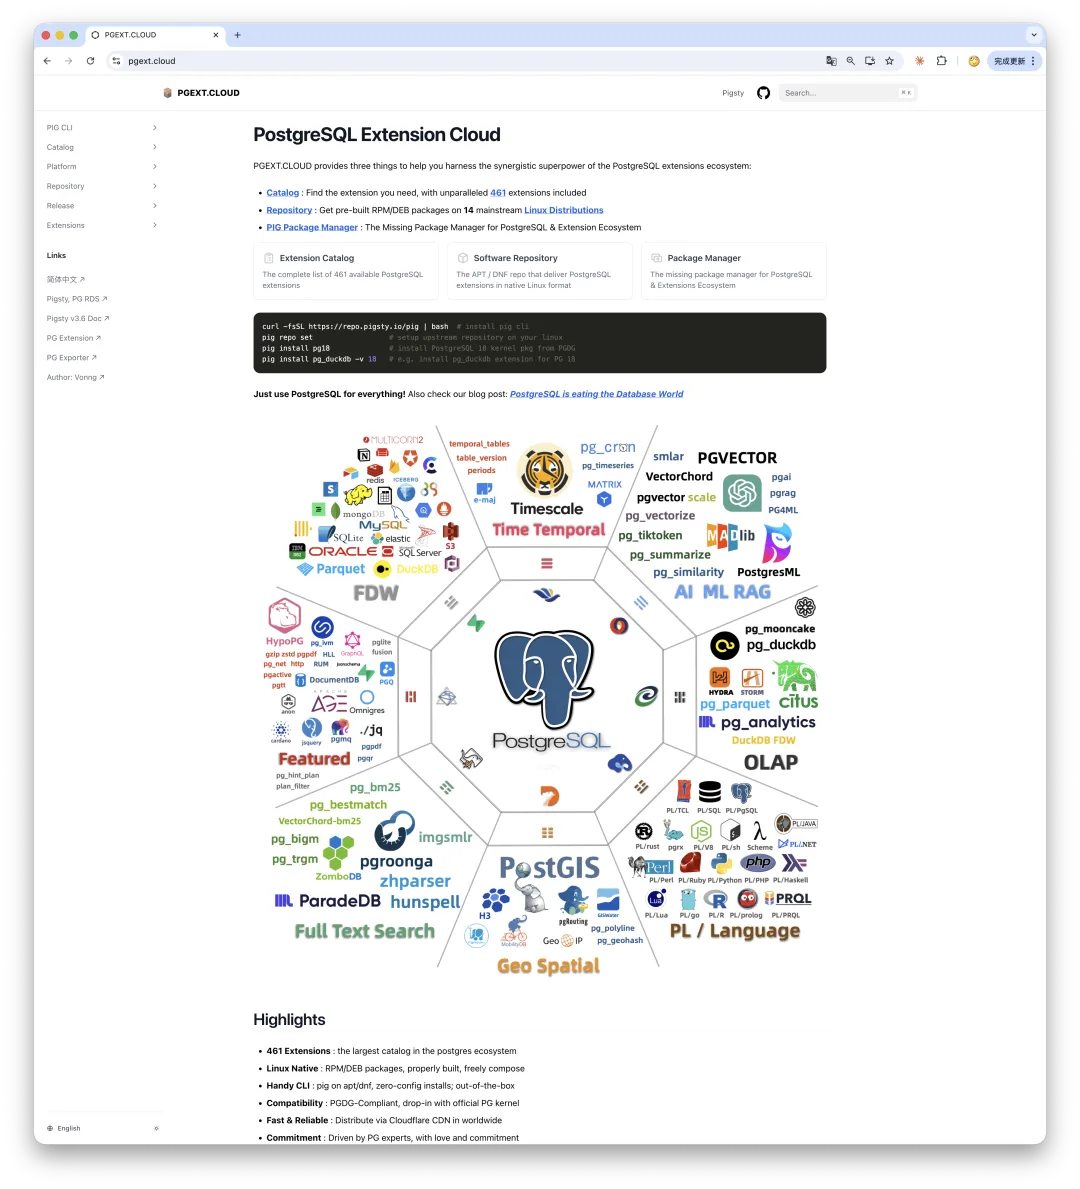
PG Extension Cloud: Unlock the Complete PostgreSQL Experience, Free and Without a VPN
Hextra is another lightweight theme in the same vein as Fumadocs. I like it a great deal. It is excellent for small projects, such as book translations, but starts to show its limits on a large documentation site. I still gladly use it for my books, tutorials, and smaller projects.
The fifth version: Hugo + Docsy.
The conclusion is simple:
If you are building a static documentation site, just use Hugo. Docsy is a Google-backed theme used by the Kubernetes and etcd documentation sites. Its fundamentals are solid, its search works well, its structure is clear, and it remains actively maintained. For a lightweight project, use Hextra; for a heavyweight one, use Docsy. If you need a content-rich dynamic site, Next.js is worth considering, but it can indeed be rather heavy.
I have used Hugo for nearly a decade, and it has never let me down. After trying so many new things, I discovered that the framework I chose six or seven years earlier was still the best fit. That seems to prove an old lesson: solid, boring technology is often the best technology. A website’s value does not come from how flashy it looks, but from whether the information inside it is worth reading. Content is still king.
Would the time spent on all this experimentation have been better used making video tutorials or writing hands-on case studies? Perhaps. But after making the full circuit, I now understand the available options, their trade-offs, and their limits—and I have sharpened my own web-design skills and taste along the way. That is valuable in itself.
Who can say for sure? Tinkering is half the fun.
Originally published in Chinese on vonng.com.
1.9 - Forging a China-Rooted, Global PostgreSQL Distro
Hi, I’m Feng Ruohang, author of Pigsty and an independent open-source contributor. Let’s talk about how to build a PostgreSQL distribution that is rooted in China and useful to the whole world.
The question isn’t whether PG will win—it already has. The question is: What role do we play in that victory? Spectator or protagonist? Follower or leader?
Why now
PostgreSQL is the default database
Stack Overflow’s 2025 survey shows 58.2% of professional developers use PG—18.6 points ahead of MySQL, and the gap is widening. New SaaS, AI startups, even OpenAI default to PG. DB-Engines rankings and JetBrains surveys tell the same story.
Capital agrees: in 2025 Databricks bought Neon (~$1 B) and Snowflake bought Crunchy Data ($250 M). AWS Aurora DSQL, Azure HorizonDB, GCP AlloyDB—all PG. Technology won, money followed.
China is missing from the PG narrative
Despite hundreds of domestic “PG-derived” products, our presence in the global ecosystem is faint. Until recently there wasn’t a single Chinese committer on the PG core list. The most visible Chinese-led PG project by GitHub stars is… Pigsty, a one-man project. That’s both flattering and a little sad.
At PG conferences I’ve met only a handful of Chinese developers. We’re spectators at our own victory parade.
What must change
The kernel wars are over; the fight shifts to distributions. Whoever controls the distro controls the experience—like Ubuntu did for Linux. We need a PG “Ubuntu” built with China’s strengths but serving global developers, the way DeepSeek did in AI.
Pigsty as a case study
Pigsty started at Tantan (China’s #2 dating app). We were dealing with 2.5 M global QPS, PL/pgSQL-heavy business logic, hundreds of physical clusters. Off-the-shelf tooling couldn’t cope, so we built our own HA, backups, monitoring, IaC. China’s scale was the forge. If it survives Tantan, it’s overkill everywhere else.
But “rooted in China” isn’t enough; “facing the world” means becoming part of the global supply chain. That requires obsessing over developer experience, not just DBA comfort.
In 2023 Pigsty already did HA + backups + observability + bare-metal delivery. Yet something was missing—features. PG’s true power is extensions. MySQL spends years grafting on vectors; PG’s community ships pgvector and kneecaps an entire market in months.
So I built an extension repository. I waited for others to do it, nobody did, so I compiled them myself: first a dozen, then dozens, then hundreds. Today Pigsty provides 437 extensions across EL9/EL8/Debian/Ubuntu, more than the official PGDG repos. That makes Pigsty part of the upstream supply chain: when developers apt install an extension, they’re using binaries built in China yet serving users worldwide.
Vision
- Rooted in China: leverage our scale, scenarios, and demand to harden solutions under extreme stress.
- Facing the world: ship battle-tested, developer-friendly distros and extension repos that anyone can consume, just like they consume Debian packages.
- Play to our strengths: we may not have a kernel committer yet, but we can dominate tooling, packaging, automation, and integrations—the layers that actually reach users.
Pigsty isn’t the only answer, but it proves a point: a single Chinese engineer, working the right problem, can earn a seat at PostgreSQL’s global table. Imagine what we could do together.
Originally published on vonng.com.
1.10 - On Trusting Open-Source Supply Chains
My earlier post “PG ‘Export Controls’ and Supply-Chain Trust” drew a comment from an administrator at Tsinghua University’s TUNA mirror:
“As a university mirror admin, calling us ‘lying flat’ or ‘irresponsible’ is unfair and demoralizing.”
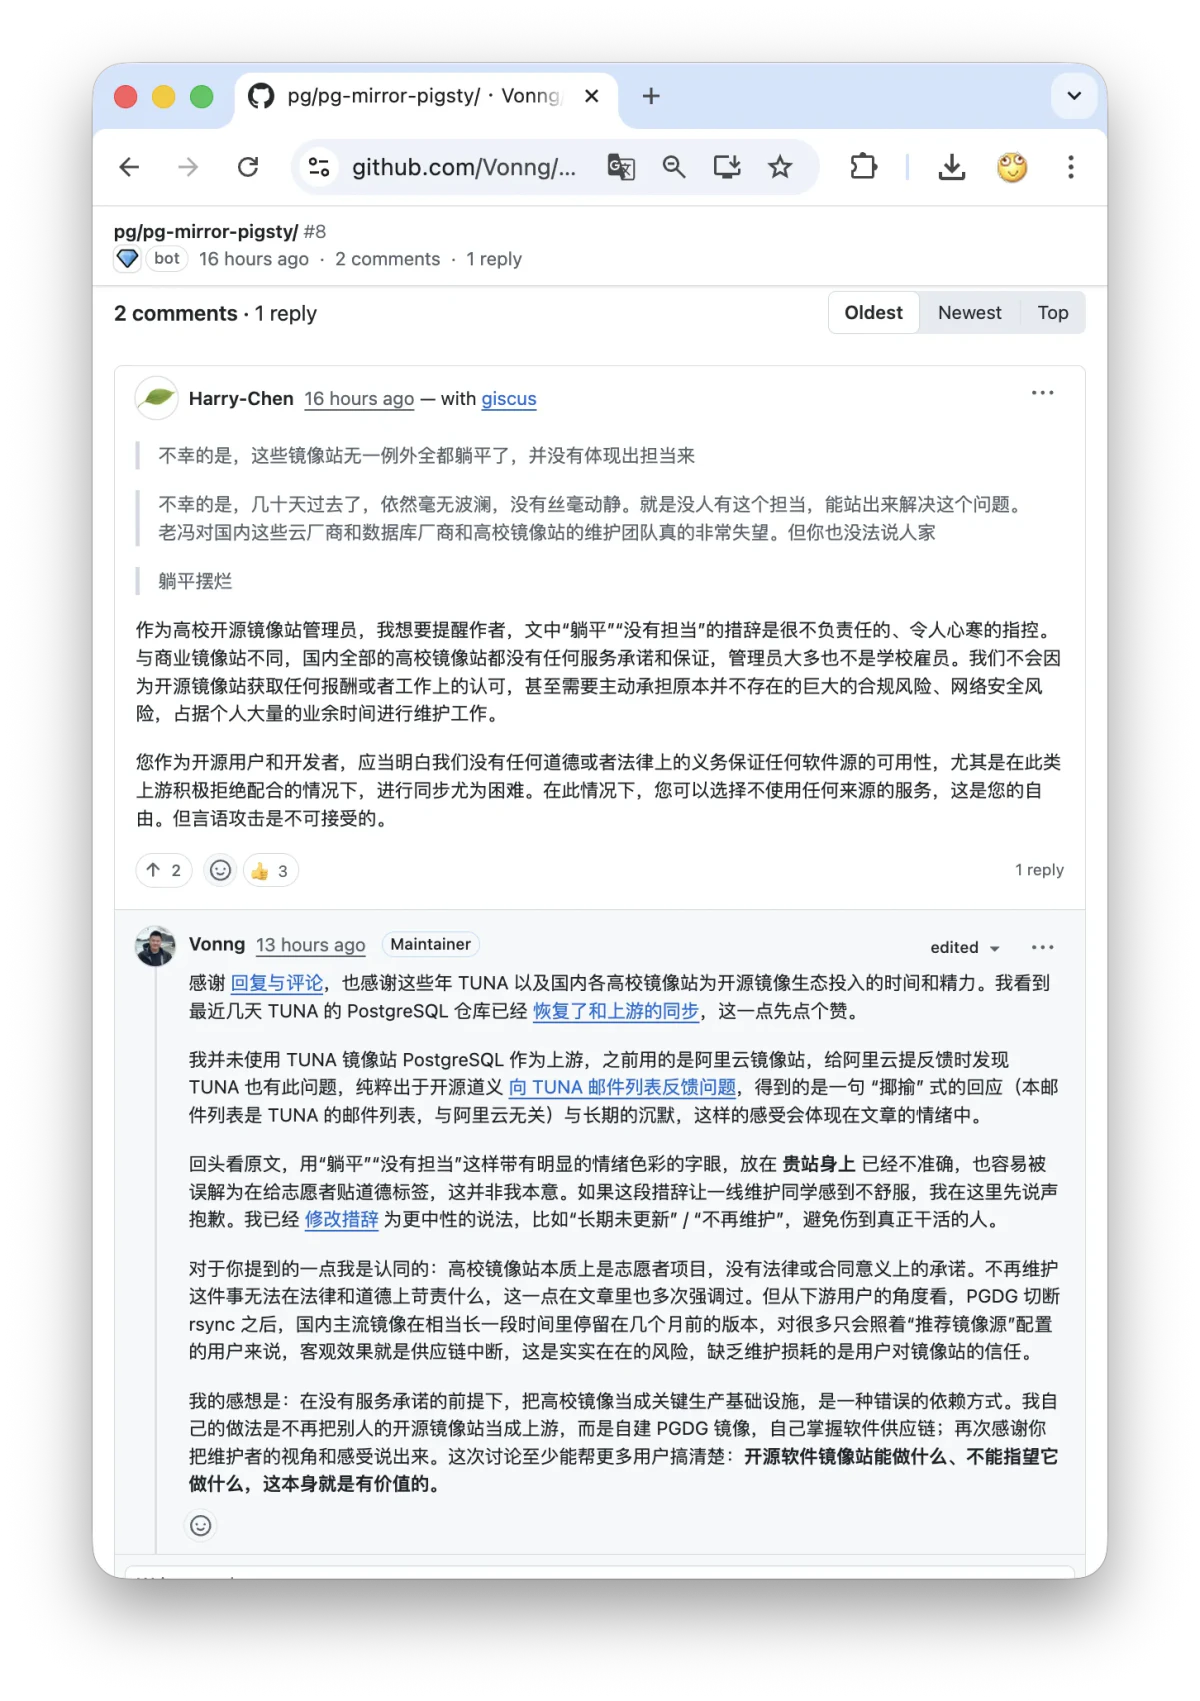
I replied:
Thanks for the feedback, and for the time and work that TUNA and other university mirrors have contributed over the years. I see that TUNA’s PostgreSQL repository has resumed synchronization, which is good news.
When I first found the problem, I was using Alibaba Cloud’s PostgreSQL mirror. I later noticed the same problem at TUNA and reported it on the mailing list. The reply said that the list belonged to TUNA, not Alibaba Cloud. After I clarified the report, I heard nothing further. That experience affected the tone of my article.
Looking back, “lying flat” and “irresponsible” were too emotional, especially when applied to your team. They could read as moral judgments on volunteers, which was not my intention. I apologize for that wording. I have replaced it with descriptions such as “not updated for a long time” and “no longer maintained.”
I agree that university mirrors are volunteer projects without contractual service commitments. But downstream users still face a real problem: after PGDG cut off rsync, major mirrors in China remained months out of date. Users following instructions to use a recommended mirror experienced a supply-chain interruption. That damages trust.
My conclusion is that treating a volunteer mirror as critical production infrastructure, without a service commitment, is a mistake. I now host my own PGDG mirror and control that part of my supply chain. Thank you for explaining the maintainer’s perspective. Helping users understand what they can expect from mirrors is valuable in itself.
My reflections
After receiving the comment, I checked TUNA again. PostgreSQL 18 packages were available, although “Last Update” still showed May 16, 2025. That suggested a manual sync. Besides the Pigsty repository, China had another node providing reasonably current PGDG packages. Credit to TUNA for restoring it.
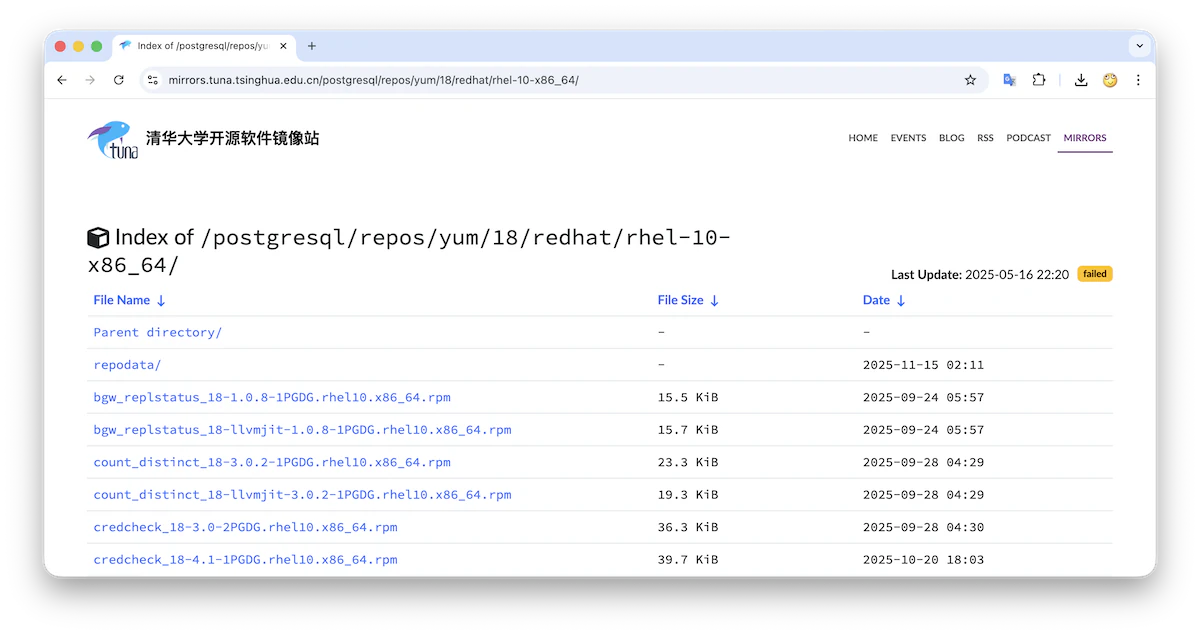
When this outage began, Pigsty used Alibaba Cloud’s PostgreSQL mirror. My criticism was aimed mainly at a large company with substantial resources — familiar territory for my Cloud Mudslide articles. Alibaba Cloud benefits heavily from open source, yet left its PostgreSQL mirror stale. It was the TUNA volunteers who responded, and I understand why they objected.
I do not think that providing a free mirror obliges either group to maintain it forever. But users will still judge the result. My frustration was real; applying it to university volunteers in those terms was unfair. I changed the wording to describe the maintenance problem itself.
When I found the global mirror synchronization problem, I emailed Alibaba Cloud. I also checked other mirrors and reported the same problem to TUNA. My message contained TUNA URLs whose labels still said “ALIYUN,” which prompted the reply about the wrong mailing list. I corrected that mistake and explained the shared upstream problem. There was no further reply until this November discussion.
After waiting about another month, I set up a PGDG mirror for China on Tencent Cloud, alongside Pigsty’s own repository. I removed Alibaba Cloud’s PostgreSQL mirror from Pigsty’s dependencies and took control of PostgreSQL package distribution. Without this interruption, I probably would not have done it so soon.
I am often blunt with cloud vendors. That does not mean I dismiss the difficulties volunteers face. University maintainers deserve more support and fewer moral accusations. That is why I changed my wording.
Open source and trust
I recently experienced the same problem from the maintainer’s side. I maintain several open-source projects, including pg_exporter, a Prometheus exporter used by some PostgreSQL vendors.
On November 20, I noticed a comment on an issue opened in September. In October, the user had explained that two issues had gone unanswered for a month. They had been excited about version 1.0 and considered contributing, but the lack of response had changed their mind:
“I am not willing to bet on a project with a maintainer who is absent.”
They hoped my absence was temporary and wished both me and the project well.
I had spent September driving around Xinjiang and barely used a computer. I had opened the issues, then forgotten about them. My lack of attention cost the project a user’s trust, and perhaps a future contributor. I regretted letting them down. I put other work aside, addressed the reported problems, and released version 1.0.3.
When an upstream mirror stops working and a report receives neither a response nor a fix, I feel the same way that user did. I do not want to depend on a project whose maintainer appears absent.
The software supply chain
In “PG ‘Export Controls’ and Supply-Chain Trust,” I argued that publishing source code is only one way to build trust. Continued effort, dependable delivery, and a willingness to address problems matter too.
I understand the mirror administrator’s frustration. They receive no pay, spend their own time maintaining the service, and take on security and compliance responsibilities. Being called irresponsible is a poor reward for that work.
There is an uncomfortable gap between the two perspectives. A maintainer can reasonably say, “I am not paid, and I have made no commitment.” A user sees a public service and starts to treat it as dependable infrastructure. That expectation may be unreasonable, but it exists.
A mirror also occupies a specific place in the supply chain. It carries software from upstream to downstream, so stale packages can directly affect production systems. Providers differ in reliability, in whether they offer an SLA, and in whether they accept responsibility when something fails.
Consistent maintenance and clear expectations build trust. Stale or unreliable results erode it. The TUNA administrator’s statement that university mirrors make no service guarantees is honest. It also tells a production operator where that service’s limits are.
My point is that a production supply chain should not depend on an upstream service that explicitly makes no commitment to its availability.
Quality and commitments
TUNA provides useful services. I use its PyPI and Homebrew mirrors on my own computer to speed up downloads. Early versions of Pigsty also used some of TUNA’s PostgreSQL mirrors. After several unexpected HTTP 403 failures disrupted automated deployments, I switched to Alibaba Cloud.
Alibaba Cloud’s mirror was generally reliable until PGDG stopped rsync access. Its PostgreSQL packages then remained months out of date. That reduced my trust, so I took over the PGDG mirror myself. At the time of writing, I still use Alibaba Cloud for operating-system packages. If those mirrors repeatedly fail, I may also host Rocky Linux, Ubuntu, and Debian mirrors.
The choices follow from the commitments each party makes:
- TUNA says university mirrors offer no service commitment. Downstream users can choose their use cases accordingly.
- Alibaba Cloud has not made that point explicit. I judge its service by its record. If it keeps failing, I will report the problems, criticize the service, or replace it.
- For my Pigsty and PGDG APT/DNF repositories, I make a commitment: if they break, I will fix them. Failure damages my reputation; for paying customers, it also means failing an SLA.
Mirrors, repositories, and distributions support the rest of our infrastructure. Accepting responsibility for their operation is part of becoming a supplier that others can rely on.
When an upstream says, “Don’t count on me,” my response is, “Then I’ll take responsibility for it myself.”
A word from our sponsor
I rarely pass up a chance to mention my own work. These three public repositories may be useful to you. They have global endpoints behind Cloudflare and separate endpoints in China, and can be configured through PIG, APT, or DNF. See the repository documentation for current addresses and setup instructions.
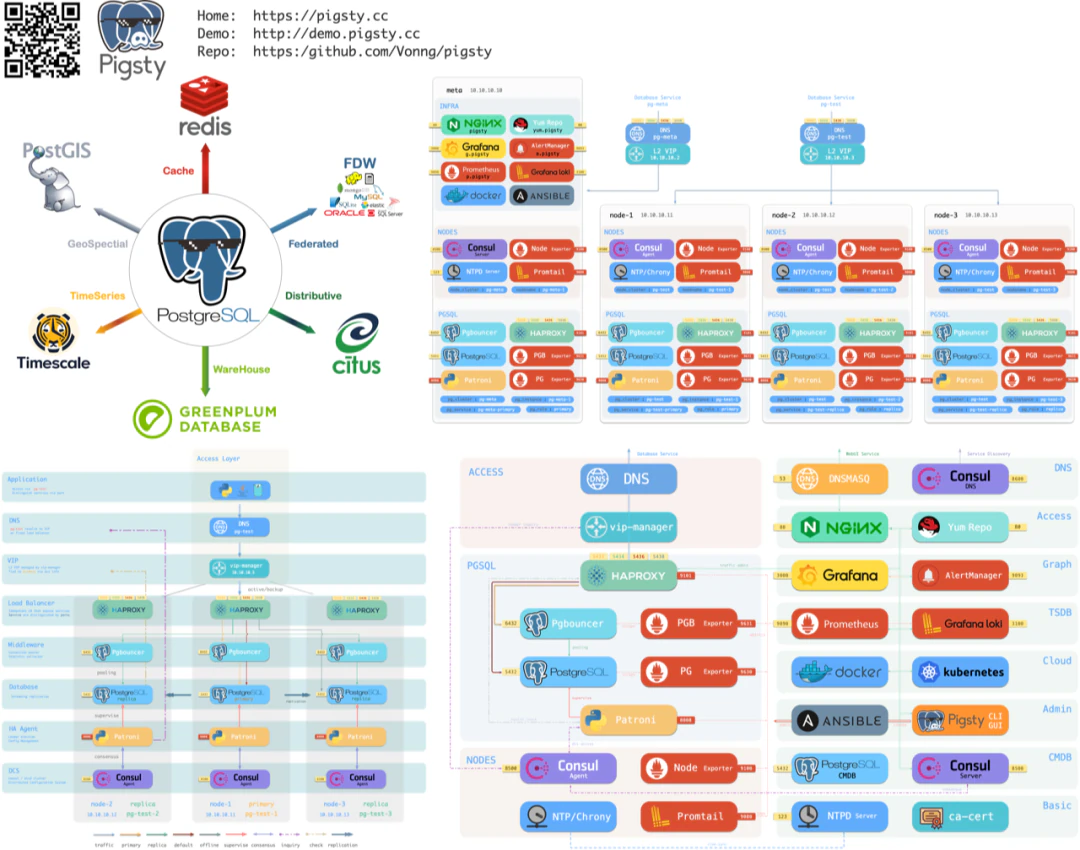
PGDG mirror
The mirror copies the PostgreSQL Global Development Group’s packages for EL 7–10, Debian 11–13, and Ubuntu 20.04–24.04. On November 22, 2025, it had just completed a sync and was being updated weekly.
PIGSTY PGSQL
This repository supplements PGDG with PostgreSQL variants, including PolarDB, IvorySQL, Babelfish, OrioleDB, OpenHaloDB, Percona TDE, and Supabase. At the time of writing, it provided 437 PostgreSQL extensions and ecosystem tools across 14 Linux distribution major versions.
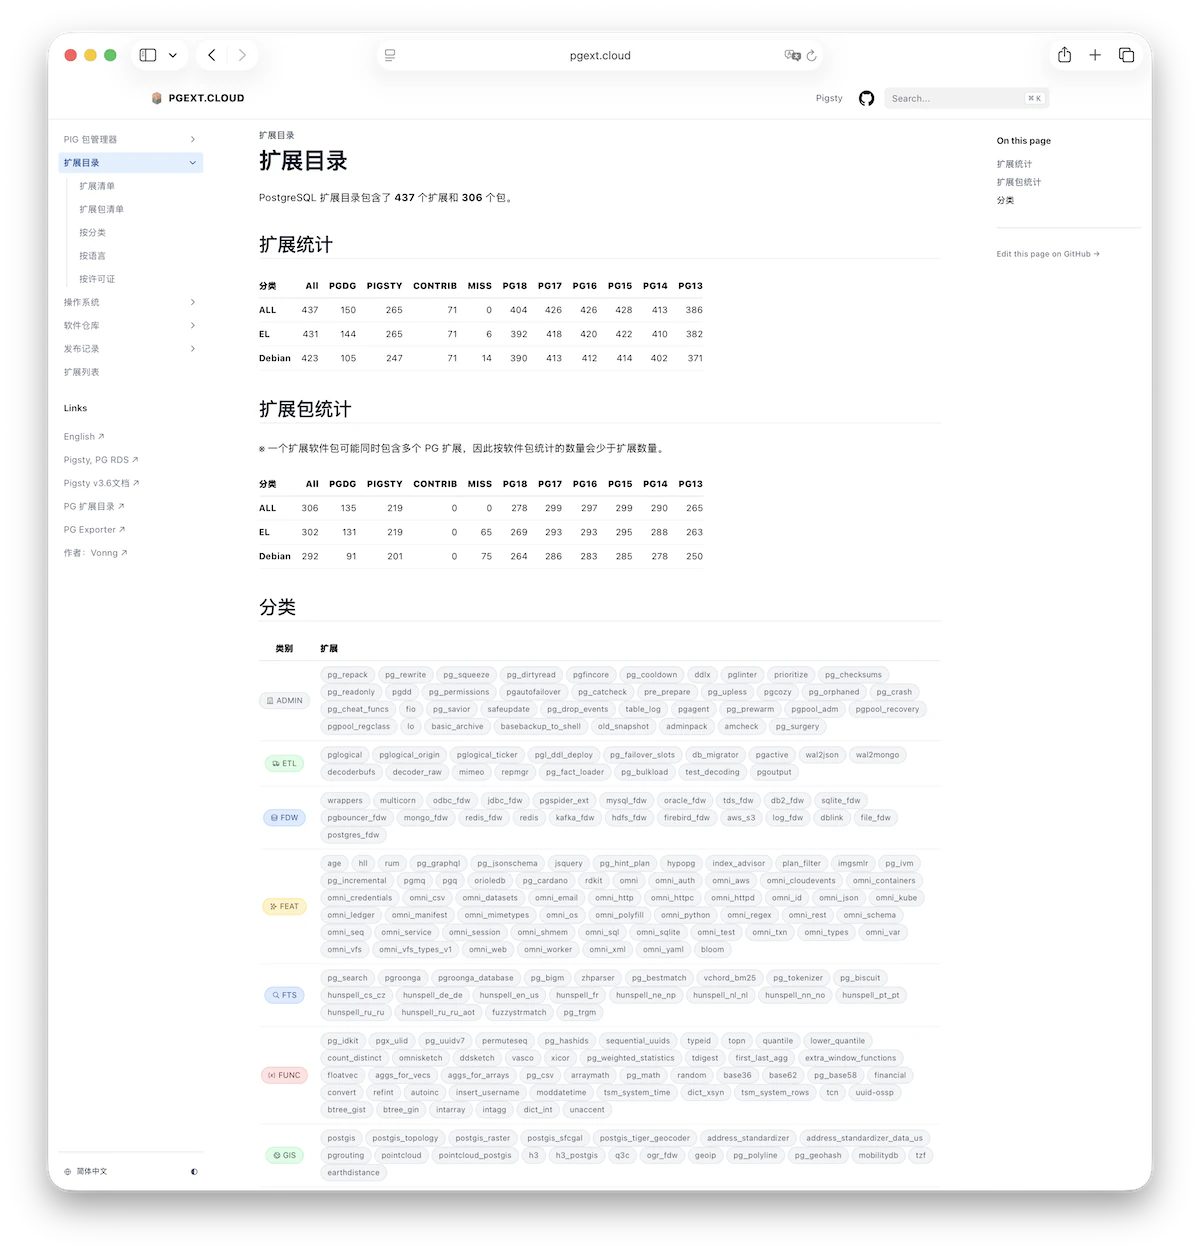
PIGSTY INFRA
This repository provides database tools, Grafana, Prometheus, and exporters. The following package versions describe the November 22, 2025 snapshot.
Databases and ecosystem tools
| Package | Version |
|---|---|
| IvorySQL | 4.6 |
| etcd | 3.6.6 |
| minio | 20250907161309 |
| mcli | 20250813083541 |
| kafka | 4.0.0 |
| duckdb | 1.4.2 |
| ferretdb | 2.7.0 |
| tigerbeetle | 0.16.60 |
| juicefs | 1.3.0 |
| dblab | 0.34.2 |
| v2ray | 5.28.0 |
| pig | 0.7.2 |
| vip-manager | 4.0.0 |
| pev2 | 1.17.0 |
| promscale | 0.17.0 |
| pgschema | 1.4.2 |
Prometheus and exporters
| Package | Version |
|---|---|
| prometheus | 3.7.3 |
| pushgateway | 1.11.2 |
| alertmanager | 0.29.0 |
| blackbox_exporter | 0.27.0 |
| VictoriaMetrics | 1.129.1 |
| VictoriaLogs | 1.37.2 |
| pg_exporter | 1.0.3 |
| pgbackrest_exporter | 0.21.0 |
| node_exporter | 1.10.2 |
| keepalived_exporter | 1.7.0 |
| nginx_exporter | 1.5.1 |
| zfs_exporter | 3.8.1 |
| mysqld_exporter | 0.18.0 |
| redis_exporter | 1.80.0 |
| kafka_exporter | 1.9.0 |
| mongodb_exporter | 0.47.1 |
Grafana and log tools
| Package | Version |
|---|---|
| grafana | 12.3.0 |
| loki | 3.1.1 |
| promtail | 3.0.0 |
| vector | 0.51.1 |
| grafana-infinity-ds | 3.6.0 |
| grafana-vmlogs-ds | 0.21.4 |
| grafana-vmetrics-ds | 0.19.6 |
| grafana-plugins | 12.0.0 |
Utilities
| Package | Version |
|---|---|
| sealos | 5.1.1 |
| rclone | 1.71.2 |
| restic | 0.18.1 |
| mtail | 3.0.8 |
| genai-toolbox | 0.18.0 |
| sqlcmd | 1.8.0 |
Originally published on vonng.com.
1.11 - PG Extension Cloud: Unlocking PostgreSQL’s Entire Ecosystem
PostgreSQL’s killer feature is extensibility. PostGIS, pgvector, pg_duckdb, pg_search—extensions turn PG into GIS engine, vector DB, analytics warehouse, search cluster. But compiling and shipping them reliably across distros is a nightmare, especially when official mirrors freeze or your network can’t reach upstream.
After two years of grinding, I’m launching PGEXT.CLOUD: the infrastructure for discovering, packaging, and installing PG extensions.
What’s inside
- Extension catalog – Browse 431 extensions with metadata, docs, compatibility matrices, how-to guides. Think “Wikipedia for PG extensions.”
- Binary repos – Native RPM/DEB packages for 14 Linux releases and 6 major PG versions. No Docker-only traps.
pigCLI – A 4 MB Go tool that wraps your existing package manager and hides the matrix of platforms/versions.
Try it on a fresh server/container:
Behind those three lines sits combinatorial chaos—14 distros × 6 PG versions × 431 extensions. PIG selects the matching packages for the host.
Why we needed this
Official PGDG repos ship ~135 extensions. Popular ones (PostGIS, pgvector) are there, but many heavy-hitters aren’t: pg_duckdb, pg_mooncake, plv8, Supabase’s Rust extensions. PGDG maintainers understandably don’t want to maintain ten-minute Rust builds.
I hoped projects like Tembo’s trunk or pgxman would solve distribution. They didn’t. So I built it myself. Today PGEXT.CLOUD packages 260 EL extensions and 241 Debian extensions—about 72% of everything listed. The catalog tracks availability by OS/version and documents installation for every extension.
Smooth installs
pig isn’t a new package manager; it’s a piggyback layer over yum/dnf/apt. You can still use apt install postgresql-18-pgvector directly—the repos are standard. pig just automates repo setup, architecture detection, PG version switching, and dependency resolution.
Open supply chain
Some folks asked, “You’re in China—how do we trust your binaries?” Supply-chain trust is hard regardless of nationality; even PGDG’s yum repo relies on Devrim’s reputation. My answer: everything is open. The build scripts, Dockerfiles, and tooling are public. You can rebuild any package yourself in an isolated environment:
Then:
The packages on PGEXT.CLOUD are built exactly this way. If you don’t trust me, rebuild locally and host your own repo. That’s the point: open tooling, reproducible builds, no lock-in.
PGEXT.CLOUD is my attempt to make PostgreSQL’s extension ecosystem accessible. Discover what exists, install it in seconds, and unleash PG’s full potential.
Originally published on vonng.com.
1.12 - Build and Packaging: An Overlooked but Scarce Skill
I was recently chatting with my friend Yurii, the founder of Omnigres. He wants to hire a PostgreSQL packaging expert and has even coined a title for the role: EEE, or Extension Ecosystem Engineer. It is an interesting idea. The job description is public, so I have included it at the end.
A Scarce Skill: Linux Packaging
I think this job description asks for a little too much: DevRel + SRE + DBA + build engineer + PostgreSQL specialist, all in one person. It almost reads as though it were written for me. But I have genuinely never met anyone else with that exact combination, so I advised Yurii that hiring a build engineer who knows Debian and Enterprise Linux packaging inside out would be more realistic. Even that will be difficult, though. Scarce hardly begins to describe people who understand build and packaging work. DevRel talent may be scarcer still.
The context here is specifically building and packaging PostgreSQL kernels and extensions for Linux. Most of the code is C or C++, with some Rust, Java, Go, and other languages mixed in. The main deliverables are RPM and DEB packages distributed through YUM and APT repositories. I believe this is a remarkably valuable skill that gets very little attention.
When Did I Realize This?
I first recognized the importance of packaging in 2017, during an interview with Pivotal. One of the interviewers asked, almost in passing, “Do you know how to package software? We don’t have anyone who does.” I wondered what kind of package he meant. RPMs? As it turned out, yes. Later, Yao of YMatrix, who had also come out of Pivotal, asked me much the same thing: “You know build and packaging work pretty well, don’t you? We badly need that skill right now.” That made the gap stick in my mind.
Since then, I have examined software released by many database companies in China and abroad. Their packaging is often painful to behold. How, for example, did Greenplum used to ship to customers? As a single CentOS 7.9 RPM. That was it. Wanted to run it on EL 8, EL 9, Ubuntu, Debian, or another Linux distribution? Tough luck.
Alibaba Cloud’s PolarDB for PostgreSQL and HighGo’s IvorySQL also started with only one or two EL RPMs. After a great deal of pushing from me, they eventually covered the mainstream Linux distributions. For the MySQL-compatible OpenHalo kernel and OrioleDB, I simply stepped in and packaged them myself.
Why Build and Packaging Matter
Packaging expertise is scarce, but where does its value come from? Most end users do not care whether your software is open source. What they care about is whether a stable, reliable—and preferably free—binary package is available to download. Greenplum is now closed source, yet friends still ask me from time to time for Greenplum RPMs. Yao’s YMatrix, a closed-source branch of GP7, is commercial software. But it offers a free trial download, so people can still use it. Whether its source is open hardly matters to them.
A more recent example is the KubeSphere community’s binary cutoff. The source code was still there, but the project deleted its binary artifacts—the container images—and that directly affected end users. Whether the code was open source made no practical difference to them. The real supply-chain chokepoint has never been source code, but the finished software artifacts users actually run.
Packaging Makes Open Source Self-Reliant
Open-source expert Tison explored this issue in depth in his articles “How Can You Use Open Source Software with Confidence?” and “Can Open Source Software Be Cut Off?”. His conclusion is that open-source software itself cannot be cut off, but its artifacts can. If you want to use open source with confidence, the most important safeguard is to keep a local copy of the software or operate your own package repository. Build and packaging work is the foundation for that independence.
Consider the recent PGDG repository supply disruption. Almost every mirror worldwide lost synchronization with the PGDG upstream and remained stuck on versions five months out of date. At the time, only xTom in Germany, Yandex in Russia, and Pigsty in China were providing manually updated mirrors of the latest PGDG packages.
Of course, a mirror merely copies binary artifacts built by someone else. Imagine the more extreme case: instead of merely stopping incremental synchronization, PGDG locked everything down completely. To build an independent repository from scratch, with separate packages for RISC-V, MIPS, ARM, and the rest of the architectural menagerie, you would still have to cross the build-and-packaging barrier.
Not All Packaging Is Equal
Someone will inevitably say, “But it is open source. You can compile it yourself.” That is true. Software written in modern languages often comes with a much smoother packaging workflow. Go programs, for example, are exceptionally easy to build and package. Tools such as GoReleaser can build an entire cross-platform matrix in one shot, generate RPM and DEB packages, build and push Docker images, and create a GitHub Release automatically. With vibe coding, you could probably implement such a workflow in under half an hour.
But that is not what we are talking about. We are talking about ecosystem-scale projects such as Debian and PostgreSQL, especially the C and C++ software at their core. Packaging the PostgreSQL database is not a matter of producing a handful of RPMs, either. Across the 10 Linux distributions and five PostgreSQL major versions I support, plus extensions and tools, I now provide roughly 40,000 RPM and DEB packages.
Build and packaging work is not easy. You must untangle dependencies involving glibc, ICU, OpenSSL, and PostGIS’s enormous dependency tree; deal with the obscure system libraries required by assorted extensions; resolve version conflicts across distributions and even across major releases of the same distribution; and master a whole toolbox that includes CMake, Make, Ninja, Cargo, and more.
Why Not Docker?
Docker looks like a shortcut around packaging: build once, run anywhere. If only. Docker does remove Linux distribution releases—EL 9, Debian 12, Ubuntu 24.04, and so on—from the build matrix. But you still need separate builds for PostgreSQL major versions, system architectures, and hundreds of extensions in multiple versions. And if you inspect PostgreSQL Docker images, you will find that their Dockerfiles often still use apt install to install PGDG’s DEB packages. Linux packages are upstream of Docker images, not the other way around.
Second, extensions are one of PostgreSQL’s defining advantages over other databases, yet container images still have no elegant answer to the problem of persistent PostgreSQL extensions. You do not know which of hundreds of extensions a user will need, but installing every one of them makes an image bloated and foolish. Álvaro is doing some pioneering work in this area, but in my view the approach remains some distance from mature operational practice.
Is Putting a Database in Docker a Good Idea?
Should Databases Be Deployed in Kubernetes?
How I Got Into Packaging
I started doing this work only about two years before writing this article. I wanted Pigsty to support self-hosted Supabase, but Supabase depended on more than a dozen PostgreSQL extensions, most of which were absent from the official PGDG binary repositories. I asked Devrim, the maintainer of the PGDG YUM repository, about them. He told me that extensions written in Rust would never make it into PGDG because they took too long to compile. So I rolled up my sleeves and built the RPMs myself.
Once the RPMs existed, I thought I might as well produce DEBs too. And once I supported more than a dozen PostgreSQL extensions, why not package the other 200-plus extensions missing from the official PGDG repositories?
Step by step, that effort grew into the PostgreSQL extension repository I maintain. At the time of writing, it contained nine flavors of the PostgreSQL kernel and more than 200 PostgreSQL extensions—423 available extensions when combined with PGDG. It offered the world’s broadest selection of usable PostgreSQL extension artifacts. Without false modesty, when it comes to PostgreSQL build and packaging work, Devrim on the YUM repository, Christoph on the APT repository, Álvaro on the OCI repository, David Wheeler on PGXN, and I are among the strongest practitioners in the field.
The clearest example is Supabase. As the darling of the AI wave and perhaps the database sector’s biggest winner, it should have drawn an army of vendors into the market. Yet at the time of writing, the only open-source PostgreSQL distributions capable of delivering self-hosted Supabase were Pigsty, my Linux-native distribution based on RPM and DEB packages, and Álvaro’s StackGres, based on OCI images and Kubernetes.
That is because we solved the build, packaging, and distribution problems for Supabase’s specialized extensions. This is the actual bottleneck. Even if Supabase publishes the source code for those extensions—and later switches to the OrioleDB kernel—how many people understand that code? How many users can turn it into something they can actually run?
Engineers who know EL or Debian packaging do exist. Engineers who also understand the PostgreSQL ecosystem well enough to build hundreds of PostgreSQL packages across more than ten Linux distributions are genuinely rare.
A Vanishingly Rare Craft
In practice, I have found this skill astonishingly scarce. Yurii asked me who else understands it. In China, nobody comes to mind. Even globally, perhaps the author of ZomboDB, who also created pgrx and was hired by ParadeDB, could do it well. Beyond that, I struggle to name anyone.
The PostgreSQL ecosystem has a huge number of extensions, but ParadeDB is the only extension vendor I know that ships mainstream Linux RPM and DEB packages at release time for pg_search. They do it because they release so frequently. I grew tired of packaging every release for them, so I taught them the process step by step. PGroonga, TimescaleDB, and Citus also produce their own packages, but those packages do not consistently follow PGDG conventions and their build matrices often have holes. Citus has long lacked ARM packages; TimescaleDB misses several specific distributions; and PGroonga packages against the PostgreSQL version bundled by Debian. The list goes on.
The same pattern appears among Chinese database vendors. Alibaba Cloud’s PolarDB for PostgreSQL and IvorySQL once offered only a few EL RPMs. After I pushed them hard, they eventually produced packages for all 10 mainstream Linux distributions supported by Pigsty. I also helped them fix several elementary packaging mistakes. For the MySQL-compatible OpenHalo, I simply built the DEB and RPM packages myself. Supabase’s OrioleDB appeared to lack this capability as well, so I packaged it too and made it work out of the box in Pigsty.
Conclusion
Value often comes from non-consensus skills. Build and packaging work is a perfect example. To a casual observer, it looks like little more than compiling some code and wrapping it in a package. In reality, it is an exceptionally scarce craft—one whose absence creates painful supply-chain chokepoints.
References
Originally published in Chinese on vonng.com.
1.13 - The PostgreSQL 'Supply Cut' and Trust Issues in Software Supply Chain
This month, KubeSphere removed its container images, prompting a debate about open-source supply chains. A quieter disruption had already affected PostgreSQL: PGDG had closed its mirror synchronization channels. For me, that disruption tested how database vendors and cloud providers respond when their upstream supply chain fails.
I was disappointed by the response. I stopped relying on Chinese cloud and university mirrors and built a domestic mirror of the PGDG YUM and APT repositories myself.
PGDG’s “Supply Cut”
PostgreSQL is one of the most widely used open-source databases. Many Linux users install it through the PGDG APT and YUM repositories. In mid-May, PGDG (PostgreSQL Global Development Group) closed the FTP and rsync channels used to synchronize its repositories. Most mirrors stopped receiving updates and continued serving packages that were months old.
I covered this in detail in “Chokepoint: PGDG Cuts Mirror Sync Channels” on July 7th. At that time, Germany’s xTom appeared to update its mirror manually each month. Most other mirrors still held packages from March, April, or May. When I checked again yesterday, Russia’s Yandex had also updated its APT mirror manually; the others were still stale.
| Provider | Region | Sync Timestamp | URL |
|---|---|---|---|
| Alibaba-Cloud | China | 2025-03-31 | sync timestamp |
| Tencent Cloud | China | 2025-03-31 | sync timestamp |
| Volcano Cloud | China | 2025-03-10 | sync timestamp |
| Huawei Cloud | China | 2024-01-02 | sync timestamp |
| Tsinghua TUNA | China | 2025-03-31 | historical screenshot |
| Zhejiang Univ | China | 2025-03-31 | sync timestamp |
| USTC | China | Removed | removal notice |
| TrueNetwork | Russia | 2025-01-31 | sync timestamp |
| JAIST | Japan | 2025-03-31 | sync timestamp |
| DOTSRC | Denmark | 2025-03-31 | sync timestamp |
| MirrorService | UK | 2025-03-31 | sync timestamp |
| Princeton Univ | USA | 2025-03-31 | sync timestamp |
| YANDEX | Russia | 2025-08-13 | mirror |
| XTOM | Germany | 2025-07-24 | mirror |
| PIGSTY | China | 2025-08-14 | repository docs |
Mirrors “Stop Updating”
For instance, the 17.5 May update fixed CVE-2025-4207 GB18030-related vulnerability, and the just-released 17.6 series fixed 3 CVEs and 55 bugs. If you’re a mirror user, you can’t update and patch in time. Not to mention PostgreSQL 18 releasing next month. We’re still in the early stages — just two PG minor versions behind, but soon it’ll be a major version behind. All those accumulated vulnerability patches and security fixes become unavailable to domestic users, creating increasingly larger exposure risks.
From a mirror user’s perspective, the flow of updates had stopped. PGDG did provide an alternative: direct downloads through a CDN.
Why PGDG “Cut Supply”
In the PostgreSQL mailing list, on May 20th, a Korean mirror maintainer asked why rsync sync with PGDG official repository suddenly broke.
Dave Page explained that FTP and rsync had never been officially supported services. The repositories ran on two physical machines and handled about 10 TB of traffic each day, including substantial unwanted traffic. PGDG moved downloads behind Fastly’s CDN.
The reasoning is understandable: a CDN can serve users directly across many locations. PGDG kept HTTP access available and closed FTP and rsync. Users who could reach the CDN could switch to the official repository.
What This Meant for Users in China
The disruption had less impact where users could reach PGDG’s CDN. In mainland China, access to those CDN endpoints was unreliable or blocked. Stale domestic mirrors therefore left many users without a practical source of current packages.
A proxy could restore access, but not every user could configure one, and downloads could still be slow. Domestic mirrors remained important. Docker did not remove that dependency: Docker Hub also had access problems, and many PostgreSQL images installed packages from the same APT repositories.
From this angle, Chinese users faced a real supply-chain bottleneck. PGDG had supplied an alternative, but local network restrictions made it hard to use. Whatever the cause, someone needed to restore access to current packages.
Common choices included Alibaba Cloud, Tsinghua University’s TUNA, Zhejiang University, and USTC. The mirrors I checked had stopped updating. That was frustrating, although these were free services rather than contracted suppliers.
Supply Chain Risk
In “How to Safely Use Open-Source Software?” and “Does Open-Source Software Have Supply Cut Risk?”, Tison distinguishes access to source code from access to a supplier’s services. His argument is that a supplier cannot withdraw the rights already granted over an open-source copy. Expectations of continued service often get confused with those rights.
Users depend on a concrete supply chain, however. RPMs, DEBs, container images, and the repositories that distribute them can disappear or stop receiving updates. Keeping that delivery path available takes work and money.
Distribution has costs. Developers may enjoy writing software, but packaging, repository maintenance, and reliable delivery require sustained work. At ¥0.80 per GB, 10 TB of daily traffic would cost thousands of yuan a day. Universities and large internet companies often operate mirrors because they already have the infrastructure and need the packages themselves.
Most users do not pay PGDG or mirror operators. An open-source license does not require its authors to operate a package repository indefinitely. Users who depend on a free service still need to decide how to maintain their own supply chain.
How to Solve Supply Chain Risk?
Could commercial database vendors solve this? Many Chinese database products derive from PostgreSQL, so I expected at least some vendors to maintain a local mirror. Yet many depended on Alibaba Cloud or TUNA themselves. Others shipped a few RPM files rather than maintaining a repository at all.
I maintain a repository with nine PostgreSQL kernel variants and more than 200 additional extensions—over 400 available extensions when combined with PGDG. Building it has given me substantial packaging experience, alongside the work of Devrim on YUM, Christoph on APT, Álvaro on OCI delivery, and David Wheeler on PGXN.
I still use PGDG for the standard PostgreSQL packages. Devrim and Christoph already do that work well; Pigsty’s repository supplements it with extensions. PGDG is therefore an upstream supplier for Pigsty, and Alibaba Cloud had been our indirect supplier in China. When that mirror and the alternatives stopped updating, I needed a replacement.
I reported the problem to Alibaba Cloud and TUNA and discussed it with Dege. Weeks passed without a resolution. I was disappointed, but waiting longer would not solve the problem for Pigsty users.
I’ll Do It Myself
So I built the mirror. FTP and rsync were closed, but HTTP remained available. Yesterday, with help from Claude Code, I spent about two hours writing a synchronization process with apt-mirror and reposync, then downloaded and tested the packages. The solution was much simpler than I had expected. It was frustrating to see such a small amount of work remain undone for so long.
The complete repository occupied hundreds of gigabytes. I selected x86_64 and aarch64 packages for PostgreSQL 13–17 on Debian 11/12/13, Ubuntu 22.04/24.04, and EL 7/8/9/10. Keeping only the latest package versions reduced the mirror to a few dozen gigabytes. After about two hours of downloading, I published the mirror behind a domestic CDN. PIG v0.6.1 uses this mirror in mainland China, and Pigsty v3.6.1 will follow. Pigsty can now maintain its own path from PGDG to local users.
The mirror is free to use, with or without Pigsty. Public downloads add bandwidth costs, but maintaining the mirror is also part of my commitment to customers, and everyone benefits from that work. Contributions of servers, CDN capacity, or funding are welcome.
This reminded me of the extension repository. Two years ago, I hoped projects such as Tembo and pgxman would provide the delivery tools I needed. After waiting for months, I built PIG, the extension catalog, and the package repository myself. Projects such as Omnigres and Autobase now use that repository to deliver packages to their users. My own supply chain has become part of theirs.
Publishing source code alone does not provide a reliable supply of packages. Trust comes from sustained work: maintaining releases, keeping delivery commitments, and responding when things break. An open-source repository is one part of that commitment.
Originally published on vonng.com.
1.14 - PGDG Cuts Off Mirror Sync Channel
Recently, while building Pigsty offline packages, I discovered that the PostgreSQL version installed during local testing wasn’t quite right - 17.4 was behind the latest 17.5 by one minor version. Also, when testing on EL10, I found several repositories were throwing errors. Strangely, using the global default repository in Hong Kong worked fine, but once using Chinese mirror sites locally, errors occurred.
Upon closer inspection, I found that domestic mirror sites had all lost synchronization with the PostgreSQL upstream repository: Tsinghua University Open-Source Software Mirror Site (TUNA) last successful sync was May 16th, while Alibaba-Cloud Mirror Site’s last sync timestamp was March 31, 2025. Foreign mirror sites like mirrors.xtom.de also had this problem, with last sync on June 20th, though you could clearly see signs of manual updates and disconnection from sync.
I searched and found that on May 20th in the PostgreSQL mailing list, a Korean mirror site maintainer had already asked about this issue - the mirror site maintainer asked why rsync synchronization with PGDG official repository suddenly broke?
PostgreSQL contributor Dave Page replied that due to massive amounts of illegal traffic flooding in, they decided to permanently shut down the previously unofficial FTP server, no longer providing rsync sync options, only allowing HTTP access.
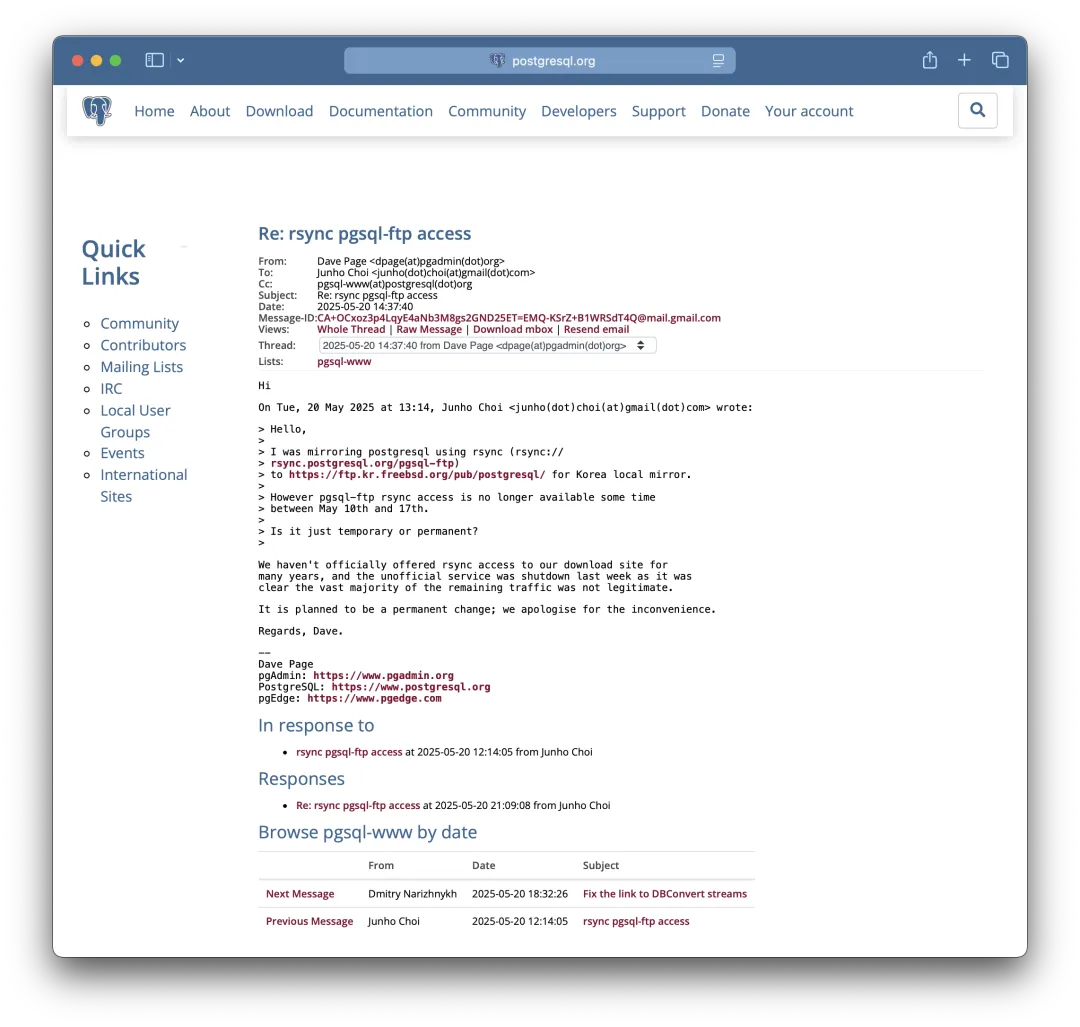
PostgreSQL, as the world’s most popular database software, has the vast majority of users downloading and installing pre-built binary software packages through PGDG official repositories rather than compiling from source. This repository is hosted on just two physical machines - according to PostgreSQL Infra Team statistics, roughly 66 million requests per day (about 750 downloads per second), about 10TB of data transfer daily.
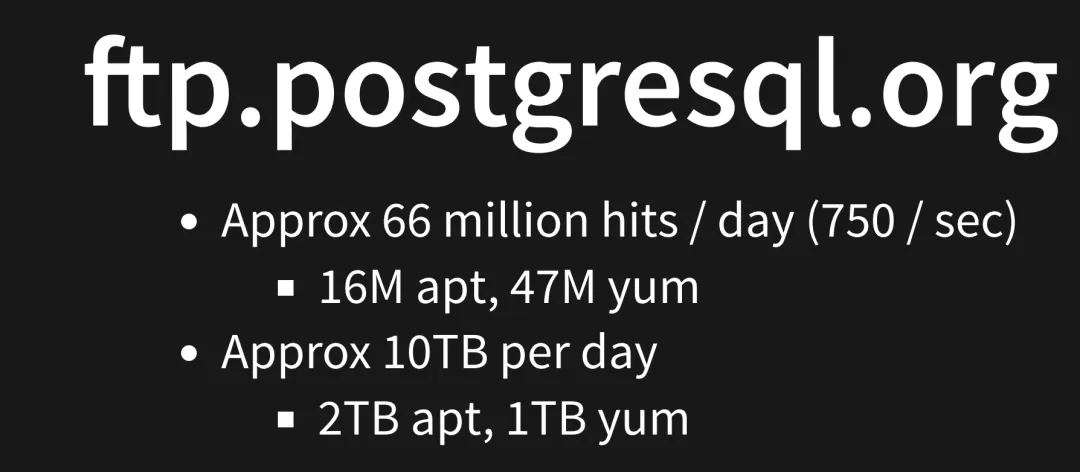
At PGConf.dev 2025, the infrastructure presentation described a move from four servers to two, with a CDN in front. Then seeing this traffic was too much to handle, they just cut off rsync/ftp, and all downstream PostgreSQL repositories worldwide went dark. Honestly, I think this is quite ridiculous - if you block all these mirror sites, when users flood directly to the original upstream, won’t the traffic be even greater?
But honestly, you can’t really blame them for anything, because this is just open source STYLE - no warranty - after all, they’re not charging money, developers have no obligation to keep doing charity. But from another perspective, this really strangled global users’ supply chain: for example, if users using mirror sites can’t timely update to 17.5 which fixes CVE vulnerabilities.
I’ve already reported this issue to Alibaba-Cloud Mirror and Tsinghua TUNA Mirror maintainers to see if it can be fixed recently. For example, using HTTP to pull updates. If it can’t be resolved in the short term, I’m prepared to pull down part of the PGDG repository myself and put it on Cloudflare to make a mirror site first.
From a supply chain security perspective, forking and modifying a PG kernel indeed has no real use. But maintaining a self-controlled software binary product repository has critical significance for operational autonomy and control.
I’ve also been thinking about setting up a mirror site domestically myself, since I’ve already set up a Pigsty APT/YUM repository, adding PG wouldn’t be a big deal. But actually Alibaba-Cloud and TUNA have been doing quite well before, so I’ve always used these two as default configurations for domestic users.
As for the long term, actually I could recompile and package a dedicated PostgreSQL repository, especially since I’ve recently packaged several PG branch kernels, plus over 250 extensions in the PG ecosystem not included by PGDG. I’m already a veteran packager when it comes to building APT/YUM repositories. However, the main issue is maintenance takes too much time, and domestic traffic costs are also too expensive. But if there’s a sponsor willing to support unlimited traffic high-bandwidth servers, I’d be happy to do some extra volunteer work.
Originally published on vonng.com.
1.15 - Postgres Extensions Day — See You There!
The annual PostgreSQL developer conference, PGConf.dev, will be held in Montreal in May. Postgres Extensions Day takes place the day before it, with a focus on extension development, packaging, and release. The agenda has just been released, with 14 talks.
This time, I’ll be speaking in the first afternoon session: “The Missing Postgres Extension Repo and Package Manager”. I’ll introduce Pigsty’s extension repository and the PIG package manager, and discuss the work of building and maintaining PostgreSQL extensions. It is a chance to share a Chinese developer and database vendor’s experience with developers from around the world — even if that vendor is a one-person shop, haha.
Postgres Extensions Day is scheduled for May 12, 2025, at Plaza Centre-Ville in Montreal, Quebec, Canada. PGConf.dev 2025 follows at the same venue on May 13–16.
Last year’s PG developer conference in Vancouver was incredibly rewarding, though there were very few participants from China. Not sure how this edition will be - if you’re also going, please leave a comment and we can meet up in person!
If you plan to attend, register separately at pgext.day. The Postgres Extension Developers Coalition organizes this independent event. Attendance is free; a regular PGConf.dev ticket costs CAD 500 before tax.
Below is the PG Extension Summit agenda - looking forward to seeing readers at the extension summit!
Extension Summit Schedule
1. From pl/v8 to pl/<any>: Towards Easier Extension Development
9:00 am → 25 min, Hannu Krosing
From pl/v8 to pl/<any>: towards easier extension development
pg_tle lets developers write and deploy trusted-language extensions without superuser privileges. It also provides hooks for trusted language functions, such as enforcing password policies. pl/<any> further allows using any language to write database functions, thereby implementing extensions. The main approach is writing Language Handlers in JavaScript and using languages that can be transpiled to JavaScript as PostgreSQL’s embedded (or “pl/”) language.
Examples include:
- pl/jsonschema: Based on the AJV JSON Schema validation library, directly converting JSON Schema definitions into runnable validation functions, sometimes far outperforming pg_jsonschema wrapped with Rust + PGRX.
- pl/wasm: Runs compiled WebAssembly as standard PostgreSQL functions. For compute-intensive code, the session abstract reports execution times about 2–3 times those of native code.
- pl/codelength: Example handler that converts any source code into a function returning the original code’s length.
Future expansions on pl/v8 could include:
- Writing custom FDWs (similar to Python’s Multicorn)
- Writing custom logical decoding plugins
- Exposing more hooks and trace points for JavaScript handlers
- Allowing users to directly construct plan trees, even adding new node types or monitoring probes
2. Upgrade as an Extension
9:30 am → 25 min, Andrey Borodin
Upgrade as an extension
(No content description available, but the title alone sounds exciting!)
3. Inlining Postgres Functions: Now and Then
10:00 am → 25 min, Paul Jungwirth
Inlining Postgres Functions, Now and Then
When PostgreSQL calls user-defined functions (or built-in functions), it might attempt inlining, providing new possibilities for SQL developers and extension authors. This talk will introduce two inlining methods currently used by PostgreSQL (available now) and a patch in development aimed at supporting inlining for most set-returning functions. Your functions can replace themselves with a “plan tree,” which the optimizer then merges with other query parts - almost like writing a macro!
4. Postgres à la Carte: Dynamic Container Images with Your Choice of Extensions
10:30 am → 25 min, Alvaro Hernandez
Postgres à la carte: dynamic container images with your choice of extensions
When building Postgres container images, required extensions are typically bundled, but security and size concerns prevent packaging all hundreds of available extensions at once. However, different users need vastly different extension combinations, and building dedicated container images for every possible combination would exceed the number of atoms in the universe.
Dynamic OCI container images can be generated on demand with the required extensions. These images can be used in any OCI-compatible environment like Kubernetes.
This talk will explore the concepts and technology behind dynamic container images and how to apply them for loading arbitrary extension combinations into Postgres images. The presentation will feature extensive demonstrations!
5. Cppgres: One Less Reason to Hate C++
11:00 am → 25 min, Yurii Rashkovskii
Cppgres: One less reason to hate C++
Writing Postgres extensions in C often feels tedious, error-prone, and repetitive. While many developers avoid C++ due to its complexity, modern C++ offers rich features making it easier to write reliable, maintainable Postgres extensions.
If you’re considering switching to Rust, consider C++ first - using the same compiler while enjoying more safety and usability.
This talk will introduce Cppgres: a lightweight, header-only C++20 library for writing safer, more readable Postgres extensions. Using concepts, automatic type deduction, and other modern C++ techniques, you can write concise, efficient, maintainable extensions. The talk will show how these features apply to extension development.
6. Working with MemoryContexts and Debugging Memory Leaks in Postgres
11:30 am → 25 min, Phil Eaton
Working with MemoryContexts and debugging memory leaks in Postgres
This talk will focus on creating and switching MemoryContexts in real scenarios, using tools like Linux’s eBPF to discover memory leaks. Content is based on real production cases, summarizing experiences and practical techniques from writing extensions and finding bugs.
7. Postgres as a Control Plane: Challenges in Offloading Compute via Extensions
12:00 pm → 25 min, Sweta Vooda
Postgres as a Control Plane: Challenges in Offloading Compute via Extensions
As Postgres’s role expands from storage layer to control plane, extensions orchestrating external systems (like vector search engines) must balance performance, consistency, and integration.
This talk will explore designing Postgres extensions to offload computation while maintaining SQL simplicity and transactional guarantees. Examples from pgvector-remote cover buffering, predicate pushdown, connection pooling, and VACUUM.
The session is aimed at engineers who want to offload computation while keeping a SQL interface.
8. Lunch
12:30 pm → 60 min
9. The Missing Postgres Extension Repo and Package Manager
1:30 pm → 25 min, Ruohang Feng
The Missing Postgres Extension Repo and Package Manager
Haha, that’s really me.
While PostgreSQL extensions are powerful and flexible, most users prefer “out-of-the-box” rather than compiling and manually building themselves. I have built a repository with packages for more than 200 extensions, filling gaps in the official PGDG repository. These RPM/DEB packages cover five Linux distributions, five major PostgreSQL versions, and x86-64/ARM64 architectures.
This talk will explore building this repository, including challenges like cross-distribution compatibility, multi-architecture support, version alignment, sharing experiences, lessons, and future improvements to make PostgreSQL extension installation easier.
10. How to Automatically Release Your Extensions on PGXN
2:00 pm → 25 min, David Wheeler
How to automatically release your extensions on PGXN
There’s currently no unified release center for all PostgreSQL extensions. While PGXN is the largest extension source code release service, it only includes about one-third of public extensions, and some versions aren’t current enough.
PGXN aims to become the root registry for all extension versions, hoping to sync all release information downstream to enable automated build processes. To achieve this, developers need to proactively upload extension updates to PGXN, benefiting the entire PostgreSQL community.
This talk will demonstrate setting up release processes on PGXN and achieving automation through Git, JSON, GitHub workflows, keeping your extensions current with one-click publishing to PGXN.
11. Extending PostgreSQL with Java: Overcoming Development Challenges in Bridging Java and C Applications
2:30 pm → 25 min, Cary Huang
Extending PostgreSQL with Java: Overcoming Development Challenges in Bridging Java and C Application
Java and C have vastly different design philosophies and memory management approaches. These seemingly opposite languages can work together seamlessly with the right methods to extend C-based PostgreSQL and integrate with Java applications or libraries.
This talk will share the development journey of the SynchDB project, which writes C extensions on the PostgreSQL side and integrates Java-version Debezium Embedded, guiding data change streams from MySQL, SQL Server, Oracle, and other sources into PostgreSQL.
The talk covers the challenges of using C and Java within one extension, including:
- JNI-based cross-language calls
- The process of embedding Debezium Embedded in C extensions
- Handling memory management and performance overhead
- Architectural integration of two language components
- Best practices for error handling, monitoring, and maintainability
Attendees will learn how to bring change data from other databases into PostgreSQL and combine C and Java within one extension.
12. Rethinking OLAP Architecture: The Journey to pg_mooncake v0.2
3:00 pm → 25 min, Cheng Chen
Rethinking OLAP Architecture: The Journey to pg_mooncake v0.2
In this talk, we’ll explore shortcomings of pg_mooncake v0.1 and major architectural changes made in v0.2. We’ll share lessons learned using Postgres replication, background worker processes, and extension-form inter-process communication (IPC).
13. Spat: Hijacking Shared Memory for a Redis-Like Experience in PostgreSQL
3:30 pm → 25 min, Florents Tselai
Spat: Hijacking Shared Memory for a Redis-Like Experience in PostgreSQL
Traditional databases typically use shared memory for work areas like query execution, caching, and transaction management - invisible to users. But what if we transformed it into high-performance data structures and caches for direct user use?
This talk will introduce PostgreSQL’s shared memory APIs exposed to extension developers (including the new DSM Registry) and how to build Spat: an in-memory data structure server storing data entirely in shared memory, providing Redis-like experience within PostgreSQL.
Spat provides key-value storage patterns supporting strings, lists, sets, hashes, and other structures, becoming lightweight, high-speed temporary storage within PostgreSQL. The talk will discuss the challenges of using shared memory this way.
14. Scaling PostgreSQL with Citus: Distributed Data for Modern Applications
4:00 pm → 25 min, Mehmet Yilmaz
Scaling PostgreSQL with Citus: Distributed Data for Modern Applications
This talk will explore how the Citus extension transforms PostgreSQL into a horizontally scalable distributed database. It covers Citus architecture, extension deployment, and production use.
Content includes:
- How Citus extends PostgreSQL to support distributed query processing and data sharding
- Best practices for extension packaging, release, and deployment in different environments
- Considerations for performance tuning and security mechanisms in distributed Postgres cluster operations
- Real success cases and lessons learned
15. Extensibility - New Options and a Wish List
4:30 pm → 25 min, Alastair Turner
Extensibility - new options and a wish list
Now is a great time to be a PostgreSQL extension developer - the community continues growing, even spawning dedicated extension summit events.
Meanwhile, Postgres continues opening more extensible areas. Over the past year, several core commits made EXPLAIN, cumulative statistics, COPY, and other parts extensible, but proposals in some areas like storage still await progress.
This talk will introduce recent new extensible areas (with example code) and discuss areas that still need work, especially storage.
16. Dinner
6:00 pm – 9:00 pm
Dinner
Looking Back at PGConf.dev 2024
- Andreas Scherbaum PostgreSQL Development Conference 2024 - Review
- PgCon 2024 Developer Meeting
- Robert Haas: 2024.pgconf.dev and Growing the Community
- How engaging was PGConf.dev really?
- Cary Huang: PGConf.dev 2024:Shaping PostgreSQL’s Future in Vancouver
- PGCon.Dev Extension Ecosystem Summit Notes @ Vancouver
- PG Conference 2024 Opening, Where’s the Vancouver Foodie Travel Group?
Originally published on vonng.com.
1.16 - Pig, The Postgres Extension Wizard
PIG is a Go command-line tool for installing PostgreSQL and extensions through the system package manager. It selects packages for the operating system, CPU architecture, and PostgreSQL version, then uses APT, YUM, or DNF to install them.
The extension repository supplies native RPM and DEB packages, including TimescaleDB, Citus, pgvector, and Rust extensions. It follows PGDG packaging conventions so these packages can be used with the standard PostgreSQL packages.
I built PIG to make that repository easier to use. You can search by extension name, inspect its metadata, and install the matching package without assembling package names yourself.
PIG v0.1 release · Source code · The ideal way to deliver PostgreSQL extensions
Get Started
Install the pig package with the installer or the system package manager.
Then it’s ready to use; assume you want to install the pg_duckdb extension:
Extension management
Repository management
Originally published on vonng.com.
1.17 - The Ideal Way to Deliver PostgreSQL Extensions
PostgreSQL Is Eating the Database World through the power of extensibility. When this post was first published, the repository packaged 340 PostgreSQL extensions as RPM / DEB packages for mainstream Linux distributions. The live Pigsty Extension Catalog has kept growing since then.
I believe the PostgreSQL community has reached a consensus on the importance of extensions. So the real question now becomes: “What should we do about it?”
What’s the primary problem with PostgreSQL extensions? In my opinion, it’s their accessibility. Extensions are useless if most users can’t easily install and enable them. But it’s not that easy.
Even the largest cloud PostgreSQL vendors are struggling with this. They have some inherent limitations (multi-tenancy, security, licensing) that make it hard for them to fully address this issue.
So here’s my plan: I’ve created a repository that hosts 340 of the most capable extensions in the PostgreSQL ecosystem, available as RPM / DEB packages on mainstream Linux OS distros. The goal is to take PostgreSQL one solid step closer to becoming the all-powerful database and achieve the great alignment between the Debian and EL OS ecosystems.
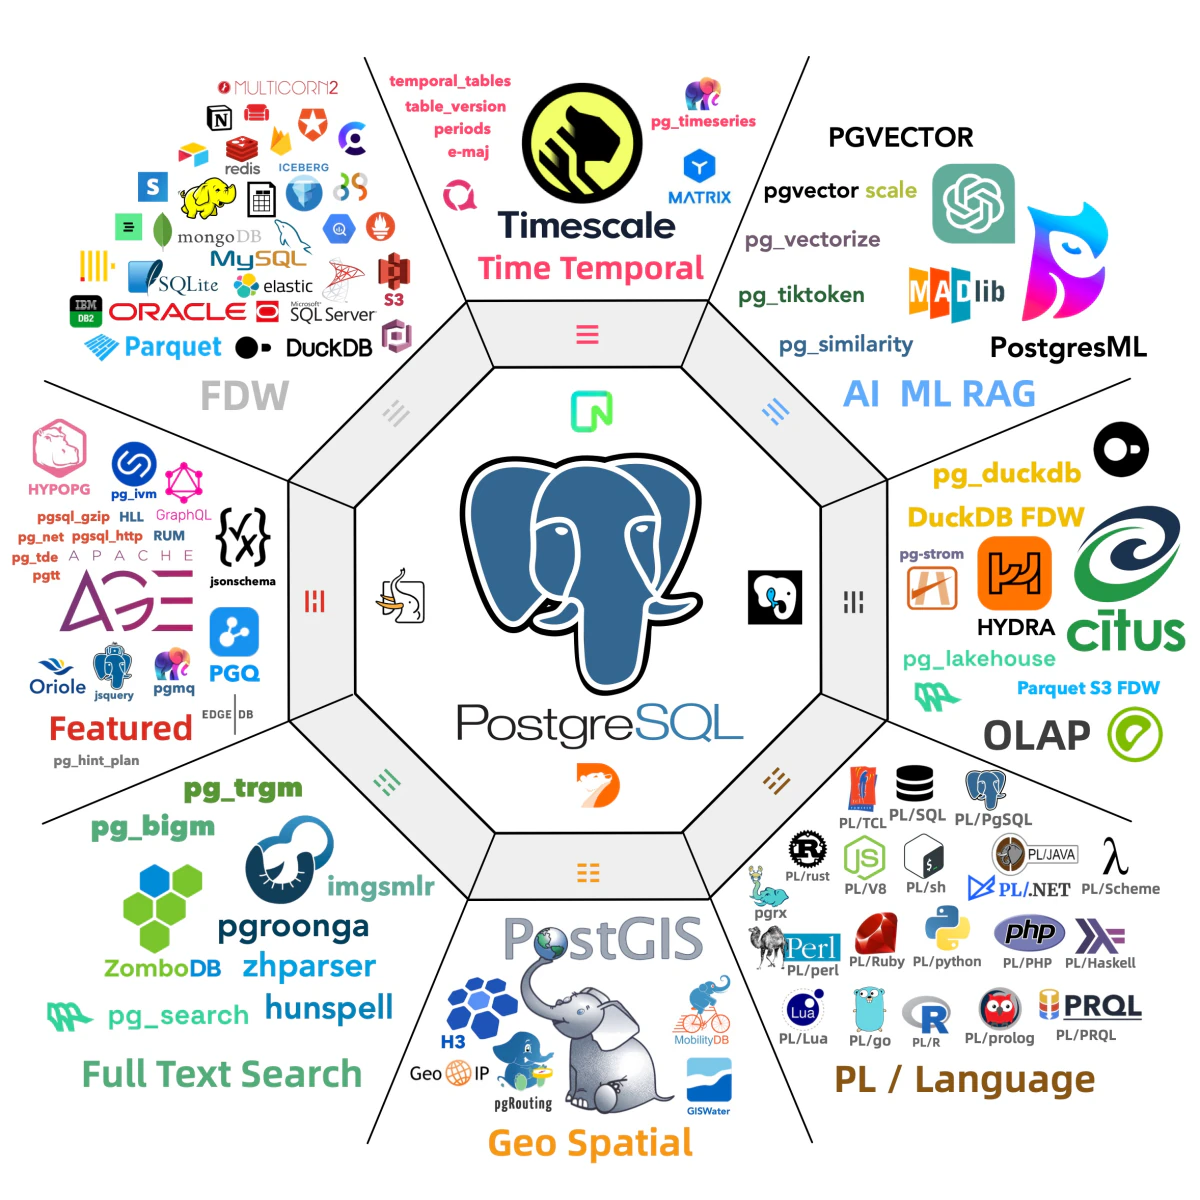
The status quo
The PostgreSQL ecosystem is rich with extensions, but how do you actually install and use them? This initial hurdle becomes a roadblock for many. There are some existing solutions:
PGXN says, “You can download and compile extensions on the fly with pgxnclient.”
Tembo says, “We have prepared pre-configured extension stack as Docker images.”
StackGres & Omnigres says, “We download .so files on the fly.” All solid ideas.
Based on my experience, the vast majority of users still rely on their operating system’s package manager to install PG extensions. On-the-fly compilation and downloading shared libraries might not be viable for production environments, because many database setups don’t have internet access or a proper toolchain ready.
In the meantime, existing OS package managers like yum/dnf/apt already solve issues like dependency resolution, upgrades, and version management well.
There’s no need to reinvent the wheel or disrupt existing standards. So the real question is: Who’s going to package these extensions into ready-to-use software?
PGDG has already made a fantastic effort with official YUM and APT repositories. In addition to the 70 built-in Contrib extensions bundled with PostgreSQL, the PGDG YUM repo offers 128 RPM extensions, while the APT repo offers 104 DEB extensions. These extensions are compiled and packaged in the same environment as the PostgreSQL kernel, making them easy to install alongside the PostgreSQL binary packages. In fact, even most PostgreSQL Docker images rely on the PGDG repo to install extensions.
I’m deeply grateful for Devrim’s maintenance of the PGDG YUM repo and Christoph’s work with the APT repo. Their efforts to make PostgreSQL installation and extension management seamless are incredibly valuable. But as a distribution creator myself, I’ve encountered some challenges with PostgreSQL extension distribution.
What’s the challenge?
The first major issue facing extension users is Alignment.
In the two primary Linux distro camps — Debian and EL — there’s a significant number of PostgreSQL extensions. Excluding the 70 built-in Contrib extensions bundled with PostgreSQL, the YUM repo offers 128 extensions, and the APT repo provides 104.
However, when we dig deeper, we see that alignment between the two repos is not ideal. The combined total of extensions across both repos is 153, but the overlap is just 79. That means only half of the extensions are available in both ecosystems!
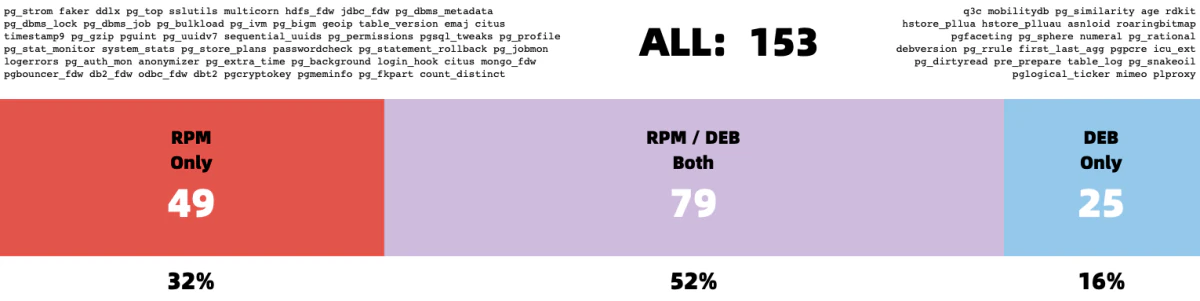
Only half of the extensions are available in both EL and Debian ecosystems!
Next, we run into further alignment issues within each ecosystem itself. The availability of extensions can vary between different major OS versions.
For instance, pljava, sequential_uuids, and firebird_fdw are only available in EL9, but not in EL8. Similarly, rdkit is available in Ubuntu 22+ / Debian 12+, but not in Ubuntu 20 / Debian 11.
There’s also the issue of architecture support. For example, citus does not provide arm64 packages in the Debian repo.
And then we have alignment issues across different PostgreSQL major versions. Some extensions won’t compile on older PostgreSQL versions, while others won’t work on newer ones. Some extensions are only available for specific PostgreSQL versions in certain distributions, and so on.
These alignment issues lead to a significant number of permutations. For example, if we consider five mainstream OS distributions (el8, el9, debian12, ubuntu22, ubuntu24),
two CPU architectures (x86_64 and arm64), and six PostgreSQL major versions (12–17), that’s 60 RPM/DEB build combinations per extension, just for one extension!
On top of alignment, there’s the problem of completeness. PGXN lists over 375 extensions, but the PostgreSQL ecosystem could have as many as 1,000+. The PGDG repos, however, contain only about one-tenth of them.
There are also several powerful new Rust-based extensions that PGDG doesn’t include, such as pg_graphql, pg_jsonschema, and wrappers for self-hosting Supabase;
pg_search as an Elasticsearch alternative; and the now-archived pg_analytics, pg_parquet, and pg_mooncake for OLAP processing. The reason? They are too slow to compile…
What’s the solution?
Over the past six months, I’ve focused on consolidating the PostgreSQL extension ecosystem. Recently, I reached a milestone I’m quite happy with. I’ve created a PG YUM/APT repository with a catalog of 340 available PostgreSQL extensions.
Here are some key stats for the repo: It hosts 340 extensions in total. Excluding the 70 built-in extensions that come with PostgreSQL, this leaves 270 third-party extensions. The PGDG repositories supply part of this set. I maintain, fix, compile, package, and distribute the additional extensions through Pigsty. The table below shows availability by repository and platform.
| OS \ Entry | All | PGDG | PIGSTY | CONTRIB | MISC | MISS | PG17 | PG16 | PG15 | PG14 | PG13 | PG12 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| RPM | 334 | 115 | 143 | 70 | 4 | 6 | 301 | 330 | 333 | 319 | 307 | 294 |
| DEB | 326 | 104 | 144 | 70 | 4 | 14 | 302 | 322 | 325 | 316 | 303 | 293 |
For each extension, I’ve built versions for the 6 major PostgreSQL versions (12–17) across five popular Linux distributions: EL8, EL9, Ubuntu 22.04, Ubuntu 24.04, and Debian 12. I’ve also provided some limited support for older OS versions like EL7, Debian 11, and Ubuntu 20.04.
This repository also addresses most of the alignment issue. Initially, there were extensions in the APT and YUM repos that were unique to each, but I’ve worked to port as many of these unique extensions to the other ecosystem. Now, only 7 APT extensions are missing from the YUM repo, and 16 extensions are missing in APT—just 6% of the total. Many missing PGDG extensions have also been resolved.
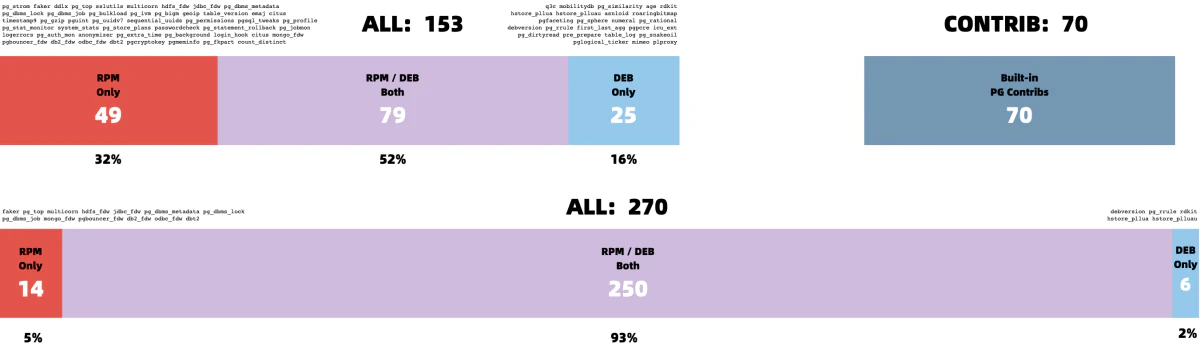
I’ve created a comprehensive directory listing all supported extensions, with detailed info, dependency installation instructions, and other important notes.
I hope this repository can serve as the ultimate solution to the frustration users face when extensions are difficult to find, compile, or install.
How to use this repo?
Now, for a quick plug — what’s the easiest way to install and use these extensions?
The simplest option is to use the OSS PostgreSQL distribution: Pigsty. The repo is autoconfigured by default, so all you need to do is declare them in the config inventory.
For example, the self-hosting Supabase config requires extensions that aren’t available in the PGDG repo. You can simply download, install, configure/preload, and create extensions by referring to their names.
To simply add extensions to existing clusters:
Although this repo is designed to be used with Pigsty, it is not mandatory. You can still enable this repository on any EL/Debian/Ubuntu system with a simple one-liner in the shell:
APT Repo


For the Debian 12 and Ubuntu 22.04/24.04 targets covered here, add the APT repository as follows. See the current repository reference for supported platforms and repository setup.
YUM Repo


For EL 8/9 and compatible platforms, use the following commands to add the YUM repository:
What’s in this repo?
The live catalog organizes extensions by category, platform, repository, language, license, and attributes. It started with categories such as TIME, GIS, RAG, FTS, OLAP, FEAT, LANG, TYPE, FUNC, ADMIN, STAT, SEC, FDW, SIM, and ETL, and continues to evolve as the extension ecosystem grows.
Check the Pigsty Extension Catalog for the current details.
Some Thoughts
Each major PostgreSQL version introduces changes, making the maintenance of 140+ extension packages a bit of a beast.
Especially when some extension authors haven’t updated their work in years. In these cases, you often have no choice but to take matters into your own hands. I’ve personally fixed several extensions and ensured they support the latest PostgreSQL major versions. For those authors I could reach, I’ve submitted numerous PRs and issues to keep things moving forward.
Back to the point: my goal with this repo is to establish a standard for PostgreSQL extension installation and distribution, solving the distribution challenges that have long troubled users.
A recent milestone is that, the popular open-source PostgreSQL HA cluster project postgresql_cluster, has made this extension repository the default upstream for PG extension installation.
Currently, this repository (repo.pigsty.io) is hosted on Cloudflare. In the past month, the repo and its mirrors have served about 300GB of downloads. Given that most extensions are just a few KB to a few MB, that amounts to nearly a million downloads per month. Since Cloudflare doesn’t charge for traffic, I can confidently commit to keeping this repository completely free and under active maintenance for the foreseeable future, as long as Cloudflare doesn’t charge me too much.
I believe my work can help PostgreSQL users worldwide and contribute to the thriving PostgreSQL ecosystem. I hope it proves useful to you as well. Enjoy PostgreSQL!
Originally published on vonng.com.
2 - Design Notes
Design notes explain the decisions and proposals behind PIG. Each note gives its date, status, scope, alternatives, and supporting evidence. Proposals describe directions under discussion; implemented and released records explain work that has reached those stages.
For command syntax and usage, use the PIG documentation. For changes in each version, use the release notes.
2.1 - From Human-Friendly to Agent-Native: PIG's CLI Contract
Decision date: 2026-02-12
Status: Released in pig v1.1.0 and refined by later command-layer work. The 2026-10-16 refinements below are Implemented in the v1.10.0 candidate, not yet released.
Current reference:pigcommand overview
Scope: PIG-owned commands and their machine-consumption contract; opaque passthrough commands keep their native interface.
Decision
PIG provides terminal text for people and structured results for automation. Commands that produce
stable data expose JSON or YAML and status codes. Supported workflows also expose execution plans.
Transparent passthroughs such as pig pt preserve the external tool’s output, prompts, and exit status.
Context
PIG began as a convenient package-management CLI. As it grew into PostgreSQL, Patroni, pgBackRest, Pigsty, and repository operations, a human-only interface created several problems:
- automation had to scrape colored prose;
- a zero process exit could hide a failed inner operation;
- destructive workflows could not be inspected before execution;
- an agent had to issue many discovery commands before understanding the host;
- wrappers could accidentally mix subprocess chatter with structured output.
The v1.1.0 design introduced global output selection, stable result objects, execution plans, and
the pig context snapshot. Later refactors narrowed these promises to commands that can actually
own them reliably.
Alternatives considered
Three tempting approaches were rejected:
- Parse human text. It is fragile across wording, localization, colors, and upstream tools.
- Capture every subprocess into JSON. This breaks interactive programs, streaming output, terminal control, and native exit semantics.
- Invent one universal result schema. Package transactions, recovery plans, metrics, and context snapshots have different stable data; flattening them loses meaning.
Contract
The durable contract is:
- text is the default interface for people;
- a command advertises structured output only when PIG owns a stable result;
- structured stdout contains one parseable result, while diagnostics and wrapped-tool output use stderr;
- a plan describes intended actions, scope, risk, and expected effects without performing them;
- destructive PIG-owned operations fail closed when confirmation is missing;
- status codes distinguish usage, confirmation, environment, dependency, and execution failures;
pig contextprovides a bounded environment snapshot rather than forcing consumers to infer it;- transparent passthroughs retain the upstream contract.
The 2026-10-16 refinements apply the same contract to pig ext:
- Availability checks and every summary format share matrix precedence, architecture aliases, and the metadata fallback. macOS reports declared PostgreSQL support without promising packages. This describes the catalog’s package snapshot. Default build targets retain their metadata and local-installation rules independently of the matrix.
- Partial imports return failure while preserving resolved, downloaded, and unresolved items. Completed downloads remain on disk; the operation does not promise an atomic transaction.
pig petreats HTTP 4xx/5xx as failure. Error details expose the numeric status and standard description, never the response body or server-supplied reason phrase.pig license issueexplicitly delivers a newly issued credential. Its successful structured result preserves the token indata.captured_output. Signing-key input is omitted from parameters, and raw key-loading errors are replaced with fixed messages at the command boundary. Parameter errors and safe signing-key diagnostics remain readable in every output format. Other sensitive command wrappers retain full output and error-detail redaction.
Consequences
This split makes scripts more reliable and lets agents choose commands based on risk and output capability. It also creates maintenance obligations: every structured field becomes compatibility surface, stdout purity needs tests, and a wrapper must not promise more stability than the tool it delegates to.
The output contract follows the command: PIG results for PIG operations, native output for forwarded tools.
Verification and evolution
Fixed source commits and regression tests for the committed v1.10.0 refinements cover: availability and counts, partial imports, exporter HTTP failures. These commits do not establish a release boundary.
The initial framework shipped with v1.1.0.
The command-layer consolidation in
fb93602 later removed duplicated wrappers and
centralized plan and output glue. Patroni subsequently became a transparent passthrough, an
example of reducing PIG-owned structure when the upstream interface is already authoritative.
Tests now cover structured stdout isolation, result rendering, plan behavior, confirmation gates, and context collection in the packages that own those contracts.
Current status
Use the output mode supported by each command. See the pig reference for structured
results and passthrough behavior.
2.2 - Compile, Validate, Then Commit: The Native sty conf Pipeline
Decision date: 2026-02-18; the production contract was finalized on 2026-08-14.
Status: Implemented and released in pig v1.8.0.
Current reference:pig sty conf
Scope: Generating one validated static Inventory from a trusted Pigsty template; not arbitrary YAML transformation.
Decision
pig sty conf should behave like a small compiler: resolve one safe template, parse it, apply a
bounded set of structural mutations, validate the complete candidate, and atomically commit the
output only after every required stage succeeds.
The command does not invoke the legacy configure script and does not fall back to raw shell
execution. Its structured result reports selected inputs, effective choices, applied change kinds,
and warnings without returning generated secret values.
Context
Template configuration looks simple until paths, symlinks, multiple IP placeholders, version-pinned templates, mirrors, proxy environments, generated credentials, and partially valid YAML interact. A text replacement pipeline can cascade IP substitutions, rewrite unrelated domains, leak secrets, or truncate the destination after a late validation failure.
The output Inventory may contain administrative credentials, so both file handling and result rendering are part of the security boundary.
Alternatives considered
- Call the existing shell configure script. Rejected because parsing, validation, and result semantics would remain outside PIG’s control.
- Use global search and replace. Rejected because IP and domain values need exact placeholder boundaries and simultaneous mapping.
- Write first and validate afterward. Rejected because a failed candidate could replace a usable Inventory.
- Accept arbitrary absolute templates. Rejected because the command should compile known Pigsty modes, not become a privileged file copier.
- Return generated passwords for convenience. Rejected because structured logs and agent traces are not secret-delivery channels.
Contract
- templates resolve below the Pigsty configuration tree through safe relative names;
- absolute paths, traversal, path escape, and direct, symlink, symlinked-parent, or hard-link source/output aliasing are rejected;
- parsing and IP-collision checks precede external preflight;
- placeholder IPs are mapped simultaneously and unrelated addresses remain unchanged;
- domain replacement matches the exact template token;
- profile, region, proxy, locale, and PostgreSQL-version changes are structural and bounded;
- generated credentials use one random value per known identifier and expose only identifiers in results;
- the complete candidate receives native validation and optional bounded Ansible parsing;
- any failure leaves the destination untouched;
- success writes atomically with mode
0600.
Consequences
Use sty conf to generate a new Inventory from a known template. Use the lossless
pig inventory workflow to edit an existing Inventory.
Version-pinned templates keep their version and warn when a conflicting version request cannot apply.
Verification and evolution
The native configure direction was first recorded on 2026-02-18. The production refinement landed with
74e084e, and the final contract synchronization
followed in adc4260. Tests cover traversal and
aliasing, simultaneous IP mapping, domain boundaries, interactive and closed-input selection,
version handling, proxy and region changes, secret generation and redaction, preflight ordering,
validation failures, permissions, and atomic writes.
Current status
Use pig sty conf to generate a new Inventory from a Pigsty template and
pig inventory to inspect or edit an existing declaration. Current flags, modes,
and preflight behavior live in the pig sty reference.
2.3 - The 70% Tuner: Defining the Boundary of pig pg tune
Decision date: 2026-03-21
Status: Released in pig v1.3.2, following implementation on 2026-03-23.
Current reference:pig pg tune
Scope: Generate a starting configuration from hardware, PostgreSQL version, and workload profile.
Decision
pig pg tune calculates core PostgreSQL parameters and prints them for review. It detects CPU,
memory, and disk capacity, accepts explicit overrides, and applies a selected workload profile.
Text output displays the generated parameters; JSON and YAML output include the inputs and parameters.
Review the values and select the settings to apply through your configuration system.
The original “70% tuner” name describes a practical starting point. It is not a measured accuracy score.
Context
A fresh installation needs an initial configuration before workload measurements are available. One static configuration cannot fit both a small development machine and a large database server. Hardware-based formulas provide a repeatable baseline that the operator can inspect and adjust.
Alternatives considered
- Ship one fixed configuration. Memory and parallelism settings need to scale with the host.
- Build an adaptive tuner. This would require workload data, experiments, and a feedback loop.
- Apply settings automatically. The operator needs to review the generated values and choose how to deploy them through the existing configuration workflow.
- Calculate every PostgreSQL parameter. Replication, security, and availability settings also depend on requirements that hardware detection cannot determine.
Contract
- Use the detected hardware or the operator’s explicit CPU, memory, and disk values.
- Select formulas through
oltp,olap,tiny, orcrit. - Produce the same parameters for the same resolved inputs and PostgreSQL version.
- Include the resolved profile, hardware, and PostgreSQL version in structured results.
- Print text parameters in a stable order and identify the SSD assumption in the header.
- Validate input ranges and omit parameters unavailable in the selected PostgreSQL version.
- Leave configuration files and the running server unchanged.
Consequences
Operators can use the output for a new installation or initial sizing. Review the values, apply them through the configuration system in use, then measure the workload. Query concurrency, checkpoint behavior, storage latency, and replication requirements guide later adjustments.
Verification and evolution
The initial implementation is
60eecfe.
The v1.3.2 release introduced parameter generation.
The current implementation
returns a result for rendering. Tests in
tune_test.go
cover workload formulas, resource limits, overrides, and version-dependent parameters.
Current status
Parameter generation is released.
See the pig pg reference for inputs and output examples.
2.4 - Why PIG Keeps the Cobra Command Layer Flat
Decision date: 2026-06-30
Status: Implemented; the repository uses this layout for new commands.
Current reference:pigcommand overview and the source repository
Scope: Go source ownership and command registration, not the public command taxonomy itself.
Decision
The cmd package stays flat. One top-level command belongs in one top-level Go file: pg.go,
pb.go, pt.go, pe.go, sty.go, do.go, repo.go, and their peers. Even large command trees
remain in that entry-point file unless there is an explicit decision to change the layout.
The file may be long, but it should contain Cobra concerns: names, aliases, annotations, flags,
argument validation, help, registration, and option mapping. Concrete work belongs in cli/*,
internal/*, or another implementation package.
Context
Earlier command growth produced many small files named after subcommands and several parallel implementations of confirmation, structured output, plan rendering, and legacy wrapping. It became difficult to answer simple questions: where is a top-level command registered, which file owns an alias, and whether two helpers implement the same policy.
PIG’s command families are large, but their public grammar is one surface. Keeping that grammar in one place makes review and collision detection easier, while implementation packages remain decomposed by responsibility.
Alternatives considered
- A directory per command under
cmd. Rejected for normal commands because it scatters one public grammar across many packages and encourages business logic near Cobra. - One file per subcommand. Rejected because registration, aliases, and inherited flags become hard to audit as one contract.
- Put everything in
cmd. Rejected because tests, reuse, and error handling suffer when operational logic depends on Cobra state. - Abstract every repeated line. Rejected because speculative frameworks can hide the command grammar; only stable, cross-command glue should be shared.
Contract
cmd/root.goowns root setup, global flags, and top-level registration;cmd/utils.goowns shared command-layer helpers;- each normal top-level command has one matching top-level source file; matching and focused test files may accompany it;
- Cobra code validates syntax and maps options, but does not perform the operation;
- reusable confirmation, annotation, structured-output, and plan helpers have one implementation;
- implementation packages accept ordinary options and return typed results or errors without depending on Cobra globals.
Consequences
Some command files are intentionally large. The trade-off is accepted because the public surface can be reviewed as a unit, while the implementation remains split below it. The rule also reduces file churn when aliases or flags move and gives agents a deterministic starting point.
Review the separation of responsibilities, not file length. Operational logic belongs in the implementation packages, including logic inside closures.
Verification and evolution
The convention was recorded in
9eb70db, followed by the large command-surface
consolidation in fb93602. Guard tests check alias
collisions and command registration, while package tests exercise the implementation beneath the
Cobra layer.
Current status
This remains the repository rule for new work. Public command documentation belongs on this site; source-layout enforcement remains close to the code so contributors and coding agents encounter it before editing.
2.5 - Why PIG Builds Debug Packages by Default
Decision date: 2026-09-03
Status: Released in v1.8.1.
Current reference:pig build
Scope: Debug-package policy forpig build extandpig build pkg; individual package recipes remain authoritative for their payload.
Decision
pig build ext and pig build pkg request the platform’s normal debug-package output by default.
PIG does not pass a suppression setting during an ordinary build. Users who need the smaller or
faster artifact set opt out explicitly with --nodbg.
On RPM systems, the ordinary build leaves the distribution’s debuginfo and debugsource
machinery enabled; --nodbg defines debug_package as empty. On Debian and Ubuntu,
--nodbg adds noautodbgsym to DEB_BUILD_OPTIONS while preserving existing options. The old
-s|--symbol spelling remains accepted as a deprecated compatibility no-op because debug output
no longer needs to be enabled.
Context
The earlier command made RPM debug output opt-in with --symbol and otherwise injected
debug_package %{nil}. That inverted the platform convention and made the default build less
useful for post-crash analysis. Debian’s Debhelper already creates automatic dbgsym packages by
default when eligible, and provides noautodbgsym as the explicit opt-out.
Debug packages increase build time, storage, and repository volume, but those costs are visible and manageable. Missing symbols are much harder to reconstruct after the exact source, compiler, and binary have moved on.
Alternatives considered
- Keep
--symbolas an opt-in. Rejected because release-quality artifacts should retain the matching diagnostic material by default. - Always require debug packages. Rejected because quick local builds and constrained artifact pipelines need an explicit opt-out.
- Rewrite package recipes from PIG. Rejected because spec files and
debian/rulesown package payload details; mutating them at execution time would be surprising and difficult to audit. - Use
nostripfor DEB opt-out. Rejected because it changes the main binary instead of merely suppressing the separate automatic debug package.
Contract
- without
--nodbg, PIG adds no debug-suppression macro or environment option; - on RPM,
--nodbgadds--define "debug_package %{nil}"torpmbuild; - on DEB,
--nodbgappendsnoautodbgsymtoDEB_BUILD_OPTIONSwithout discarding existing values such asparallel=Nornocheck; --symbolremains parseable for compatibility but is hidden, deprecated, and redundant;- structured command results expose
nodbgand retainsymbolas the effective inverse value; - the normal installation package remains the build-success authority; debug packages are additional artifacts, not substitutes for it;
- pure SQL,
noarch, or otherwise ineligible builds need not emit an empty debug package; - an explicit decision inside a package recipe or an operator-supplied build environment remains authoritative. The command default is a policy request, not permission to rewrite recipes.
Consequences
Compiled extensions normally produce more files and consume more build and repository space. In
return, a default build is suitable for stack traces, core analysis, and symbol servers without a
second reconstruction build. Existing scripts that pass --symbol keep working, while scripts
that intentionally want the old reduced artifact set must move to --nodbg.
Recipe repositories should remove blanket debug suppression where it does not represent a specific package constraint. That is a separate reviewed change because some packages are architecture independent, fail debug extraction, or use custom build systems.
Verification and evolution
The superseded opt-in behavior is pinned in the earlier
build flag registration
and
rpmbuild command construction.
The replacement was implemented in
1c6f524.
Command tests keep --nodbg visible and the compatibility flag deprecated. Builder tests verify
that the default RPM argv omits the suppression macro, the opt-out includes it, and the DEB
environment preserves existing options while adding noautodbgsym once.
Platform validation should sample a compiled extension on one EL builder and one DEB builder,
checking both default debug artifacts and their absence under --nodbg. Recipe-level exceptions
must be reported separately rather than treated as proof that the PIG command ignored its option.
Current status
Released in v1.8.1. See the current reference linked above for usage and platform requirements.
2.6 - One Grammar for Dangerous Work: PIG's Operations CLI Safety Contract
Decision date: 2026-07-02
Status: Released forpg,pb,pt, andpitrby v1.5.0; the 2026-08-29doandbuild proxyrefinements were released in v1.8.1. The acceptance refinements below are Implemented for v1.10.0; source evidence is listed under verification. They are not yet released.
Current reference:pig pg,pig pb,pig pitr,pig do, andpig build
Scope: PIG-owned operational commands; transparent upstream commands retain upstream confirmation and exit behavior.
Decision
Operational convenience must not blur operational meaning. PIG distinguishes low-level primitives from multi-stage orchestrators, makes destructive intent explicit, reserves aliases carefully, and requires plans and structured results to describe the same action that text mode will execute.
The most important example is recovery: pig pb restore is the pgBackRest primitive, while
pig pitr coordinates Patroni, PostgreSQL shutdown, restore, restart, and post-recovery guidance.
An alias must never make those two paths look interchangeable.
Context
The first generation of convenience aliases accumulated inconsistent positional arguments,
confirmation flags, output handling, and service semantics. Similar words such as restart,
restore, promote, and failover can refer to very different layers. A short alias that crosses
those layers can turn a harmless-looking invocation into an unmanaged destructive primitive.
Automation also exposed false-success risks when wrapper output, subprocess output, and result rendering used different definitions of success.
Alternatives considered
- Maximize shorthand aliases. Rejected because collisions and cross-layer synonyms are more dangerous than a few saved characters are valuable.
- Put confirmation on every risky-looking word. Rejected for passthrough commands because the upstream tool must own its prompt and semantics.
- Make the orchestrator call a convenience alias of the primitive. Rejected because recovery coordination has additional stop, verification, and restart invariants.
- Return success after launching the inner command. Rejected because the result must reflect the complete owned workflow.
- Restrict maintenance database names to ASCII identifiers. Rejected because spaces and non-ASCII names are valid inputs. Reject libpq connection-string syntax instead, and preserve the positional boundary when generating commands.
Contract
- sibling command names and aliases are unique;
- an alias cannot shadow a different top-level command;
- destructive PIG-owned operations require explicit confirmation and support non-mutating plans where a meaningful plan exists;
- command-layer validation rejects malformed or extra positional arguments before side effects;
- command-specific names mirror the downstream Pigsty contract, or use the narrowest documented safe boundary when the downstream playbook has no explicit grammar;
- structured output and text mode share one result and one success definition;
- credential-bearing values stay out of diagnostics, and readiness or connectivity failure remains a command failure rather than a logged warning followed by success;
- low-level restore does not claim to manage Patroni or HA routing;
- the PITR orchestrator stops the manager when required, proves PostgreSQL is stopped, restores, optionally starts PostgreSQL, and deliberately leaves Patroni stopped for operator verification;
- native tools receive extra arguments only through an explicit, documented boundary.
The 2026-10-16 to 2026-10-17 refinements apply the same boundary to the v1.10.0 candidate:
- Cross-user DBSU writes stage an exclusively created private sibling, use mode
0600and the executing DBSU’s ownership, reject symlink/non-regular destinations, replace the exact path, and clean staging on failure. Linux uses an exact-target rename; macOS uses the system Perlrenamesyscall because BSDmvhas directory-target semantics. repo rmvalidates the whole operand list before changes. Only zero operands mean full backup;allremainsnode,pgsql, andinfra.requested_modulesretains the original request;removed_reposdescribes the expanded actions.repo add,repo set, andrepo infoalso reject explicit empty names and comma-separated empty entries as a whole request. Only omitted operands retain the add/set default ofall. Add/set also validate module-name syntax before initializing the repository manager. Unsafe names reject the whole request; syntactically valid unknown names retain additive partial success, while replacement rejects them before changes.- With an explicit
pg -D, SQL operations and database enumeration bind to that directory’s recorded port and socket. Ambiguous metadata fails before execution. Omitting-Dpreserves native client connection defaults;/pg/dataremains the default for instance operations. Explicit empty or whitespace-only-Dvalues fail before configuration or operational work. Plans, confirmation retries, and verification commands preserve the same target and operation options, including an explicit-D /pg/data.VACUUM FULLplans require confirmation, as execution does. The 2026-10-17 maintenance refinement rejects connection-string database operands before plans, confirmation, or execution, without echoing the supplied value. A libpq connection string could otherwise override the selected host/port and expose credentials.vacuum,analyze, andfreezevalidate the complete enumerated database list before any maintenance starts. Generatedvacuumandrepackcommands place all options before--and the database name, preserving a name such as--allas a single-database operand. - Fork replacement requires matching metadata
with an explicit target for nonempty unmanaged directories, including non-PGDATA directories.
Empty destinations remain usable; managed forks must be replaced by name. Private paths are
resolved as DBSU, and unresolved aliases fail closed. The 2026-10-17 review removes the extra
/pg/dataprohibition: eligibility depends on target ownership, source/destination relationships, and runtime state. A conventional path cannot identify every primary and may be a legitimate fork target. Forced cleanup of managed orphan directories remains supported. For unmanaged removal, a permission-denied local path check retries as the selected DBSU; it must establish that the target is a directory and not a symlink before deletion can proceed. EPERMalone must not authorizepg init --forceor PITR restore. Independent executable identity may establish PID reuse; unavailable identity remains unknown. A live PID must identify PostgreSQL before lifecycle commands may signal it or connection metadata may be used for SQL. Unknown state carries no usable PID for force-stop escalation. Fork start must not persist success in that state; list output reportsunknownandruntime_unknown: true. Role detection also fails on an unknown running state; file-based role evidence cannot override a confirmed stopped state. Forced initialization reports probe failures separately from a running conflict. Plan preconditions report indeterminate runtime state asunknown, never a passed check with PID zero. Status queries distinguish permission failures (130201, exit3) from other probe failures (130808, exit1); partial data in either failure cannot establish that the instance is stopped.- Timeline reporting binds SQL to the selected data directory’s valid PID metadata and socket.
If that cannot be resolved, it uses that directory’s
pg_controldataor reports an unknown timeline. Promotion execution and the requirement to verify the primary role stay unchanged. - PITR cancellation and EOF return confirmation-required (
161001, exit7) before service stops, restore, or restart. Acceptance must execute the confirmation path and observe zero lifecycle side effects. PIG_NON_INTERACTIVEand structured execution disable prompt stdin and add sudo-n, including legacy structured wrappers. Native passthrough and explicit data stdin retain their contracts.- Sensitive captured output and error details remain private. Signing-key load errors never echo the supplied key. Explicit raw exports remain available on their documented text surfaces.
Consequences
Some historical shorthand disappeared and some scripts had to adopt cluster-first or explicit target syntax. In return, command names now preserve layer boundaries, plans correspond to real actions, and recovery automation cannot silently substitute a primitive for the orchestrator.
Plans show the affected resources and actions so operators can review recovery before execution.
Verification and evolution
Fixed source commits and regression tests for the committed v1.10.0 refinements cover:
runtime identity and SQL targets,
fork ownership and private paths,
PITR cancellation and unknown state,
plan target preservation,
status error classification. These commits do not establish a release boundary.
The later maintenance database-name and -- operand boundaries
include Cobra argument-reparse tests and a real libpq target-boundary regression test.
The repository operand preflight rejects
unsafe module names before key preparation or repository writes and preserves partial additive
results for syntactically valid unknown modules.
The normative command specifications entered the repository in
c62c0f5. Subsequent commits aligned aliases,
early validation, restore targets, service semantics, and role detection. Guard tests traverse the
Cobra tree to reject sibling and cross-layer alias collisions. Recovery tests cover plan,
confirmation, stop escalation, side restores, restart behavior, and structured failure results.
Maintenance regression checks must reparse generated commands with Cobra and exercise the real
libpq client against controlled local endpoints; checking for -h and -p in argv alone is insufficient.
Patroni later moved to transparent passthrough. That refinement keeps the same safety principle: PIG owns safeguards only for workflows it owns.
The same contract was applied to pig do name and cluster validation in
3e1603b,
with Ansible built-in targets closed in
a880485.
Package-backed, credential-safe, truthful build proxy setup entered in
220ef9c,
followed by structured-argument redaction and corrected machine annotations in
74cb128,
and optional operands were reflected in the machine grammar in
de7ffd0.
The changes were exercised on Ubuntu 24.04 and Rocky Linux 9 ARM64 Farrow guests, then released
from source commit 1c6f524
after the v1.8.1 CI run passed.
Current status
Use pig pb restore when you intentionally want the pgBackRest primitive and pig pitr
when you want the managed recovery workflow. See the command reference pages for current syntax and platform requirements.
2.7 - Edit the Declaration, Preserve the Document: Lossless Pigsty Inventory
Decision date: 2026-07-18
Status: Implemented and released in pig v1.6.0. The 2026-10-16 to 2026-10-17 refinements below are Implemented in the v1.10.0 candidate, not yet released.
Current reference:pig inventory
Scope: Static Pigsty Inventory inspection, scoped editing, validation, comparison, and safe writes.
Decision
PIG treats pigsty.yml as both a semantic declaration and a human-maintained source document.
Semantic parsers determine what the Inventory means; the original bytes remain authoritative for
how it is written. Scoped edits replace bounded source ranges and then reparse the complete
candidate before an atomic write.
This avoids a common YAML-tool failure: a logically correct edit that silently rewrites comments, key order, quoting, anchors, block scalars, or line endings across the entire file.
Context
Pigsty Inventories are long-lived operational assets. They contain topology, tuning, credentials, comments, examples, anchors, and locally meaningful ordering. A conventional parse-mutate-serialize cycle can produce a valid but unreviewable diff and may change constructs the operator never selected.
At the same time, raw text editing without semantic validation can put invalid or contradictory configuration on disk. The design needed source fidelity and whole-document correctness together.
Alternatives considered
- Round-trip through one YAML serializer. Rejected because no selected serializer preserved the full source contract byte-for-byte across the real Pigsty corpus.
- Use regular expressions for YAML. Rejected because quoting, comments, aliases, block scalars, and nested collections make text-only semantic decisions unsafe.
- Edit only a normalized generated copy. Rejected because the active Inventory is operator-owned and would still diverge from the generated representation.
- Allow every node type to be replaced. Rejected because anchors, aliases, tags, and block scalars need stricter handling than ordinary mappings and scalars.
Contract
- duplicate keys and multi-document YAML are rejected;
- selectors address one unambiguous declaration fragment;
- semantic decoding and source-range discovery are separate concerns;
- an edit starts from the exact source revision and fails if the file changes concurrently;
- the edited fragment is normalized only as required for its insertion context;
- the complete candidate is reparsed and validated before commit;
- writes use a same-directory temporary file, sync, rename, and directory sync;
- symlink and unsafe path changes are rejected;
- a successful edit removes group and other permissions, preserving the owner’s existing read and write permissions;
- diagnostics, diffs, plans, and structured results omit declaration values unless a command is explicitly a raw text surface.
The 2026-10-16 acceptance refinement preserves role-name strings and structured role grants in
pg_users[].roles. Editing, serialization, and CMDB export must preserve YAML 1.1 string semantics,
including "1:30"; "010" is a regression control, not a claim of an earlier defect.
The 2026-10-17 refinement also requires dates and timestamps supplied as strings to remain strings
when loaded by PyYAML. Existing timestamp values retain their source bytes as opaque scalars;
this does not add date arithmetic or normalize the document. Acceptance compares emitted types
with an independent YAML loader, rather than relying only on PIG’s own round trip.
sty deploy and do consume the configuration layer’s already resolved
Inventory path. Flag and environment relative paths use the caller’s cwd, quoted ~/ uses the
user’s home, and defaults remain explicit at execution. Missing sources do not fall back.
Static inspection still never executes dynamic sources; Ansible retains its execution boundary.
Consequences
The editor is more complex than ordinary YAML marshaling, and some syntactically valid fragments are deliberately refused when source fidelity cannot be proven. The benefit is a reviewable diff: unselected parts of the Inventory remain byte-for-byte stable, invalid YAML cannot be committed, and a concurrent edit cannot be overwritten silently.
Inventory can contain custom credential fields, so field names alone cannot reliably identify secrets.
For this reason, show prints the selected declaration as raw text. Metadata and validation commands omit declaration values.
Verification and evolution
Fixed source commits and regression tests for the committed v1.10.0 refinements cover: resolved sources and role grants, date-like string preservation, independent YAML consumer acceptance. These commits do not establish a release boundary.
The root Inventory contract and existing-CMDB boundary were established in
ba6e678, with the implementation landing in
ea43858. Tests exercise real Pigsty configuration
corpora, byte-identical round trips, scoped replacement, protected YAML forms, concurrent-change
rejection, atomic-write failures, selectors, validation, and secret-free diagnostics.
Later refactors removed legacy options and separated validation stages without changing the source-fidelity model.
Current status
The static Inventory remains the primary declaration surface. Use the current
pig inventory reference for selectors, validation profiles, structured output, and
the explicitly experimental CMDB bridge.
2.8 - Use the CMDB Pigsty Already Has
Decision date: 2026-07-18
Status: Released in v1.6.0 as an experimental adapter. The earlier revision-store design is superseded.
Current reference:pig inventory cmdb
Scope: Exchanging declarations with Pigsty’s existing CMDB, not designing another configuration database.
Decision
PIG must reuse the CMDB already provided by Pigsty. Its responsibility is a bounded adapter: validate a static Inventory, load declarations into the existing tables, dump the existing projection, check consistency, and switch Ansible between the static and dynamic sources safely.
PIG does not own a second schema, migration history, snapshot ledger, compare-and-swap revision store, three-way merge engine, or rollback database.
Context
An early design treated CMDB support as a greenfield backend. It proposed a separate schema,
immutable snapshots, revision tokens, merge and rollback operations, backup bundles, and source
switch records. The design was internally coherent but started from the wrong premise: Pigsty
already had the pigsty and pglog schemas, load scripts, dynamic Inventory projection, and source
switching behavior.
Building a parallel control plane would duplicate facts, create synchronization problems, and make PIG responsible for a data model owned by another project.
Alternatives considered
- Keep the new revision store as an advanced mode. Rejected because two authorities are still two authorities, even if one is optional.
- Mirror between the new and existing schemas. Rejected because conflict resolution and migration would become permanent product responsibilities.
- Hide the existing scripts behind a shell wrapper. Rejected because PIG needs bounded timeouts, safe connection handling, structured plans, and atomic source switching.
- Remove CMDB support entirely. Rejected because a small native adapter adds useful validation and automation without redefining the schema.
Contract
- Pigsty’s existing schema and projections are the data-model authority;
- PIG connects through an explicit database target, environment configuration, or
service=meta; - credentials, DSNs, SQL bodies, and declaration values never enter plans or diagnostics;
checkis read-only;initreplaces thepigstyandpglogschemas from the version-matched baseline and requires confirmation; back up an existing database first;loadreplaces declaration rows transactionally and requires explicit confirmation;dumprefuses an unexpected overwrite unless forced;enableanddisableedit only recognized Ansible Inventory source forms and write atomically;- unfamiliar executable Inventory sources are refused rather than rewritten;
- the entire command family remains labeled experimental.
Consequences
The correction removed the parallel revision-store implementation and its maintenance burden.
The remaining adapter is smaller, easier to audit, and compatible with existing Pigsty operations.
It also inherits the limits of that system: init needs an operator-managed backup, and loading a
declaration set is a replacement operation rather than collaborative version control.
Verification and evolution
The corrected boundary was recorded in
ba6e678. The abandoned implementation was removed
in e0f73ed, deleting the parallel schema, snapshot,
merge, revision, and rollback machinery. Tests for the retained path cover PostgreSQL compatibility,
connection redaction, transaction failures, digest-pinned confirmation, dump safety, and atomic
source switching.
Current status
The existing-CMDB adapter shipped in v1.6.0 but remains experimental.
Back up CMDB state before initialization or replacement. See the
pig inventory reference for the supported workflow.
2.9 - A Bounded Grafana Client Instead of Dashboard Shell Scripts
Decision date: 2026-07-18
Status: Released in v1.6.0; dashboard schema v2 support followed in v1.6.2.
Current reference:pig sty grafana
Scope: Dashboard import, export, cleanup, and selected organization and user preferences.
Decision
PIG uses a native HTTP client to manage Grafana dashboards. Local JSON paths select a dashboard, a folder, or a complete dashboard directory. This gives load, dump, and cleanup a common selection model and lets users preview destructive work.
The default directory is the Pigsty dashboard bundle. Users can select another compatible directory.
Cleanup normally selects dashboard UIDs declared by the local files; explicit clean --all selects
all dashboards and folders in the active Grafana organization.
Context
The previous shell scripts depended on local file layout and offered limited detail about partial failures. Moving these operations into PIG makes timeouts, authentication, path validation, and results consistent. A local declaration also provides a precise default cleanup scope.
Alternatives considered
- Keep shell scripts as the public interface. Network limits, redaction, and structured results would remain split across scripts.
- Expose arbitrary Grafana API calls. PIG only needs dashboard operations and a few preferences.
- Select cleanup targets by folder name. Names can collide. The selected JSON files provide dashboard UIDs; folders are removed only after they are empty.
- Embed a default password. Credentials belong in user configuration.
Contract
- Limit request duration and response size, and reject unsafe redirects.
- Check public health before authentication.
infocan return health alone when no password is set. - Resolve credentials from explicit inputs, environment, or Inventory; omit them and response bodies from diagnostics and structured results.
listlists all dashboards in the active organization.loadvalidates and imports the selected local files without deleting live dashboards.bootselects the existingpigstydashboard as home, stars it, and names the organization Pigsty.initloads a complete dashboard directory and runsbootonly after every load succeeds.dumpexports the selected remote scope as deterministic JSON with atomic file writes.cleandeletes locally declared UIDs and then empty folders.--allexplicitly selects the entire active organization. Both modes show a plan and require confirmation.langandstyleupdate the selected preference for the organization and current user. Styleautomaps to Grafana’ssystemvalue.- Normalize supported dashboard schema v1 and v2 representations when reading and writing them.
Consequences
Load and cleanup use the same local declarations, so users can operate on one dashboard or folder.
A matching UID identifies the target; it does not prove that PIG originally created it. Users must
review the cleanup plan, especially when selecting --all.
Datasource provisioning, plugin installation, and user administration remain in Grafana’s own tools.
Verification and evolution
The native workflow landed in
3060485. Dashboard schema v2 support followed in
67f6e3b.
The released tests
cover health-only operation, authentication, load scopes, bootstrap ordering, export stability,
preference updates, local UID cleanup, explicit full cleanup, and changed-plan rejection.
HTTP-client tests cover timeouts, redirects, response limits, and redaction.
Current status
The dashboard workflow is released. See pig sty grafana for path selection,
credentials, and cleanup examples.
2.10 - Let Patronictl Speak for Itself
Decision date: 2026-07-21
Status: Implemented and released in pig v1.6.0.
Current reference:pig pt
Scope: Patronictl-backed cluster commands plus PIG-owned configuration selection, settings sugar, service, status, and log helpers.
Decision
pig pt is a transparent launcher for the installed patronictl. PIG selects the configuration
and dispatches a small set of local helpers. Every other command token and all following arguments
are passed unchanged, with native prompts, terminal behavior, output formats, and exit codes.
PIG no longer maintains a copy of Patronictl’s evolving command tree.
Context
Mirroring Patronictl required PIG to reproduce commands, options, positional grammar, confirmation,
formatting, and version-dependent behavior. That surface changed upstream and PIG’s copy drifted.
Users could receive different semantics depending on whether they called patronictl directly or
through PIG.
The wrapper still adds value in a Pigsty environment: selecting the correct config as the database operating-system user, providing local service and log workflows, and translating a small settings operation into one native edit-config call.
Alternatives considered
- Continue mirroring every upstream command. Rejected because it guarantees lag and duplicates validation that Patronictl already owns.
- Allow only a tested command allowlist. Rejected because new upstream commands would remain unavailable until a PIG release.
- Capture native output into PIG JSON. Rejected because it breaks interactive editing, streaming, prompts, terminal fidelity, and upstream schemas.
- Remove
pig ptentirely. Rejected because deterministic config selection and local Pigsty helpers remain useful.
Contract
- the first non-option command token determines local dispatch or passthrough;
set, local service shortcuts,status, andlogare PIG-owned;- all other commands and remaining tokens are forwarded verbatim;
pig pt -- COMMAND ...bypasses a local-name collision explicitly;- wrapper-level options must precede the native command token;
- native help can run without resolving a local Patroni configuration;
- Patronictl owns interactive prompts, native
--format, and exit codes; - global PIG structured output is rejected where it would consume a native option ambiguously;
- the selected config is resolved predictably and the process runs as the database system user.
Consequences
Automation had to adopt Patronictl’s cluster-first positional grammar and native output flags. Some PIG-only aliases and result schemas disappeared. In exchange, new Patronictl features work without a PIG release and behavior no longer depends on a lagging wrapper implementation.
The local set helper remains intentionally small: it classifies scalar Patroni keys and
PostgreSQL parameters, then performs one native edit-config action.
Verification and evolution
The rewrite landed in
6cbc23b. Tests cover token-boundary parsing,
verbatim argv preservation, config precedence, database-user execution, native exit propagation,
help without configuration, output-mode rejection, the -- escape, and local-helper collisions.
The final help-path refinement landed before v1.6.0.
Current status
Use Patronictl’s own documentation for forwarded command grammar and pig pt for PIG’s
config selection and local helpers. For JSON output from a forwarded command, use Patronictl’s native --format json option.
2.11 - PIG 2.0 Product Direction
Decision date: 2026-08-13
Status: Proposal for review; not implemented.
Current reference: PIG documentation and release history
Scope: Candidate product boundaries and verification gates for a future PIG 2.0 / Pigsty 5.0 line.
Decision
The proposed direction makes PIG the stable onboarding front door from an empty controller to a validated, deployable Pigsty Inventory. PIG would own Catalog selection, resolution, plans, bounded execution orchestration, structured results, and redacted receipts. It would continue to delegate package transactions, configuration application, and infrastructure state to DNF/APT, Ansible, and future provider-specific tools.
The proposal deliberately preserves PIG’s standalone value: repo, ext, and install must work
without a Pigsty project. It also preserves explicit deployment consent: a future pig sty setup
may download, bootstrap, and configure, but it must stop before multi-node deploy unless the user
invokes deployment separately.
Context
By v1.8.0 PIG could download releases, bootstrap a controller natively, compile Inventory, manage repositories and extensions, and run selected operations. Several product seams remained:
- repository, package-alias, extension, route, and Pigsty metadata could change independently;
- projects had no explicit Catalog identity to protect later resolution from global updates;
- route choice and repository safety were not one visible product contract;
- execution results did not yet form a durable, redacted receipt across the onboarding path;
- compatibility among PIG, Pigsty, Catalog schema, operating systems, and Ansible needed one release matrix rather than separate assumptions.
The proposal focuses 2.0 work on metadata consistency and a repeatable setup workflow.
Alternatives considered
- Turn PIG into a monolithic configuration and state engine. Rejected because Inventory, Catalog authoring, package managers, Ansible, and providers already own different facts.
- Make Pigsty depend on a live PIG or pgext checkout. Rejected because a Pigsty release must remain independently usable from generated, versioned artifacts.
- Make setup deploy automatically. Rejected because creating and validating configuration is a different consent boundary from changing remote nodes.
- Reimplement DNF/APT failover or Ansible execution. Rejected because PIG should select inputs and explain results, not become another package manager or configuration engine.
- Block 2.0 on Vagrant/Terraform unification. Rejected because lab providers have different state semantics and do not determine the core onboarding path.
- Invent a universal
sty planimmediately. Rejected until at least two owned workflows prove that one reusable plan schema exists.
Contract
If accepted, the product direction would enforce these boundaries:
- each fact type has one authority: Inventory for cluster declarations, Catalog authoring sources for product metadata, project lock for selected snapshot identity, receipts for observed results, and providers for live state;
- PIG owns Catalog schema, validation, client, resolver, and selection, but not every authoring database;
sty setupcomposes existing init, boot, and configure use cases instead of duplicating them;- setup stops after a validated Inventory; deploy remains explicit;
- standalone commands follow a compatible Catalog channel, while a Pigsty project pins its selected snapshot after a successful setup or configuration commit;
- ordinary commands never rewrite an existing project lock implicitly;
- route selection is explicit or a bounded first-run decision, not a continuous GeoIP, cloud-IMDS, or background-latency service;
- package download retry and endpoint failover remain owned by DNF/APT;
- execution artifacts are versioned and redacted; raw upstream modes preserve native streams and exit behavior;
- doctor remains diagnostic and does not gain default repair authority;
- future lab support is a thin adapter and never makes PIG the owner of Terraform state.
Consequences
The proposal creates a clearer first-run story and makes metadata selection auditable. It also adds new durable contracts: snapshot identities, project locks, migration rules, trust policy, receipts, and compatibility matrices. Those contracts increase the testing and release burden and must not ship as loosely coupled features.
An Ansible event bridge depends on redaction and compatibility tests. Doctor/support bundles and lab adapters are deferred until after the initial release. The EL7 support level remains open.
Verification and evolution
This proposal requires evidence before it can become a release contract:
- a native onboarding VM matrix across the declared Linux targets;
- adversarial Catalog signature, expiry, rollback, mix-and-match, and offline tests;
- semantic-diff proof that generated Pig, Pigsty, and pgext consumers do not drift;
- an Ansible callback experiment with zero
no_logor secret leakage; - route-selection tests for global, China, proxy, and restricted-network environments;
- repository-signing tests before secure defaults are changed;
- rehearsed 1.x-to-2.0 layout, lock, and mixed-version migration;
- schema and structured-output fixtures tied to an explicit compatibility matrix.
The implementation baseline used for this proposal is
v1.8.0.
That release contains native boot and configure, but it does not implement the proposed Catalog v2,
project pin, setup command, event receipt, or 2.0 migration contract.
Current status
The proposal remains open. Decisions are still needed for Catalog security, overlays, paths, EL7 support, and the Ansible event bridge. Use the current documentation for released commands.
2.12 - Catalog v2 Proposal: Immutable Typed Snapshots
Decision date: 2026-08-13
Status: Proposal; security mechanism, overlays, packaging, and path layout remain open.
Current reference:pig extandpig repodescribe the v1 Catalog behavior.
Scope: A candidate PIG 2.0 publication and consumption model for product metadata, not Inventory or live system state.
Decision
Catalog v2 should be one immutable, verifiable snapshot composed of multiple typed targets. A manifest binds platform, repository, route, package-alias, extension, compatibility, Pigsty release, and public-key metadata to exact bytes. Candidate targets are validated together and activated through one pointer, preventing a new repository catalog from being mixed silently with an old extension matrix.
The snapshot digest is its identity. Package, system, user, portable, and project scopes store or select the same verified content; they do not merge unrelated base snapshots into a synthetic Catalog.
Context
The v1 Catalog is practical but spreads related facts across embedded CSV, repository YAML, Pigsty variables, generated sites, and reload paths. Some fields repeat derived information, and the extension matrix compresses several independent identities into one record. Independent updates make it difficult to prove that repository, package, extension, and compatibility data belong to the same publication event.
Catalog v2 must define how related data is published, verified, and activated together.
Alternatives considered
- Create a larger
extension.csvor one giant YAML file. Rejected because unrelated target types evolve differently and cannot be activated or streamed independently. - Use SQLite, protobuf, or a custom binary matrix immediately. Rejected because the current dataset has not demonstrated a performance need that justifies a new runtime and debugging cost.
- Merge system, user, and project base snapshots field by field. Rejected because the result has no single publisher, digest, compatibility statement, or signature.
- Store active or project-pinned content only in a cache. Rejected because deleting a cache must not destroy a durable user or project decision.
- Let a user file shadow the official trust root. Rejected because security policy is a constraint, not an ordinary last-writer-wins preference.
- Silently update and activate in the background. Rejected because metadata changes can alter package resolution and must be an observable operation.
Contract
The proposed snapshot contract is:
- deterministic UTF-8 JSON for manifests and small targets, and JSONL for large sparse targets;
- raw manifest bytes and target length/hash are verified without parse-and-reserialize ambiguity;
- manifests carry schema, monotonic security version, creation, expiry, channel, and PIG/Pigsty compatibility;
- an embedded rescue baseline is always available;
- package-owned baselines, durable snapshot stores, mutable state pointers, and purgeable download caches are separate paths;
- Linux follows FHS/XDG, macOS uses Application Support and Caches, and portable
PIG_HOMEkeeps config, data, state, cache, and run roles distinct; - a project lock records snapshot identity and ordered overlays, while the verified snapshot is materialized into durable project support data;
- selecting a digest and finding its bytes are separate algorithms;
- system security policy can only be tightened by lower scopes, not weakened silently;
- updates download into private staging, verify every layer, sync, move into a content-addressed store, and atomically replace the active pointer;
- failures retain the previous active snapshot;
- project pins do not move when user or system active channels update;
- offline export includes verification metadata and public trust material, never private keys;
- old
ext reloadandrepo reloadmay map to one whole-snapshot update for one compatibility period, but cannot activate targets independently.
The runtime Catalog excludes Inventory, credentials, live probes, installed-package state, Ansible events, provider state, confirmations, and metrics that change without a product decision.
Consequences
Typed targets make ownership and validation clearer, and content addressing makes rollback and airgap import auditable. Project materialization prevents a deployment from depending on one user’s global cache. Independent OS packages can refresh a read-only baseline without changing an active user selection.
The cost is a larger release protocol: key rotation, expiry, rollback protection, garbage collection, path permissions, migration, package-manager lifecycle, overlay conflicts, and cross-repository generators all become compatibility-sensitive work.
The extension model must also separate SQL extension identity, upstream project, distribution or
build unit, versioned release, OS package offer, target availability, and display policy. Derived
fields such as aggregate platform support or required_by should be generated, not maintained as a
second truth.
Verification and evolution
Before implementation, the proposal requires an ADR to choose between go-tuf and a minimal signed manifest. Both candidates must pass the same threat tests: bad signatures, expired metadata, rollback, target substitution, mix-and-match snapshots, truncated downloads, and offline verification. If neither passes, Catalog v2 cannot be a 2.0 release feature.
Additional gates cover FHS/XDG/macOS/portable paths, root and non-root permissions, read-only homes and projects, symlink replacement, disk-full and concurrent activation, package upgrade/remove semantics, project survival after global-cache deletion, and parity migration of the current extension and availability corpus.
The proposal was based on
v1.8.0.
v1.9.0 still uses the embedded and independently
reloadable v1 Catalog.
Current status
Catalog v2 is not implemented. Security, paths, and overlay rules need decisions and tests first.
If overlay conflict and trust rules are not ready, a complete custom signed channel can provide
the initial customization path. Current usage is documented under pig ext and
pig repo.
2.13 - One-command Xray Clients and Servers
Decision date: 2026-10-05
Status: Released in v1.9.0. The 2026-10-16 refinements below are Implemented in the v1.10.0 candidate, not yet released.
Current reference:pig build, operations safety, and release history
Scope: One-command Xray client and server setup; Linux clients and servers, plus a macOS client. Shared Nginx ingress remains a separate deployment boundary.
Decision
Extend pig build proxy with explicit client and server subcommands. Use VLESS over RAW,
REALITY, and xtls-rprx-vision for the new workflow. First server setup generates matching credentials;
repeated setup preserves the existing client connection contract and offers the same standard URI.
The client takes a URI or explicit command-line parameters,
installs Xray, configures the local listener, starts its service, and verifies the connection.
A URI can be pasted directly or read from a file or stdin.
Retain the existing command path and x alias. The zero-argument command installs or verifies
Xray. The historical id@host:port [local] form retains its VMess meaning and default port during
a compatibility period, through the existing V2Ray workflow.
Context
The previous implementation
installs vray, writes an HTTP-to-VMess configuration to /etc/v2ray.json, grants the v2ray
group access, writes shell aliases, restarts v2ray, and checks an HTTPS request. Existing tests
cover argument parsing, package-manager selection, and credential redaction.
The inspected reference pair uses Xray 26.3.27. The running macOS client exposes HTTP and SOCKS on one loopback port, 8888, and uses VLESS/RAW/REALITY/Vision with a Chrome fingerprint, disabled multiplexing, and ML-DSA-65 verification. Both HTTP and SOCKS requests succeeded during the review. The client UUID, short ID, and SNI match the server’s corresponding fields.
The reference Linux server listens on loopback port 9443. Nginx owns public port 443 and selects
the backend by SNI, forwarding a PROXY protocol header. Xray accepts that header, connects to a
REALITY target, sends allowed traffic through freedom, and blocks destinations matching
geoip:private. Nginx provides the public entry point in this deployment.
Inspected Pigsty RPM and DEB artifacts for both architectures provide /usr/bin/xray,
/etc/xray.json with mode 0640 and ownership root:xray, an xray:xray service account,
xray.service, and geodata in /usr/share/xray. Their installation scripts reload systemd without
automatically starting or enabling the service. Public repository indexes list version
26.3.27-1PGSTY. Runtime tests are listed below.
Alternatives considered
- Rename V2Ray paths and keep only VMess. Insufficient: it does not provide server setup or the working reference protocol. The old template passes Xray’s configuration validator, but Xray emits a VMess deprecation warning.
- Build a general proxy manager. Deferred: subscriptions, protocol catalogs, TUN, transparent routing, traffic accounting, and arbitrary configuration import are outside the requested pair.
- Create a new top-level command now. Deferred: the existing
build proxyentry can hold the two roles without changing the root grammar or creating a second implementation. - Copy the reference server verbatim. Rejected: a loopback listener requiring PROXY protocol cannot serve direct public connections, and existing Nginx port ownership must be respected.
- Require a connection file for client setup. Rejected: pasting one URI or supplying parameters directly is the primary workflow; a protected file or stdin remains useful for automation.
- Print generated credentials in ordinary success output. Rejected: structured results and routine logs must remain safe to retain. An explicit export can return a URI to the terminal.
Contract
The implemented role grammar is:
Server inputs and defaults. Require the advertised --host and a REALITY --target.
Public --port defaults to 443; the direct listener defaults to that port on all IPv4 interfaces.
On first setup with --proxy-protocol, the listener instead defaults to 127.0.0.1:9443.
An explicit --listen changes the bind endpoint without changing the advertised public port.
On repeated setup, omitting --listen preserves the existing supported listener rather than
replacing it with a first-setup default.
On first setup, derive SNI from the target hostname unless --sni is supplied. On repeated setup,
preserve the existing SNI instead of deriving a replacement. Validate the target’s TLS
compatibility before applying configuration; do not silently choose an unrelated camouflage host.
Generate a UUID, X25519 key pair, random eight-byte short ID, and a distinct ML-DSA-65 seed and
verification key. Reuse existing PIG-managed material on repeated setup; ordinary reruns do not
rotate credentials. Rotation and multi-user management require a later explicit contract.
Use warning logging, disabled access logging, decryption: none, the Vision flow, and an
explicit private-destination blocking rule. Set the geodata environment to the packaged asset path.
Server idempotence. Repeating setup with the same inputs must leave existing clients usable without changing their configuration. Preserve the UUID, X25519 private key and corresponding client authentication material, short ID, ML-DSA seed and verification key, SNI, and protocol defaults. With the same advertised host and public port, export the same canonical URI. Generate credentials only when creating a server configuration for the first time, never because setup runs again.
If the managed configuration and service settings already match the requested state and the service is running and enabled, perform checks without rewriting files or restarting the service. If only the service has stopped or become disabled, restore the requested service state using the existing credentials. Missing, malformed, or ambiguous existing authentication material is an error; do not repair it by silently regenerating credentials. Reject setup inputs that conflict with the existing authentication or SNI contract. Such changes need an explicit migration or rotation contract rather than an ordinary rerun.
Reuse an existing server. server --export-only --host HOST --export DESTINATION reads the
existing packaged server configuration and exports a connection URI using its current UUID, SNI,
short ID, and derived client verification material. The advertised public port still defaults to
443; never infer it from a loopback backend port. Require one unambiguous supported VLESS/REALITY
inbound, client, SNI, and short ID. Reject ambiguity or malformed material instead of selecting an
arbitrary entry. This mode does not install, rewrite server or service configuration, restart,
enable, or rotate credentials. An explicitly requested file export is its only persistent write.
Derive verification material in process so existing private keys and seeds do not enter subprocess
arguments. This branch performs a read-only query with explicit credential export; the shared server command retains its conservative action annotation.
Client inputs and defaults. Accept a single quoted vless:// positional URI as the primary
workflow. Also support direct parameter mode with --server host:port, --id, --sni,
--public-key, and --short-id; --pqv supplies ML-DSA verification when used by the server.
The direct mode supplies the connection fields while REALITY, RAW, Vision, and Chrome retain
the defaults below. All input forms feed the same validated connection model and renderer.
Keep --from FILE and --from - as optional file/stdin inputs. Reject mixed connection input
forms rather than silently overriding URI fields with flags. Local options such as --listen
remain available for every input form.
client.uri is an ordinary UTF-8 text file containing one standard vless:// URI and an optional
trailing newline; the filename is arbitrary. It is not a new PIG configuration format.
Support the reference combination only: REALITY, Vision, and TCP/RAW. Map URI type=tcp to JSON
network: raw, pbk to password, sid to shortId, and pqv to mldsa65Verify.
Preserve the ML-DSA verification field; never silently drop it. Reject duplicate or unsupported
parameters that would change connection meaning. The mapping follows the
upstream sharing specification.
On first setup, bind a socks inbound to 127.0.0.1:12345, retaining the existing PIG client
endpoint default. --listen can explicitly select 127.0.0.1:8888 to match the inspected client.
On repeated setup, omitting --listen preserves the existing managed client’s listener.
Provide HTTP support on the same port, UDP enabled, and
multiplexing disabled. Use encryption: none, the Vision flow, a Chrome fingerprint, and
spiderX: /. The upstream Socks reference
documents HTTP support. Validate HTTP and SOCKS independently; a TCP listener alone is insufficient.
The CLI fields map to the existing reference configuration as follows. Client paths below are relative to its VLESS outbound; server paths are relative to its VLESS inbound.
| CLI field | Client configuration | Server configuration or export |
|---|---|---|
Server --host, --port; client --server |
settings.vnext[0].address and .port |
Advertised URI endpoint; not necessarily the bind endpoint |
Role-specific --listen |
Local inbound listen and port |
VLESS inbound listen and port |
Client --id |
settings.vnext[0].users[0].id |
Matches settings.clients[0].id |
--sni |
streamSettings.realitySettings.serverName |
Member of streamSettings.realitySettings.serverNames |
Client --public-key |
streamSettings.realitySettings.password |
Derived from streamSettings.realitySettings.privateKey |
Client --short-id |
streamSettings.realitySettings.shortId |
Member of streamSettings.realitySettings.shortIds |
Client --pqv |
streamSettings.realitySettings.mldsa65Verify |
Derived from streamSettings.realitySettings.mldsa65Seed |
Server --target |
No direct client field; SNI must be compatible | streamSettings.realitySettings.target |
Server --proxy-protocol |
No client field | streamSettings.rawSettings.acceptProxyProtocol: true |
The reference server keeps realitySettings.xver: 0: accepting a PROXY header from Nginx and
forwarding a PROXY header to the REALITY target are different settings. Template defaults preserve
the reference flow, transport security, logging, disabled multiplexing, server private-destination
blocking, and client fingerprint. The public endpoint, bind endpoint, and target have separate roles.
Platform and service ownership. Linux uses the configured package repositories and the package
account, configuration path, and unit above. macOS clients use Homebrew Xray, a mode-0600 user
configuration at ~/.config/xray/pig-proxy.json, and a dedicated user LaunchAgent named
com.pigsty.xray-proxy; do not take over another Xray daemon or Homebrew service.
Linux setup requires root and a running systemd instance; macOS client setup requires a regular user and existing Homebrew. macOS server setup is outside this change.
New role setup explicitly starts and enables the managed service; install-only does not start or enable it.
On Linux, PIG owns a bounded pig-proxy.conf systemd drop-in for asset location and capabilities.
Direct binding to a privileged port requires only CAP_NET_BIND_SERVICE in the bounding and
ambient sets. Reset both sets before assignment because systemd combines positive directives
with the package unit. A loopback backend on an unprivileged port does not need that capability.
Do not depend on permissive host sysctl settings or run Xray as root to make port 443 work.
Application and recovery. Parse arguments and preflight paths, port ownership, service conflicts,
and existing configuration before mutations. Recognize managed configuration by its complete
supported shape, not merely an inbound tag. Replacing a different or unsupported client configuration requires --replace --yes. Unsupported
server configurations and service units using another account, an explicit different group, or
extra configuration arguments are refused. Preview supports --plan, with no installation, credential creation, file writes, or restarts.
Render JSON through Go serialization. Stage protected candidates, validate them with Xray under
the actual service identity, then atomically apply configuration and service changes. Compare
content, ownership, and permissions before treating files as unchanged. On macOS, track persistent
disablement separately from loaded state, enable the managed LaunchAgent on start, and restore both
states on failure. Save original
content, ownership, mode, service enablement, and running state for bounded rollback. Check service
health and connectivity before publishing shell aliases or connection exports. Client setup requires
HTTP 204 from https://www.google.com/generate_204 through both HTTP and SOCKS, so server outbound
access to this endpoint is part of the client acceptance condition. An application
failure returns nonzero and reports which recovery steps succeeded; an installed package may remain.
Never delete or automatically stop V2Ray. A port conflict stops preflight and produces a migration
instruction. Existing V2Ray configuration remains available for operator-controlled rollback.
Retain po, px, and pck for client convenience, including lowercase proxy variables needed by
build tools. Activating those variables in the calling shell still requires sourcing the generated
shell file and invoking po; a child process cannot modify its parent shell.
Secrets and exports. --export FILE writes the explicitly requested connection export with
mode 0600 and no server private key or ML-DSA seed. --export - explicitly delivers one complete
URI on stdout, with non-secret setup diagnostics on stderr. This credential-export mode requires
text output; reject JSON/YAML combinations before mutations instead of putting the URI inside a
structured result. Ordinary setup output remains redacted. Command-line input is supported even
though the caller’s shell history or process inspection can retain those supplied credentials;
file and stdin input remain available when that matters.
Treat the whole URI as a credential, including its UUID and authentication fields. Default logs, plans, JSON/YAML results, and failure details contain only redacted summaries and export paths. Generate and derive key material in process. Capture validator output privately: upstream configuration errors can include the invalid secret value. Never use a generic subprocess capture as a safe credential boundary. Re-exporting to an existing protected file containing the same canonical URI succeeds without rewriting it. A different existing export is a conflict; never silently overwrite it or print its contents in a diagnostic.
Ingress and verification boundaries. Direct mode is the default one-command server setup.
The explicit --proxy-protocol backend mode requires loopback binding and a trusted pre-existing
frontend. PIG does not rewrite Nginx or firewall/cloud rules in this change. A busy public port
causes a clear failure instead of stopping its owner. Backend readiness does not prove public ingress;
server setup reports local checks and leaves external reachability pending until a client handshake
and HTTPS request succeed.
Generating equivalent Xray configurations includes all of the reference pair’s protocol and authentication fields. Reproducing the entire reference deployment also requires Nginx’s SNI map, its PROXY-enabled website backend, and OS-specific service registration. This implementation manages Xray and its own service settings; it does not claim to recreate that Nginx composition from a server URI. Configuration equivalence does not imply byte-for-byte preservation of tags, field order, or installation-specific names.
The 2026-10-16 compatibility refinement accepts the complete marker-free macOS plist generated by the earlier renderer when its configuration and binary paths match. A management comment alone is insufficient. Edited or foreign files require explicit replacement. Linux recognition is also limited to the complete generated capability variants. After the one-time comment migration, identical execution must preserve the running service.
The marker-free fixture is generated by executing the earlier renderer. That source file is
byte-identical to the publicly available
v1.9.0 source at 9eb54888.
This is old-source-format evidence, not verification of a particular released binary.
Consequences
Users get two setup operations connected by one standard URI, or supply client parameters directly,
with matching generated parameters instead of manual JSON editing. No connection file is required.
Both new clients and the historical VMess form default to 127.0.0.1:12345 on first setup.
Direct servers default to the public port on all IPv4 interfaces; PROXY-protocol backends default
to 127.0.0.1:9443. Repeated setup preserves existing listeners when --listen is omitted.
Configuration and service management remain explicit about role, OS, ownership,
and external ingress.
The implementation uses cmd/build.go and focused files under cli/build. It reuses the
existing plan, output, confirmation, privileged-write, and logging helpers.
Verification and evolution
Fixed source commits and regression tests for the committed v1.10.0 refinements cover: complete legacy service recognition. These commits do not establish a release boundary. The v1.9.0 runtime evidence below covers the original implementation.
The implementation is recorded in
d090b7c,
with ownership and service-state fixes in
5d8660c.
Tests cover role syntax, equivalent input forms, redaction, listener defaults, credential reuse,
export conflicts, protected files, capability selection, and plans. Full Go tests, vet, static
analysis, dead-code and complexity checks, and repeated command/build race tests passed locally.
Runtime checks used Xray 26.3.27:
| Environment | Verified behavior |
|---|---|
| Fresh Debian 13 ARM64 client | Package installation; service running as xray; HTTP and SOCKS health checks; unchanged configuration and PID on repeat setup; rollback after a wrong UUID |
| Fresh Debian server | Direct privileged-port listener; 0640 configuration and 0600 export; stable credentials, files, and PID on repeat setup; rollback after export failure |
| Existing Homebrew Xray on macOS | Isolated LaunchAgent; HTTP/SOCKS connectivity; unchanged reruns; restoration of configuration and persistent disabled state after failure |
| Existing reference server | Read-only export and client tests left its configuration hash and PID unchanged |
The new server’s exported URI completed REALITY/Vision connections with ML-DSA verification. HTTP and SOCKS requests to a reachable TLS site returned HTTP 200. Its network could not reach the Google health endpoint, so full client setup for that pair failed and rolled back. Full client setup passed against the existing reference server, through its Nginx/PROXY ingress.
Runtime coverage did not include RPM installation, a fresh Homebrew installation, UDP forwarding, other Xray versions, or deployment of a new PROXY-protocol frontend.
Current status
Released in v1.9.0. Nginx ingress automation and credential rotation remain future work.
2.14 - Bootstrapping a Pigsty Controller as a Recoverable Transaction
Decision date: 2026-08-14
Status: Implemented and released in pig v1.8.0.
Current reference:pig sty boot
Scope: Preparing a Pigsty controller and its package sources; not deploying a database cluster.
Decision
pig sty boot should be one native, failure-aware controller bootstrap workflow. It resolves an
explicit source before privilege elevation, prepares online or offline repositories, installs only
the required controller packages, proves Ansible is usable, and performs bounded finishing checks.
Repository replacement is transactional: definitions are backed up and restored when package setup fails. Optional conveniences may warn, but invalid explicit input, package failures, and an unusable final Ansible environment are hard failures.
Context
The previous command delegated to a shell bootstrap script. That made source selection, download,
sudo boundaries, repository rollback, error classification, and structured automation difficult to
observe. A present ansible-playbook binary could also be mistaken for a usable environment even
when its Python dependencies were missing.
Offline installations added another ambiguity: an already ready controller may still need a local repository prepared for later nodes.
Alternatives considered
- Continue invoking the legacy script. Rejected because PIG could not own the transaction or explain partial failure reliably.
- Require the entire command to start as root. Rejected because explicit downloads and source validation do not need privilege and should happen before one bounded elevation.
- Treat an Ansible binary as readiness. Rejected because the executable may use a Python environment missing required modules.
- Skip repository work when Ansible is ready. Rejected because staging an explicit offline source is an independent requested effect.
- Make every finishing check fatal. Rejected because locale convenience, localhost SSH repair, or tree initialization can fail without invalidating an otherwise usable controller.
Contract
- explicit local paths and URLs are validated and never silently fall back to online mode;
- automatic offline sources must pass ownership and permission checks;
- a committed local repository can take precedence over a selected package;
- download and restricted archive extraction use native bounded implementations;
- offline bundles require a
pigsty/repo_completesentinel; additional roots are preflighted and renamed beforepigsty, while conflicts and interrupted residue fail closed for manual cleanup; - privilege elevation happens once after source resolution and can be disabled or made non-interactive;
- overwritten repository definitions are recoverable on setup failure;
- readiness executes Ansible and checks the Python modules it will use;
- the result distinguishes ready, offline, online, and existing modes;
- hard failures and finishing warnings are separate structured fields;
- bootstrap does not claim that Pigsty deployment has succeeded.
Consequences
The native workflow is larger than a script launcher, but its side effects and rollback state are visible. It can stage offline content on an already usable controller and gives automation a stable result without hiding optional problems.
After bootstrap, generate the Inventory, deploy the selected services, and check their status.
Verification and evolution
The native implementation landed in
222616e and was refined in
74e084e. Tests cover source precedence,
permission checks, restricted extraction, sudo re-exec, repository rollback, locale recovery,
Ansible/Python readiness, localhost SSH, initialization, warning classification, and structured
results. The release page records delivery in v1.8.0.
The offline-bundle refinement in
8fa3abb
preserves multiple validated top-level repositories and retains the repo_complete marker.
It shipped in v1.8.1.
Current status
pig sty boot prepares the controller. Run deployment separately after configuring the Inventory.
See pig sty for source modes, environment controls, and next steps.
2.15 - Install the Pigsty Repository Key Automatically
Decision date: 2026-10-04
Status: Released in v1.9.0.
Current reference:pig repo
Scope: Installing the existing embedded Pigsty public key during repository configuration.
Decision
When a selected module contains an available pigsty-infra or pigsty-pgsql repository,
prepare the embedded Pigsty public key before changing repository definitions. Apply this in
the shared configuration workflow so repo add, repo set, and callers that reuse it agree.
Reuse an existing key file. Automatic installation is best-effort; an explicit signing-key
reference in selected repository metadata makes installation failure fatal.
Context
The source baseline
installed the key only when a caller requested GPGCheck, as native sty boot does.
Ordinary repo add/set therefore omitted a public key already shipped inside PIG.
The key is needed by both Pigsty repositories. Their membership spans pigsty, infra,
pgsql, and the default all selection, so checking only the literal argument pigsty
would miss normal usage.
APT does not discover files under /etc/apt/keyrings automatically. A repository must reference
the prepared file with signed-by; otherwise a successful write still leaves NO_PUBKEY
warnings during cache refresh.
Removing signed-by during fallback can conflict with a retained definition of the same APT
source. Keep the default reference stable across successful preparation and fallback. Explicit
metadata names a required key of its own; preparing an unrelated default file cannot satisfy it.
Alternatives considered
- Download the default key at runtime. The embedded release input already supplies it and works offline, without adding a network or external-tool dependency.
- Install the key on every repository operation. Unrelated repositories should not cause a Pigsty key write. Resolve membership and platform availability first.
- Fail every repository operation when automatic key installation fails. Rejected because optional key preparation should not prevent the existing compatibility mode from working. Explicit signing-key metadata remains a strict boundary.
- Enable all signature checks at the same time. Publisher identity, RPM package signatures, and APT metadata authentication are separate contracts. Automatic key installation does not establish signing coverage for every package or mirror.
Contract
- Validate requested modules before installing the key. A rejected replacement does not install it or move repository files.
- Match the two Pigsty repository identifiers in resolved modules, including custom modules; the URL’s hostname alone does not select a signing identity.
- Write the existing embedded key to
/etc/pki/rpm-gpg/RPM-GPG-KEY-pigstyon EL or/etc/apt/keyrings/pigsty.ascon Debian/Ubuntu when installation is needed, with mode0644. - Check for an existing regular key file first, including a symlink resolving to one; reuse it without changing its contents or permissions. If the existence check fails, attempt installation.
- Create missing parent directories through the existing sudo fallback and use the atomic file writer. A denied destination check must still reach the privileged attempt, which checks the destination again. An occupied directory or dangling symlink is an installation error.
- Without explicit key metadata, installation failure warns and continues. Only selected Pigsty
definitions fall back to APT
trusted=yesor RPMgpgcheck=0andrepo_gpgcheck=0. Fill the defaultgpgkeyorsigned-byreference on both success and failure. Do not rewrite retained repository files to implement fallback. - Explicit key preparation applies to the actual reference. APT
signed-byaccepts absolute paths to existing regular keyring files, separated by commas; install the embedded key when the default path is explicitly named. EL prepares an explicitly named default file if needed and passesgpgkeypaths or literal URLs to nativerpm --import. - Failure to prepare an explicit key is fatal before backup, repository writes, or cache refresh. Preserve its reference and never downgrade that definition. A valid custom key does not depend on the default path; an implicit-key failure in another selected repository affects only that implicit definition.
- Successful ordinary operations preserve signature-checking settings.
sty bootrequests signing on successful key preparation and follows the same implicit-key fallback on failure. - Put fallback warnings on stderr and in
repo add/set’sdata.warnings;sty bootretains them in its own warnings. Implicit installation does not import into RPM’s database; explicit EL metadata does. Neither path changes APT’s global trust store. - Repository rollback restores definitions; already installed or imported public keys remain.
Consequences
Adding a Pigsty repository also attempts to prepare its public-key file, including on offline hosts. Ordinary key failures no longer prevent repository setup. Falling back disables signature verification for those Pigsty definitions and is reported explicitly. A successful existence check preserves the administrator’s existing file; it does not validate that file’s contents. Third-party repository trust remains unchanged. APT may retain previously authenticated indexes with a warning when a key becomes unavailable. Successful repository configuration therefore does not prove that every index was freshly downloaded. The maintained repository reference describes the resulting defaults and paths.
Verification and evolution
The automatic-key implementation
and repository regression tests
are recorded in source commit 56f7353. Local regression tests exercise EL, Debian, and Ubuntu on both supported architectures,
default and composite selections, existing-key reuse, denied existence checks, custom modules,
unavailable repositories, implicit-key fallback, and explicit-key failure before repository
mutation. Existing replacement tests continue to cover rollback.
Actual CLI tests on local EL9, EL10, Debian 12, and Ubuntu 24 ARM64 guests use isolated mount namespaces. They
verify installation as an ordinary user through sudo with missing key directories, exact embedded
bytes and permissions, repeated execution, composite selections, parseable structured output,
implicit-key failure continuing with a warning, and explicit-key failure stopping before
repository replacement. Real DNF/APT refreshes use isolated caches, and the resulting indexes
are queried for available packages. APT tests also verify that the installed key is referenced
without NO_PUBKEY warnings and that explicit signed-by with trusted=no authenticates the
metadata. These checks do not install packages or verify RPM package signatures. The guests'
original repository definitions, keys, and caches remain unchanged.
Follow-up regression checks cover retained APT sources and previously authenticated caches, custom-key absence before both add and replacement, a valid custom key with an unusable default path, and mixed explicit/implicit definitions. Permission tests deny ordinary-user traversal of the key directory and verify both privileged installation and rejection of a hidden symlink. RPM import tests use an isolated copy of the guest’s RPM database.
Current status
Released in v1.9.0. See the current reference linked above for usage and platform requirements.
2.16 - One Catalog Entry Count for the Website and CLI
Decision date: 2026-10-16
Status: Implemented in the v1.10.0 candidate, not yet released.
Current reference:pig extcatalog count
Scope: Catalog totals and default listing membership; package installation and SQL activation rules remain defined by each entry.
Decision
Use the number of catalog records as the shared extension count. Include packaged SQL utilities and retained lifecycle records. Calculate CLI totals from the catalog actually loaded or downloaded.
Context
The catalog serves package discovery as well as PostgreSQL extension discovery. A packaged SQL
utility can be useful without a control file or a CREATE EXTENSION entry point. Excluding it
from the default list and total makes those outputs disagree with the website and catalog file,
even though an explicit name search still finds it.
Alternatives considered
- Count only records classified as PostgreSQL extensions. Rejected because it gives the CLI and website different totals for the same catalog.
- Add a separate public count for every entry type. Unnecessary for the current listing contract.
- Hard-code the announced total in the CLI. Rejected because a downloaded catalog can differ from the bundled one.
Contract
- The unfiltered default list includes every catalog record, including SQL utilities and removed records.
- Text row counts and JSON/YAML
data.countequal the number of returned records. - Searches count their matches;
--pkgcontinues to count leading package records. - The global availability text summary uses the complete catalog count.
- Catalog refresh results use the downloaded record count in
data.extension_countand their message. - Website totals follow the bundled catalog. A newer downloaded catalog may have a different total.
- Counting a record does not change its DDL requirements, lifecycle state, or platform availability.
Impact
SQL utilities appear in the default list as well as explicit searches. Output field names and types remain stable. Consumers should interpret the extension total as catalog coverage; it is not a count of extensions enabled in a database or installable on a particular host.
Verification
Fixed source commits and regression tests for the committed v1.10.0 refinements cover: catalog entry count and availability. These commits do not establish a release boundary.
The preceding classification rule is preserved in the v1.9.0 catalog source. Acceptance checks compare parsed record counts with default lists, availability summaries, and catalog refresh results. They cover packaged SQL utilities and removed records, while keeping search and package counts specific to their returned rows.
Status
Accepted on 2026-10-16 and implemented with regression tests. The v1.10.0 candidate bundles 603 records and is not yet released. Use the current reference for the counting contract and release notes for version boundaries.
2.17 - Target PostgreSQL Versions for Category Aliases
Decision date: 2026-11-06
Status: Implemented in source commit7c069dc; released in v1.10.4.
Current reference:pig extcategory aliases
Scope: DynamicpgN-*andpgsql-*category aliases that resolve extension package groups.
Decision
Stable category aliases use the requested PostgreSQL major when evaluating package visibility.
pgN-<category> takes the major from the alias, and pgsql-<category> -v N uses the same target
major. Package templates are rendered for that requested major after visibility is evaluated.
The catalog remains the source of package names and platform availability. This lets refreshed
metadata describe package splits and version-specific support without adding extension-specific
branches to the alias resolver. The current catalog describes EL PG14/15 pgaudit as
pgaudit_14/pgaudit_15, PostGIS 3.7 as postgis37_N, and the address-standardizer and
PG16+ Tiger Geocoder packages as separate entries.
The current Beta PostgreSQL placeholder keeps its compatibility rule: it borrows the latest stable matrix and retains PGDG-origin entries only, because the catalog does not yet have a matrix row for that target.
Context
Before this change, pgsql-* category aliases evaluated stable targets against the latest stable
catalog row. A command such as pgsql-gis -v 14 could therefore include a package whose matrix
entry existed only for PG18, such as the Tiger Geocoder. The numbered form, pg14-gis, already
used the requested major and produced a different package group.
The same resolver also contained a hardcoded EL pgaudit rename for PG14 and PG15. That rename
reflected historical package names, while the current pgaudit recipes and catalog use
pgaudit_$v. Keeping the package rule in code made the alias result stale when the package
metadata was corrected.
Alternatives considered
- Keep the latest stable template for every
pgsql-*alias. Rejected because an explicit-v Nmust respect the requested PostgreSQL-major support matrix. - Add more extension-specific package exceptions. Rejected because pgaudit and PostGIS package names and support rows are catalog data that can be rendered by the common resolver.
- Use only RPM/DEB version metadata. Rejected because the package matrix also records OS, architecture, source repository, hidden state, and unavailable cells.
- Remove Beta borrowing. Rejected because the current Beta target has no catalog row of its own; it continues to need a stable template with the existing PGDG-only restriction.
Contract
- A stable
pgN-<category>alias evaluates visibility against PostgreSQL major N. - A stable
pgsql-<category>alias evaluates visibility against the command’s target version; an explicit-v Ntherefore has the same result aspgN-<category>. - When no target reaches the resolver, the existing command probing and operation defaults remain in force; a zero target inside the alias parser resolves to the latest stable major.
- Package templates are rendered for the requested target major. Visible leading non-contrib entries are deduplicated by rendered package name.
- On a known operating system, a missing matrix cell remains unavailable. Existing unknown-OS metadata fallback behavior is unchanged.
- The Beta target borrows the latest stable matrix and keeps only PGDG-origin entries. This is the sole stable-template borrowing exception.
- The configured OS repository must provide the package named by the catalog; the resolver does not migrate an already installed package between historical names.
Consequences
pig ext add pgsql-gis -v 14 --plan and pig ext add pg14-gis --plan now select the same PG14
matrix. PG14/15 no longer inherit the PG18-only Tiger Geocoder entry. The corrected pgaudit catalog
rows produce pgaudit_14 and pgaudit_15 on EL, and the PostGIS 3.7 catalog rows produce
postgis37_N plus the independent address-standardizer and PG16+ Tiger Geocoder packages where
the matrix says they are available.
The behavior is easier to refresh because package-specific naming lives in the catalog. Users still need a repository containing the selected package, especially for the Pigsty-origin EL pgaudit PG14/15 rows.
Verification and evolution
Source commit 7c069dc
adds regression coverage for the target-version, numbered-alias, default-version, Beta, and
future-major paths in cli/ext/category_alias_test.go. Embedded catalog tests in
cli/ext/catalog_embedded_test.go cover pgaudit across EL8/9/10 and both architectures, and
PostGIS, address-standardizer, and Tiger Geocoder package resolution across EL and Ubuntu PG14-18.
The catalog changes are in cli/ext/assets/extension.csv.
The committed source was checked with git diff --check, go test -shuffle=on -count=1 ./...,
go vet ./..., go test -race -shuffle=on -count=1 ./cli/ext ./cli/install, staticcheck ./...,
the configured complexity lint, and deadcode ./.... The v1.10.4 tag contains this implementation; the corresponding release notes record its delivery.
Current status
The target-version behavior is implemented in the source commit above and documented in the
pig ext reference. Release notes and deployment status remain separate
from this implementation record.
3 - Release Notes
The latest stable version is v1.10.4.
Release notes for every published pig version, newest first. Artifacts and checksums for
each version live on its GitHub release page.
See Installation for upgrade commands and platform-specific instructions.
3.1 - pig v1.10.4
PIG v1.10.4 refreshes the embedded PostgreSQL extension catalog from 620 to 626 entries and fixes category aliases to respect the requested PostgreSQL major version. The November 6, 2026 snapshot adds seven entries and drops the retired pgcontext_pgvector record, for a net increase of six.
New catalog entries
| Extension | Version | PostgreSQL support | Description |
|---|---|---|---|
pg_warren |
0.8.0 |
15–18 | Versioned graph traversal and computation over PostgreSQL tables |
pg_statecharts |
0.1.0 |
16–18 | Hierarchical state machines and transactional event handling |
pg_statecharts_dev |
0.1.0 |
16–18 | SCXML import and migration tooling for pg_statecharts |
pg_lion |
0.3.0 |
16–18 | Roaring bitmap inverted indexes for filtering, counts and aggregates |
pg_lion_citext |
0.3.0 |
16–18 | Case-insensitive citext operator class for lion indexes |
pg_lion_vector |
0.3.0 |
16–18 | Filtered nearest-neighbor indexes for pgvector vector and halfvec |
opencc |
0.1.0 |
14–18 | OpenCC conversion between Simplified Chinese, Traditional Chinese, regional variants and Japanese Shinjitai |
Installability depends on the target PostgreSQL major, operating system, architecture, and configured repository.
Version and package metadata updates
Selected catalog version changes:
| Extension | Version change |
|---|---|
postgis |
3.6.4 → 3.7.0 |
timescaledb_toolkit |
1.26.0 → 1.27.0 |
vchord |
1.1.1 → 1.2.0 |
vchord_bm25 |
0.3.0 → 1.0.0 |
pg_tokenizer |
0.1.1 → 1.0.0 |
pg_search |
0.26.3 → 0.26.5 |
pg_duckdb |
1.1.1 → 1.2.0 |
pg_lake |
3.5 → 3.6 |
anon |
3.2.3 → 3.3.2 |
pg_integrity_checksums |
2.0.0 → 2.1.0 |
The refresh also updates package availability, dependencies, descriptions, and source metadata. PostGIS 3.7 uses the postgis37_N RPM family, with separate address-standardizer and Tiger Geocoder packages. The EL pgaudit catalog uses pgaudit_14 and pgaudit_15 for PostgreSQL 14 and 15.
Category aliases follow the target version
For stable PostgreSQL versions, pgsql-<category> -v N now selects the same platform and PostgreSQL-major matrix as pgN-<category>. For example, pig ext add pgsql-gis -v 14 --plan no longer includes packages available only for a newer PostgreSQL major. Package names come from the catalog, replacing the obsolete pgaudit rename in the resolver. Beta targets retain the existing latest-stable, PGDG-only fallback.
Catalog count and build versions
The embedded catalog contains 626 records: 624 available entries and 2 retained removed records. They map to 518 distinct package names, including PostgreSQL contrib modules, or 457 non-contrib package families. See the catalog-entry counting rule.
Go remains at 1.27.3, embedded Pigsty at 4.5.0, and default cargo-pgrx at 0.19.3. Follow the installation guide to upgrade PIG.
Checksums
| File | Checksum |
|---|---|
| pig-1.10.4-1.aarch64.rpm Linuxarm64SHA-256 | 4981a060779423ab4d6c5baaa8fe6c26adb972fc34b9515119b9e5d4723513ce |
| pig-1.10.4-1.x86_64.rpm Linuxamd64SHA-256 | d1624bbcec5d3f4715d223acca8311182ef1ee36542c16bcf82602674ee82b07 |
| pig-v1.10.4.darwin-amd64.tar.gz macOSamd64SHA-256 | 9384759851af53f5cddc381007f78de9a226b43b914848291df86ec41096119e |
| pig-v1.10.4.darwin-arm64.tar.gz macOSarm64SHA-256 | d0f876a518b82f021c83914c5909f1ac914cbe8c0aa0957cef37c83d69b79b0d |
| pig-v1.10.4.linux-amd64.tar.gz Linuxamd64SHA-256 | 1caa6f4af13e1f40f5faa9752628efe1dd85190b344bf1597cb3c8d23e99fe0b |
| pig-v1.10.4.linux-arm64.tar.gz Linuxarm64SHA-256 | 756b7c94936a4c8cca1b0a15f3bcac8eee9669480b8d6af205e920b673a680ba |
| pig_1.10.4-1_amd64.deb Linuxamd64SHA-256 | 98bbfce9dc263e94d4025debdd9bf0e137d9ec12afff4d57e4e08530b1255bf3 |
| pig_1.10.4-1_arm64.deb Linuxarm64SHA-256 | 18447ccff10fd31c90ae16b34f2885a0415bc6efca5d0ff78f435e68ba6438e1 |
v1.10.4 ·
3.2 - pig v1.10.3
PIG v1.10.3 refreshes the embedded PostgreSQL extension catalog from
616 to 620 entries, adding four extensions and updating package, version,
compatibility, and availability metadata.
New extensions
| Extension | Version | PostgreSQL support | Description |
|---|---|---|---|
oai_fdw |
1.16 |
14–18 | Read-only OAI-PMH foreign data wrapper for metadata harvesting over HTTP/HTTPS |
pg_agent_gate |
0.3.0 |
18 | SQL proposal, verification, and execution gate with human approval for agent roles |
pg_integrity_checksums |
2.0.0 |
14–18 | Physical and logical checksums for PostgreSQL pages, rows, tables, indexes, and databases |
pg_stat_tcpinfo |
1.1 |
14–18 | Linux TCP connection statistics, latency, and retransmission metrics |
These records describe catalog and package availability; actual installability still depends on the target PostgreSQL major, operating system, architecture, and repository snapshot.
Version and metadata refresh
The catalog updates existing package and extension metadata, including
pg_nanotime 0.2.0 → 0.3.0, supautils 3.4.4 → 4.0.0,
pg_ducklake 1.0.2 → 1.0.3, pg_improv 0.10.0 → 0.12.1,
wrappers 0.6.3 → 0.6.4, edtf_postgres 1.2.3 → 1.3.2,
hypopg 1.4.3 → 1.4.4, and rdf_fdw 3.0 → 3.1.
It also refreshes package matrices, compatibility ranges, descriptions, and
source metadata for the maintained catalog.
Catalog count
The catalog now contains 620 entries: 617 available records and 3 retained removed records. The catalog-entry counting rule includes SQL utilities and lifecycle records; availability remains platform-specific.
Go remains at 1.27.3, embedded Pigsty at 4.5.0, and default cargo-pgrx at
0.19.3. Follow the installation guide to upgrade PIG.
Checksums
| File | Checksum |
|---|---|
| pig-1.10.3-1.aarch64.rpm Linuxarm64SHA-256 | 2068ca8150df3ee837d0ba6e533ba651703c7223c14c522703ee1be9c41666ea |
| pig-1.10.3-1.x86_64.rpm Linuxamd64SHA-256 | 97ff1c1799262650a92d669dafc905d498d5ab3cf58619198322bc2d274b4ceb |
| pig-v1.10.3.darwin-amd64.tar.gz macOSamd64SHA-256 | 16203993bbba93dee16a38eac3eedbf67ed2cce3c7894cedbba613e95578004c |
| pig-v1.10.3.darwin-arm64.tar.gz macOSarm64SHA-256 | 0eb3f0447107734ae7decf3bc16caf99087e86119e83ce34987ebb376285fb14 |
| pig-v1.10.3.linux-amd64.tar.gz Linuxamd64SHA-256 | a3e61d0d71b9226ac89aa3b1e29baa8c92e5109ecaa2c7e26343f474e5832e04 |
| pig-v1.10.3.linux-arm64.tar.gz Linuxarm64SHA-256 | 5f25ff6cf634f708d5f70bde39a07d83fe9c7d1ef7d944395eb294eb64554ecf |
| pig_1.10.3-1_amd64.deb Linuxamd64SHA-256 | dfabbcf4fcdf612d79a7cce76db08d36683e00bd2b0f27c7e78258f54fcb721a |
| pig_1.10.3-1_arm64.deb Linuxarm64SHA-256 | 4065ed14209a4857b26fa1c7e19adbeee2e5be68df41710db33b64b18159045f |
v1.10.3 ·
3.3 - pig v1.10.2
PIG v1.10.2 refreshes the embedded PostgreSQL extension catalog from
615 to 616 entries, adding pg_nanotime and updating extension versions,
compatibility, and package availability metadata.
New extension
Add pg_nanotime 0.2.0, which
provides nanosecond timestamp and fixed-duration interval types. The catalog
records RPM and DEB packages for PostgreSQL 17 and 18. Upstream classifies
0.2.0 as a testing release.
Version updates
| Extension | Previous | Updated |
|---|---|---|
citus, citus_columnar |
14.2.0 |
14.3.0 packages |
duckdb_fdw |
2.0.1 |
2.0.2 |
pg_mentat |
1.17.2 |
1.18.0 |
pg_tre |
4.5.1 |
4.5.2 |
The Citus catalog extension version is 14.3-1; its RPM and DEB package version
is 14.3.0. The refresh also adds DEB availability metadata for pg_tre on
PostgreSQL 17 and 18.
Catalog metadata
- Update PostgreSQL compatibility, package availability, licenses, and descriptions.
- Set the
duckdb_fdwcatalog range to PostgreSQL 15–18 andpgcontext_pgvectorto PostgreSQL 17. - Count 616 catalog entries: 613 available records and 3 retained removed records. The catalog-entry counting rule includes SQL utilities and lifecycle records; availability still depends on the platform and PostgreSQL major version.
Go remains at 1.27.3, embedded Pigsty at 4.5.0, and default cargo-pgrx at
0.19.3. Follow the installation guide to upgrade PIG.
Checksums
| File | Checksum |
|---|---|
| pig-1.10.2-1.aarch64.rpm Linuxarm64SHA-256 | f07992b20b0b397d1e4bb286656b404e3c911775e98e5fc7d940ef91439f62ed |
| pig-1.10.2-1.x86_64.rpm Linuxamd64SHA-256 | 372f4fe8d54a1ad888c91976d011d8b95de3e10286966cfc94b0ab91e2170b20 |
| pig-v1.10.2.darwin-amd64.tar.gz macOSamd64SHA-256 | a54be0a4ceadf1e047b74fdb187ff57e9f97b81907c8d66795e7787de88ad864 |
| pig-v1.10.2.darwin-arm64.tar.gz macOSarm64SHA-256 | 60df049a38e109bccb3089d74fa41e0d22606ce4df0e4fadae39530d546ca731 |
| pig-v1.10.2.linux-amd64.tar.gz Linuxamd64SHA-256 | 686c5d6cf682a5a5a1d70cc09a86fecc441b22456f79bb84f192c4730ac2bd8a |
| pig-v1.10.2.linux-arm64.tar.gz Linuxarm64SHA-256 | e1e84d5afcddc8e474d130de638bc400bb965f887bdc9face842f111fb94afeb |
| pig_1.10.2-1_amd64.deb Linuxamd64SHA-256 | 38b9634be544a1ee462926f74f3c647c2fc1b21eeffb43e41c24a9033a03a63b |
| pig_1.10.2-1_arm64.deb Linuxarm64SHA-256 | 4034cebd3a51839ecb0cb8bdf325d783f1ebb88e19b4664ab21fbf31316eae58 |
v1.10.2 ·
3.4 - pig v1.10.1
PIG v1.10.1 is a security and catalog maintenance release. It upgrades Go to
1.27.3, refreshes tooling dependencies, and expands the embedded PostgreSQL
extension catalog from 603 to 615 entries.
Security update
- Upgrade the Go toolchain from
1.27.2to1.27.3. CI and release builds read the version fromgo.mod. - Include the
crypto/x509fix for CVE-2026-111943 / GO-2026-6809. Go’s certificate verifier rejects chains containing specific intermediate certificates that are no longer trusted.
Go 1.27.3 adds one security fix over 1.27.2, as documented in the
Go release announcement.
Earlier Go security fixes are already included in the 1.27.2 baseline used by PIG v1.10.0.
Dependency updates
Update inherited tooling dependencies through version-specific module replacements:
| Module | Previous | Updated |
|---|---|---|
github.com/cpuguy83/go-md2man/v2 |
v2.0.6 |
v2.0.7 |
github.com/stretchr/objx |
v0.1.0 |
v0.8.0 |
golang.org/x/mod |
v0.41.0 |
v0.42.0 |
golang.org/x/tools |
v0.51.0 |
v0.52.0 |
Extension catalog
The embedded catalog now contains 615 entries, with 12 additions since v1.10.0:
codesystem,encsearch,hdr_histogram,pg_improvpg_kv,pg_lease,pg_synonym,pg_table_rangepg_tre,pg_try_cast,stannum,tin
The refresh also updates existing extension versions and package availability metadata.
The total follows the catalog-entry counting rule: it includes
packaged SQL utilities and retained records for removed extensions. It does not imply
that all 615 entries support CREATE EXTENSION or can be installed on every platform.
Compatibility
Commands, flags, and configuration remain compatible with v1.10.0.
Embedded Pigsty remains at 4.5.0, and default cargo-pgrx remains at 0.19.3.
Building from source requires Go 1.27.3 or later. Prebuilt packages do not require a local Go installation.
Follow the installation guide to upgrade PIG. Replacing the PIG executable
brings in the updated Go standard library; upgrading the host’s Go installation alone
does not update an existing PIG binary.
Checksums
| File | Checksum |
|---|---|
| pig-1.10.1-1.aarch64.rpm Linuxarm64SHA-256 | fbd58de4cd1fa767c6d2b15d4fcb029fe38c90a0d12db2e387b7f698b5c8a69d |
| pig-1.10.1-1.x86_64.rpm Linuxamd64SHA-256 | 7955e93744fcc2d4cce9044102c2bd7ca470388a0556d3220a624f78e38c629b |
| pig-v1.10.1.darwin-amd64.tar.gz macOSamd64SHA-256 | 31fea0e9513e551e2be8dc99a8fc0f77de4bdfe40e66dadc206e227254bb7942 |
| pig-v1.10.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 1177f3b616279100ce97d23eb4fa6bc2e8daf02dbd23780a8dd5025240082c5a |
| pig-v1.10.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 0e837098d45b080ddf9205681709dbc38318d2b65cbdaed711246fd5834c3b50 |
| pig-v1.10.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 6658242816263ea4f5e3abeb3454665098c7100c75c76a3e45386a15faf6f397 |
| pig_1.10.1-1_amd64.deb Linuxamd64SHA-256 | 37f5dca9407010c56d8c5747c8ddcef101d7f07602296e0bb89620c633692eab |
| pig_1.10.1-1_arm64.deb Linuxarm64SHA-256 | f385d1c6fac40a6cf648505d349a72e7e3eadf2948024f086efe81733c2a9be5 |
v1.10.1 ·
3.5 - pig v1.9.0
Pig v1.9.0 adds one-command Xray client/server setup, automatic Pigsty repository-key
preparation, and a refreshed 600-entry extension catalog. The default cargo-pgrx
version is now 0.19.3; the embedded Pigsty version remains 4.5.0.
Xray clients and servers
pig build proxyinstalls or verifies Xray.pig build proxy clientconfigures a VLESS/REALITY/Vision HTTP/SOCKS client;pig build proxy serverconfigures a Linux server. Linux uses systemd; the macOS client uses a dedicated user LaunchAgent.- Client input accepts a standard VLESS URI,
--from FILE/-, or explicit connection flags. The first client listener is127.0.0.1:12345; the first direct server listener is0.0.0.0:443. Repeated setup preserves existing listeners and server credentials. - Matching configuration, ownership, permissions, and service state avoid rewrites and
restarts. Failed client connectivity checks restore prior managed files and service state.
Replacing a different client requires
--replace --yes;--planpreviews either role. server --export-only --host HOST --export -exports an existing connection without changing the deployment. File exports use mode0600; explicit stdout export requires text output. Ordinary results and plans omit credentials. The historical VMess positional form remains available through V2Ray.
Run the server command on the server, then transfer client.uri securely to the client and run
the client command there. See pig build for prerequisites and macOS setup.
Repository keys
repo add,repo set, andsty bootprepare the embedded Pigsty public key when selected repositories need it. Existing regular key files are reused; missing defaults are installed offline at/etc/pki/rpm-gpg/RPM-GPG-KEY-pigstyor/etc/apt/keyrings/pigsty.asc.- Implicit default-key failure emits a warning and falls back only for selected Pigsty
definitions. Default key references remain stable, including APT
signed-by. - Explicit signing-key references are mandatory: invalid or unavailable keys fail before
repository replacement or cache refresh. EL imports explicit references with
rpm --import. Selecting unrelated repositories does not prepare the Pigsty key.
See pig repo for signature-enforcement
defaults and the distinction between key preparation and metadata refresh.
Catalog and build defaults
- The embedded catalog contains 600 entries, adding 22 entries to the v1.8.1 snapshot.
New entries include
edtf_postgres,plphp,pg_lexo,pg_money,istore,colnames,pg_statkit,pgtelemetry,pg_rusage,pgexporter_ext,pg_statvfs, andlibx509pq. Package versions and platform-availability metadata are refreshed as well. - The catalog total includes retained lifecycle records. Installability depends on each
extension’s state and OS/architecture/PostgreSQL matrix. Use
pig ext avail NAMEto check a target. pig build pgrxdefaults tocargo-pgrx 0.19.3. An explicit-vand extension-specific catalog metadata continue to select another required version.- Platform debug packages remain enabled by default, as in v1.8.1. Use
--nodbgfor RPMdebuginfo/debugsourceand DEBdbgsymsuppression;-s|--symbolis a deprecated no-op.
Compatibility
No existing command or flag is removed. New Xray role commands use VLESS/REALITY/Vision; existing positional VMess commands retain their V2Ray behavior. Server setup checks the local listener and service. Configure the firewall, cloud security group, and any Nginx frontend for the chosen public port, then verify the connection from the client.
Verification
The verified v1.9.0 tag points to
9eb5488. The exact commit passed
full CI, including randomized tests,
command race regressions, vet, static analysis, vulnerability scanning, and a release snapshot.
The Release workflow produced eight
Linux/macOS archives and RPM/DEB packages. Published downloads were verified against SHA-256.
Checksums
| File | Checksum |
|---|---|
| pig-1.9.0-1.aarch64.rpm Linuxarm64SHA-256 | d0d80bd23a654308598f265ce4b4d4f78d6156c113ce6aa00f82bfc9519a180f |
| pig-1.9.0-1.x86_64.rpm Linuxamd64SHA-256 | e3b25640c9e528f2b883f7e5f4838640a8897857fa22dc1324aca69b72966a7c |
| pig-v1.9.0.darwin-amd64.tar.gz macOSamd64SHA-256 | d7eb266e1b8ab60d20ac582c6b0e3741b7e8516ce1a56df447c0285b3e5dcab9 |
| pig-v1.9.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 096284577d0493ddba871b51e820654b358c7f4eb9c11175674a1d21b2718824 |
| pig-v1.9.0.linux-amd64.tar.gz Linuxamd64SHA-256 | a4b5ffca540bc4f924f86398bcad6cb7221ac7520b54b1d3fd32c9877d9cafd2 |
| pig-v1.9.0.linux-arm64.tar.gz Linuxarm64SHA-256 | ddfa80fbb34f6738dd68e0d04cd92355711330f6896cd650df7d71b012788def |
| pig_1.9.0-1_amd64.deb Linuxamd64SHA-256 | 3d955a24a8ff805ee2b6da6428e2b882f97104e2fb597785225269443071d93a |
| pig_1.9.0-1_arm64.deb Linuxarm64SHA-256 | c175b37552147e64590309801800826a0075ae8285ed78178c2adcaec3741471 |
v1.9.0 ·
3.6 - pig v1.8.1
Pig v1.8.1 is a safety, correctness, and maintenance release on top of
v1.8.0. It hardens command initialization, privileged log access,
repository and build workflows, release integrity, and structured-output redaction. It also
refreshes the embedded extension catalog and moves the build toolchain to Go 1.27.1 and
cargo-pgrx 0.19.2. The embedded Pigsty version remains 4.5.0.
CLI safety and correctness
- Read-only and configuration-independent commands no longer require a writable
HOMEor create~/.pigas a side effect. Leaf commands preserve their declared initialization policy. pig pg log,pig pt log, andpig pb logpreserve arguments through sudo execution as the database OS user and reject unsafe log-file links.pig dovalidates Pigsty names and rejects reserved Ansible cluster targets before execution.- Native PostgreSQL role detection is bound to the selected instance rather than an unrelated local default.
- Structured results redact credentials, license material, and build-proxy identifiers while retaining truthful command failure.
Repository and build hardening
- Repository add and remove operations now fail when any requested operation fails, deduplicate module selections, and preserve replacement boundaries.
- Offline cache bundles reject unsafe paths, links, special files, and incomplete inputs; archive extraction remains rooted and fail-closed. The obsolete exported cache wrapper was removed after production moved to the structured result path.
- Build source and artifact validation rejects incomplete or unsafe inputs.
pig build proxyuses the package-provided service contract, treats its operands as optional, and keeps secret identifiers out of structured output. - Self-update verifies release checksums, and release tooling refuses dirty or mismatched-tag publication and immutable artifact replacement.
Toolchain and catalog
-
pig build extandpig build pkgkeep platform debug packages enabled by default; use--nodbgto omit them.-s|--symbolremains a deprecated compatibility no-op. -
Go is updated to
1.27.1; Logrus to1.10.2; GoReleaser to2.18.0; and golangci-lint to2.13.2. -
pig build pgrxnow installscargo-pgrx 0.19.2by default. Use-vwhen an extension requires an older pgrx line recorded in its catalog metadata. -
The embedded catalog is refreshed from the maintained pgext view. It adds
acdat 0.1.0, marks the supersededpgcontext_pgvectorentry removed, and updates package versions, repository ownership, PostgreSQL coverage, and availability matrices.
Verification
The release is built from source commit
1c6f524.
The exact commit passed the full CI workflow,
including randomized tests, command race regressions, vet, static analysis, dead-code detection,
vulnerability scanning, and a GoReleaser snapshot. The tag then passed the
Release workflow, which produced the
published RPM, DEB, macOS, and Linux artifacts.
Compatibility notes
- No CLI command or flag is removed in this release.
- Scripts that previously depended on read-only commands creating local configuration should create that state explicitly instead.
- The pgrx default changes to
0.19.2; extension-specific metadata remains authoritative when a build requires another pgrx version.
Checksums
| File | Checksum |
|---|---|
| pig-1.8.1-1.aarch64.rpm Linuxarm64SHA-256 | 4154b3e49cb499e57d7c7b1ab4ae5e45d03d5d0c2ffe26d6ade64e46db6923cf |
| pig-1.8.1-1.x86_64.rpm Linuxamd64SHA-256 | 35c398f409d9293b4f8c0cdf949b19c62d06016ec7e724472143d2327199869d |
| pig-v1.8.1.darwin-amd64.tar.gz macOSamd64SHA-256 | 6c08b6a698191b8b6494a0f60880fb17cafa535bad12d5c544333e4625048455 |
| pig-v1.8.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 0fb6c86cc18a29aeb74e9d12e717c104087c6ecf5a43250dfcc71cd7681fb868 |
| pig-v1.8.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 9219e87433ebd239e0773ae7417fdd08e97bb511312e6747542bf46b6b1bbf2b |
| pig-v1.8.1.linux-arm64.tar.gz Linuxarm64SHA-256 | b30924880f21126ece3afc77ca75794a0ceb77964cdfd8bc20da72d9d3273078 |
| pig_1.8.1-1_amd64.deb Linuxamd64SHA-256 | 6fc304501671921b18439223c630c7d4635b10ac75493d5c12a5987ff80c618e |
| pig_1.8.1-1_arm64.deb Linuxarm64SHA-256 | 1a70cd71f6c1f443812fe30535427891513c0ba03be219ac21f1a3d6fd450051 |
v1.8.1 ·
3.7 - pig v1.8.0
Pig v1.8.0 makes Pigsty controller setup native. The two core setup commands,
pig sty boot and pig sty conf, are now failure-aware Go workflows instead of
wrappers around the legacy bootstrap and configure shell scripts. The release
keeps the public catalog total at 575 packaged PostgreSQL extensions and embeds
Pigsty 4.5.0.
Native pig sty boot
pig sty boot is now one native, failure-aware controller bootstrap transaction. It does not
execute <PIGSTY_HOME>/bootstrap, and its HTTP download and archive extraction paths do not
depend on curl, wget, tar, or gzip.
Privilege and readiness
- The command can be launched as an ordinary user. Pig resolves and downloads an explicit source
before a single sudo re-exec;
PIG_NO_SUDO=1disables elevation andPIG_NON_INTERACTIVE=1requests non-interactive sudo. - On Debian 12/13, locale preparation is attempted before and, when useful, after controller package installation.
- Readiness is proven by executing
ansible-playbook, discovering its Python interpreter, and checkingyaml,jmespath, and eithercryptographyorOpenSSL. A present but unusable Ansible binary no longer produces a false success.
Repository sources and transactions
- Source selection covers a local archive, an HTTP(S) URL, a permission-checked automatic
/tmp/pkg.tgz, an already committed/www/pigstyrepository, and regional online repositories. A bad explicit source is a hard error and never silently becomes an online boot. - A completed
/www/pigstyrepository wins over a selected package. Pig can create the expected/www -> /data/nginxlayout itself, uses restricted extraction for offline content, and enables only the strictpigsty-localrepository in offline mode. Online setup installs the embedded Pigsty key and keeps repository signature checks enabled. - The default overwrite policy backs up repository definitions and restores them when repository
or package setup fails.
--keepselects an additive policy and can retry a failed online refresh against existing definitions. - The reported mode is explicit:
ready,offline,online, orexisting. An explicit, automatically discovered, or committed offline source is prepared even when Ansible is already usable.
Finishing checks and automation
- Pig probes controller helpers, repairs key-based SSH to
127.0.0.1for the invoking admin user, and initializes a missing~/pigstyfrom online or local content when possible. - Locale, helper, localhost-SSH, and Pigsty-tree finishing failures are warnings. Invalid explicit input, repository/package failures, unsupported installation paths, and unusable post-install Ansible remain hard failures.
- JSON and YAML use the
pig.sty.boot/v2result contract, including the selected mode and package manager, repository policy and rollback state, source paths, locale, SSH and initialization status, changes, warnings, and the nextconf,inventory, anddeploycommands.
Native pig sty conf
pig sty conf is now a complete native Inventory compiler. It does not execute ./configure or
fall back to raw Shell behavior: Pig resolves one template, performs bounded structural changes,
validates the full candidate, and only then commits the output.
Safe configuration pipeline
- The default template is
conf/meta.yml; a safe slash-separated relative mode may be supplied positionally or with--conf. Absolute paths, traversal, path escape, and source/output aliasing through direct paths, symlinks, symlinked parents, or hard links are rejected. - Source parsing and IP-collision checks happen before external preflight. Parse, mutation, preflight, or validation failure leaves the destination unchanged.
- Pig performs native Inventory validation and, when available, a bounded
ansible-inventoryparse. Successful output is atomically written with mode0600.
Structural Inventory changes
- Up to ten distinct
--ipvalues map simultaneously to slots10.10.10.10through10.10.10.19; unrelated VIPs remain intact. Without--ip, interface selection is explicit and deterministic in interactive, non-interactive, and closed-input execution. --domainreplaces only the exacti.pigstytoken. Controllers with fewer than four CPUs are automatically switched from theoltpnode and PostgreSQL tuning profiles totiny.- Region changes update
all.vars.region;chinaactivates Docker and pip mirrors already supplied by the template.--proxymaterializes available proxy environment variables underall.vars.proxy_env. - Generic templates support PostgreSQL 14-18 and explicit 19 beta, including matching locale and
beta repository selection. Version-pinned
mssql,polar, andpgNNmodes keep their effective template version and emit a warning. --generateassigns one random 24-character value to each known credential identifier and updates active values and documented placeholders consistently. Result output lists generated identifiers but never secret values.
Preflight and result contract
- Unless
--skipis selected, preflight covers the platform, package manager, controller resources, sudo/admin access, localhost SSH, and Ansible availability. Build templates underconf/build/intentionally bypass IP mapping and admin preflight. - JSON and YAML use
pig.sty.configure/v1and report the template and output, selected and discarded addresses, requested and effective PostgreSQL versions, applied options, generated secret identifiers, and warnings.
Other Updates
- EL8 and newer package operations consistently prefer DNF, local RPM requirements are resolved
by provider capability, fresh repository bootstraps restore the expected
/wwwlayout, and self-update tolerates whitespace in the latest marker. - The extension catalog, package versions, metadata, and availability matrices receive their routine refresh while the published PostgreSQL-extension count remains 575.
- CI and release builds use Go
1.26.6, pinned analysis tools and GoReleaser, dependency verification, workflow linting, vulnerability scanning, and a full release snapshot.
Compatibility Notes
pig sty bootno longer executes<PIGSTY_HOME>/bootstrap. Automation that relied on shell-script side effects should consume the native command and its structured result.pig sty conf --rawhas been removed. Use the native workflow;--conf MODEremains available, withpig sty conf MODEas the equivalent positional form.pig sty conf --ipaccepts up to ten comma-separated IPv4 addresses;--skipand--ipremain mutually exclusive. Uppercase-Ochooses the Inventory file, while global lowercase-ochooses the command output format.- EL8 and newer use DNF. The limited EL7 compatibility catalog retains its separate legacy YUM path.
Checksums
| File | Checksum |
|---|---|
| pig-1.8.0-1.aarch64.rpm Linuxarm64SHA-256 | 02fd2628810c1b00de730ece32b09dba1318be4c99a4ff1a0551740e32bf223b |
| pig-1.8.0-1.x86_64.rpm Linuxamd64SHA-256 | 72ba72a00af52a84b08b1346f85b42668b52bc097e315774ff9f501ca23ece8b |
| pig-v1.8.0.darwin-amd64.tar.gz macOSamd64SHA-256 | f023a5c9049dc532a057e932c73a8197683eaf4d97cb7a8f219492da1ad2a65f |
| pig-v1.8.0.darwin-arm64.tar.gz macOSarm64SHA-256 | e0ccf61c4d135dbc45359c207751092aeb6df788e826bb73eccc1a1ed8800998 |
| pig-v1.8.0.linux-amd64.tar.gz Linuxamd64SHA-256 | a24a08c1b8d54adcdef5a99ed7b91caeedef1552a1440b1258eb4eb07fb20353 |
| pig-v1.8.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 9d23875804f87e78039498245059fd6b765831f027aacfc511ad0ac42711fa7b |
| pig_1.8.0-1_amd64.deb Linuxamd64SHA-256 | 96259ff7584cd52254c91a9fd7d77bd577f23c55cb09f4bc995a3ca0fcbc7321 |
| pig_1.8.0-1_arm64.deb Linuxarm64SHA-256 | 2e7370211514df6355ef96fb812670febe6ee1b85a28378432c33ebdaecb4b63 |
v1.8.0 ·
3.8 - pig v1.7.0
Pig v1.7.0 is a repository compatibility and catalog release on top of v1.6.2. It makes China-mirror selection explicit, preserves native DNF module filtering by default, restores a streamlined EL7 repository catalog, and grows the bundled extension snapshot from 572 to 575. The embedded Pigsty version remains 4.5.0.
Highlights
-m|--mirrornow selects the bundledchinarepository definitions directly. PGDG, Rocky Linux, Debian, Ubuntu, Docker, and other regional routes use the maintained mirror list instead of the former runtime PGDG proxy rewrite.- EL repository definitions no longer receive
module_hotfixes=1globally. Pigsty and PGDG repositories that intentionally override module streams opt in explicitly; BaseOS, AppStream, EPEL, and other repositories retain native DNF module filtering. - EL7 keeps a deliberately limited compatibility catalog: archived CentOS 7 Base/Updates/Extras/SCLo and EPEL definitions for
x86_64, plus shared Pigsty and supported PGDG entries. The DNF-onlymodule_hotfixeskey is stripped when rendering EL7 YUM configuration. - Repository setup now reports unsupported platforms when the catalog has no matching definitions, instead of continuing with an empty repository set.
- Release metadata is bumped to
1.7.0; the embedded Pigsty version remains4.5.0.
Extension Catalog
- Packaged extensions: 572 -> 575, with no removals.
- 3 new extensions:
pg_local_cache 1.2.0,pg_statviz 0.1.0, andpg_policy 0.1.0. - Version refreshes include
biscuit 3.0.0,pg_clickhouse 0.10.0,pg_search 0.25.2,pg_turbovecpackages1.29.0,pg_uuid_v8 1.1.0, and the Debianq3c 2.0.5package. - Package metadata and availability matrices are refreshed. Run
pig ext reloadwhen you need a catalog newer than this release snapshot.
Compatibility Notes
- No commands or global flags are removed in this release.
-m|--mirroris now an explicit China-region selection rather than a PGDG proxy rewrite. Use--region=default|china|europewhen you need a specific route.- Custom EL repository definitions that require module-stream overrides must now set
meta.module_hotfixes: 1explicitly. This setting is intentionally omitted for ordinary OS repositories and removed on EL7. - EL7 is end-of-life and only has limited compatibility coverage; prefer EL8 or newer for current PostgreSQL and extension packages.
Checksums
| File | Checksum |
|---|---|
| pig-1.7.0-1.aarch64.rpm Linuxarm64SHA-256 | e3a339fefdd2203825d15438b52f18e729547eb88dae014212a46006a9bd47d1 |
| pig-1.7.0-1.x86_64.rpm Linuxamd64SHA-256 | 34ce29d75ef9f669f3bf832cc812ae082abda7320ee2b2336ea61e701b9b67f8 |
| pig-v1.7.0.darwin-amd64.tar.gz macOSamd64SHA-256 | d26803c685ba29c01cb8e6dfe50c6c1b0f004173be82015618fa8cdf6a329ba7 |
| pig-v1.7.0.darwin-arm64.tar.gz macOSarm64SHA-256 | ea8120d48b93da936919f590ebbefeb72e73277e6bc133c1ef0bb1abc055d3ce |
| pig-v1.7.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 40295b64a2423094fa6f4e6d31da8d8ad5b26698c397d8916c0289591522d0bf |
| pig-v1.7.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 7929091732957d85751ef3381285a1e5b0c3c7f82c0e00fc24ed085c496012d5 |
| pig_1.7.0-1_amd64.deb Linuxamd64SHA-256 | 41523c15f36a6c1acaf4af5c851d2626472fc15c21d25f91fc1e991fe8411072 |
| pig_1.7.0-1_arm64.deb Linuxarm64SHA-256 | adf7b2d9ce8fe42bad935428d16a9c998337df986b1065e0761dc167ce837ef5 |
v1.7.0 ·
3.9 - pig v1.6.2
Pig v1.6.2 is a feature and catalog release on top of v1.6.1. It grows the packaged extension catalog from 562 to 572, adds native Grafana dashboard schema v2 support, and improves local repository generation. The embedded Pigsty version remains locked at 4.5.0.
Highlights
pig sty grafananow accepts both legacy dashboard JSON and nativedashboard.grafana.app/v2Dashboard resources. Loading a v2 dashboard uses Grafana’s resource API so tabs and section variables survive the round trip; dumping preserves an existing v2 destination while new dumps keep the legacy format by default.pig repo createnow preferssow create --pigsty --timeout 10m -- <dir>when SOW is available, requires the resultingrepo_completemarker to exist as a regular file, and falls back tocreaterepo_c/dpkg-scanpackageson Linux.- Local repository creation now works on macOS through SOW, defaults to the current directory there, and does not require
sudo. The Linux default remains/www/pigsty. - Release metadata is bumped to
1.6.2; the embedded Pigsty version stays at4.5.0.
Extension Catalog
- Packaged extensions: 562 -> 572, with no removals.
- 10 new extensions:
pg_turbovec,pg_disorder,pg_mentat,plruby,jsonb_plruby,hstore_plruby,ltree_plruby,pg_describe,cat_tools, andpg_vault_tde. - 12 version refreshes:
timescaledb 2.29.1,q3c 2.0.5,pgmnemo 0.16.1,pg_search 0.25.1,citus 14.2.0,citus_columnar 14.2.0,provsql 1.12.0,plpgsql_check 2.10.4,pg_rational 0.0.3,pgbson 2.1.0,pg_readme 0.7.1, andpg_readme_test_extension 0.7.1. - Package metadata and availability matrices are refreshed. Run
pig ext reloadto replace the embedded release snapshot with the latest online catalog.
Compatibility Notes
- No commands or global flags are removed in this release.
- When SOW is installed,
pig repo createnow prefers it over the legacy Linux generators and checks that the completion marker exists before reporting success. - The catalog count is not a promise that every package is available on every PostgreSQL / OS / architecture combination; use
pig ext avail NAMEon the target host. - Package-manager and install-script upgrades use the newest version published by the configured Pigsty repository, which may lag GitHub. Use the GitHub assets when you need this exact release.
Checksums
| File | Checksum |
|---|---|
| pig-1.6.2-1.aarch64.rpm Linuxarm64SHA-256 | 6697a96bbf476e697a5c3da8b6c861719e4b7208e1e4fe927cf4b475ea1f162f |
| pig-1.6.2-1.x86_64.rpm Linuxamd64SHA-256 | ad0b311867bc6cd689dd73e9a96b84f1fe0f49f6c0f1184abf9eb3232a07a184 |
| pig-v1.6.2.darwin-amd64.tar.gz macOSamd64SHA-256 | bb167e04fceb6cebee5c8a2423279cefb4474f46301a5055c464ac98294dc9db |
| pig-v1.6.2.darwin-arm64.tar.gz macOSarm64SHA-256 | 3de74e33321884a0c36596c1e7df9370be594a315395538e9ba5b775bbc1a79d |
| pig-v1.6.2.linux-amd64.tar.gz Linuxamd64SHA-256 | 7b69214e115e6815e772b7e179aa4070bd8553e585b164ba3a0f69a1d53a0294 |
| pig-v1.6.2.linux-arm64.tar.gz Linuxarm64SHA-256 | b511e727642987867be5921d72e8019e9c6186b82e63ddc34ad653773abed5a8 |
| pig_1.6.2-1_amd64.deb Linuxamd64SHA-256 | 3d1a80b833c6179b84ac5cc590ad06695b187b2bb4a09f544b1a14f9684dc4bc |
| pig_1.6.2-1_arm64.deb Linuxarm64SHA-256 | 00e4c84cd6b07a98401c73fb58dedaafe34bc794d7604edbcb76c5de39b0fb44 |
v1.6.2 ·
3.10 - pig v1.6.1
pig v1.6.1 is a maintenance release on top of v1.6.0. It carries no new
commands and no flag changes — the point of the release is the catalog that ships inside the
binary.
What changed
- Extension catalog refreshed. The embedded
extension.csvis regenerated from the Pigsty package repositories, sopig ext listandpig installresolve against current package versions without apig ext reloadround trip. - Pigsty version aligned to 4.5.0. The embedded Pigsty version that
pig styandpig statusreport now points at Pigsty 4.5.0. - Version strings bumped across the build metadata and
pig update.
The catalog embedded in the v1.6.1 release covers 562 packaged extensions across PostgreSQL
14–18 on EL 8/9/10, Debian 12/13, and Ubuntu 22/24/26, for both x86_64 and aarch64.
Running pig ext reload can replace that release snapshot with a newer online catalog.
Upgrading
A fresh install picks up v1.6.1 automatically:
You can also refresh only the catalog on an existing install, without upgrading the binary:
See the release notes for the full version history.
v1.6.1 ·
3.11 - pig v1.6.0
Pig v1.6.0 is a major release: pig pt becomes a transparent patronictl launcher, the new root-level pig inventory command group brings lossless editing and validation of pigsty.yml (with an experimental PostgreSQL CMDB bridge), pig sty grafana adds native Grafana dashboard management, and the packaged extension catalog grows to 562.
Highlights
pig ptis rewritten as a nativepatronictlpassthrough: all cluster commands (list,restart,switchover,failover,edit-config, …) forward directly with native flags, prompts, output, and exit codes, so new patronictl features work without waiting for a pig release. Local helpersstatus,log,set, andservice/svcremain, with new-c/--config-file,-d/--dcs-url,-k/--insecureoptions and apig pt -- …escape hatch.- New root-level
pig inventorycommand group (aliasinv):status/list/show/edit/validate/check/diff— a lossless YAML engine that preserves comments, formatting, key order, and anchors byte-for-byte;editvalidates before writing and writes atomically, so invalid YAML can never reach disk. - New experimental
pig inventory cmdbsubcommands (check/init/load/dump/enable/disable) exchange the inventory with the Pigsty CMDB in PostgreSQL over a native driver, with bounded timeouts and digest-pinned confirmation for destructive operations. - New
pig sty grafana(aliasgf) manages Grafana dashboards natively over HTTP:info/list/boot/load/init/dump/clean/lang/style. Thepig stysurface is simplified:sty edit/validate/check/cmdb/dashboard/releaseare removed in favor ofpig inventory,pig sty grafana, andpig sty list/get. - Reliability hardening: repo / catalog / download writes are atomic (no more truncated files on interrupt); structured
-o json|yamlkeeps stdout as a pure result envelope with wrapped-tool output on stderr; finer exit codes (usage errors → 2, missing--yesconfirmation → 7); Ansible list variables are JSON-encoded. - Repository refresh: MySQL repos upgraded to 8.4 LTS, new Percona XtraBackup (
pxb84) and MySQL Tools repos, Kubernetes v1.36, LLVM apt coverage for Debian/Ubuntu 26, Percona TDE sourced directly from repo.percona.com,wiltondbrepo removed. - Toolchain: Go 1.26.5, new native PostgreSQL driver (pgx v5), embedded Pigsty version
4.4.0.
Extension Catalog
- Packaged extensions: 531 -> 562; the broader PGEXT.CLOUD directory contains 2,230 entries.
- 33 new extensions, including the
pg_lakefamily (pg_lake,pg_lake_table,pg_lake_engine,pg_lake_iceberg,pg_lake_copy),pg_jieba,pg_cjk_parser,pg_fts,pgmonitor,pgmemento,pg_tiktoken_c,online_advisor,pgsqlmock, andplx. - 2 removed:
pg_analytics,spat; 58 version refreshes, includingvector 0.8.5,timescaledb 2.28.3,pg_search 0.24.3,pg_tde 2.2.1, andpowa 5.2.0. - Package aliases synced with Pigsty:
kafkais renamed tokafka-stack; the Debian/Ubuntupostgresqlalias now maps topostgresql-$vonly (usepgsql/pgsql-fullfor the full dev set).
Compatibility Notes
- ⚠
pig pt failover <name>: the positional argument is now the cluster, not the promotion candidate — usepig pt failover CLUSTER --candidate MEMBERand review any failover automation before upgrading. pig ptpositionals are native cluster-first (restart CLUSTER [MEMBER]); forwarded commands return native patronictl exit codes, own their confirmation prompts (-yno longer gates them), and no longer support-o json(use native--format json).pig pt configis replaced bypig pt set K=Vand nativeshow-config/edit-config.- In structured output mode, wrapped-tool output moves to stderr and stdout carries only the JSON/YAML envelope — update scripts that parsed mixed output.
pig inventory edittightens the inventory file mode to 0600 after a successful edit, since the file may contain credentials.
Checksums
| File | Checksum |
|---|---|
| pig-1.6.0-1.aarch64.rpm Linuxarm64SHA-256 | 6899e8a3e1c0adfe8c0c177c0632b0a00821b304ed5998fcbdf28d02660c6768 |
| pig-1.6.0-1.x86_64.rpm Linuxamd64SHA-256 | cabe593fe7f5c31cdbcd8d546ae4925b57f98f70c564452335568389f3f9737c |
| pig-v1.6.0.darwin-amd64.tar.gz macOSamd64SHA-256 | 1f46d4a0b4710eed06b2cf8e7e17ee04b8d65331697c5c65afd513cc28282231 |
| pig-v1.6.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 845decb95697fc68bc5e12bc80cecfd4c6d23160afee96568b699d82f2e9261d |
| pig-v1.6.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 4f1bb4fda8131db9f40db15e1575a6045b373dee609250cf5ee2bdedc2db89e2 |
| pig-v1.6.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 4384d11150e31d614ed4ac3de4d6bf7ee7fa111ac84f5575753bb9f2f31f4ed8 |
| pig_1.6.0-1_amd64.deb Linuxamd64SHA-256 | e35ef0f2c76afe5f3512d34c0440abd8c0106c0e2775c5452e167ae3a4127e8e |
| pig_1.6.0-1_arm64.deb Linuxarm64SHA-256 | c3bc6d04c6acd7e5c3164a33b7525b25a93e2de9822ce957c15c18ee0d551901 |
v1.6.0 ·
3.12 - pig v1.5.1
Pig v1.5.1 updates PG kernel forks to the latest package names.
Highlights
- Add mirror/proxy mode to repo, build, sty, update, and extension update workflows;
pig build rust -malso configures Cargo mirror settings withrsproxy.cn. - Add explicit PostgreSQL 19 beta build switches:
pig build repo --beta,pig build tool --beta, andpig build pgrx -b, while keeping PostgreSQL 18 and PG14-18 as the stable defaults. - Refresh kernel and fork package aliases for IvorySQL, PolarDB, OrioleDB, OpenHaloDB, Babelfish, and the pgEdge suite.
- Improve the Cloudberry package build flow for
cloudberry,cloudberry-backup, andcloudberry-pxf. - Refresh source/package metadata for Cloudberry, Babelfish, OrioleDB, pgEdge, PolarDB,
polarstore,zlog,libpgfeutils, andlibfq. - Improve repository generation for newer EL release strings, including PGDG on EL9.6+ / EL10+ and EPEL’s EL10
10zstream. - Refresh extension versions including
pg_ivm 1.15,spock 5.0.10,snowflake 2.5.0,pg_tde 2.2,decoderbufs 3.6.0, and IvorySQL5.4packages.
Checksums
| File | Checksum |
|---|---|
| pig-1.5.1-1.aarch64.rpm Linuxarm64SHA-256 | bc83887d640ed299a967b4eda2ae6db621a985abfa022fccabf508f7ec7b98e3 |
| pig-1.5.1-1.x86_64.rpm Linuxamd64SHA-256 | f0eab8e638d9e00a9172751446db869d0fe6ca7f382c7d540a931e0764014c0a |
| pig-v1.5.1.darwin-amd64.tar.gz macOSamd64SHA-256 | b32d894dc444ef2b9ec00816d50d82b5834e64c35b3bb18f08b6286a7ca8e8e7 |
| pig-v1.5.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 4d768829b7e93fac6c732e27f665d3ab3945ec8bc1c336e5b91980932e8c9932 |
| pig-v1.5.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 69f4a016af52f1ee8f1a1ffc1e405bb3be551c3813b6d24f70ef8394330be5eb |
| pig-v1.5.1.linux-arm64.tar.gz Linuxarm64SHA-256 | f49becb5fd556b36a9aa8de0c27bdbe210f7958f59254d780774828f2340e77b |
| pig_1.5.1-1_amd64.deb Linuxamd64SHA-256 | a0d15145409d8a2629a74d3071f7af593e470920f22d9af4bf6f96725dbb6d49 |
| pig_1.5.1-1_arm64.deb Linuxarm64SHA-256 | f05b9b5abef5992ed16cbb5b6a6e3e5e58230072e3665ecc57b9ce2df3edb9a6 |
v1.5.1 ·
3.13 - pig v1.5.0
Pig v1.5.0 is a PostgreSQL operations release for day-to-day DBA work. It adds local database clone/fork workflows, clarifies the boundaries between pg, pt, pb, and pitr, and tightens preview, confirmation, and structured-output behavior for high-risk operations.
Highlights
pig pgis now more focused on local PostgreSQL operations.pig pg clonecreates quick database-level copies, whilepig pg forkcreates disposable physical instance forks for local validation, recovery drills, and isolated experiments.- Recovery flows are split more clearly:
pig pitris the orchestration entry point across Patroni, PostgreSQL, and pgBackRest;pig pb restoreremains the low-level pgBackRest restore primitive. Restore commands now require an explicit target and provide more concrete plans and post-restore guidance. - Patroni operations are more predictable: high-risk actions such as
pig pt restart,reinit,switchover, andfailoveruse Pig-managed confirmation and plan output;pig pt config pgpoints operators topig pt restart --pendingwhen a restart is required. - Automation is safer: structured output no longer implies confirmation for destructive commands. High-risk execution requires explicit
-y/--yes, while--planandnext_actionsare more consistent for preview-then-execute workflows. - Logs and status output are more useful during incidents:
pg,pb, andptlog commands now cover common latest / tail / show / grep workflows, and structured log snapshots use JSONL semantics. - Build and release defaults were refreshed: Pig is
1.5.0, embedded Pigsty is4.4.0, andpig build pgrxdefaults tocargo-pgrx 0.19.1.
Extension Catalog
- Available extensions: 524 -> 531, with no removals.
- New extensions:
pg_ducklake,pgdisablelogerror,pg_stat_log,pg_stat_plans,passwordpolicy,db2fce,plpgsql_wrap. - Refreshed a batch of existing extension versions and package metadata, including
timescaledb 2.28.2,postgis 3.6.4,vector 0.8.4,biscuit 2.4.1,citus 14.1.0,orioledb 1.8,documentdb 0.113,credcheck 5.0, andpgtt 4.5. orioledbaliases no longer pin to PG17; they resolve against the requested PostgreSQL major. EL9 ARM64 Patroni aliases now point to noarch packages.
Compatibility Notes
- Use
-y/--yesfor destructive operations in automation; structured output mode no longer substitutes for human confirmation. pig pb restoreandpig pitrrequire exactly one explicit recovery target; use--target-action=promotefor auto-promote behavior.- Several ambiguous short options were cleaned up. For log commands,
-o jsonmeans a JSONL snapshot and is not used for tail/follow streaming modes.
Checksums
| File | Checksum |
|---|---|
| pig-1.5.0-1.aarch64.rpm Linuxarm64SHA-256 | 9f83b78ed2eccedd55a86c634f88364f1945c3cefa1b23efdd72a7cf2062e1df |
| pig-1.5.0-1.x86_64.rpm Linuxamd64SHA-256 | b792001498e9907d4659db46640f9c5164152b20689f90f93418f76fb4633e6e |
| pig-v1.5.0.darwin-amd64.tar.gz macOSamd64SHA-256 | ae1081dfbff8564ecdf713c85e8025c91bfd38e6575ea9ac99a92f968ab8a29d |
| pig-v1.5.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 6d69efcdcdc79fd90d2112e1e8042887020402aa037252d89d632243e7085dc6 |
| pig-v1.5.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 8f914821b317cde73d3aec4ed311d5e90710bbc8cb372c1de3322083c31f4a85 |
| pig-v1.5.0.linux-arm64.tar.gz Linuxarm64SHA-256 | d4de9ef1c28d0a3661c4a4d47c469b7bfd5f5bddb610325796afb669ab162234 |
| pig_1.5.0-1_amd64.deb Linuxamd64SHA-256 | 35fd32affb4cb5bcca845d47a768782fb7005f06fcc1bcb5b7755d2627f96245 |
| pig_1.5.0-1_arm64.deb Linuxarm64SHA-256 | 2be1df804d3f630560bc3ced0107c49ffad8bb52b004f72c7f8b4d09dc8d3e04 |
v1.5.0 ·
3.14 - pig v1.4.2
- Refresh the built-in extension catalog from 510 to 524 available extensions. This adds 14 extensions:
pg_stl,pgmnemo,psql_bm25s,pg_orca,pg_sorted_heap,graph,pgrdf,fsm_core,jsonschema,pg_durable,pg_mockable,pg_uuid_v8,pg_stat_backtrace, andpg_projection. - Update package metadata for 48 existing extensions, including
timescaledb 2.28.0,timescaledb_toolkit 1.23.0,pg_task 2.1.29,pg_search 0.24.0,pg_clickhouse 0.3.2,pg_graphql 1.6.1,documentdb 0.112,toastinfo 1.7,wrappers 0.6.1, andpgclone 4.3.2. No extensions were removed or demoted. - Add PostgreSQL 19 beta install/build/config support. PG19 is accepted as an explicit installable major, while PostgreSQL 18 remains the stable default for auto-detection, catalog display, and latest-version aliases.
- Add
pg19package aliases and PG19 category alias resolution. PG19 category aliases borrow the PostgreSQL 18 visibility template and limit beta package expansion to PGDG-origin entries. - Teach
pig sty conf -v 19to enable thebetarepository module when the template supports it, and emit clear warnings when a template is not tuned for PG19 beta or cannot enable the beta repo automatically. - Fix Patroni cluster operations by passing the resolved
CLUSTER_NAMEtopatronictl restart,reinit,switchover, andfailover;pig pt listalso accepts an optional cluster name. - Bump the default
pgrxversion forpig build pgrxfrom0.18.0to0.18.1. - Bump release metadata to
v1.4.2, refresh Go module checksums, and add focused tests for PG19 aliases/config generation plus Patroni cluster-scope behavior.
Checksums
| File | Checksum |
|---|---|
| pig-1.4.2-1.aarch64.rpm Linuxarm64SHA-256 | 790afe4d6622cb041b06c622bc466cb1b2960a77487f368238027fb4a3a5ef93 |
| pig-1.4.2-1.x86_64.rpm Linuxamd64SHA-256 | ef918166b38a5eb1d108a928718c9e2cb8c3590e5a1f72effee942faca9b4bea |
| pig-v1.4.2.darwin-amd64.tar.gz macOSamd64SHA-256 | 3e37ff22aed076cbdd453911dc89fcc9340b1a4faac62c0580094bc1eb2d6273 |
| pig-v1.4.2.darwin-arm64.tar.gz macOSarm64SHA-256 | 5eb7db776cb149331ebb33e3e6164e1cf711d0107941b92c6930a1d4c4b4eb23 |
| pig-v1.4.2.linux-amd64.tar.gz Linuxamd64SHA-256 | c536c324e40a861217e31f4699ee5f0e6c2daeb4e6f0f0e8cc5f606da9d787eb |
| pig-v1.4.2.linux-arm64.tar.gz Linuxarm64SHA-256 | 8b2d5746264a95269535e5a426f78fe0020f73fa3391fcb613f274551c4786ab |
| pig_1.4.2-1_amd64.deb Linuxamd64SHA-256 | 566e06f6da1fe9d635c41258d20cd9ff10de4e6e74b3b41ba2c6204ba22743c8 |
| pig_1.4.2-1_arm64.deb Linuxarm64SHA-256 | 8c09e741975cb2f74b0f88c5995a8fa43d6c30a9a7ab7aaf0b8d83a7c66e1fc1 |
v1.4.2 ·
3.15 - pig v1.4.1
- 510 extensions, 3 new extensions, 20 updated.
- Ubuntu 26.04
resolutesupport, drop support for Ubuntu 20.04focal. - Bump
el9.aarch64ad hocpatronito4.1.2. - Bump pgEdge to PostgreSQL 18.
- Calibrate upstream repo definition.
Checksums
| File | Checksum |
|---|---|
| pig-1.4.1-1.aarch64.rpm Linuxarm64SHA-256 | cbfbb04b9640dcf39fcd9ccfa49e500dd0e65b72c0326c0d166e6f43e52b6dc3 |
| pig-1.4.1-1.x86_64.rpm Linuxamd64SHA-256 | c3325c7c68559b3149567eddd5963c4bc3bb4b39622740ca469f9d5d274e462b |
| pig-v1.4.1.darwin-amd64.tar.gz macOSamd64SHA-256 | c82e8a5e010aed198748576a3740479ac73eaa4a05f50cd4afc82fbcc9075d4d |
| pig-v1.4.1.darwin-arm64.tar.gz macOSarm64SHA-256 | a62e223a9f3fb6755cfeabfed2b9241d1be8aad42251917ddb2a4757fa5df6bd |
| pig-v1.4.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 65938e1158deb8a795c32ae99ff09178b7dec6b09743f8bdfbd9fd09a522e89f |
| pig-v1.4.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 0fe4172dd1f03ac1b6ac73a28cdfe78b70c6613996252a230710b291faf8db58 |
| pig_1.4.1-1_amd64.deb Linuxamd64SHA-256 | bdcc318ed50bff505f193f3a265d8fd2c7b093a104d5e5728b8c070e3580827e |
| pig_1.4.1-1_arm64.deb Linuxarm64SHA-256 | 1a1acb69d41bcfb9df8fb86c8d3c076050df5a242b639c1215833cd6394e112d |
v1.4.1 ·
3.16 - pig v1.4.0
- Refresh the extension catalog and increase the total available extensions to 510, with version bumps such as
timescaledb 2.26.3,decoderbufs 3.5.0,pgclone 4.0.0, andnominatim_fdw 1.3. - Bump the default
pgrxversion from0.17.0to0.18.0and align related Rust extension builds. - Refresh authoritative source bundles for
pig build get, covering Cloudberry / OrioleDB build inputs and bundled artifacts for RDKit and OneSparse-related packages. - Fix
repo setflag isolation and correct schema maintenance SQL. - Bump
patronito4.1.1forel9.aarch64.
Checksums
| File | Checksum |
|---|---|
| pig-1.4.0-1.aarch64.rpm Linuxarm64SHA-256 | c8d2f46ea1b25f7d4665ee0994f0cb403a59f1464f80b3ecfa575ac283e5ecd0 |
| pig-1.4.0-1.x86_64.rpm Linuxamd64SHA-256 | fb1fd2f4f1e71894779de7b11a42960c09261620dffa0b54ff7f84e60efbf976 |
| pig-v1.4.0.darwin-amd64.tar.gz macOSamd64SHA-256 | aa08045a31c26b9a6bfb770753817581c819022a6ed899e44f7b5a31f57f1733 |
| pig-v1.4.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 80e50dd2ccd08d4a4016e85518186e156498e00c56a898e65acb96466db339f0 |
| pig-v1.4.0.linux-amd64.tar.gz Linuxamd64SHA-256 | e425bf35ab6cb7907e94caca802b4418e3baf4bb1642dd957ab4baaa9db9f583 |
| pig-v1.4.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 840a21695955d64af7df12f7157b49573b18586bb2bf9cc5e7079074b86d39b7 |
| pig_1.4.0-1_amd64.deb Linuxamd64SHA-256 | 401d91bae78b14e3dcc338aaac9e451e94282c79efbe9affabcfeb8b36ece587 |
| pig_1.4.0-1_arm64.deb Linuxarm64SHA-256 | d60515f72fb9f8963554dc5668d2398e5ecefd0153a7756a9d555de90115bcce |
v1.4.0 ·
3.17 - pig v1.3.4
Bump total available extensions to 504.
Checksums
| File | Checksum |
|---|---|
| pig-1.3.4-1.aarch64.rpm Linuxarm64SHA-256 | dc78def9a1e5eb483ac5df4c87f4ac0ef2018bb12b4bedff650d8ba4d58a05fd |
| pig-1.3.4-1.x86_64.rpm Linuxamd64SHA-256 | 998fcbdab1846c94c3155391d2100dad9b0fe338f48212022db38980bb11e696 |
| pig-v1.3.4.darwin-amd64.tar.gz macOSamd64SHA-256 | 031048c561abbeeeaa73fa3ac919b9fb89479b61c8a759bee5db2efba2e8a1df |
| pig-v1.3.4.darwin-arm64.tar.gz macOSarm64SHA-256 | e13c939330d32fa91819ce2da88d121fb02a1063240dbf6cc8fa7975960f8fd3 |
| pig-v1.3.4.linux-amd64.tar.gz Linuxamd64SHA-256 | 46aa321cf45fc9be635d91b38969b7f3602b7f226f43e5ee0e7614a030945c64 |
| pig-v1.3.4.linux-arm64.tar.gz Linuxarm64SHA-256 | f25c4f336edba5c9d2145368082f54e5b1a8b2d4261285b7a1721c088df4caa4 |
| pig_1.3.4-1_amd64.deb Linuxamd64SHA-256 | 563516047e37b25da01da9e25bcbada2c55642d1636b1bdab7d62488f9dcdfbb |
| pig_1.3.4-1_arm64.deb Linuxarm64SHA-256 | 81bb482892f7fd4be862d0f377cb37d01c925006c96998d81d94c770ed9652ba |
v1.3.4 ·
3.18 - pig v1.3.3
- Refresh extension catalog and increase total available extensions to 481.
- Bump Go toolchain from
1.26.0to1.26.2.
Extension Updates
| Extension | Old | New | Notes |
|---|---|---|---|
timescaledb |
2.25.2 | 2.26.2 | available, PG15-18 |
pg_background |
1.8 | 1.9.2 | DEB only, PG14-18 |
pg_ivm |
1.13 | 1.14 | upgraded, PG14-18 |
system_stats |
3.2 | 4.0 | upgraded, PG14-18 |
nominatim_fdw |
1.1.0 | 1.2 | upgraded, PG14-18 |
pg_textsearch |
0.5.0 | 1.0.0 | PG17-18 |
pg_clickhouse |
0.1.5 | 0.1.10 | available, PG14-18 |
pg_search |
0.22.2 | 0.22.6 | manual download, PG15-18 |
pg_store_plans |
1.9 | 1.10 | upgraded, PG14-18 |
pg_dispatch |
0.1.5 | new, PG14-18 | |
pg_fsql |
1.1.0 | new, PG14-18 | |
pg_liquid |
0.1.7 | new, PG14-18 | |
pg_regresql |
2.0.0 | new, PG14-18 | |
pg_slug_gen |
1.0.0 | new, PG15-18 | |
pg_stat_ch |
0.3.3 | new, PG16-18 | |
pg_variables |
1.2.5 | new, PG14-18 | |
pgcalendar |
1.1.0 | new, PG14-18 | |
pgclone |
2.2.0 | new, PG14-18 | |
pgelog |
1.0.2 | new, PG14-18 | |
pglock |
1.0.0 | new, PG14-18 | |
pgproto |
0.2.1 | new, PG14-18 | |
postgresbson |
2.0.2 | new, PG14-18 | |
rdf_fdw |
2.4.0 | new, PG14-18 | |
parray_gin |
1.4.0 | new, PG14-18 |
Checksums
| File | Checksum |
|---|---|
| pig-1.3.3-1.aarch64.rpm Linuxarm64SHA-256 | e74418061ea975fbc3e8a89b31f274d7dc3617d12b9d681e5c8ef03584392088 |
| pig-1.3.3-1.x86_64.rpm Linuxamd64SHA-256 | 8450e3e1076425fc8a10f24cc5fd833c3d2d880bab12baff5c10e59a31f62231 |
| pig-v1.3.3.darwin-amd64.tar.gz macOSamd64SHA-256 | 952a0e94b9020fca5add91f8e9a398fbedfda5d2e5c8736e59ddaa2b7152c826 |
| pig-v1.3.3.darwin-arm64.tar.gz macOSarm64SHA-256 | c896b4fd44b19a250f4c3c47dc78643e10e92fde8cb6531b08cdc78e3623bb8a |
| pig-v1.3.3.linux-amd64.tar.gz Linuxamd64SHA-256 | d18a92f9aa05d6315c5e9bfde3245afc08fca93d200a8063aa20cb40feb8e85e |
| pig-v1.3.3.linux-arm64.tar.gz Linuxarm64SHA-256 | 62d020072360229b47f6c430b014344b912f2d9b58fd528154ae9c4ee805190a |
| pig_1.3.3-1_amd64.deb Linuxamd64SHA-256 | 7a613a1f1c323ee78276b1733df026b8b0f415e0057b4cb8e509f771bfd3d614 |
| pig_1.3.3-1_arm64.deb Linuxarm64SHA-256 | f4c91ce86b787b6ab8cd584949d38c2ca87eb82d5e066bab91b80345252f43d8 |
v1.3.3 ·
3.19 - pig v1.3.2
Routine maintenance release.
- Refresh a batch of extension version metadata and catalog entries.
- Add the
pig pg tunesubcommand to generate PostgreSQL tuning parameters from hardware resources and workload profiles. - Add
pduandpgdogsource package aliases forpig build get. - Migrate extension catalog URLs from
pgext.cloudtopigsty.io/ext.
Checksums
| File | Checksum |
|---|---|
| pig-1.3.2-1.aarch64.rpm Linuxarm64SHA-256 | d760f47652ff3e2e4a61eb7b9a68ca68665b2b36c187c52f5eaf50d2f007d8f3 |
| pig-1.3.2-1.x86_64.rpm Linuxamd64SHA-256 | c2e02e62497f4c2055a9b448ddb3a24c618fcd488580c28b2b9a0e7cedacef55 |
| pig-v1.3.2.darwin-amd64.tar.gz macOSamd64SHA-256 | b8d066ddefa4530946c74c30e7e4acdab6abf8da70a47dcfe2a77719b79e397f |
| pig-v1.3.2.darwin-arm64.tar.gz macOSarm64SHA-256 | a90e78d879fd720fd2865870c696aed7952558d5ae75591deced3121f2aab1f9 |
| pig-v1.3.2.linux-amd64.tar.gz Linuxamd64SHA-256 | 2fe3a9ffbb6383154dfd25ed79420b210828eabf6a96a8af6e8feb9d744b9559 |
| pig-v1.3.2.linux-arm64.tar.gz Linuxarm64SHA-256 | 522290aaf14f98f0bae83ce75cc76749f2a4e72742eb5c3cba36a1d2fa4d12c2 |
| pig_1.3.2-1_amd64.deb Linuxamd64SHA-256 | d6c1cf2c52962045f6bbfb2a669058e7f903088526591d6c939e7723f3928d30 |
| pig_1.3.2-1_arm64.deb Linuxarm64SHA-256 | 4352385c629b26a1837054445a546da89591499848b557699c2fb70fde9377aa |
v1.3.2 ·
3.20 - pig v1.3.1
This is a small maintenance release from v1.3.0 to v1.3.1.
- PG13 install/build support is removed because PGDG upstream has dropped PG13 archive/distribution.
- Active supported PostgreSQL major versions are now 14-18.
- Refresh extension catalog (
461 -> 464), includingpg_pinyin,pg_eviltransform, andqos. - Percona PPG upstream repo is bumped to
18.3. - Fix
pig builddependency/build sync issues; rsync now uses--keep-dirlinks. - In YUM repos, Nginx is split out from
infrainto its own module index (nginx).
Checksums
| File | Checksum |
|---|---|
| pig-1.3.1-1.aarch64.rpm Linuxarm64SHA-256 | 196e57c7dd46cdedd90ab75965a766f74aabc3bc23ddc8fb757473647bed7b8f |
| pig-1.3.1-1.x86_64.rpm Linuxamd64SHA-256 | e4bdd52ef635524d5aec95f6a5abd76bd49940584ecbb00bd309a4f9186292ac |
| pig-v1.3.1.darwin-amd64.tar.gz macOSamd64SHA-256 | 4f3f9479344c158e1c5edc3003471be6b595c01b7d86104bf676b34f8faadce5 |
| pig-v1.3.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 05ae2f550ef5062ab5714518a24bbf52f48079ca6d0190359fae5b8f4cb7f20d |
| pig-v1.3.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 940645497e907e56bfd387a478e580ac930aaa72593cc9d04225a08b37880ec4 |
| pig-v1.3.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 8b2c204fd6c933a1097cd1cd0ce491b02ba5c0025626a331a199684ceca3ab43 |
| pig_1.3.1-1_amd64.deb Linuxamd64SHA-256 | 1cfc23d147795cc4c1ea9596e6978d79ff1ec34c02850fbb224f7c2844548ea5 |
| pig_1.3.1-1_arm64.deb Linuxarm64SHA-256 | e495678ae1c762194a56e8c9969fd2109e7a59830f34a4747039fb978f7820cc |
v1.3.1 ·
3.21 - pig v1.3.0
This release is a focused engineering update from v1.2.0 to v1.3.0: 15 commits, 74 files changed, +1184 / -236 LOC.
It hardens the pig build pipeline and extends catalog/alias coverage, increasing total extensions from 451 to 461.
Highlights
- Build source download improvements (
pig build get):- Parse multi-source
Sourcefields (whitespace/newline/tab) and deduplicate entries. - Add source mappings for
agensgraph/agentsgraph. pgedgenow downloads bothpostgresql-17.9.tar.gzandspock-5.0.5.tar.gz.
- Parse multi-source
- Dependency resolution and install improvements (
pig build dep):- RPM dependencies can infer PG major from
pgmajorversionin spec files; missing spec/control files now return explicit errors. - DEB dependency parsing now covers
Build-Depends/Build-Depends-Arch/Build-Depends-Indep, including multiline fields, alternatives, arch qualifiers, and build-profile cleanup. PGVERSIONplaceholders can be expanded from--pg, installed PG majors, or extension metadata.- Dependency install failures are downgraded to warnings so batch runs continue.
- RPM dependencies can infer PG major from
- DEB build result semantics fixed (
pig build ext/pkg):- Successful build command exit code is authoritative; artifact discovery is best-effort warning only.
- Suppress empty package-list banners on successful no-artifact runs.
- Partial artifacts are warnings, not failures.
- Build logs now print real metadata source/version values instead of always composing
name-version.
- Better machine-readable ext operation output (
pig ext rm/update):- After alias resolution,
removed/updatednow returns resolved package names instead of extension aliases.
- After alias resolution,
- Extension catalog and alias updates:
- New aliases:
agensgraph/agens,pgedge,babelfishpg. openhalodbis aligned to PG14 package naming;ivorysqldbnaming is aligned.- Fork metadata and availability matrix were refreshed in batch (including
timescaledb,pgmq,orioledb,documentdb,pg_tde, andbabelfishpg_*entries).
- New aliases:
- Engineering and release:
- Version bumped to
v1.3.0(including av1.2.1transition commit), copyright year moved to 2026, and README refreshed for 461 extensions and current alias docs.
- Version bumped to
Compatibility Notes
- Structured
removed/updatedfields inpig ext rm/updatenow contain package names. Automation that matched extension aliases should update parsing logic.
New Extensions (451 -> 461)
| Extension | Version | Notes |
|---|---|---|
aux_mysql |
1.5 | openHalo MySQL compatibility helper (PG14) |
gb18030_2022 |
1.0 | IvorySQL charset conversion module |
ivorysql_ora |
1.0 | IvorySQL Oracle compatibility extension |
ora_btree_gin |
1.0 | Oracle datatype GIN indexing support |
ora_btree_gist |
1.0 | Oracle datatype GiST indexing support |
pg_get_functiondef |
1.0 | Function definition utility |
plisql |
1.0 | PL/iSQL procedural language |
snowflake |
2.4 | pgEdge Snowflake-style ID generator |
spock |
5.0.5 | pgEdge multi-master logical replication extension |
lolor |
1.2.2 | pgEdge logical-replication-friendly large objects |
Full Commit List (v1.2.0..v1.3.0)
b8ecf8dbump version string to 1.2.155df9a4build/get: support multi-source parsing and pgedge spock tarballda8e347add agensgraph and pgedge alias86edbd7ext: show resolved package names in rm/update resultsef3c905build/dep: improve rpm/deb dependency resolution7144e09ext/catalog: refresh fork metadata and matrix entriesbefffbfbuild(deb): treat successful build command as authoritative result33fd517build(deb): avoid empty package list banner on successful no-artifact runs3b450f2avoid concat ext pkg name with version when download33847abfix(ext): satisfy staticcheck S1011 in rm/updateb8b917dbuild(dep): treat dependency install failures as warnings8110c00adjust ivorysqldb babelfishpg aliasfac9fafbump version to 1.3.01f88f06chore: update copyright year to 2026c804757v1.3.0
Checksums
| File | Checksum |
|---|---|
| pig-1.3.0-1.aarch64.rpm Linuxarm64SHA-256 | 196f32419886da095f303b1bcad2729b674abc03d412199e88a39390b2616534 |
| pig-1.3.0-1.x86_64.rpm Linuxamd64SHA-256 | a2dcc930dd47a08e85285c1fb7925e1355a1e67d458a265a7ef6d9666bc8e7ec |
| pig-v1.3.0.darwin-amd64.tar.gz macOSamd64SHA-256 | c7ebda6b9839408b12ffe1c8ea561f03e1793aae0732f9bbe2320a0d45160714 |
| pig-v1.3.0.darwin-arm64.tar.gz macOSarm64SHA-256 | b717b485ed0a4a8c11dd8bf918400595b21df5ef43818836ec332f8518674c1a |
| pig-v1.3.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 40e6570c6ba0fe36c97950ff8de585eecb6bc1f862509a04f410a5f08ee90148 |
| pig-v1.3.0.linux-arm64.tar.gz Linuxarm64SHA-256 | d61430eeafc8005a22918a9aa60dea5c987916f9834331b5484f761b8235644f |
| pig_1.3.0-1_amd64.deb Linuxamd64SHA-256 | 62c9a4fadc7dda393d6f28ab83b5f3d741e7d7f7de7abe40a5b89c393288519c |
| pig_1.3.0-1_arm64.deb Linuxarm64SHA-256 | 19261ae50e873a05a10a6ad500ab1b429b22e2612325c09f9cd5443dcd34308b |
v1.3.0 ·
3.22 - pig v1.2.0
-
Extension catalog and alias resolution enhancements:
- Introduce dynamic PG category alias resolution by PG major version.
- Add OS-level alias overrides (
ansible/bootstrap) and converge unknown distro fallback to PGDG-only. - Add aliases such as
node/infraandbabelfish/cloudberry, and refresh extension metadata to reduce package resolution ambiguity.
-
Plan preview for high-risk operations:
- Add
pig install --planwith structured execution plan output. - Align preview semantics for
pig pitrand pgBackRestrepack/expireunder--plan/--dry-run. - Add plan-flag consistency tests to keep subcommand behavior aligned.
- Add
-
Native
styconfiguration capability:- Add
pig sty configurewith full execution flow (preflight, argument handling, execution orchestration). - Unify
sty conf/configurebehavior: native implementation by default, with--rawfallback retained. - Add tests for configure main flow, preflight, routing, and install integration to improve maintainability.
- Add
-
Repo/build/reliability fixes:
- Fix nil dereference in repo cache on
os.Staterror paths. - Align Ubuntu and Debian repo channel mapping, and add timeout control for mirror pulls during reload.
- Harden
repo rmfor dotted module names with safe deletion and path validation. - Fix symlink preservation, cross-device migration, and target-directory handling in
sty initand build flows. - Improve text output and matrix color rendering, and fix ext command validation for empty args/targets.
- Fix nil dereference in repo cache on
-
35 commits, 66 files changed, LOC:
+5006 / -379 -
PG extension and kernel package updates
| Package | Old | New | Notes |
|---|---|---|---|
timescaledb |
2.25.0 | 2.25.1 | |
citus |
14.0.0-3 | 14.0.0-4 | Rebuilt from the latest official upstream release |
age |
1.7.0 | 1.7.0 | Add PG 17 support for version 1.7.0 |
pg_background |
- | 1.8 | DEB-only build; RPM package comes from PGDG |
pgmq |
1.10.0 | 1.10.1 | This extension package is currently unavailable |
pg_search |
0.21.6 | 0.21.8 | Used as direct download package |
oriolepg |
17.11 | 17.16 | OriolePG kernel update |
orioledb |
beta12 | beta14 | Matched with OriolePG 17.16 |
cloudberry |
- | 2.0.0 | New package |
babelfishpg |
- | 5.5.0 | New BabelfishPG package group |
babelfish |
- | 5.5.0 | New Babelfish compatibility package |
antlr4-runtime413 |
- | 4.13 | New runtime dependency for Babelfish |
Checksums
| File | Checksum |
|---|---|
| pig-1.2.0-1.aarch64.rpm Linuxarm64SHA-256 | 344b77385fa9c3d4fe5e1961340e68716251e38d1cb8308f5af45ce8a03cd206 |
| pig-1.2.0-1.x86_64.rpm Linuxamd64SHA-256 | aa9cf1820a9045cc42f0d66689d5e8679cb71452042f3f01ddd4c3a518a2b757 |
| pig-v1.2.0.darwin-amd64.tar.gz macOSamd64SHA-256 | f26e4d9e9fa76c39f7c591c18a09287ca3388e016d121c196302ee9eafb5b678 |
| pig-v1.2.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 2ca41efc3495822305f6e6a3ae1825d57cc97e764f280581f833c72e6e5019a2 |
| pig-v1.2.0.linux-amd64.tar.gz Linuxamd64SHA-256 | f7aa291b3534d92d0459b6e8301190e39c63db14a45a6c097d4c5d3062c35181 |
| pig-v1.2.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 38007ecd6d7a69bae0e3d8f7c78f1a4c8bbaead320b7ac319b0d94d6b53853f0 |
| pig_1.2.0-1_amd64.deb Linuxamd64SHA-256 | e824716ddfbf3805dc0a1fd6d97917241b7780503657e9fd40a37beb6b398d7a |
| pig_1.2.0-1_arm64.deb Linuxarm64SHA-256 | b67baa404d877b37004331041cb270c85b8f9a3f8a92a5083390a54d76553d2a |
v1.2.0 ·
3.23 - pig v1.1.1
Fixes
- Preserve symlink semantics during build-tree migration and support cross-device moves.
- Handle a PostgreSQL log directory configured as the filesystem root without resolving files outside the intended directory.
- Allow
pig repo rmto remove repository modules whose names contain dots while retaining safe-path validation. - Accept safe relative symlinks when
pig sty initextracts a Pigsty release archive.
Checksums
| File | Checksum |
|---|---|
| pig-1.1.1-1.aarch64.rpm Linuxarm64SHA-256 | 22fe5e951f09e7cfa46ab22781199b3209792992940eb5615ace4928e41a7429 |
| pig-1.1.1-1.x86_64.rpm Linuxamd64SHA-256 | 7f5a10bbefdc39e5d66a7e688fa78c5ba566c8140458b9f4b1536ff0d7ed457a |
| pig-v1.1.1.darwin-amd64.tar.gz macOSamd64SHA-256 | b90aec9dc559df81c46d32575a8d231fa6d7eeb8b25f4d2e0b6076cc0a9c0e59 |
| pig-v1.1.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 3063e3a72e68371a082b4e629d12aafda46d96eddc22976beb2049881854f4ea |
| pig-v1.1.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 081ff8c81bf61108a35ca4cdc51007d4ddf1de8a041d8be087e58e7068e7e177 |
| pig-v1.1.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 9a81e868699f92d73f8aeb7752206b6eaac8d42d1688089a1f543b12ee0d272d |
| pig_1.1.1-1_amd64.deb Linuxamd64SHA-256 | 85ce861cfbff846be2ba912ba8dfc766121dad14a59937387d9c5e26b0b6f541 |
| pig_1.1.1-1_arm64.deb Linuxarm64SHA-256 | 3a108f0544af4d1f98acee55c06c5b5af3b856e3be2b18767e6db0b8a1cc664f |
v1.1.1 ·
3.24 - pig v1.1.0
This release upgrades the CLI architecture from v1.0.0 to v1.1.0 (79 commits, 193 files changed),
with the core goal of moving pig from a “human-friendly CLI” to an “agent-native orchestratable CLI”.
Seven new extensions are added, bringing the total available extensions to 451.
New Features
- Land the unified agent-native output framework: introduce global
--output(text/yaml/json/json-pretty), and provide unifiedResultstructure, stable status codes, and machine-readable output forext/repo/pg/pt/pb/pitr/status/version/context. - Introduce ANCS (Agent Native Command Schema) metadata: add semantic fields such as
type/volatility/parallel/risk/confirm/os_user/cost, and makehelpemit a command capability tree directly in structured mode for agent-side capability and risk discovery. - Add
pig context(pig ctx) environment snapshot command: aggregate host, PostgreSQL, Patroni, pgBackRest, and extension information in one call for direct agent workflow context injection. - Expand plan capabilities beyond PITR: add
pig ext add/rm --plan,pig pg stop/restart --plan,pig pt switchover/failover --plan, and align withpig pitr --plan/--dry-runinto a reviewable execution plan format (actions, scope, risks, expected outcomes). - Further improve structured result coverage: embed native
pgbackrest infoJSON, and unify structured return DTOs across Patroni/PostgreSQL/PITR/Repo/Ext subsystems for automation compatibility. - Strengthen compatibility layer: add legacy structured wrappers for existing command groups such as
pg_exporter/pg_probe/do/sty, preserving legacy interaction behavior while exposing structured execution results and output capture. - Update pigsty to
v4.1.0.
Extension Update
| Extension | Old | New |
|---|---|---|
| timescaledb | 2.24.0 | 2.25.0 |
| citus | 14.0.0-2 | 14.0.0-3 |
| pg_incremental | 1.2.0 | 1.4.1 |
| pg_bigm | 1.2-20240606 | 1.2-20250903 |
| pg_net | 0.20.0 | 0.20.2 |
| pgmq | 1.9.0 | 1.10.0 |
| pg_textsearch | 0.4.0 | 0.5.0 |
| pljs | 1.0.4 | 1.0.5 |
| sslutils | 1.4-1 | 1.4-2 |
| table_version | 1.11.0 | 1.11.1 |
| supautils | 3.0.2 | 3.1.0 |
| pg_math | 1.0 | 1.1.0 |
| pgsentinel | 1.3.1 | 1.4.0 |
| pg_uri | 1.20151224 | 1.20251029 |
| pgcollection | 1.1.0 | 1.1.1 |
| pg_readonly | 1.0.3 | 1.0.4 |
| timestamp9 | 1.4.0-1 | 1.4.0-2 |
| pg_uint128 | 1.1.1 | 1.2.0 |
| pg_roaringbitmap | 0.5.5 | 1.1.0 |
| plprql | 18.0.0 | 18.0.1 |
| pglinter | 1.0.1 | 1.1.0 |
| pg_jsonschema | 0.3.3 | 0.3.4 |
| pg_anon | 2.5.1 | 3.0.1 |
| vchord | 1.0.0 | 1.1.0 |
| pg_search | 0.21.4 | 0.21.6/0.21.7 |
| pg_graphql | 1.5.12-1 | 1.5.12-2 |
| pg_summarize | 0.0.1-2 | 0.0.1-3 |
| nominatim_fdw | - | 1.1.0 |
| pg_utl_smtp | - | 1.0.0 |
| pg_strict | - | 1.0.2 |
| pg_track_optimizer | - | 0.9.1 |
| pgmb | - | 1.0.0 |
Bug Fixes
- Security fix: resolve parsing panic in
pig build proxywhen receiving malformed proxy addresses. - Security fix: resolve path traversal risk in
pig pg log, preventing access to files outside the log directory via../../. - Security hardening: improve installer/repo path and quoting handling to reduce path injection and invalid-path misuse risks.
- Build pipeline reliability fixes: correctly propagate errors and return non-zero exit codes in
pig build get/pkg/extwhen download/build fails; fix false failures in DEB builds caused bypg_vermismatch. - Repo/catalog refresh fixes: support quiet mirror fallback for
ext/repo reload; makerepo add/set/rmreturn proper error status when cache updates fail. - Extension management fixes: adjust
ext updateto explicit-target updates and fix status drift issues; ensureext importdownloads requested DEB resources to the specified repo directory. - Output/observability fixes: align structured output exit code behavior with text mode rendering; improve permission handling and parsing stability in
pg status.
Checksums
| File | Checksum |
|---|---|
| pig-1.1.0-1.aarch64.rpm Linuxarm64SHA-256 | 95245dc035270df2b02cdd5d19afac57ccf4949a61b07b1b806fffde3a3b780e |
| pig-1.1.0-1.x86_64.rpm Linuxamd64SHA-256 | 8b1a26f1b5dd002841a0b31904eea8ce94d1e6c4acde4704a78d9e121e1656f4 |
| pig-v1.1.0.darwin-amd64.tar.gz macOSamd64SHA-256 | dbd079510513f1cd0521b0871cc6fe3eed8f7fa26f66c04c682568c43e24c456 |
| pig-v1.1.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 3f3ba081b54569a7de4d9a8fce72c02c84d9e1cbeb53173567f970c7291af251 |
| pig-v1.1.0.linux-amd64.tar.gz Linuxamd64SHA-256 | ad61384bf01cbb8346ce869da0bc893203ad316c516fb9420cb748f1519a005e |
| pig-v1.1.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 7713632beea1e6ca5c3e2e7172c4adee13a2b1b256755f6c2898b6ca98ee1e00 |
| pig_1.1.0-1_amd64.deb Linuxamd64SHA-256 | 70cfc41b7b0aad48f29e12c22c34afd55b938bf50868ac8ab067b9cb62ccb867 |
| pig_1.1.0-1_arm64.deb Linuxarm64SHA-256 | fc5cf16671254f8f3495ff7e80c9d77d06b2328c1a247f90f96cf1e918e0ad0e |
v1.1.0 ·
3.25 - pig v1.0.0
This release introduces three major new subcommand groups (pig pg, pig pt, pig pb) for managing PostgreSQL, Patroni, and pgBackRest, along with an orchestrated PITR command and enhanced extension availability display.
New Commands
-
pig pg- PostgreSQL instance managementpg init/start/stop/restart/reload/status- Control and manage PostgreSQL instancespg role/promote- Detect and switch instance role (primary/replica)pg psql/ps/kill- Connection and session managementpg vacuum/analyze/freeze/repack- Database maintenance operationspg log- Log viewing (list/tail/cat/less)
-
pig pt- Patroni cluster managementpt list/config- View cluster status and configurationpt restart/reload/reinit- Manage cluster memberspt switchover/failover- Cluster failover operationspt pause/resume- Control automatic failoverpt start/stop/status/log- Patroni service management
-
pig pb- pgBackRest backup managementpb info/ls- View backup informationpb backup/restore/expire- Backup operationspb create/upgrade/delete- Stanza managementpb check/start/stop/log- Control operations
-
pig pitr- Orchestrated Point-In-Time Recovery- Automatic Patroni/PostgreSQL coordination
- Multiple recovery targets: time, LSN, XID, restore point
- Dry-run mode and post-recovery guidance
New Features
- Add availability matrix to
pig ext availandpig ext ls
Improvements
- Unified command aliases across pg/pt/pb commands
- Standardized error message format
- Code refactoring and cleanup
Bug Fixes
- Fix missing UTIL extension category
Checksums
| File | Checksum |
|---|---|
| pig-1.0.0-1.aarch64.rpm Linuxarm64SHA-256 | 306637079e942bcac9ccbc089cd09a80051898f8db1630269bb1acd3fbdaa872 |
| pig-1.0.0-1.x86_64.rpm Linuxamd64SHA-256 | d2b9440410f00efbca174d63b507c39d97fc55f402d8e9290ee054c1b1c6414c |
| pig-v1.0.0.darwin-amd64.tar.gz macOSamd64SHA-256 | c8a169e48a8168ee03db508ca2edc22b56ecf6997bae924e9023796ab7ae4e62 |
| pig-v1.0.0.darwin-arm64.tar.gz macOSarm64SHA-256 | c0996037bfeffeae241b545e69d46c06e7fec2d7d456885229f3af9a7f9ea2f8 |
| pig-v1.0.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 13837c6f2379edf965888bad9e373e69f70cb72e8428bca18c2c804e2bd879f6 |
| pig-v1.0.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 08207dfedd6f72745631596a3d3293de65cc12e1544956a643d1da2165d2c876 |
| pig_1.0.0-1_amd64.deb Linuxamd64SHA-256 | a543882aa905713a0c50088d4e848951b6957a37a1594d7e9f3fe46453d5ce66 |
| pig_1.0.0-1_arm64.deb Linuxarm64SHA-256 | 4cd6ec54261b09025c12e9c56bcc0cd3c11779ea0e8becdbd4f901cf2e7c8995 |
v1.0.0 ·
3.26 - pig v0.9.0
Changes
- Rename
pig sty installtopig sty deployso the command name reflects that it runs the Pigsty deployment playbook. - Add the
-g,-p, and-ooptions topig sty conf, aligning it with the configure script available in this release. - Keep
llvmjitin thepgsql-fullpackage alias.
Checksums
| File | Checksum |
|---|---|
| pig-0.9.0-1.aarch64.rpm Linuxarm64SHA-256 | ea0c098d0829720b6e364d2f2a91328876962c7f0ae94eee7bdcde0bd43313fa |
| pig-0.9.0-1.x86_64.rpm Linuxamd64SHA-256 | 707f4e1fde76d3faa05165ac11e97969c22a8740c97ef84da52727d0328990cc |
| pig-v0.9.0.darwin-amd64.tar.gz macOSamd64SHA-256 | 56aeb61674ddfb64368e6f5535e06a38b76f62e3d6c9536a63be7df6babed93e |
| pig-v0.9.0.darwin-arm64.tar.gz macOSarm64SHA-256 | a213d16817d6124ffa83d93ad880a040598b6ed3fe23a74d43420c095ed43de4 |
| pig-v0.9.0.linux-amd64.tar.gz Linuxamd64SHA-256 | 6a1a1836217fa723ca42bc2276ecf1453cd2ee0acacddfc313164701b24a452f |
| pig-v0.9.0.linux-arm64.tar.gz Linuxarm64SHA-256 | 5e5728aa5922138c61c900a731f97cdc1b9653c14d7fe804b6753fb6f222b8b0 |
| pig_0.9.0-1_amd64.deb Linuxamd64SHA-256 | e80d2cb3ceb5fd58fc0262ab4b39b44e8dcccb7712151c73a41ba50cb510353b |
| pig_0.9.0-1_arm64.deb Linuxarm64SHA-256 | ecb504efffde8d696b765579332fc0b3304751fa8077c4c0394e7f3c44aa0fe2 |
v0.9.0 ·
3.27 - pig v0.8.1
Fix
- Restore
llvmjitto thepgsql-fullpackage alias after it was removed in v0.8.0. - Bump the release version to
v0.8.1.
Checksums
| File | Checksum |
|---|---|
| pig-0.8.1-1.aarch64.rpm Linuxarm64SHA-256 | fd9291b15953e8e5f579de7e0256b88ca742e11fc0ed578bf181d2ce4cf5258c |
| pig-0.8.1-1.x86_64.rpm Linuxamd64SHA-256 | c2ec07d18eeae6ad831950da44d6bb797fad3ca4d0b1f7b0e82d715a22baedec |
| pig-v0.8.1.darwin-amd64.tar.gz macOSamd64SHA-256 | b07017d257089166377fb4deffe167c952ae1dcacb6203de26a11a89097dfc34 |
| pig-v0.8.1.darwin-arm64.tar.gz macOSarm64SHA-256 | 090889ba1447693e3ace0b18222f6852448738fc4baa4964a27acc87ce560501 |
| pig-v0.8.1.linux-amd64.tar.gz Linuxamd64SHA-256 | 64cfd28d98c41776c83949b2ffb3b789c66835ccb522a346ea1b53966e9f9544 |
| pig-v0.8.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 6216612ab63c2c9006466834222bdbdcd9e7e8e112c52a6f17e26d0ebb24fbe4 |
| pig_0.8.1-1_amd64.deb Linuxamd64SHA-256 | 29a2109af6141fa990144f0ebcf3bbbe13030c75af6fb3c6bf89eb8da956d387 |
| pig_0.8.1-1_arm64.deb Linuxarm64SHA-256 | 7d8728658c942e57df259acd1da0d2655d9132ab7bffcc109527ed184784f882 |
v0.8.1 ·
3.28 - pig v0.8.0
Extension Updates
- Total extensions reached 440
- New extension: pg_ai_query 0.1.1
- New extension: pg_textsearch 0.1.0
- New extension: pg_clickhouse 0.1.0
- pg_biscuit upgraded from 1.0 to 2.0.1 (switched to new repo, renamed to biscuit)
- pg_search upgraded from 0.20.3 to 0.20.5
- pg_duckdb upgraded to official release 1.1.1
- vchord_bm25 upgraded from 0.2.2 to 0.3.0
- pg_semver upgraded from 0.40.0 to 0.41.0
- pg_timeseries upgraded from 0.1.7 to 0.1.8
- Fixed debian/ubuntu pg18 extension issues: supautils, pg_summarize, pg_vectorize, pg_tiktoken, pg_tzf, pglite_fusion, pgsmcrypto, pgx_ulid, plprql
- Pigsty version synced to 4.0.0
Repository Updates
- Removed pgdg yum sysupdate repo due to upstream changes
- Removed pgdg yum llvmjit package due to upstream changes
- Fixed patroni 3.0.4 duplicate package issue on el9.aarch64
- Added priority for el repo definitions, docker repo skipped when unavailable
- Added epel 10 / pgdg 9/10 OS minor version hotfix
Checksums
| File | Checksum |
|---|---|
| pig-0.8.0-1.aarch64.rpm Linuxarm64SHA-256 | e457832fb290e2f9975bf719966dc36e650bdcbf8505d319c9e0431f4c03bc9e |
| pig-0.8.0-1.x86_64.rpm Linuxamd64SHA-256 | c97b1bfdd7541f0f464cab0ecc273e65535c8dd2603c38d5cf8dccbf7e95b523 |
| pig-v0.8.0.darwin-amd64.tar.gz macOSamd64SHA-256 | d892f06d3d3b440671529f40e6cc7949686e0167e2a4758adc666b8a3d75254d |
| pig-v0.8.0.darwin-arm64.tar.gz macOSarm64SHA-256 | 222413bafdf5a62dc682dac32ea1118cbc34ec3544e2a1b85076ec450b9cc7ae |
| pig-v0.8.0.linux-amd64.tar.gz Linuxamd64SHA-256 | d50aa9806bbab8fee5ad9228e104fc9e7ead48729228116b5bf889000791fedc |
| pig-v0.8.0.linux-arm64.tar.gz Linuxarm64SHA-256 | d2f410f7b243a8323c8d479f462a0267ac72d217aa4a506c80b5a9927d12dff8 |
| pig_0.8.0-1_amd64.deb Linuxamd64SHA-256 | 4ccd330a995911d4f732e8c9d62aa0db479c21c9596f64c4bc129ec43f156abe |
| pig_0.8.0-1_arm64.deb Linuxarm64SHA-256 | 5cb9eccce659110f3ba58e502575564bd6befffd51992a43d84df5a17f8eb8a0 |
v0.8.0 ·
3.29 - pig v0.7.5
Extension Updates
- timescaledb 2.23.1 -> 2.24.0
- pg_search 0.20.0 -> 0.20.3
- convert 0.0.4 -> 0.0.5
- pglinter 1.0.0 -> 1.0.1
- pgdd 0.6.0 -> 0.6.1
- pg_session_jwt 0.3.3 -> 0.4.0
- pg_anon 2.4.1 -> 2.5.1
- pg_enigma 0.4.0 -> 0.5.0
- wrappers 0.5.6 -> 0.5.7
- pg_vectorize 0.25.0 -> 0.26.0
Repository Updates
Use the fixed Aliyun PGDG mirror repository
Checksums
| File | Checksum |
|---|---|
| pig-0.7.5-1.aarch64.rpm Linuxarm64SHA-256 | 9de11ac1404fc4100074113f2a5d50e4ec42c353b6e122a0b29edc17e53feca6 |
| pig-0.7.5-1.x86_64.rpm Linuxamd64SHA-256 | 071d655580f1cc63b33d41a8fb49368556b7b5a276318f4bd772a6ab50e22b34 |
| pig-v0.7.5.darwin-amd64.tar.gz macOSamd64SHA-256 | befe0a8f786e5243669ed7219acde8156d13d9adb0a5c2fb88ccf0f614a51f9b |
| pig-v0.7.5.darwin-arm64.tar.gz macOSarm64SHA-256 | 4766b4e9ba390a32a7115e9f2dd6b65cf158439e28f9c099bab5c7f2e588bae2 |
| pig-v0.7.5.linux-amd64.tar.gz Linuxamd64SHA-256 | dc45726c5e7fccd502cacaffc94c659570844151cdc279f2cac6500836071ade |
| pig-v0.7.5.linux-arm64.tar.gz Linuxarm64SHA-256 | 1483cf967d4bc9c12d4c6724567644d6b88fcd2a93aaf1d317fc6ad4e1672c13 |
| pig_0.7.5-1_amd64.deb Linuxamd64SHA-256 | 0152b7bd254eccadd640e563845abd9fa62efa68f11c6b67a5f9f0eebfa2d92e |
| pig_0.7.5-1_arm64.deb Linuxarm64SHA-256 | 7d22116d26ca09c5e2b8afbf086bb1acb1aea1148905efcc38944c18908fb105 |
v0.7.5 ·
3.30 - pig v0.7.4
- Update extension metadata:
pg_search,pgmq,pg_stat_monitor - Update pgdg repo URL, the
extrasnow move to parent directory - Bump ivorysql to 5.0 (compatible with PG 18.0)
- Bump Percona Postgres TDE Kernel to 18.1
Checksums
| File | Checksum |
|---|---|
| pig-0.7.4-1.aarch64.rpm Linuxarm64SHA-256 | 5769b0051f04dcda22dd92b30b8effc8ddfa40097308bded76ce2b38d012ce57 |
| pig-0.7.4-1.x86_64.rpm Linuxamd64SHA-256 | d15c829fa2e3ce8dcd1adc063c107607b8e70f2cf747646aaa2fa257cdbf979c |
| pig-v0.7.4.darwin-amd64.tar.gz macOSamd64SHA-256 | bb4c90e253a3d470e50316e633a41e90ed2d4a5c5a1fd3a8dbb68ee87d831d47 |
| pig-v0.7.4.darwin-arm64.tar.gz macOSarm64SHA-256 | faaf7ac7b08390f5048c081bb7a78100714387e35dc890e26d9746fc1caef415 |
| pig-v0.7.4.linux-amd64.tar.gz Linuxamd64SHA-256 | 037cacddd0dc1283f13dd2c9bace87ad7f2c74ffc245e629f1420be94bbf93df |
| pig-v0.7.4.linux-arm64.tar.gz Linuxarm64SHA-256 | 2ce819b2c3686cfb9f86790fdf61acd30bf7798bd6cd3c4f589df22e273dc867 |
| pig_0.7.4-1_amd64.deb Linuxamd64SHA-256 | 97f62d62f1cca61ce6d335efed88e3855d94ea2cd4ed941f2755fbac73931fcd |
| pig_0.7.4-1_arm64.deb Linuxarm64SHA-256 | d2b80af89ed42601716f6b41eda3f8bee16db34023527df9deef8a43aa25a498 |
v0.7.4 ·
3.31 - pig v0.7.3
- Add new command:
pig repo reloadto update repo metadata - Fix EL PGDG sysupdate aarch64 repo issue (now aarch64 repo ready)
- Fix EL10.aarch64 PGDG repo renaming issue
- Update extension versions
- Bump Pigsty version to 3.7.0
Checksums
| File | Checksum |
|---|---|
| pig-0.7.3-1.aarch64.rpm Linuxarm64SHA-256 | 83e1b491b58793859caaccb0600a8ad7f7c0ea71dfcbc1dc348bf4666f7dc742 |
| pig-0.7.3-1.x86_64.rpm Linuxamd64SHA-256 | 00671775c22918b6e92c8f39972fa2e6e78536ba0ca1e23f9bb9752a2910a974 |
| pig-v0.7.3.darwin-amd64.tar.gz macOSamd64SHA-256 | d6ac6164a09a7b2aac210b898c8729df6cbcef6462207a896caf08b1511c9cdb |
| pig-v0.7.3.darwin-arm64.tar.gz macOSarm64SHA-256 | c595df851cc76b93fe2692e880909aed316db00cfdcd75c0c5667141915e49b7 |
| pig-v0.7.3.linux-amd64.tar.gz Linuxamd64SHA-256 | baa875895623f073204d0ff8fbcb76bd37da6e5806e70aae43aaa2cb14355186 |
| pig-v0.7.3.linux-arm64.tar.gz Linuxarm64SHA-256 | b6d75f7e0474341990e2cf64b5006fb7b145839f8b54c12f70657c166bfeeb14 |
| pig_0.7.3-1_amd64.deb Linuxamd64SHA-256 | 5ddfd410c6d6c2546804bf948aab3b7978fa719d92c1477d7a33889e7b1006dd |
| pig_0.7.3-1_arm64.deb Linuxarm64SHA-256 | 2996c06fda272e01fea72bb8eec51dca8f4b9e8526d9833dcda1cf7549d1e01a |
v0.7.3 ·
3.32 - pig v0.7.2
-
Extension list update, + 6 new extensions, 437 total
-
Add PGDG EL10 Sysupdate repo
-
Add LLVM APT repo
-
Use local extension.csv catalog in pig build sub command
-
Updated extensions: vchord pg_later pgvectorscale pglite_fusion pgx_ulid pg_search citus timescaledb pg_profile pg_stat_monitor documentdb
-
New extensions: pglinter pg_typeid pg_enigma pg_retry pg_biscuit pg_weighted_statistics
Checksums
| File | Checksum |
|---|---|
| pig-0.7.2-1.aarch64.rpm Linuxarm64SHA-256 | 080dd93c33faf81e8f9d3b9d543b9949604b834ccd55331cce697df79049a9af |
| pig-0.7.2-1.x86_64.rpm Linuxamd64SHA-256 | b91056230d3a790ab0190b3680fc5dbc3eb1306b7a1c2416fb6ef421bf48dcf7 |
| pig-v0.7.2.darwin-amd64.tar.gz macOSamd64SHA-256 | 9b294e58b8c3629066b905e25dda4f51eacc1eb4b6d5d87fab32d17fb13a9cb7 |
| pig-v0.7.2.darwin-arm64.tar.gz macOSarm64SHA-256 | 74f3276752d826c8130ca22a791da48548608378a453908e7cdd095c0564a1eb |
| pig-v0.7.2.linux-amd64.tar.gz Linuxamd64SHA-256 | 0c9f6e6bf930e70206df2c6d58d1296f1a7a77ca7d89d27d47112bc44544cda4 |
| pig-v0.7.2.linux-arm64.tar.gz Linuxarm64SHA-256 | f62842217be958569ca09051e8cad0d674ee9446245e45655b91f9918927b340 |
| pig_0.7.2-1_amd64.deb Linuxamd64SHA-256 | 091d12d5d5c3c8e52b8b60ab180b88b7aeaff512aa344af0e039c7d4b73c75a0 |
| pig_0.7.2-1_arm64.deb Linuxarm64SHA-256 | 53346bd96538a20b0bb3bb4161ba117bca7b5cf6633f5d3c357fe9e560b06ff5 |
v0.7.2 ·
3.33 - pig v0.7.1
- Launch the new PGEXT.CLOUD extension catalog
- Remove unnecessary sudo usage, now can be used inside docker
- Allow using
pg18,pg17arg format in pig ext link command - Add environment var
PIG_NO_SUDOto force not using sudo - RPM Changelog: Add PG 18 support to almost all extensions
- DEB Changelog: Add PG 18 support to almost all extensions
- Infra Changelog: Routine update to the latest version
Checksums
| File | Checksum |
|---|---|
| pig-0.7.1-1.aarch64.rpm Linuxarm64SHA-256 | a696c9ec784e2fc248e5f3d87cc8aae4116e890f78c5997957d30593f2c85ca6 |
| pig-0.7.1-1.x86_64.rpm Linuxamd64SHA-256 | f669538a99cd1dc592d3005b949628fcceb9e78114fc78862d7726b340ee194d |
| pig-v0.7.1.darwin-amd64.tar.gz macOSamd64SHA-256 | e42bdaaf93b720c5b76b32b57362320e4b447109740c76089aefe030b7c8b836 |
| pig-v0.7.1.darwin-arm64.tar.gz macOSarm64SHA-256 | b4c240aadad34e785666ee0a755d9b7455724f790c2d088a1dd7c37ad3b2a457 |
| pig-v0.7.1.linux-amd64.tar.gz Linuxamd64SHA-256 | ffc687add0ca71ac90cba5749c8a7a6075cf7618cba85584072831cf3eb182f7 |
| pig-v0.7.1.linux-arm64.tar.gz Linuxarm64SHA-256 | 7b0d1f158150d0a40c525692f02b6bce9f5b4ac523a4e59278d702c334e222e1 |
| pig_0.7.1-1_amd64.deb Linuxamd64SHA-256 | 43e91a3bea273d7cacb2d7a58c0a5745501dbd06348b5cb3af971171fae70268 |
| pig_0.7.1-1_arm64.deb Linuxarm64SHA-256 | fc2a34aeb46e07cb0ae93611de47d6622c3bd46fe4c415ce4c9091840e0e08a2 |
v0.7.1 ·
3.34 - pig v0.7.0
- Add support for Debian 13 and EL 10 distributions
- Massive extension updates to the latest versions with PostgreSQL 18 support
- Almost all Rust extensions now support PG 18 via pgrx 0.16.1
pig buildcommand overhaulpig build pkg <pkg>will now download source, prepare deps, and build in one gopig build pgrxis now separated frompig build rustpig build pgrx [-v pgrx_version]can now use existing PG installation directlypig build depwill now handle extension dependencies on both EL and Debian systemspig build extnow has more compact and elegant output, can build RPM on EL without build scriptpig build specnow supports downloading spec files directly from Pigsty repopig build repo/pig repo add/pig repo setnow usenode,pgsql,infraas default repo modules instead ofnode,pgdg,pigsty
- Optimized error logging
- Brand new catalog website based on hugo and hextra
Checksums
| File | Checksum |
|---|---|
| pig_0.7.0-1_amd64.deb Linuxamd64MD5 | ad60f9abcde954769e46eb23de61965e |
| pig_0.7.0-1_arm64.deb Linuxarm64MD5 | aa15d7088d561528e38b2778fe8f7cf9 |
| pig-0.7.0-1.aarch64.rpm Linuxarm64MD5 | 05549fe01008e04f8d5a59d4f2a5f0b8 |
| pig-0.7.0-1.x86_64.rpm Linuxamd64MD5 | 0cc9e46c7c72d43c127a6ad115873b67 |
| pig-v0.7.0.darwin-amd64.tar.gz macOSamd64MD5 | ddacfb052f3f3e5567a02e92fdb31cdd |
| pig-v0.7.0.darwin-arm64.tar.gz macOSarm64MD5 | 17d25b565308d3d35513e4b0d824946b |
| pig-v0.7.0.linux-amd64.tar.gz Linuxamd64MD5 | ee7e055ceff638039956765fb747f80b |
| pig-v0.7.0.linux-arm64.tar.gz Linuxarm64MD5 | 284e674807b87447d4b33691fd7a420d |
v0.7.0 ·
3.35 - pig v0.6.2
- Use official PG 18 repo instead of testing repo
- Add
vprefix when specifying pigsty version string - Improved network connectivity check
Checksums
| File | Checksum |
|---|---|
| pig_0.6.2-1_amd64.deb Linuxamd64MD5 | 01f5b7dc20644226c762dbb229768347 |
| pig_0.6.2-1_arm64.deb Linuxarm64MD5 | ce4f00256adc12cbea91467b7f2241cd |
| pig-0.6.2-1.aarch64.rpm Linuxarm64MD5 | cefc36ae8f348aede533b30836fba720 |
| pig-0.6.2-1.x86_64.rpm Linuxamd64MD5 | d04a287c6eb92b11ecbf99542c2db602 |
| pig-v0.6.2.darwin-amd64.tar.gz macOSamd64MD5 | e637ca86a7f38866c67686b060223d9a |
| pig-v0.6.2.darwin-arm64.tar.gz macOSarm64MD5 | 79749bc69c683586bd8d761bdf6af98e |
| pig-v0.6.2.linux-amd64.tar.gz Linuxamd64MD5 | ad4f02993c7d7d8eec142f0224551bb4 |
| pig-v0.6.2.linux-arm64.tar.gz Linuxarm64MD5 | 9793affa4a0cb60e9753e65b7cba3dca |
v0.6.2 ·
3.36 - pig v0.6.1
- Add el10 and debian 13 trixie support stub
- Launch the dedicated PIG website
- Rebuild with go 1.25 and CI/CD pipeline
- Use PIGSTY PGDG mirror in mainland China
- Remove unused
pgdg-el10fixrepo - Use Pigsty WiltonDB mirror
- Add EL 10 dedicated epel repo
- pig version output with go build environment
v0.6.1 ·
3.37 - pig v0.6.0
- New extension catalog: https://ext.pgsty.com
- New subcommand:
pig installto simplifypig ext install - Add new kernel support: percona with pg_tde
- Add new package: Google GenAI MCP toolbox for databases
- Add new repo: percona repo and clickhouse repo
- Change extension summary info links to ext.pgsty.com
- Fix orioledb broken on the Debian/Ubuntu system
- Fix epel repo on EL distributions
- Bump golang to 1.24.5
- Bump pigsty to v3.6.0
Checksums
| File | Checksum |
|---|---|
| pig_0.6.0-1_amd64.deb Linuxamd64MD5 | 1804766d235b9267701a08f95903bc3b |
| pig_0.6.0-1_arm64.deb Linuxarm64MD5 | 35f4efa35c1eaecdd12aa680d29eadcb |
| pig-0.6.0-1.aarch64.rpm Linuxarm64MD5 | b523b54d9f2d7dcc5999bcc6bd046b1d |
| pig-0.6.0-1.x86_64.rpm Linuxamd64MD5 | 9434d9dca7fd9725ea574c5fae1a7f52 |
| pig-v0.6.0.linux-amd64.tar.gz Linuxamd64MD5 | f635c12d9ad46a779aa7174552977d11 |
| pig-v0.6.0.linux-arm64.tar.gz Linuxarm64MD5 | 165af4e63ec0031d303fe8b6c35c5732 |
v0.6.0 ·
3.38 - pig v0.5.0
- Update the extension list to 422
- New extension: pgactive from AWS
- Bump timescaledb to 2.20.3
- Bump citus to 13.1.0
- Bump vchord to 0.4.3
- Bug fix pgvectorscale debian/ubuntu pg17 failure
- Bump kubernetes repo to 1.33
- Bump default pigsty version to 3.5.0
Checksums
| File | Checksum |
|---|---|
| pig_0.5.0-1_amd64.deb Linuxamd64MD5 | 9ec6f3caf3edbe867caab5de0e0ccb33 |
| pig_0.5.0-1_arm64.deb Linuxarm64MD5 | 4fbb0a42cd8a88bce50b3c9d85745d77 |
| pig-0.5.0-1.aarch64.rpm Linuxarm64MD5 | 9cf8208396b068cab438f72c90d39efe |
| pig-0.5.0-1.x86_64.rpm Linuxamd64MD5 | d9a8d78c30f45e098b29c3d16471aa8d |
| pig-v0.5.0.linux-amd64.tar.gz Linuxamd64MD5 | 761df804ff7b83965c41492700717674 |
| pig-v0.5.0.linux-arm64.tar.gz Linuxarm64MD5 | 5d1830069d98030728f08835f883ea39 |
v0.5.0 ·
3.39 - pig v0.4.2
- Update the extension list to 421
- Add openhalo/orioledb support for Debian / Ubuntu
- pgdd 0.6.0 (pgrx 0.14.1)
- convert 0.0.4 (pgrx 0.14.1)
- pg_idkit 0.3.0 (pgrx 0.14.1)
- pg_tokenizer.rs 0.1.0 (pgrx 0.13.1)
- pg_render 0.1.2 (pgrx 0.12.8)
- pgx_ulid 0.2.0 (pgrx 0.12.7)
- pg_ivm 1.11.0 for debian/ubuntu
- orioledb 1.4.0 beta11
- Add el7 repo back
Checksums
| File | Checksum |
|---|---|
| pig_0.4.2-1_amd64.deb Linuxamd64MD5 | bbf83fa3e3ec9a4dca82eeed921ae90a |
| pig_0.4.2-1_arm64.deb Linuxarm64MD5 | e45753335faf80a70d4f2ef1d3100d72 |
| pig-0.4.2-1.aarch64.rpm Linuxarm64MD5 | 966d60bbc2025ba9cc53393011605f9f |
| pig-0.4.2-1.x86_64.rpm Linuxamd64MD5 | 1f31f54da144f10039fa026b7b6e75ad |
| pig-v0.4.2.linux-amd64.tar.gz Linuxamd64MD5 | 1eec26c4e69b40921e209bcaa4fe257a |
| pig-v0.4.2.linux-arm64.tar.gz Linuxarm64MD5 | 768d43441917a3625c462ce9f2b9d4ef |
v0.4.2 ·
3.40 - pig v0.4.1
- Update the extension list to 414
- Add
citus_wal2jsonandcitus_pgoutputtopig ext scanmapping - Add PG 18 beta repo
- Add PG 18 package alias
v0.4.1 ·
3.41 - pig v0.4.0
- Updated extension list, available extensions reached 407
- Added
pig dosubcommand for executing Pigsty playbook tasks - Added
pig ptsubcommand for wrapping Patroni command-line tools - Added extension aliases:
openhaloandorioledb - Added
gitlab-ce/gitlab-eerepository distinction - Built with the latest Go 1.24.2 and upgraded dependency versions
- Fixed
pig ext statuspanic issue under specific conditions - Fixed
pig ext scanunable to match several extensions
v0.4.0 ·
3.42 - pig v0.3.4
- Routine extension metadata update
- Use aliyun epel mirror instead of broken tsinghua tuna mirror
- Bump pigsty version string
- Add
gitlabrepo to the repo list
v0.3.4 ·
3.43 - pig v0.3.3
- Add
pig build depcommand to install extension build dependencies - Update default repo list
- Use pigsty.io mirror for
mssqlmodule (wiltondb/babelfish) - Merge docker module into
infra - Remove pg16/17 from el7 target
- Allow installing extensions in el7
- Update package alias
v0.3.3 ·
3.44 - pig v0.3.2
Enhancement
- New extensions
- Use
upxto reduce binary size - Remove embedded pigsty to reduce binary size
v0.3.2 ·
3.45 - pig v0.3.1
Routine bugfix
- Fix repo format string
- Fix ext info links
- Update pg_mooncake metadata
v0.3.1 ·
3.46 - pig v0.3.0
This release introduced a PIG homepage alongside the PostgreSQL extension catalog.
v0.3.0 ·
3.48 - pig v0.2.0
New extensions
- pg_documentdb_core and FerretDB
- VectorChord-bm25 (vchord_bm25) 0.1.0
- pg_tracing 0.1.2
- pg_curl 2.4
- pgxicor 0.1.0
- pgsparql 1.0
- pgjq 0.1.0
- hashtypes 0.1.5
- db_migrator 1.0.0
- pg_cooldown 0.1
Extension updates
- citus 13.0.0 -> 13.0.1
- pg_mooncake 0.1.0 -> 0.1.1
- timescaledb 2.17.2 -> 2.18.1
- supautils 2.5.0 -> 2.6.0
- VectorChord 0.1.0 -> 0.2.0
- pg_bulkload 3.1.22 (+pg17)
- pg_store_plan 1.8 (+pg17)
- pg_search 0.14 -> 0.15.1
- pg_analytics 0.3.0 -> 0.3.2
- pgroonga 3.2.5 -> 4.0.0
- zhparser 2.2 -> 2.3
- pg_vectorize 0.20.0 -> 0.21.1
v0.2.0 ·
3.49 - pig v0.1.4
New extensions
- pg_documentdb_core and FerretDB
- VectorChord-bm25 (vchord_bm25) 0.1.0
- pg_tracing 0.1.2
- pg_curl 2.4
- pgxicor 0.1.0
- pgsparql 1.0
- pgjq 0.1.0
- hashtypes 0.1.5
- db_migrator 1.0.0
- pg_cooldown 0.1
Extension updates
- citus 13.0.0 -> 13.0.1
- pg_mooncake 0.1.0 -> 0.1.1
- timescaledb 2.17.2 -> 2.18.1
- supautils 2.5.0 -> 2.6.0
- VectorChord 0.1.0 -> 0.2.0
- pg_bulkload 3.1.22 (+pg17)
- pg_store_plan 1.8 (+pg17)
- pg_search 0.14 -> 0.15.1
- pg_analytics 0.3.0 -> 0.3.2
- pgroonga 3.2.5 -> 4.0.0
- zhparser 2.2 -> 2.3
- pg_vectorize 0.20.0 -> 0.21.1
v0.1.4 ·
3.50 - pig v0.1.3
v0.1.3, routine update, with 390 extensions available now!
v0.1.3 ·
3.51 - pig v0.1.2
351 PostgreSQL Extensions, including the powerful postgresql-anonymizer 2.0
v0.1.2 ·
3.52 - pig v0.1.1
Update Extension List
v0.1.1 ·
3.53 - pig v0.1.0
pig CLI v0.1 released
v0.1.0 ·
3.54 - pig v0.0.1
Genesis Release
v0.0.1 ·
3.55 - pig v1.10.0
Pig v1.10.0 strengthens the correctness and safety of existing commands. It verifies PostgreSQL
targets before operations, preserves Inventory sources and YAML types, and makes repository,
extension, and automation results match the work actually performed. The bundled catalog grows
from 600 to 603 records. Embedded Pigsty remains 4.5.0; the default cargo-pgrx remains 0.19.3.
PostgreSQL targets and maintenance
- An explicit
-Dbindspsql,ps,kill,vacuum,analyze,freeze, andrepackto the selected instance, including--alldatabase enumeration. PIG validates the PID, data directory, port, socket, and process identity before starting the SQL client. Invalid, stale, copied, or uncertain runtime metadata causes failure instead of a fallback to another instance. - Without
-D, those SQL commands retain native client connection defaults.pg cloneandpg forkretain their own port options. Promotion timeline checks use the selected instance or its control data; an unresolved timeline is left unknown. - Plans and confirmation retry commands preserve the selected data directory, PostgreSQL version,
operating-system user, and maintenance options.
VACUUM FULLplans correctly require confirmation. - Maintenance operands are literal database names. Values containing
=or beginning withpostgres://orpostgresql://are rejected before planning or execution, without echoing the value. Spaces and non-ASCII names remain supported. Generated commands put names after--, so a database named--allcannot become a command option. vacuum,analyze, andfreeze --allvalidate the complete database list before maintenance begins. Use native clients when a connection string or a database name rejected by this boundary is required.
See pig pg for target selection and
maintenance commands for database-name rules.
Runtime state, recovery, and fork safety
- Permission failures, malformed PID metadata, and unavailable process identity are reported as
errors or unknown state. They cannot authorize forced initialization, restore, or fork replacement.
pg statusreturns130201(exit3) for permission failures and130808(exit1) for other runtime-probe failures. Plans report an unresolved precondition asunknown. - Declining PITR confirmation or reaching EOF returns
161001(exit7) before any service stop, restore, or startup. An unknown state cannot supply a PID for forced termination or count as successful startup. Post-restore SQL checks require a verified target. - Replacing a nonempty unmanaged fork requires valid ownership metadata with a matching explicit target path. Missing, damaged, or mismatched metadata cannot authorize deletion. Existing protections for running targets and source/destination relationships remain in force.
- Clone and fork path checks run as the selected database operating-system user when needed,
supporting private
0700data directories. An inaccessible or unresolved path cannot bypass validation. Managed orphan cleanup remains available through the managed fork name. - Files written as the database user use private sibling staging and exact-target replacement.
The new file has
0600permissions; directory or symlink targets are refused, and replacement does not overwrite the contents of another hard link to the old file.
The PITR reference explains the managed recovery workflow;
pig pb restore remains a separate restore primitive.
Inventory and Pigsty
sty deployanddopass the resolved Inventory path explicitly to Ansible. Flag and environment paths resolve from the caller’s working directory; quoted~/paths expand before resolution. A selected missing or invalid source does not silently fall back to another inventory.pg_users[].rolespreserves both role-name strings and structured grants, including grant state and optionaladmin,set, andinheritattributes.- Editing, serialization, and CMDB export retain strings that YAML consumers might otherwise interpret as numbers, dates, or timestamps. Existing timestamp scalars retain their original source representation. Independent PyYAML checks verify the emitted string types.
sty conf --proxyaccepts uppercase and lowercase HTTP, HTTPS, ALL, and NO proxy variables. Missing HTTP and HTTPS values both fall back to ALL_PROXY. Version completion observes dotted version boundaries, so a request for1.1cannot select1.10.
See Inventory source selection and pig sty.
Repositories and extensions
- Repository commands validate the complete operand list before changing files. Empty values,
empty comma-separated elements, and unsafe repository names fail before mutation.
Only truly argument-free
repo rmbacks up all repository files;repo rm allexpands thenode,pgsql, andinframodules. Removal results preserve the original request and distinguish missing targets from removed files.--updatealso refreshes the cache after a full backup. - Repository creation retains documentation RPMs. Debug package suppression continues to use
--nodbg; a-docsor-docname alone does not make a package a debug package. - Default extension lists, availability summaries, and refresh results count all catalog records,
including SQL utilities and retained lifecycle entries. The total describes catalog coverage,
not how many extensions can be installed on one host or enabled with
CREATE EXTENSION. - Text, JSON, and YAML share availability rules. On covered Linux platforms, package matrices take
precedence and a missing matrix cell means unavailable. Architecture aliases are normalized.
On macOS, the status describes declared PostgreSQL support without promising an RPM/DEB package.
ext list -vselects the version used to evaluate status; unavailable records remain listed. ext importreports failure if any requested package cannot be resolved or downloaded, while retaining successful downloads and reporting the completed and failed portions. APT virtual dependency markers are excluded from package download requests. Installed-library scanning also recognizes catalog entries without a control file.- The three new catalog records are
pg_icu_parser,pg_vectorsearch, andtextsearch_intl. Existing versions and platform metadata are refreshed as well. Usepig ext avail NAMEto inspect a target before installing.
Builds and automation
- Multi-version build dependency installation expands package names for every selected PostgreSQL major version and removes duplicates. Default build targets retain their metadata and local installation rules independently of package-matrix gaps.
- Debian/Ubuntu builds preserve the inherited
PATHorder and append the current user’s~/.cargo/binwhen present, preserving an explicitly selected toolchain. - Xray setup recognizes complete legacy service definitions, including marker-free macOS plists generated by the previous renderer. A comment alone cannot prove ownership; changed or foreign definitions still require explicit replacement. Matching reruns preserve a running service.
- JSON/YAML output and
PIG_NON_INTERACTIVE=1consistently disable prompt input and use non-interactive sudo in PIG-owned adapters. Explicit data-input channels remain available; native Patronictl forwarding retains its interaction and exit contract. - CMDB connection strings, legacy VMess credentials, and license keys are excluded from routine parameters and failure details. Explicit credential export and raw Inventory display retain their documented sensitive-output behavior.
- Exporter HTTP 4xx/5xx responses now fail with the numeric status and standard description,
without including response bodies or custom status text. Unsupported
pig updateplatforms fail explicitly. Command help and bilingual references are aligned with these behaviors. - Go dependencies and validation tools are refreshed. CI includes Linux permission and instance boundary acceptance plus independent YAML consumer checks.
See pig build, pig pe, and global command behavior.
Upgrade notes
Existing command names and flags remain available. Automation should handle the corrected failure
statuses for partial imports, HTTP errors, cancelled recovery, and indeterminate PostgreSQL state.
Scripts must supply valid repository operands, explicit confirmation where required, and literal
maintenance database names. When a name begins with -, place all options before -- and the name.
Upgrade with the installation instructions.
v1.10.0 ·